Think Before You Act: Decision Gate for LLM Agents
Iftach Shoham, Yuval David, Ido Levy, Segev Shlomov and colleagues (IBM) introduce JevAct, a runtime gate that checks selected agent actions before they execute by combining executable policy checks with a prefill-only decision model.
Ask this paper
Runtime gate. JevAct compiles domain policies into executable state checks and structured questions, then returns targeted feedback for bounded revision. It needs no changes to the agent model or tools.
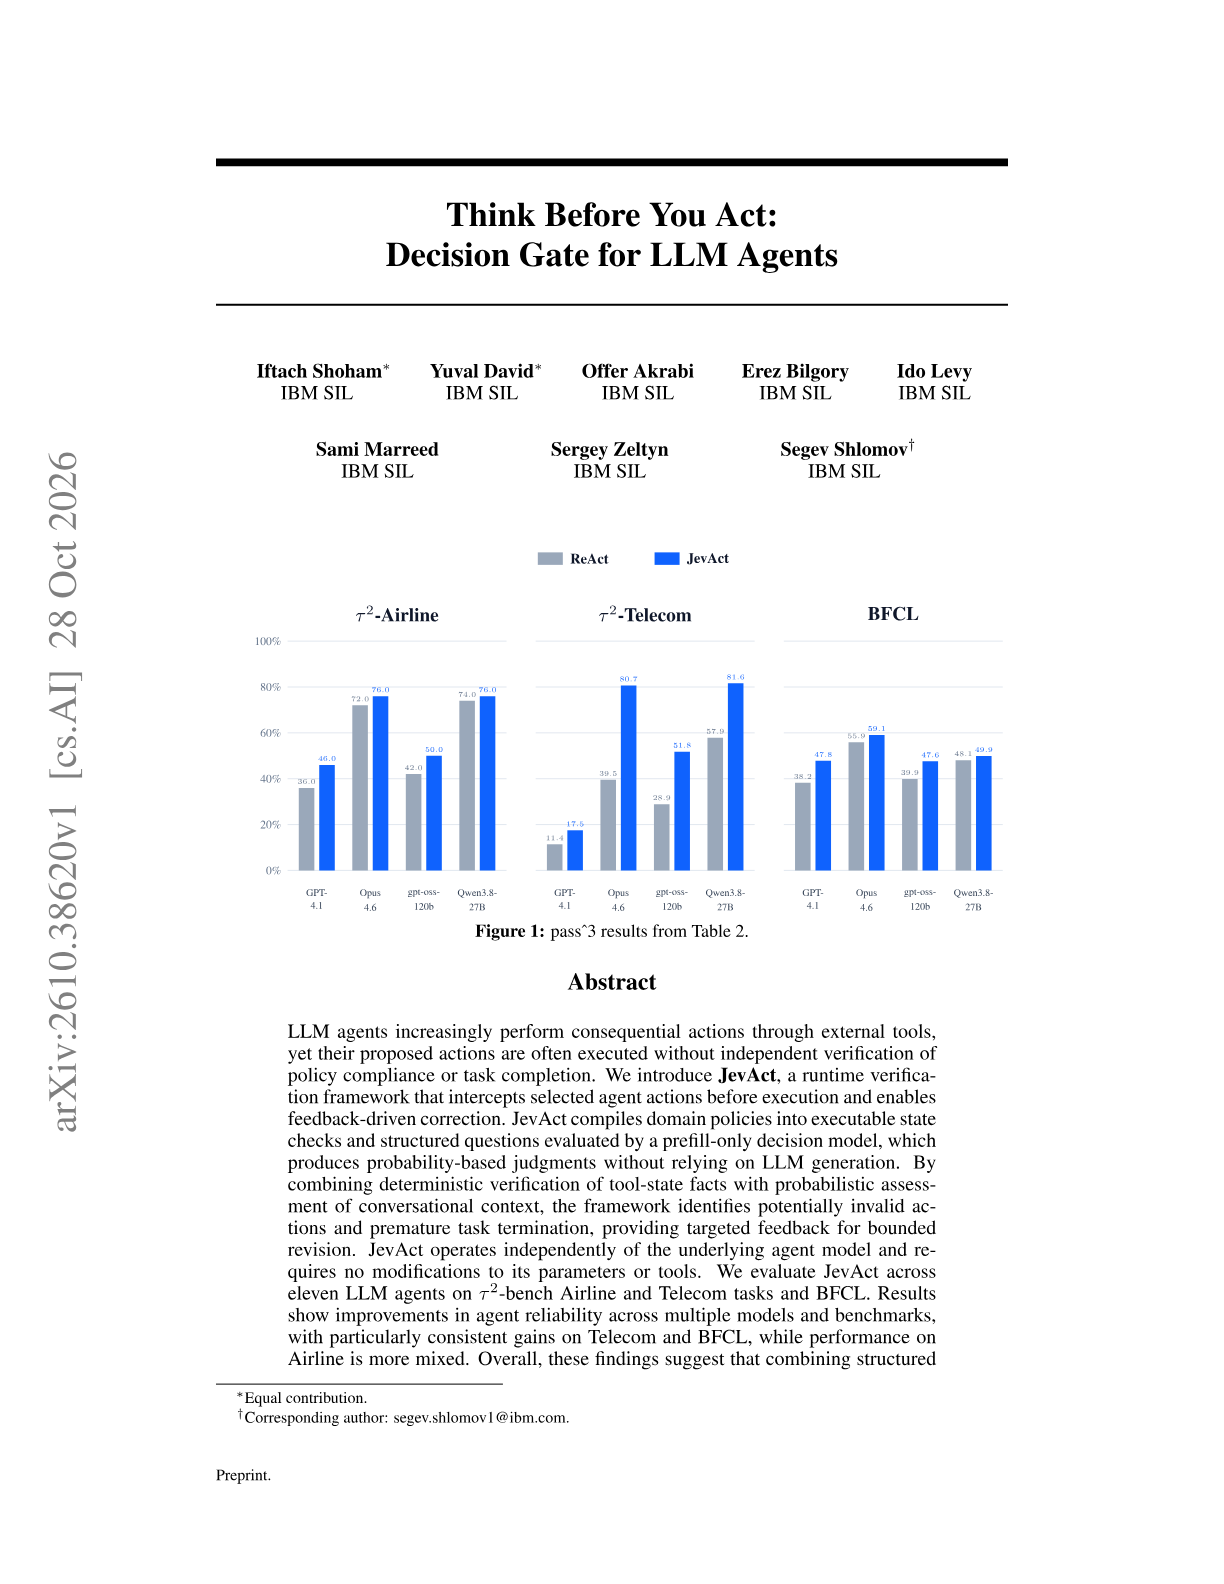
Telecom gains. On τ²-bench Telecom, all eight agents improve. Three-run success rises by 16.9 points on average, and Opus 4.6 moves from 39.5% to 80.7%.
Mixed elsewhere. On BFCL, all nine agents improve in three-run success, while at-least-once results are mixed. Airline changes are smaller and vary by agent.
Stated limits. The Telecom gain does not appear with a gpt-oss-120b user simulator. On 260 labelled development write calls, 42 of 101 incorrect calls break no compiled question.
Abstract
LLM agents increasingly perform consequential actions through external tools, yet their proposed actions are often executed without independent verification of policy compliance or task completion. We introduce JevAct, a runtime verification framework that intercepts selected agent actions before execution and enables feedback-driven correction. JevAct compiles domain policies into executable state checks and structured questions evaluated by a prefill-only decision model, which produces probability-based judgments without relying on LLM generation. By combining deterministic verification of tool-state facts with probabilistic assessment of conversational context, the framework identifies potentially invalid actions and premature task termination, providing targeted feedback for bounded revision. JevAct operates independently of the underlying agent model and requires no modifications to its parameters or tools. We evaluate JevAct across eleven LLM agents on $τ^2$-bench Airline and Telecom tasks and BFCL. Results show improvements in agent reliability across multiple models and benchmarks, with particularly consistent gains on Telecom and BFCL, while performance on Airline is more mixed. Overall, these findings suggest that combining structured decision models with executable verification can improve the reliability of tool-using LLM agents.