TRACER: Trajectory-Aware Tool Retrieval for LLM Agents
Tanish Kher, Dezhi Hong and colleagues at Microsoft present TRACER, a tool-retrieval front end that indexes observed tool-call sequences in a trie and exposes only the likely next tools, which raises tool-selection accuracy while cutting input tokens.
Ask this paper
Method. Past tool-call sequences are stored in a trie. Candidate continuations are ranked with a learned blend of empirical sequence priors and contextual priors, and only the top few tools are shown to the model.
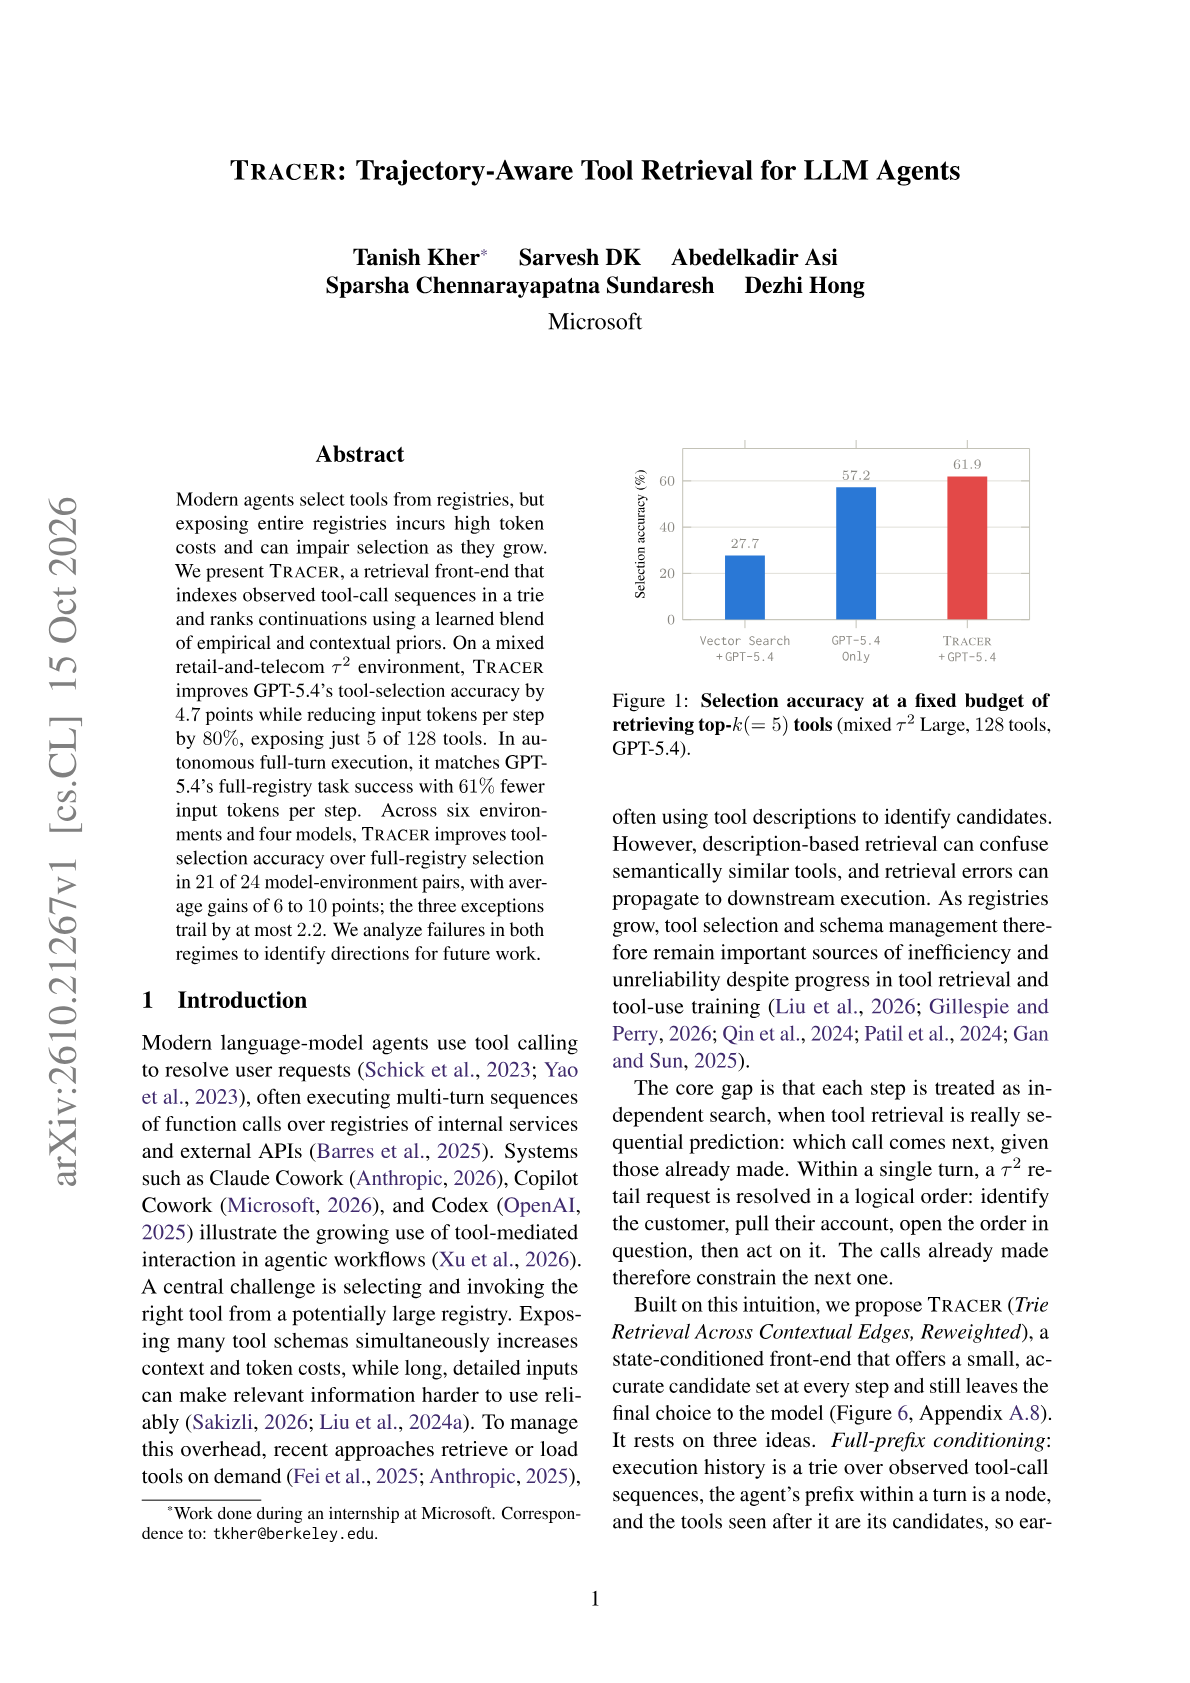
Tau-squared result. On a mixed retail and telecom tau-squared environment with 128 tools, exposing 5 tools raises GPT-5.4 tool-selection accuracy by 4.7 points and cuts input tokens per step by 80%.
Full-turn execution. In autonomous runs it matches GPT-5.4's full-registry task success with 61% fewer input tokens per step.
Breadth. Across six environments and four models, TRACER beats full-registry selection in 21 of 24 pairs, with average gains of 6 to 10 points. The three losses trail by at most 2.2 points.
Takeaway. For large tool registries, the order in which tools were called before is a strong retrieval signal.
Abstract
Modern agents select tools from registries, but exposing entire registries incurs high token costs and can impair selection as they grow. We present TRACER, a retrieval front-end that indexes observed tool-call sequences in a trie and ranks continuations using a learned blend of empirical and contextual priors. On a mixed retail-and-telecom $τ^2$ environment, TRACER improves GPT-5.4's tool-selection accuracy by 4.7 points while reducing input tokens per step by 80%, exposing just 5 of 128 tools. In autonomous full-turn execution, it matches GPT-5.4's full-registry task success with 61% fewer input tokens per step. Across six environments and four models, TRACER improves tool-selection accuracy over full-registry selection in 21 of 24 model-environment pairs, with average gains of 6 to 10 points; the three exceptions trail by at most 2.2. We analyze failures in both regimes to identify directions for future work.