UnifiedPlayers: Enhance Tool-Integrated Reasoning in Agentic Reinforcement Learning
Wenjie Liao, Liangjie Zhao and Zehong Cao train task generation, execution and evaluation jointly in UnifiedPlayers, rather than pairing self-generated trajectories with a static verifier.
Ask this paper
Three players, role-specific rewards. A Planning Player generates tasks, an Execution Player produces multi-turn trajectories with Python tool calls, and an Evaluation Player constructs executable verifiers, coordinated toward a shared objective under GRPO.
The coordination problem is stated explicitly. Each component changes the data or feedback used to train the others, which is why prior work froze the verifier.
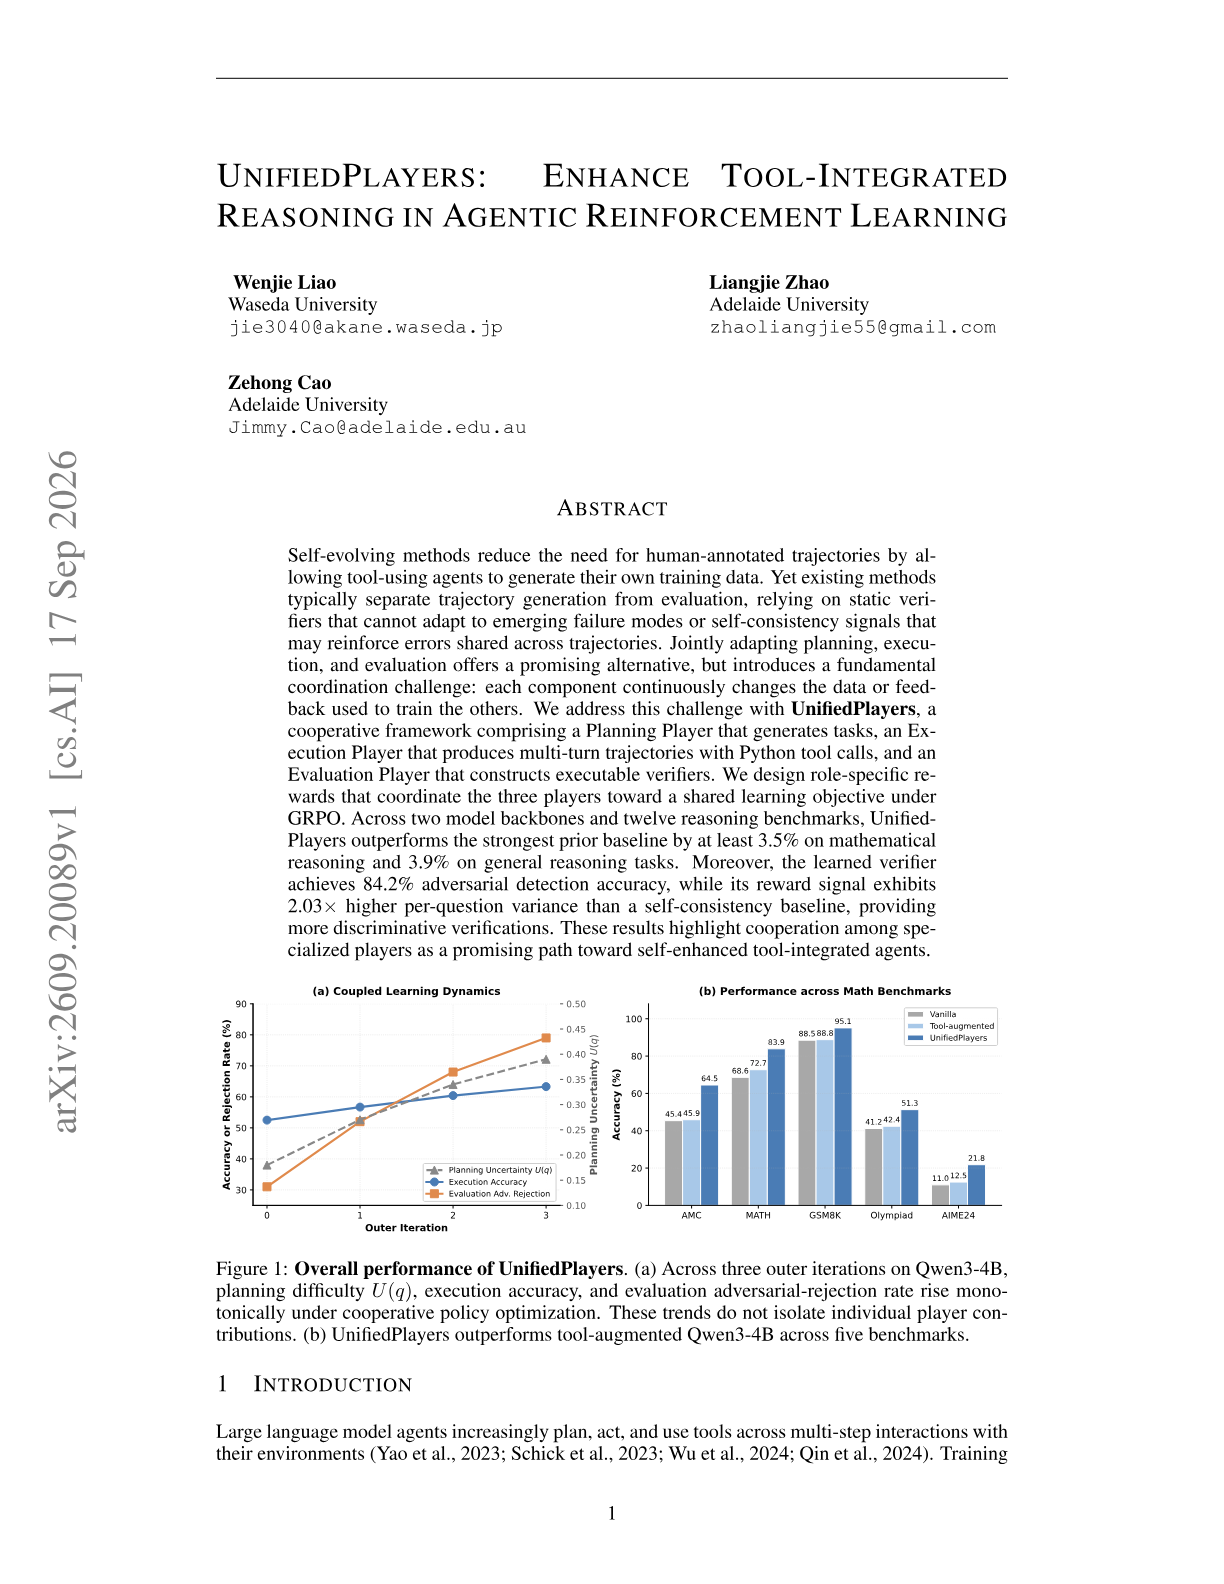
At least 3.5 and 3.9 points over the strongest baseline. On mathematical and general reasoning respectively, across two backbones and twelve benchmarks.
The learned verifier is more discriminative. 84.2 percent adversarial detection accuracy, with reward signal variance per question 2.03 times higher than a self-consistency baseline.
Abstract
Self-evolving methods reduce the need for human-annotated trajectories by allowing tool-using agents to generate their own training data. Yet existing methods typically separate trajectory generation from evaluation, relying on static verifiers that cannot adapt to emerging failure modes or self-consistency signals that may reinforce errors shared across trajectories. Jointly adapting planning, execution, and evaluation offers a promising alternative, but introduces a fundamental coordination challenge: each component continuously changes the data or feedback used to train the others. We address this challenge with \textbf{UnifiedPlayers}, a cooperative framework comprising a Planning Player that generates tasks, an Execution Player that produces multi-turn trajectories with Python tool calls, and an Evaluation Player that constructs executable verifiers. We design role-specific rewards that coordinate the three players toward a shared learning objective under GRPO. Across two model backbones and twelve reasoning benchmarks, UnifiedPlayers outperforms the strongest prior baseline by at least 3.5\% on mathematical reasoning and 3.9\% on general reasoning tasks. Moreover, the learned verifier achieves 84.2\% adversarial detection accuracy, while its reward signal exhibits 2.03$\times$ higher per-question variance than a self-consistency baseline, providing more discriminative verifications. These results highlight cooperation among specialized players as a promising path toward self-enhanced tool-integrated agents.