Verify by Doing: Co-Evolving Agent Execution and Evaluation without External Feedback
Yitong Lin, Jianda Chen, Wei Wu and colleagues at Ant International and Zhejiang University introduce Verify by Doing (VbD), which co-evolves an Actor harness and an Evaluator harness within a single task when no external success signal is available.
Ask this paper
Problem. Self-improving agents need to know whether a task succeeded. Without external feedback, a weak verifier steers updates in the wrong direction.
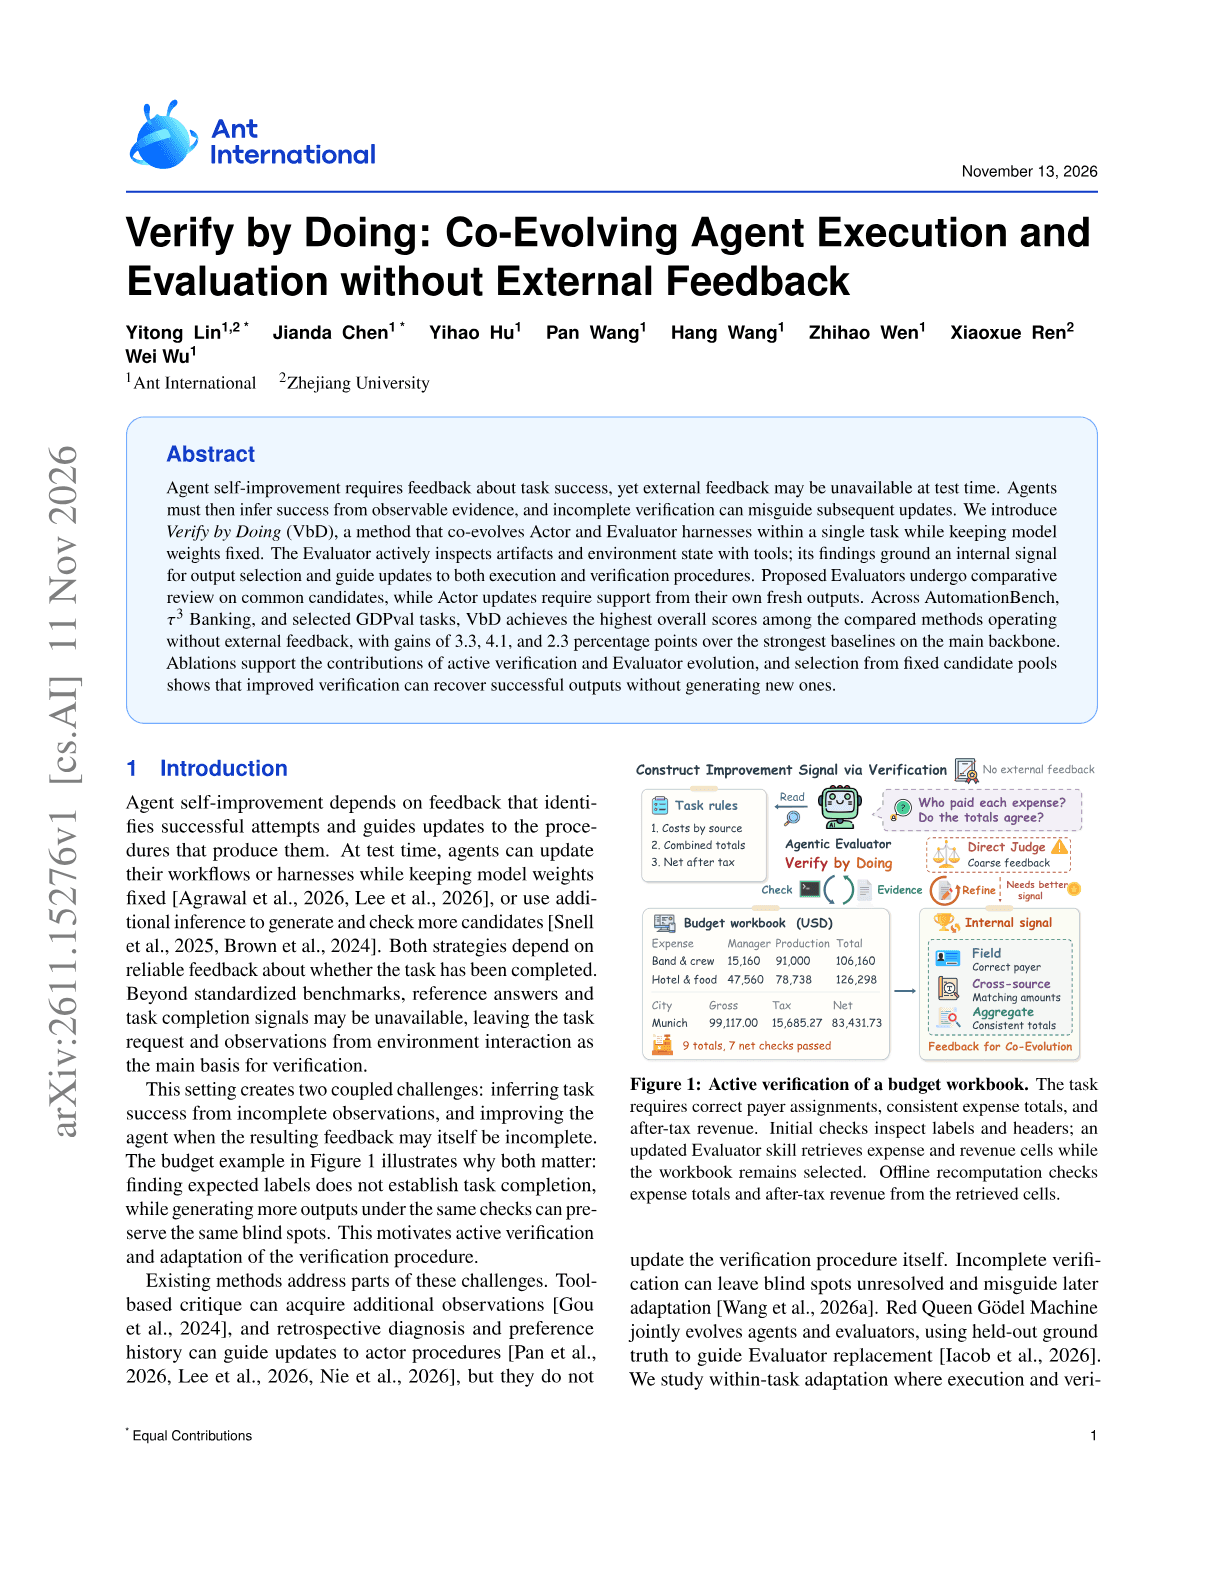
Active verification. The Evaluator inspects artifacts and environment state with tools, and its findings decide which output is selected and how both execution and verification procedures are updated. Model weights stay fixed.
Safeguards. New Evaluators are compared on a common set of candidates before adoption, and Actor updates are kept only if their own fresh outputs support them.
Results. On AutomationBench, tau3 Banking and selected GDPval tasks, VbD scores highest among methods without external feedback, beating the strongest baselines by 3.3, 4.1 and 2.3 points on the main backbone.
Ablation. Selecting from fixed candidate pools shows that a better Evaluator alone recovers successful outputs without generating new ones.
Abstract
Agent self-improvement requires feedback about task success, yet external feedback may be unavailable at test time. Agents must then infer success from observable evidence, and incomplete verification can misguide subsequent updates. We introduce Verify by Doing (VbD), a method that co-evolves Actor and Evaluator harnesses within a single task while keeping model weights fixed. The Evaluator actively inspects artifacts and environment state with tools; its findings ground an internal signal for output selection and guide updates to both execution and verification procedures. Proposed Evaluators undergo comparative review on common candidates, while Actor updates require support from their own fresh outputs. Across AutomationBench, $τ^3$ Banking, and selected GDPval tasks, VbD achieves the highest overall scores among the compared methods operating without external feedback, with gains of 3.3, 4.1, and 2.3 percentage points over the strongest baselines on the main backbone. Ablations support the contributions of active verification and Evaluator evolution, and selection from fixed candidate pools shows that improved verification can recover successful outputs without generating new ones.