A Preliminary Study of o1 in Medicine
First page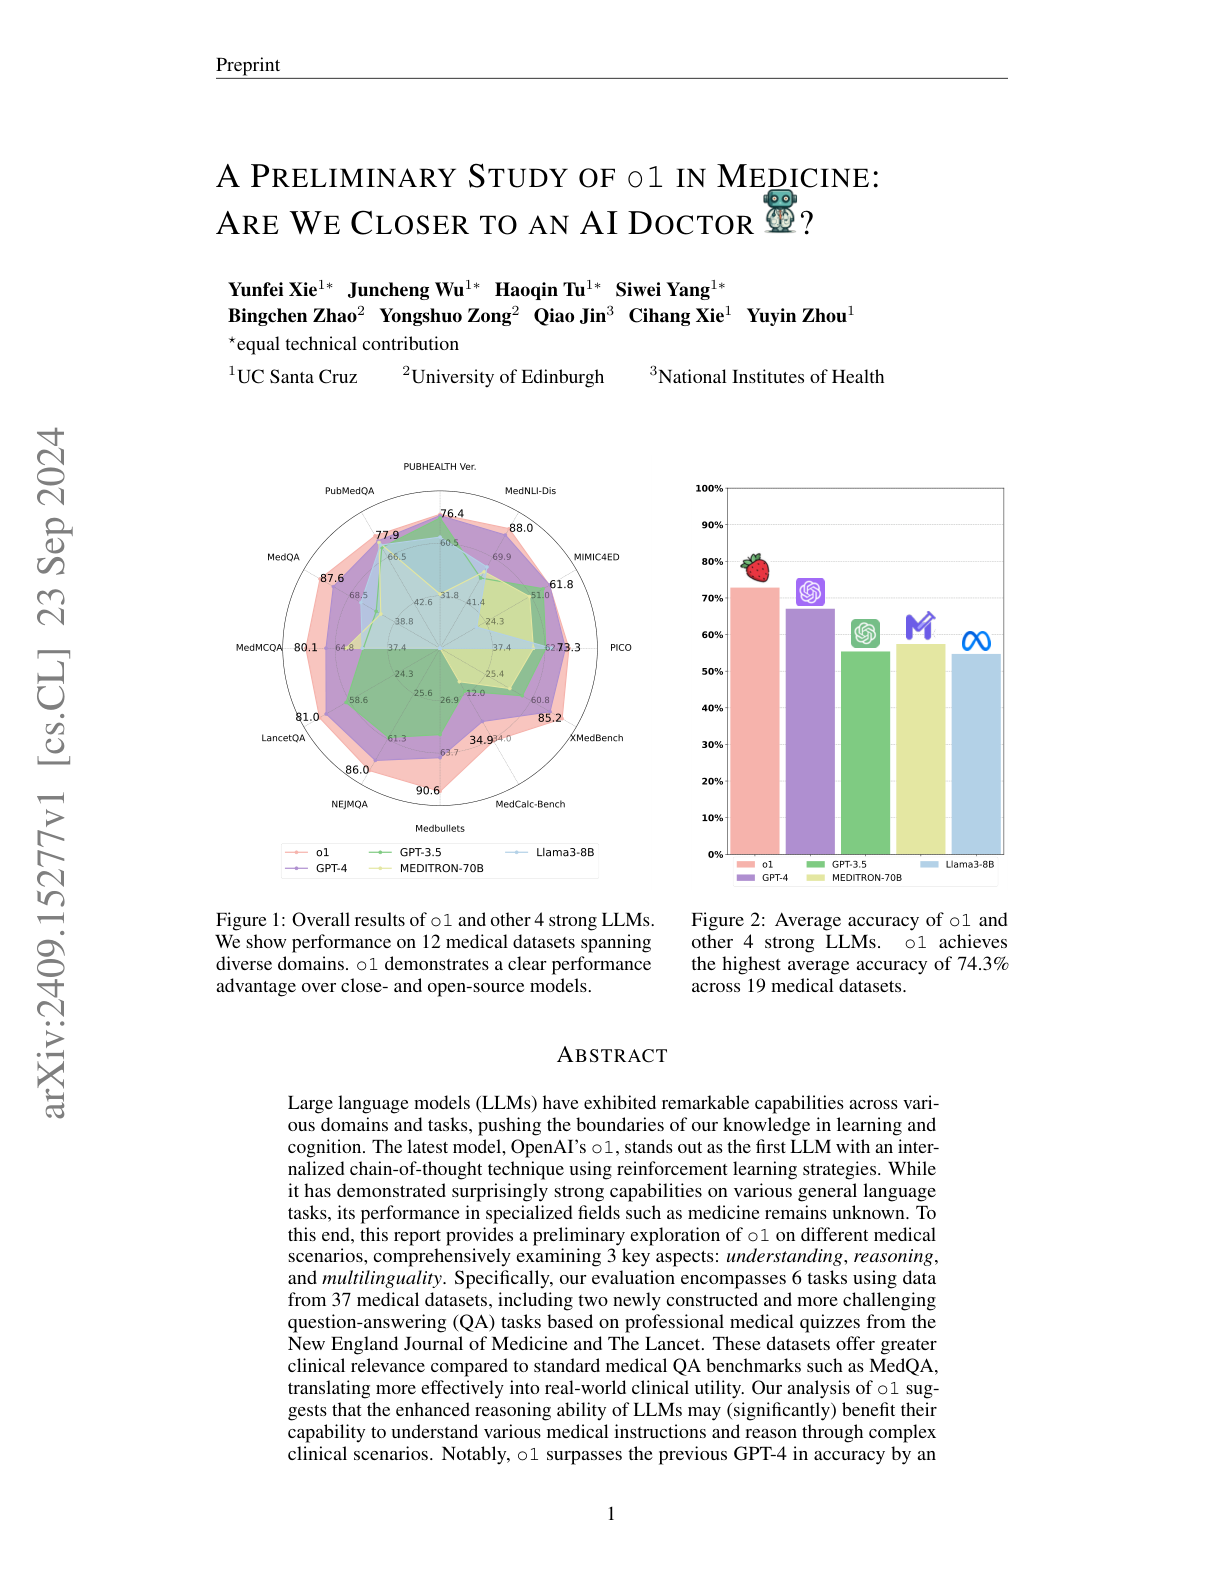
Paper summary
provides a preliminary exploration of the o1-preview model in medical scenarios; shows that o1 surpasses the previous GPT-4 in accuracy by an average of 6.2% and 6.6% across 19 datasets and two newly created complex QA scenarios; identifies hallucination, inconsistent multilingual ability, and discrepant metrics for evaluation.