AgentBench
First page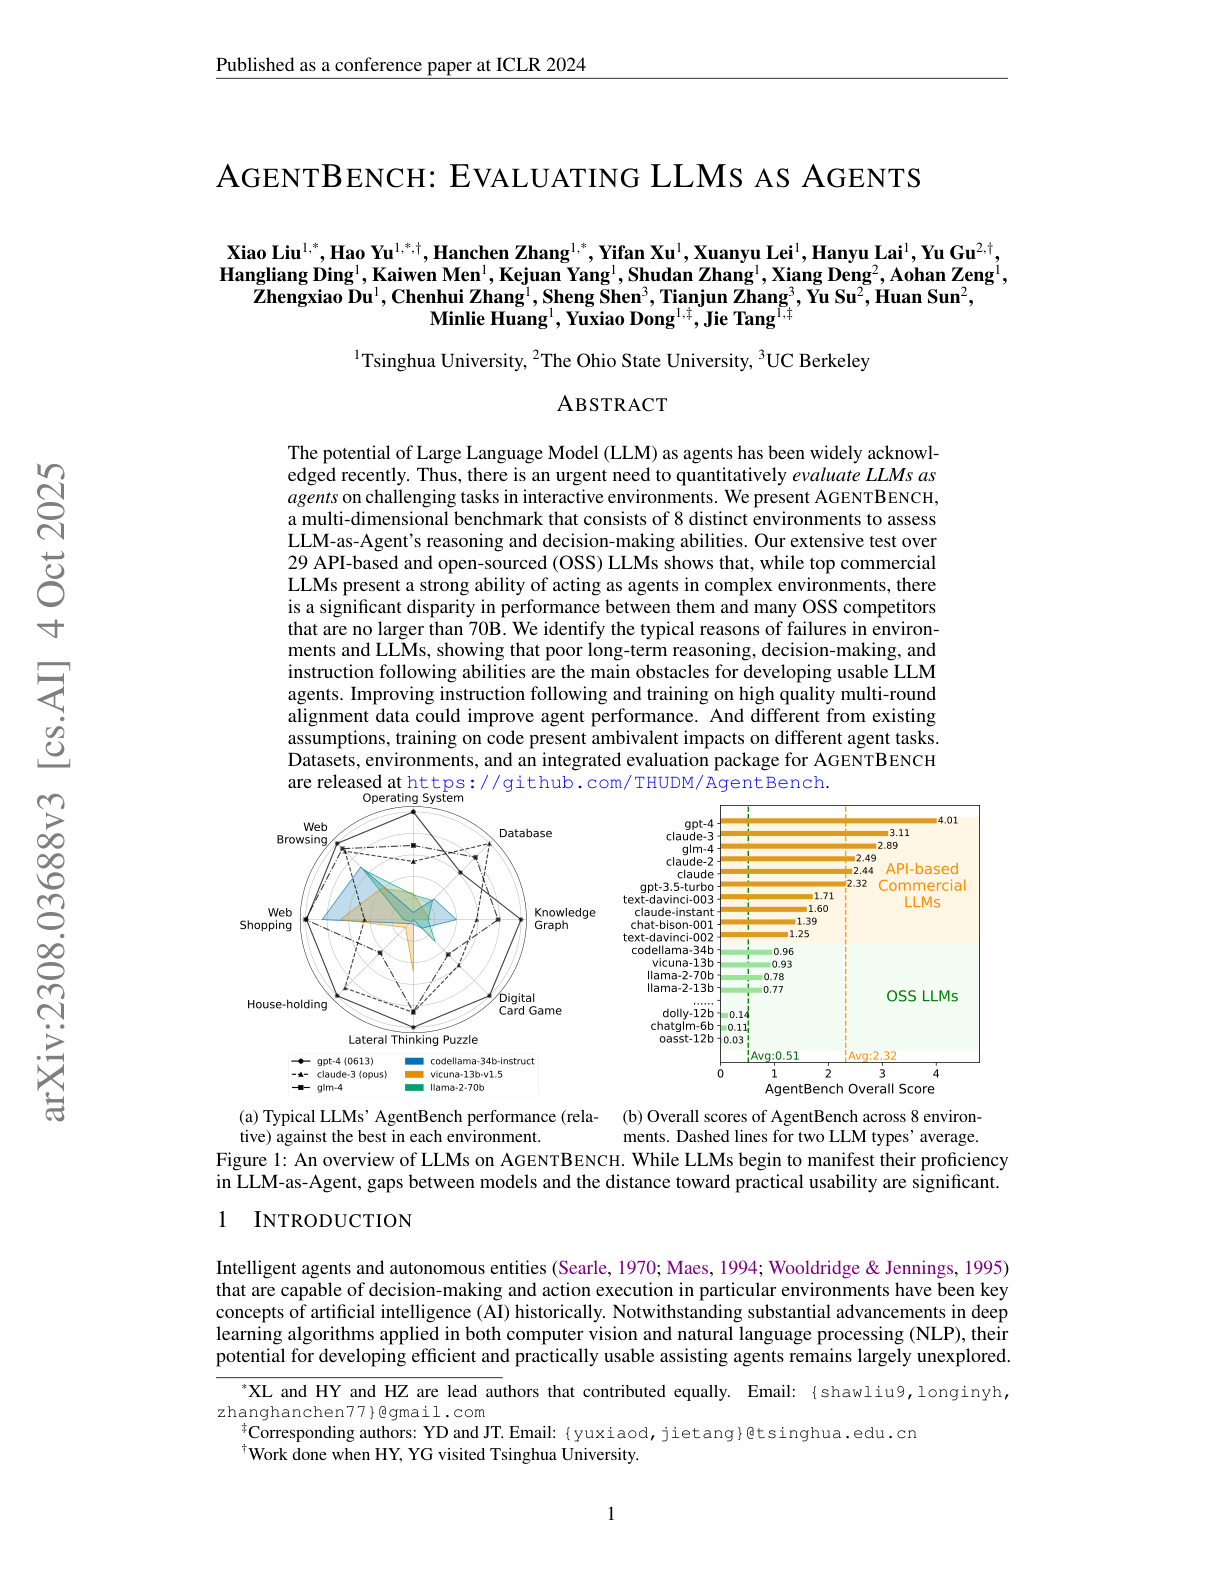
Paper summary
Tsinghua's AgentBench is a multidimensional benchmark for LLM-as-Agent reasoning and decision-making across 8 environments.
Ask this paper
01
Multi-environment design: Tests agents across 8 diverse environments including web browsing, operating systems, databases, and games - capturing breadth of agent demands.
02
Open vs. commercial gap: Reveals a significant performance gap between top commercial LLMs (GPT-4) and open-source models on agent tasks.
03
Open-source lags: Open-source LLMs lag substantially on AgentBench, exposing a gap that subsequent open-agent fine-tuning efforts targeted.
04
GPT-4 shows potential: GPT-4's performance demonstrates that frontier models can support continuously learning agents, even if they're not there yet.