Atria Dawn: The Dawn of Agentic Superintelligence
The Atria Team, a consortium whose paper carries the logos of Shanghai AI Laboratory, Fudan University, Renmin University and several Chinese Academy of Sciences institutes, releases Atria Dawn Preview, an agentic model for research and engineering work built on a 744B-parameter mixture-of-experts base, and reports how humans and agents divided the work while the model was being developed.
Ask this paper
Verifiable Experience Pipeline: Training connects each task and trajectory to a real execution environment and checks outcomes against external signals, so rewards come from verified artifacts rather than judged text.
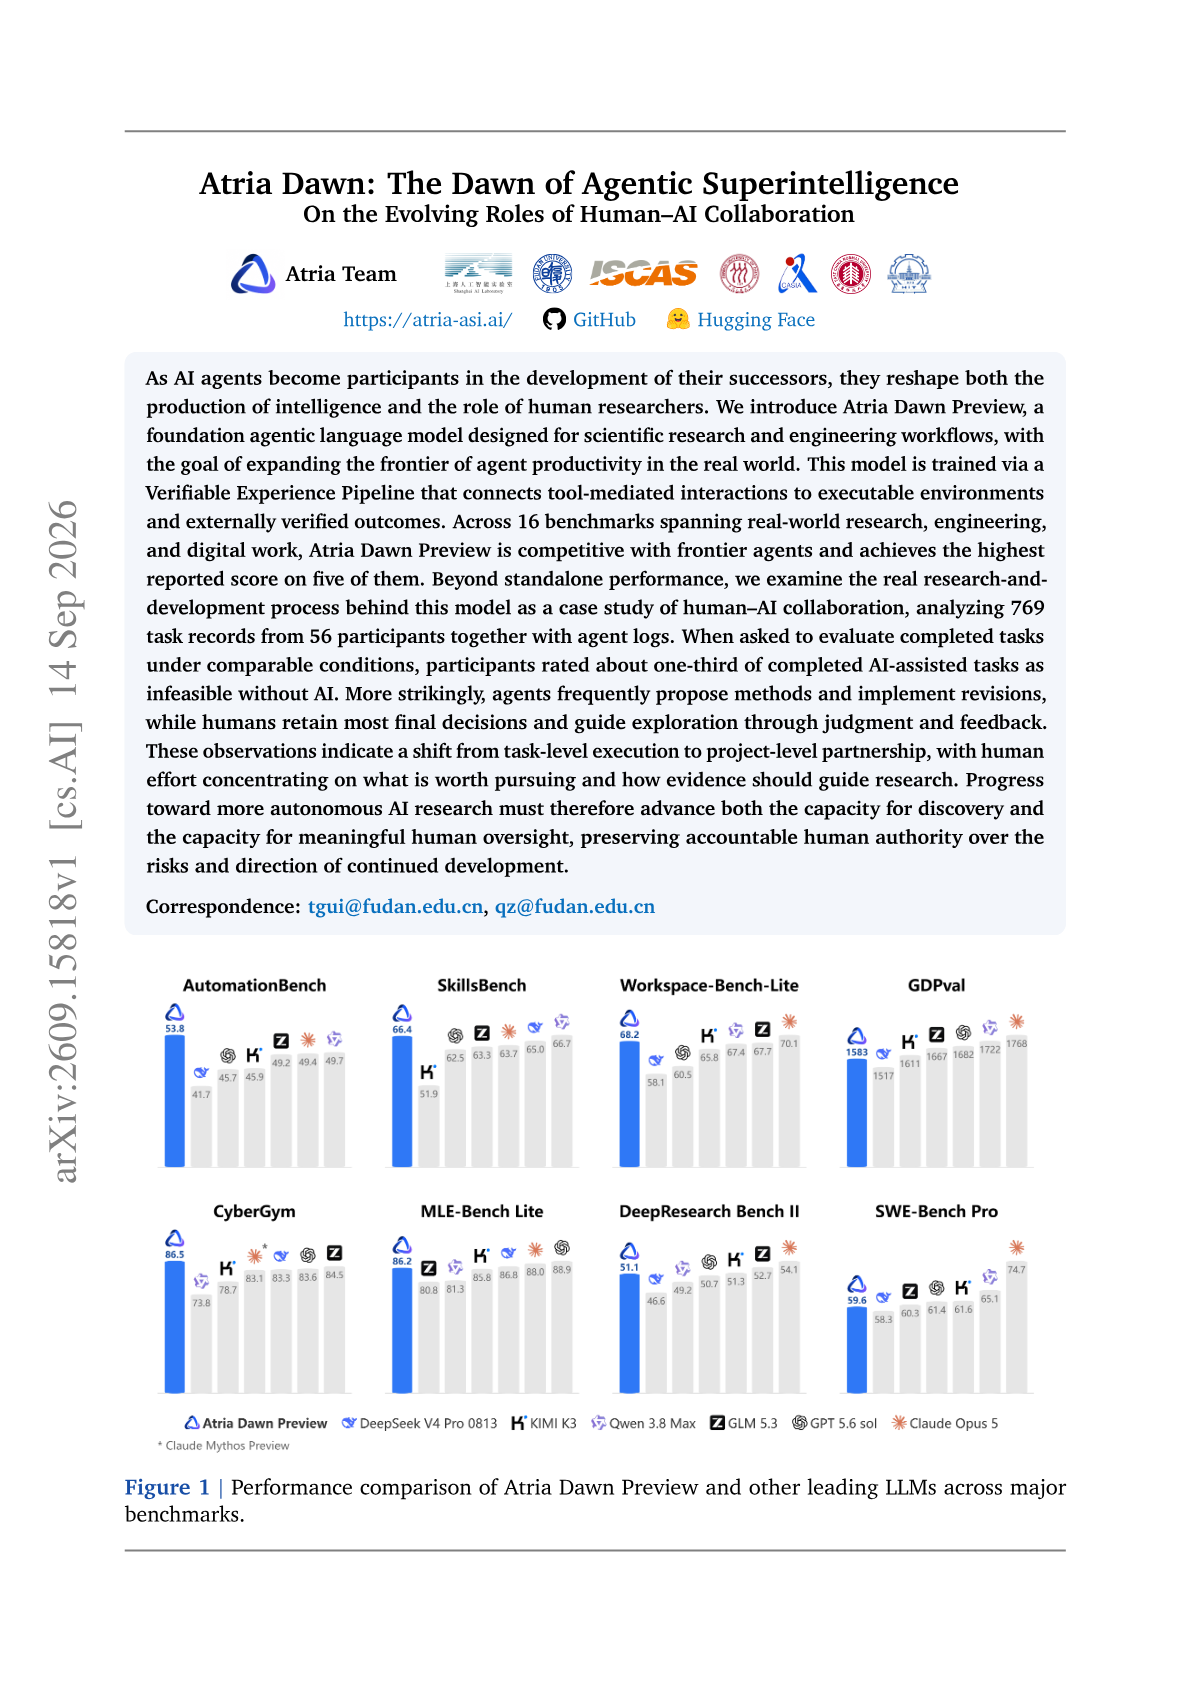
Benchmarks: Across 16 benchmarks covering tool use, search and research, workspace and professional tasks, software and terminal engineering, ML engineering and cybersecurity, the model is competitive with frontier agents and has the highest reported score on five.
Who proposed and who decided: In 769 task records from 56 participants, AI was used in 96.5% of the 739 tasks with a definitive answer. AI proposed 64.6% of 567 recorded methods and decisions, while humans made the final choice in 85.5%.
Human intervention: Of 588 tasks with recorded difficulties, 76.0% advanced because a human supplied context, clarification, diagnosis or a method change. Participants rated about one third of completed AI-assisted tasks as infeasible without AI.
Abstract
As AI agents become participants in the development of their successors, they reshape both the production of intelligence and the role of human researchers. We introduce Atria Dawn Preview, a foundation agentic language model designed for scientific research and engineering workflows, with the goal of expanding the frontier of agent productivity in the real world. This model is trained via a Verifiable Experience Pipeline that connects tool-mediated interactions to executable environments and externally verified outcomes. Across 16 benchmarks spanning real-world research, engineering, and digital work, Atria Dawn Preview is competitive with frontier agents and achieves the highest reported score on five of them. Beyond standalone performance, we examine the real research-and-development process behind this model as a case study of human--AI collaboration, analyzing 769 task records from 56 participants together with agent logs. When asked to evaluate completed tasks under comparable conditions, participants rated about one-third of completed AI-assisted tasks as infeasible without AI. More strikingly, agents frequently propose methods and implement revisions, while humans retain most final decisions and guide exploration through judgment and feedback. These observations indicate a shift from task-level execution to project-level partnership, with human effort concentrating on what is worth pursuing and how evidence should guide research. Progress toward more autonomous AI research must therefore advance both the capacity for discovery and the capacity for meaningful human oversight, preserving accountable human authority over the risks and direction of continued development.