AutoTTS
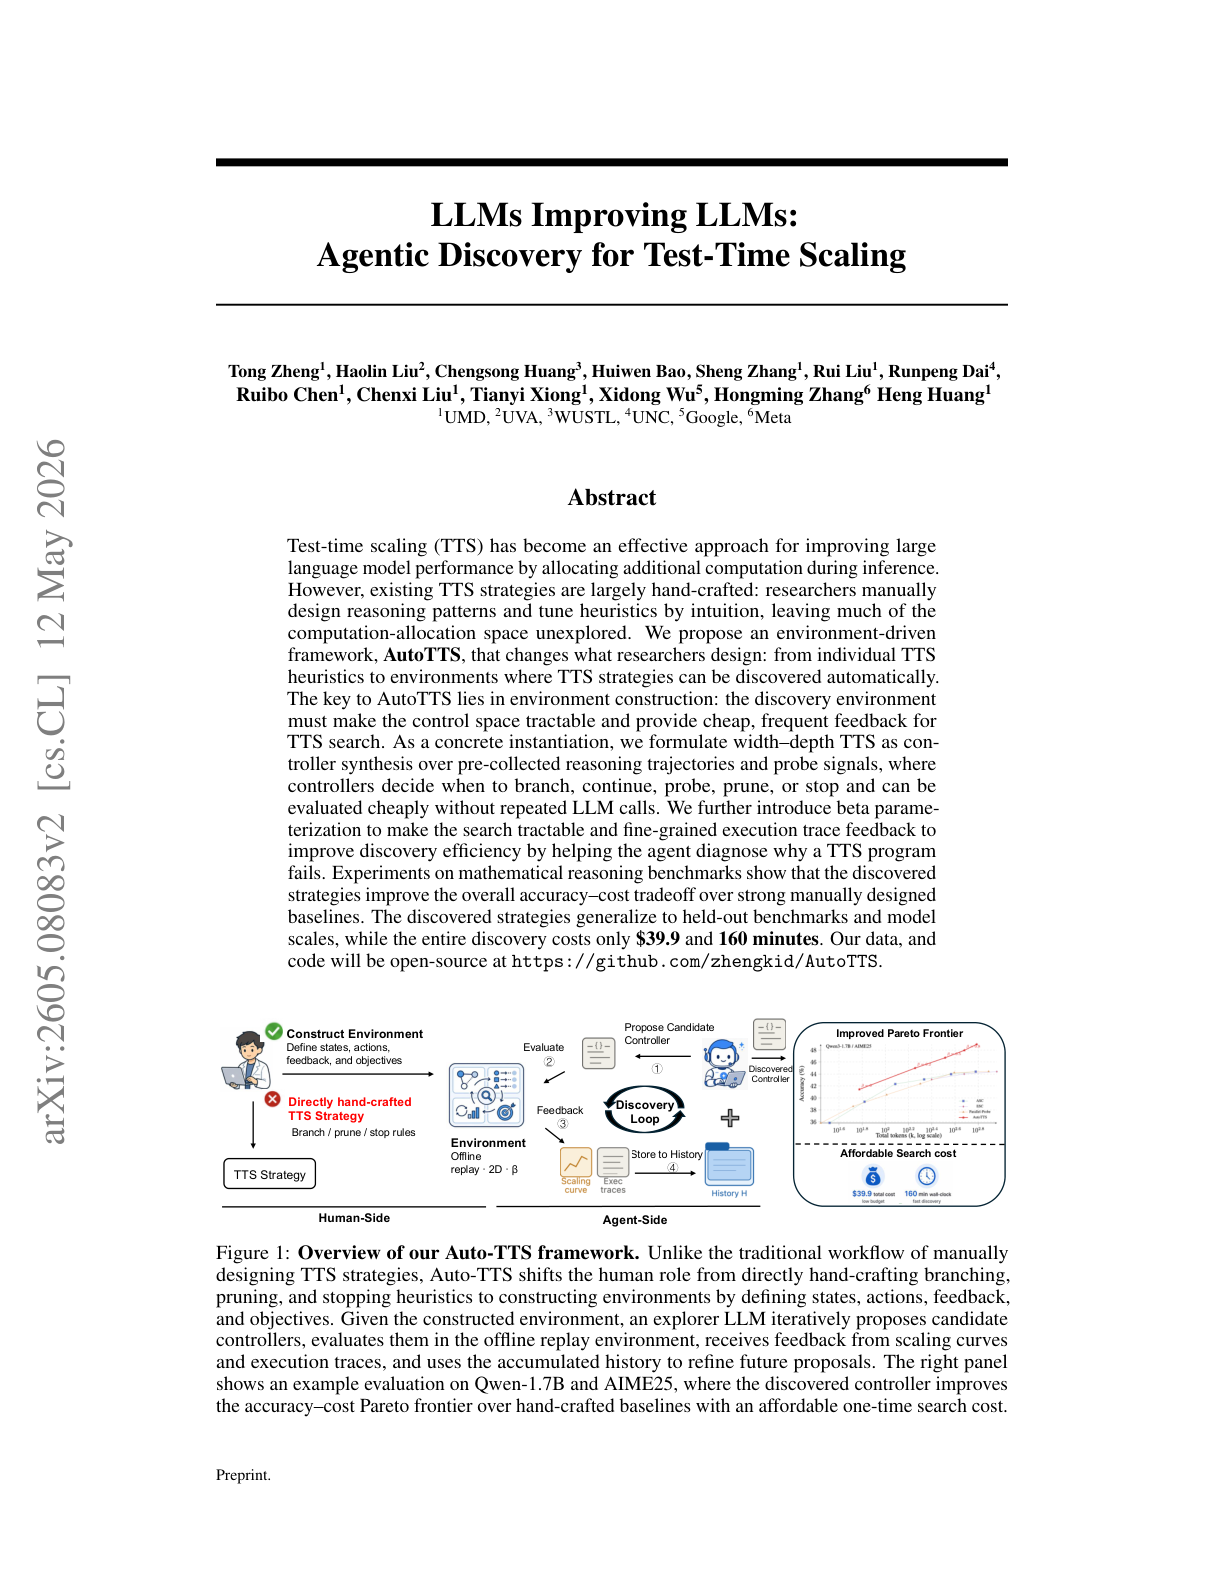
AutoTTS reframes test-time scaling as a search problem. Instead of designing branching, pruning, and stopping heuristics directly, the user constructs a discovery environment in which TTS strategies are searched automatically. Width-depth TTS is recast as controller synthesis over pre-collected reasoning trajectories and probe signals, so candidate controllers can be evaluated without repeated LLM calls.
Ask this paper
Discovery environment plus offline evaluator: The human specifies states, actions, and feedback. An explorer LLM iteratively proposes candidate controllers. Controllers are evaluated against pre-collected trajectories rather than by re-sampling the base model.
Beta parameterization and trace-level feedback: Beta parameterization makes the controller space tractable for search. Execution-trace feedback gives the explorer information about why a candidate failed, not only that it did.
Results on math reasoning benchmarks: Discovered controllers outperform hand-designed TTS recipes on the accuracy-cost Pareto frontier and transfer zero-shot to held-out benchmarks and model scales. Total discovery cost: $39.9 and 160 minutes.
Why it matters: Automated search over TTS strategies is competitive with hand-tuned heuristics at low cost, which shifts where the research effort needs to go.