Hacker Papers
- 01
Attention Is All You Need
Hacker News threads
- Jun 2017Deep Neural Networks – Attention is all you need (No recurrence or convolutions)
- Jun 2017Attention Is All You Need (Neural Networks)
- Jun 2025Attention Is All You Need
- Jun 2017Exploring LSTMs
- Apr 2020Building an end-to-end Speech Recognition model in PyTorch
- Mar 2023Google internally developed chatbots like ChatGPT years ago
- May 2023Why the Original Transformer LLM Figure Is Wrong, and Other Interesting Tidbits
- Dec 2023Ask HN: Daily practices for building AI/ML skills?
- Jan 2025Tensor Product Attention Is All You Need
- Mar 2026Ask HN: What are the greatest discoveries in the last few years?
- Sep 2026The AI Race Just Got Awkward
- 02
Language Models are Few-Shot Learners
Hacker News threads
- May 2020GPT-3: Language Models Are Few-Shot Learners
- Jun 2024Language Models Are Few-Shot Learners
- Nov 2024Language models are few-shot learners (2020)
- Jun 2020GPT-3 and Scaling Trends
- Jul 2020Show HN: Humans vs AI – A/B testing GPT-3
- Oct 2020AI training method exceeds GPT-3 performance with fewer parameters
- Oct 2022Why Mastering Language Is So Difficult for AI
- Feb 2023Why China Didn’t Invent ChatGPT
- May 2023Michael J. Fox Foundation Announces Breakthrough for Parkinson's Biomarker
- Nov 2023Sam Altman Exposes the Charade of AI Accountability
- Sep 2026GPT-6 Astra
- 03
Scaling Laws for Neural Language Models
Hacker News threads
- Feb 2020Scaling Laws for Neural Language Models
- Jun 2022Scaling Laws for Neural Language Models
- Sep 2026Scaling Laws for Neural Language Models (first "scaling laws" paper from 2020)
- Jan 2020Talking to myself: how I trained GPT2-1.5b for rubber ducking using my chat data
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Feb 2023Ask HN: How “real” are AI scaling laws?
- Apr 2023OpenAI’s CEO confirms the company isn’t training GPT-5 and ‘won’t for some time’
- Dec 2023Do large language models need all those layers?
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Feb 2026The Problem with LLMs
- Oct 2026Attention Is Not What You Need (2025)
- 04
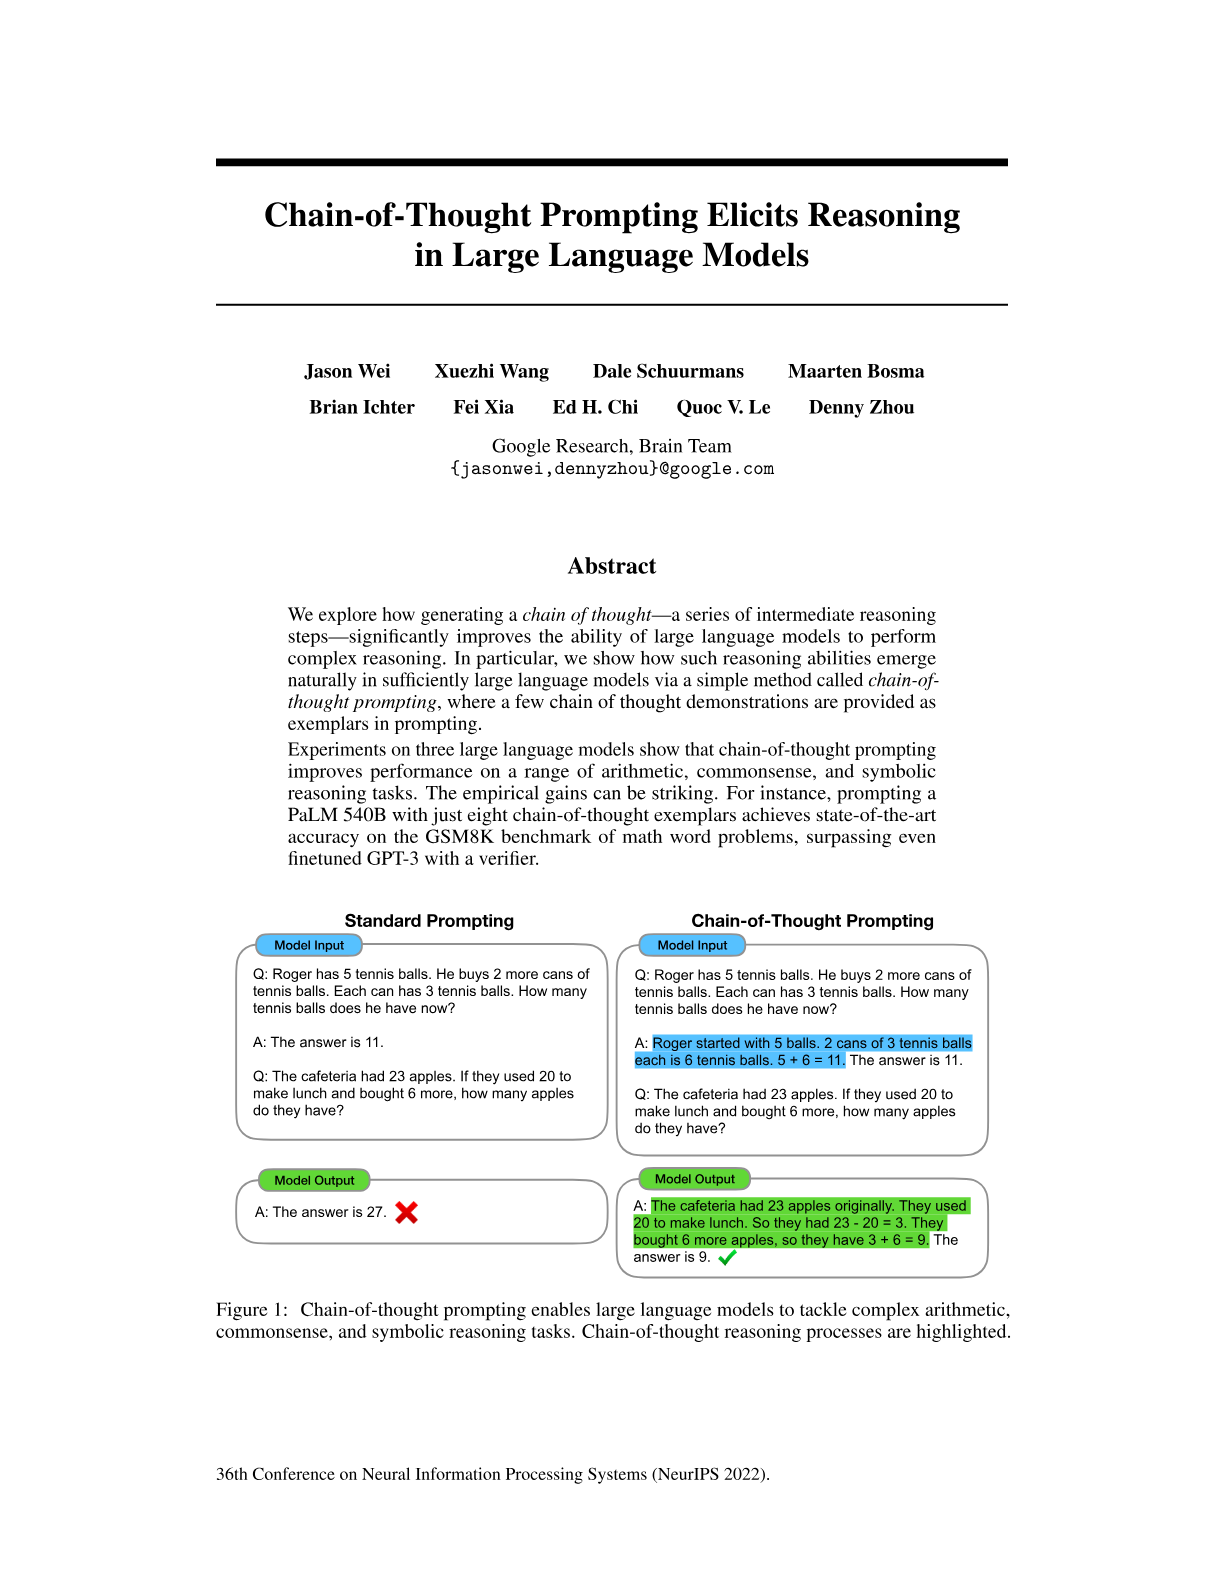
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Hacker News threads
- Apr 2022Chain of Thought Prompting Elicits Reasoning in Large Language Models
- Dec 2022Chain of Thought Prompting Elicits Reasoning in Large Language Models
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Jul 2022Am I doing it wrong? (OpenAI test)
- Mar 2023Oceania Always at War with Eastasia: Generative AI and Knowledge Pollution
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Aug 2023GPT-4 Can't Reason
- Sep 2024Training Language Models to Self-Correct via Reinforcement Learning
- Oct 2025Ortega hypothesis
- Sep 2026GPT-6 Astra
- 05
The Lottery Ticket Hypothesis: Finding Sparse, Trainable Neural Networks
Hacker News threads
- Jul 2018The Lottery Ticket Hypothesis: Finding Small, Trainable Neural Networks
- Mar 2018The Lottery Ticket Hypothesis: Training Pruned Neural Networks
- Oct 2020The Lottery Ticket Hypothesis: Finding Sparse, Trainable Neural Networks (2019)
- May 2019Smarter Training of Neural Networks
- Aug 2019Exploring Weight Agnostic Neural Networks
- Jun 2020Neurons that fire together, wire together, but how?
- Jul 2021Mammals dream about the world they are about to experience before they are born
- Oct 2022Substitute certain overhyped programming terms with more accurate replacements
- May 2023AI intensifies fight against ‘paper mills’ that churn out fake research
- Jan 2025OpenAI says it has evidence DeepSeek used its model to train competitor
- Apr 2026Show HN: SparseLab–real sparse training(CSR+custom kernel) in PyTorch, CPU-first
- 06
On the Measure of Intelligence
Hacker News threads
- Nov 2019The Measure of Intelligence: towards more human-like artificial systems
- Jun 2024The Measure of Intelligence
- Nov 2019François Chollet: The Measure of Intelligence
- Nov 2019What Would the Father of Cybernetics Think About A.I. Today?
- Jul 2020OpenAI's GPT-3 may be the biggest thing since Bitcoin
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- Jan 2023What Is AGI-Hard
- Mar 2024AIs ranked by IQ; AI passes 100 IQ for first time, with release of Claude-3
- Oct 2024Ask HN: Who is hiring? (October 2024)
- Jul 2025François Chollet: The Arc Prize and How We Get to AGI [video]
- Sep 2026Intelligence per Watt: Measuring Intelligence Efficiency of Local AI
- 07
Neural Turing Machines
Hacker News threads
- Oct 2014Neural Turing Machines [pdf]
- Oct 2014Neural Turing Machines
- May 2016Neural Turing Machines (2014)
- Feb 2015A Brief Overview of Deep Learning
- Jul 2015The Cyborg Compulsion
- Jan 2016Turing Machines Are Recurrent Neural Networks (1996)
- Jul 2016How AI based programming could work
- Jul 2017The Limitations of Deep Learning
- Jun 2020GPT-3 and Scaling Trends
- Jan 2023GPT-3: Techniques to improve reliability
- Oct 2026Show HN: A working Nintendo in ~1GB of Qwen weights
- 08
Emergent Abilities of Large Language Models
Hacker News threads
- Feb 2023Emergent Abilities of Large Language Models
- May 2024Emergent Abilities of Large Language Models
- Apr 2023Emergent Abilities of Large Language Models
- Dec 2022Ask HN: How does ChatGPT work?
- Feb 2023It Looks Like You’re Trying to Take over the World
- May 2023LLMs are not greater than the sum of their parts: Stanford researchers
- Jul 2023Llama 2 – Meta AI
- Nov 2023Telling GPT-4 you're scared or under pressure improves performance
- Mar 2024“Emergent” abilities in LLMs actually develop gradually and predictably – study
- Feb 2025Understanding Reasoning LLMs
- Aug 2026Humanity has the debate about AI consciousness backwards
- 09
A Neural Algorithm of Artistic Style
Hacker News threads
- Aug 2015A Neural Algorithm of Artistic Style [pdf]
- Aug 2015A Neural Algorithm of Artistic Style [pdf]
- Aug 2015A Neural Algorithm of Artistic Style
- Aug 2015
- Sep 2015Algorithm can create new Van Gogh or Picasso in an hour
- Feb 2016Visual Turing Test
- Apr 2016Technologists have produced a 3D-printed painting in the style of Rembrandt
- Sep 2016Implementation of Neural Style Transfer in Python and Keras
- Mar 2017Unpaired Image-to-Image Translation using Cycle-Consistent Adversarial Networks
- Nov 2017Confession as an AI researcher; seeking advice
- Apr 2023Study: ChatGPT Outperforms Physicians in Quality, Empathetic Answers to Patients
- 10
Training Compute-Optimal Large Language Models
Hacker News threads
- Apr 2022Training Compute-Optimal Large Language Models
- Mar 202270B language model outperforms Gopher and GPT-3
- Sep 2022Training Compute-Optimal Large Language Models
- Apr 2022Estimating PaLM's Training Cost
- Oct 2022GPT-3 can create both sides of an Interactive Fiction transcript
- Feb 2023Sundar Pichai: An important next step on our AI journey
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Apr 2023OpenAI’s CEO confirms the company isn’t training GPT-5 and ‘won’t for some time’
- Jul 2023Free and Fast LLM Finetuning
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jun 2026Cohere's First Model for Developers
- 11
Language Modeling Is Compression
Hacker News threads
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Show HN: 78% MNIST accuracy using GZIP in under 10 lines of code
- Jan 2024Getting Lossless Compression Adopted for Rigorous LLM Benchmarking
- Apr 2024EURISKO Lives
- May 2025The copilot delusion
- Jun 2025Fine-tuning LLMs is a waste of time
- Jan 2026Show HN: AI in SolidWorks
- Jun 2026Dune's Butlerian Jihad and the Future of AI
- Oct 2026OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
- 12
Intriguing properties of neural networks
Hacker News threads
- Feb 2015Intriguing Properties of Neural Networks [pdf]
- Jan 2019Intriguing properties of neural networks (2014)
- Jan 2015Intriguing properties of neural networks
- Apr 2014Neural Networks, Manifolds, and Topology
- Dec 2014Deep Neural Networks Are Easily Fooled
- Mar 2015Life Lessons from Machine Learning
- May 2016End to End Learning for Self-Driving Cars [pdf]
- Apr 2017Optical illusions that flummox computers
- Nov 2017How Adversarial Attacks Work
- Dec 2017Interview with Xavier Leroy
- Jan 2022Deep learning can’t be trusted, brain modelling pioneer says
- 13
The Pile: An 800GB Dataset of Diverse Text for Language Modeling
Hacker News threads
- Jun 2023The Pile: An 800GB Dataset of Diverse Text for Language Modeling
- May 2021The Pile: An 800GB Dataset of Diverse Text for Language Modeling
- Jul 2023The Pile: a dataset for language modeling [pdf]
- Mar 2021The makers of Eleuther hope it will be an open source alternative to GPT-3
- Apr 2022Textsynth: Bellard's free GPT-NeoX-20B, GPT-J playground and paid API
- Jan 2023The Limits of GPT-3 and Similar Large Language Models
- Apr 2023RedPajama: Reproduction of Llama with Friendly License (Stanford, MILA Quebec)
- Jul 2023Sarah Silverman is suing OpenAI and Meta for copyright infringement
- Sep 2023What OpenAI Really Wants
- Mar 2024DBRX: A new open LLM
- Apr 2026Even 'uncensored' models can't say what they want
- 14
GPT-4 Technical Report
Hacker News threads
- Apr 2023GPT-4 Technical Report
- Mar 2023OpenAI: GPT-4 Technical Report
- Mar 2023GPT-4 is Computer Vision on Steroids
- Mar 2023The danger isn’t that AI destroys us. It’s that it drives us insane
- Apr 2023We need to tell people ChatGPT will lie to them, not debate linguistics
- May 2023ChatGPT-Authored Legal Filing “Replete with Citations to Non-Existent Cases"
- Jul 2023Claude 2
- Jan 2024Using GPT-4 as a probabilistic classifier
- Apr 2024Meta Llama 3
- Oct 2026Why do LLM pelicans look like this?
- 15
Are Emergent Abilities of Large Language Models a Mirage?
Hacker News threads
- May 2023Are Emergent Abilities of Large Language Models a Mirage?
- Feb 2026Are Emergent Abilities of Large Language Models a Mirage? (2023)
- May 2023Scary 'Emergent' AI Abilities Are Just a 'Mirage', Stanford Study Says
- Jun 2023OpenLLaMA 13B Released
- Dec 2023Emergent Abilities of Large Language Models
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- Apr 2024Choose your weapon: Survival strategies for depressed AI academics
- May 2025Why do LLMs have emergent properties?
- Mar 2026Are LLMs not getting better?
- Sep 2026AI companies in race to demonstrate their model most threatening to humanity
- 16
Sparks of Artificial General Intelligence: Early experiments with GPT-4
Hacker News threads
- Mar 2023Sparks of Artificial General Intelligence: Early Experiments with GPT-4
- Apr 2025Sparks of Artificial General Intelligence: Early Experiments with GPT-4 (2023)
- Mar 2023ChatGPT Plugins
- Mar 2023Microsoft Researchers Claim GPT-4 Is Showing “Sparks” of AGI
- Mar 2023HN thread 35350030
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- Apr 2023AGI Is Not Chess Bots – They Will Replace Your Jobs
- Jul 2023GPT-4 API General Availability
- Jul 2024ChatGPT is better at generating code for problems written before 2021
- Aug 2026Karpathy's Pelican
- 17
TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
Hacker News threads
- Jan 2025TinyStories: How Small Can Language Models Be and Still Speak Coherent English? (2023)
- May 2023TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
- May 2023How Small Can Language Models Be and Still Speak Coherent English?
- May 2023Apple bans ChatGPT use by employees, report says
- Jun 2023Modern language models refute Chomsky’s approach to language
- Jun 2023The Darwinian argument for worrying about AI
- Oct 2023Disney Packed Big Emotion into a Little Robot
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- May 2024“Imprecise” language models are smaller, speedier, and nearly as accurate
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Sep 2026MicroLLM Lab – Try 7 tiny LLM's in the browser
- 18
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Hacker News threads
- Oct 2018BERT: Pre-Training of Deep Bidirectional Transformers for Language Understanding
- Apr 2023Bert: Pre-Training of Deep Bidirectional Transformers for Language Understanding
- Nov 2018TensorFlow Code for Google Research's BERT: Pre-Training Method for NLP Tasks
- Feb 2019Microsoft’s New MT-DNN Outperforms Google BERT
- Mar 2019Yann LeCun, Geoffrey Hinton and Yoshua Bengio win Turing Award
- Sep 2019At Tech’s Leading Edge, Worry About a Concentration of Power
- Mar 2023Google internally developed chatbots like ChatGPT years ago
- Jul 2023Ask HN: How to Break into AI Engineering
- Oct 2023Ask HN: Why is OpenAI still called OpenAI?
- Jun 2026Superintelligence: The Idea That Eats Smart People (2016)
- 19
Generative Adversarial Networks
Hacker News threads
- May 2023Generative Adversarial Networks
- Nov 2016Generative Adversarial Nets [pdf]
- Jun 2014Does Deep Learning Have Deep Flaws?
- Jan 2017Game Theory Reveals the Future of Deep Learning
- Aug 2017Ask HN: What is your favorite CS paper?
- Jan 2018AI System Sorts News Articles by Whether or Not They Contain Actual Information
- Jun 2020AI vs. AI
- May 2022Apple's director of machine learning resigns due to return to office work
- Nov 2023SDXL Turbo: A Real-Time Text-to-Image Generation Model
- Sep 2024Xkcd 1425 (Tasks) turns ten years old today
- 20
The Case for Learned Index Structures
Hacker News threads
- Dec 2017The Case for Learned Index Structures
- Dec 2017The Case for Learned Index Structures
- Dec 2017The Case for Learned Index Structures
- Dec 2017Machine Learning for Systems and Systems for Machine Learning [pdf]
- Dec 2017My Favorite Papers of 2017
- Feb 2018Chip advances require fresh ideas, speakers say
- May 2018An O(N) Sorting Algorithm: Machine Learning Sorting
- Nov 2018Optimal Shard Placement in a Petabyte Scale Elasticsearch Cluster
- Oct 2020Using Lidar to Add Autofocus to a Manual Focus Lens
- Jul 2022Ask HN: What are some cool but obscure data structures you know about?
- Jun 2026"They're made out of weights"
- 21
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Hacker News threads
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024Nvidia CEO Jensen Huang announces new AI chips: ‘We need bigger GPUs’
- May 2024GPUs Go Brrr
- Jun 2024Scalable MatMul-Free Language Modeling
- Jan 2025Run DeepSeek R1 Dynamic 1.58-bit
- Jun 2025AMD's Freshly-Baked MI350: An Interview with the Chief Architect
- Jan 2026Kimi Released Kimi K2.5, Open-Source Visual SOTA-Agentic Model
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Sep 2026Breaking the 1.58-bit Barrier for Ternary LLMs
- 22
Distilling the Knowledge in a Neural Network
Hacker News threads
- Mar 2015Distilling the Knowledge in a Neural Network
- Jul 2015How Google Translate squeezes deep learning onto a phone
- Mar 2016AlphaGo beats Lee Sedol 3-0 [video]
- Apr 2017The Myth of a Superhuman AI
- Dec 2017Neural Networks in JavaScript with Deeplearn.js
- Apr 2022Scientists discover specific neurons involved in making memories
- Mar 2023Could you train a ChatGPT-beating model for $85,000 and run it in a browser?
- Mar 2026NanoGPT Slowrun: 10x Data Efficiency with Infinite Compute
- Aug 2026OpenAI: GPT 5.6 Sol price reduction (until at least Nov 21)
- 23
Understanding deep learning requires rethinking generalization
Hacker News threads
- Feb 2017Understanding deep learning requires rethinking generalization
- Dec 2018Understanding deep learning requires rethinking generalization
- Aug 2020Understanding Deep Learning Requires Re-Thinking Generalization (2017)
- Dec 2016LSTM Neural Networks for Time Series Prediction
- May 2017Deep Learning’s Impact on Image Processing, Mathematics, and Humanity
- Jan 2018Cloud AutoML: Making AI accessible to every business
- Oct 2018The Mixed Track Record of Machine Learning Algorithms
- Feb 2020A popular self-driving car dataset is missing labels for hundreds of pedestrians
- Mar 2021Understanding deep learning requires rethinking generalization
- May 2024Gradient descent visualization
- Mar 2025Deep Learning Is Not So Mysterious or Different
- 24
The Surprising Creativity of Digital Evolution: A Collection of Anecdotes from the Evolutionary Computation and Artificial Life Research Communities
Hacker News threads
- Apr 2018When algorithms surprise us
- Mar 2018Surprising Creativity: Anecdotes from Evolutionary Computation
- Mar 2018The Surprising Creativity of Digital Evolution: Artifical Life and EC Anecdotes
- Mar 2018Evolution Is the New Deep Learning
- Jun 2018Can “effective altruism” maximise the bang for each charitable buck?
- Nov 2018Evolved antenna
- Apr 2019Notes on AI Bias
- Mar 2021Lying to the Ghost in the Machine
- Jun 2021One bee has cloned itself millions of times over the past three decades
- Aug 2022John Carmack's new AGI company, Keen Technologies, has raised a $20M round
- Jun 2023Own-Goal Football (2022)
- 25
Evaluating Large Language Models Trained on Code
Hacker News threads
- Jul 2021Evaluating Large Language Models Trained on Code
- Jul 2021Evaluating Large Language Models Trained on Code
- Jul 2021Evaluating Large Language Models Trained on Code (paper about GH copilot model)
- Jul 2021All public GitHub code was used in training Copilot
- Sep 2021GitHub Copilot Generated Insecure Code in 40% of Circumstances During Experiment
- Dec 2021GPT-3 APIs are now in public beta
- Jul 2022ML code generation vs. coding by hand: what we think programming will look like
- May 2023Replit's new Code LLM: Open Source, 77% smaller than Codex, trained in 1 week
- Oct 2023Show HN: Phind Model beats GPT-4 at coding, with GPT-3.5 speed and 16k context
- Feb 2025AI is stifling new tech adoption?
- Jul 2025Mercury: Ultra-fast language models based on diffusion
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.