Hacker Papers
- 226
Monolith: Real Time Recommendation System With Collisionless Embedding Table
Hacker News threads
- Nov 2022Monolith: Real time recommendation system with collisionless embedding table
- Nov 2022TikTok published an article on their recommendation system architecture
- Nov 2022Paper on 'Monolith: Real Time Recommendation System' by Bytedance Inc (TikTok)
- Dec 2022TikTok’s Secret Sauce
- Jan 2023Ask HN: Techwise, how did TikTok get so good?
- Feb 2023The secret sauce of TikTok’s recommendations
- Nov 2023X is changing its algorithm to highlight smaller accounts
- Dec 2024TikTok divestment law upheld by federal appeals court
- Jan 2025TikTok preparing for U.S. shut-off on Sunday
- May 2025You Don't Need Re-Ranking: Understanding the Superlinked Vector Layer
- Feb 2026TikTok's 'Addictive Design' Found to Be Illegal in Europe
- 227
Thinking Like Transformers
Hacker News threads
- Jun 2021Thinking Like Transformers
- Jun 2023Thinking Like Transformers (pdf)
- Dec 2021The potential of transformers in reinforcement learning
- May 2023It's not just statistics: GPT-4 does reason
- Jun 2023From Word Models to World Models
- Aug 2023Graph of Thoughts: Solving Elaborate Problems with Large Language Models
- Sep 2023I made a transformer by hand (no training)
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Feb 2026I want to wash my car. The car wash is 50 meters away. Should I walk or drive?
- 228
Adversarial Patch
Hacker News threads
- Jan 2018Adversarial Patch [pdf]
- Jan 2018Adversarial Patch
- Dec 2017Adversarial Patch [pdf]
- May 2018Thanks to facial recognition, a third person is arrested following a pop concert
- Dec 2018Ask HN: Has anyone used adversarial patches for effect?
- Aug 2019Testing Robustness Against Unforeseen Adversaries
- Jan 2020How to be anonymous in the age of surveillance
- Apr 2020Some shirts hide you from cameras, but will anyone wear them?
- Mar 2024The Elements of Differentiable Programming
- 229
DensePose From WiFi
Hacker News threads
- Jan 2023DensePose from WiFi
- Jan 2023DensePose from WiFi Sensing: Full Body Tracking
- Jan 2023Accurate Pose Estimation via WiFi Signals and ML
- Jan 2023Accurate Pose Estimation via WiFi Signals
- Jan 2023WiFi Routers Used to Produce 3D Images of Humans
- Jan 2023Ask HN: What will be the first AI “incident”?
- Jul 2023French Assembly to allow remote police surveillance via phone cameras and mics
- Sep 2023WiFi can read through walls
- May 2024Wi-Fi devices set to become object sensors by 2024 via IEEE 802.11bf standard
- Apr 2025BPS is a GPS alternative that nobody's heard of
- Feb 2026WiFi Could Become an Invisible Mass Surveillance System
- 230
No "Zero-Shot" Without Exponential Data: Pretraining Concept Frequency Determines Multimodal Model Performance
Hacker News threads
- May 2024No "Zero-Shot" Without Exponential Data
- Apr 2024No "Zero-Shot" Without Exponential Data
- Apr 2024No "Zero-Shot" Without Exponential Data
- May 2024Geoffrey Hinton "godfather of AI" says that AI will surpass human intelligence
- Jun 2024Mathematical Optimization for Cargo Ships
- Jun 2024OpenAI and Apple Announce Partnership
- Jun 2024Ask HN: When will we hit a limit on LLM performance?
- Jul 2024Vision language models are blind
- Jul 2024Ask HN: Are there videos of people using AI for non-trivial coding?
- Nov 2024OpenAI, Google and Anthropic are struggling to build more advanced AI
- Feb 2026(AI) Slop Terrifies Me
- 231
Acquisition of Chess Knowledge in AlphaZero
Hacker News threads
- Nov 2021Acquisition of Chess Knowledge in AlphaZero
- Nov 2021Acquisition of Chess Knowledge in AlphaZero
- Nov 2021Acquisition of Chess Knowledge in AlphaZero [pdf]
- Nov 2021Acquisition of chess knowledge in AlphaZero
- Nov 2021Acquisition of chess knowledge in AlphaZero
- Dec 2021Can deep learning help mathematicians build intuition?
- Nov 2022Acquisition of chess knowledge in AlphaZero
- Feb 2026Experts Have World Models. LLMs Have Word Models
- 232
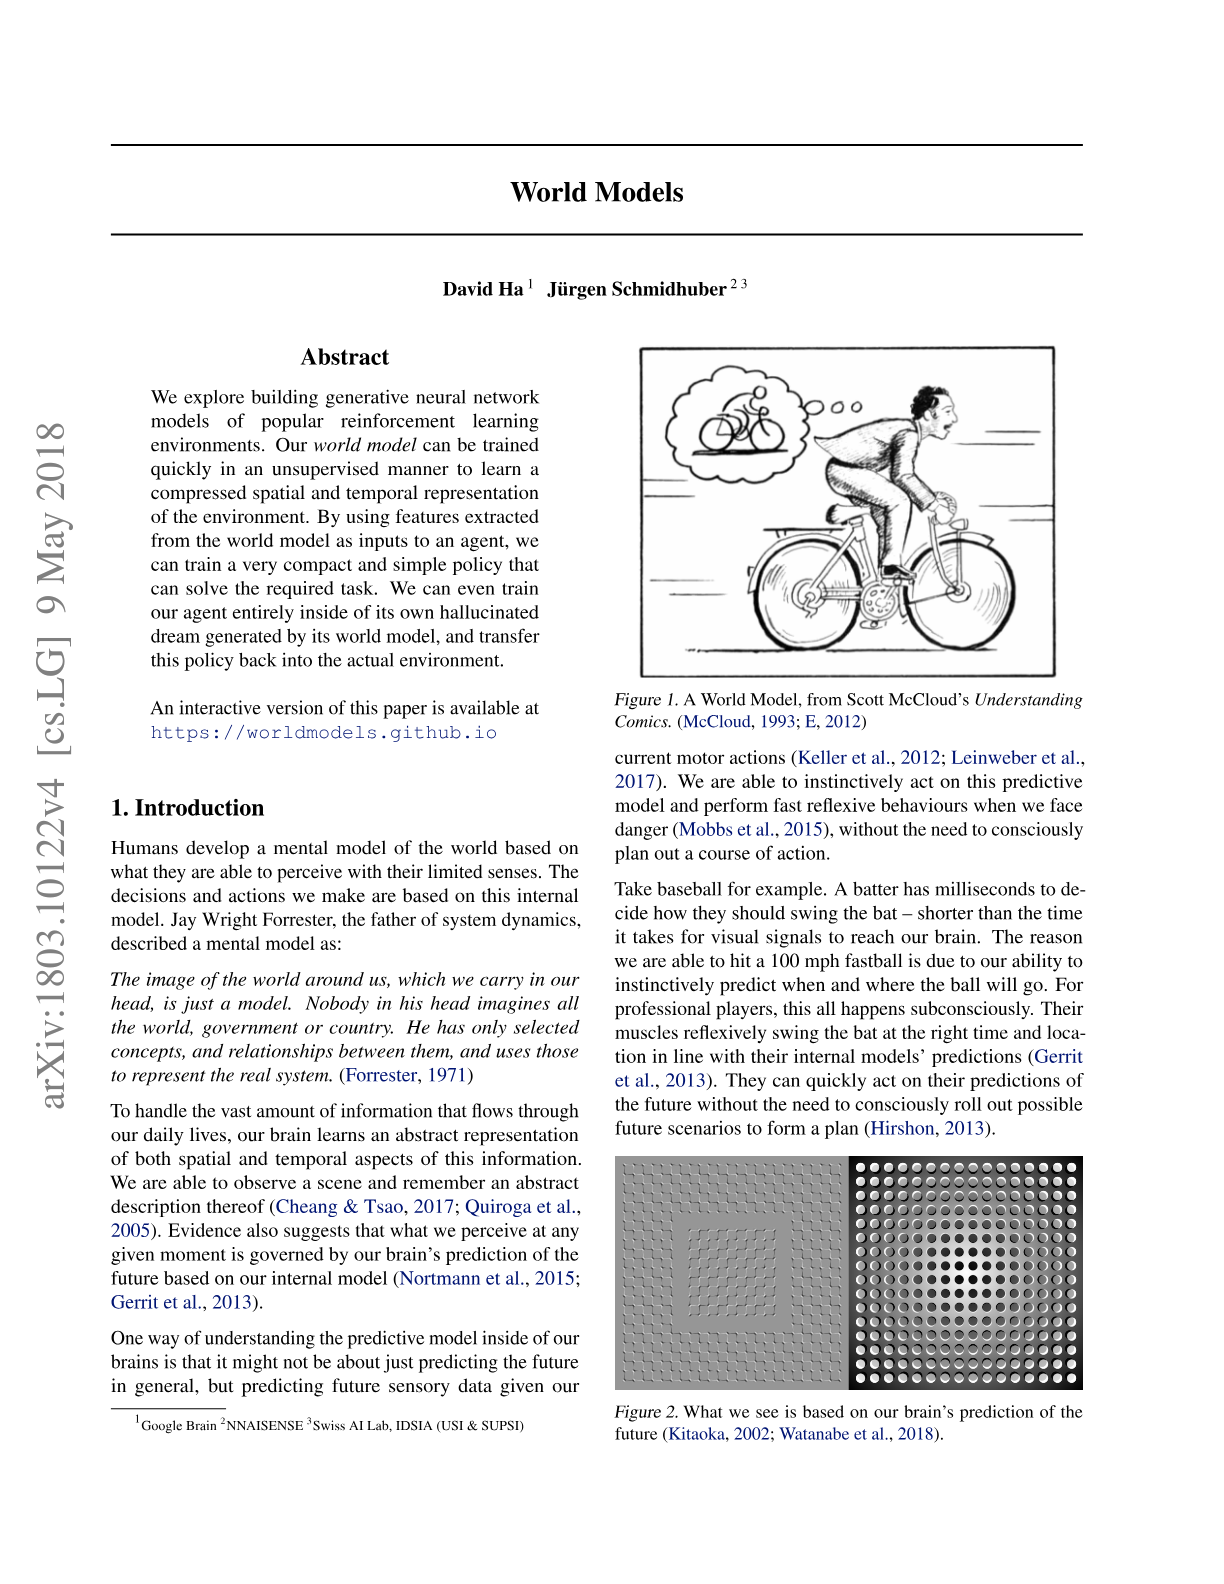
World Models
Hacker News threads
- Jun 2018World Models
- Mar 2018World Models
- Apr 2018A step-by-step guide to the “World Models” AI paper
- Jul 2018Ask HN: 2018 Summer Reading List?
- Nov 2019The revolution of machine learning has been exaggerated
- Jun 2021DeepMind says reinforcement learning is ‘enough’ to reach general AI
- Jul 2021More Protein Folding Progress – What’s It Mean?
- Sep 2025'World Models,' an old idea in AI, mount a comeback
- Feb 2026The Waymo World Model: A New Frontier for Autonomous Driving Simulation
- 233
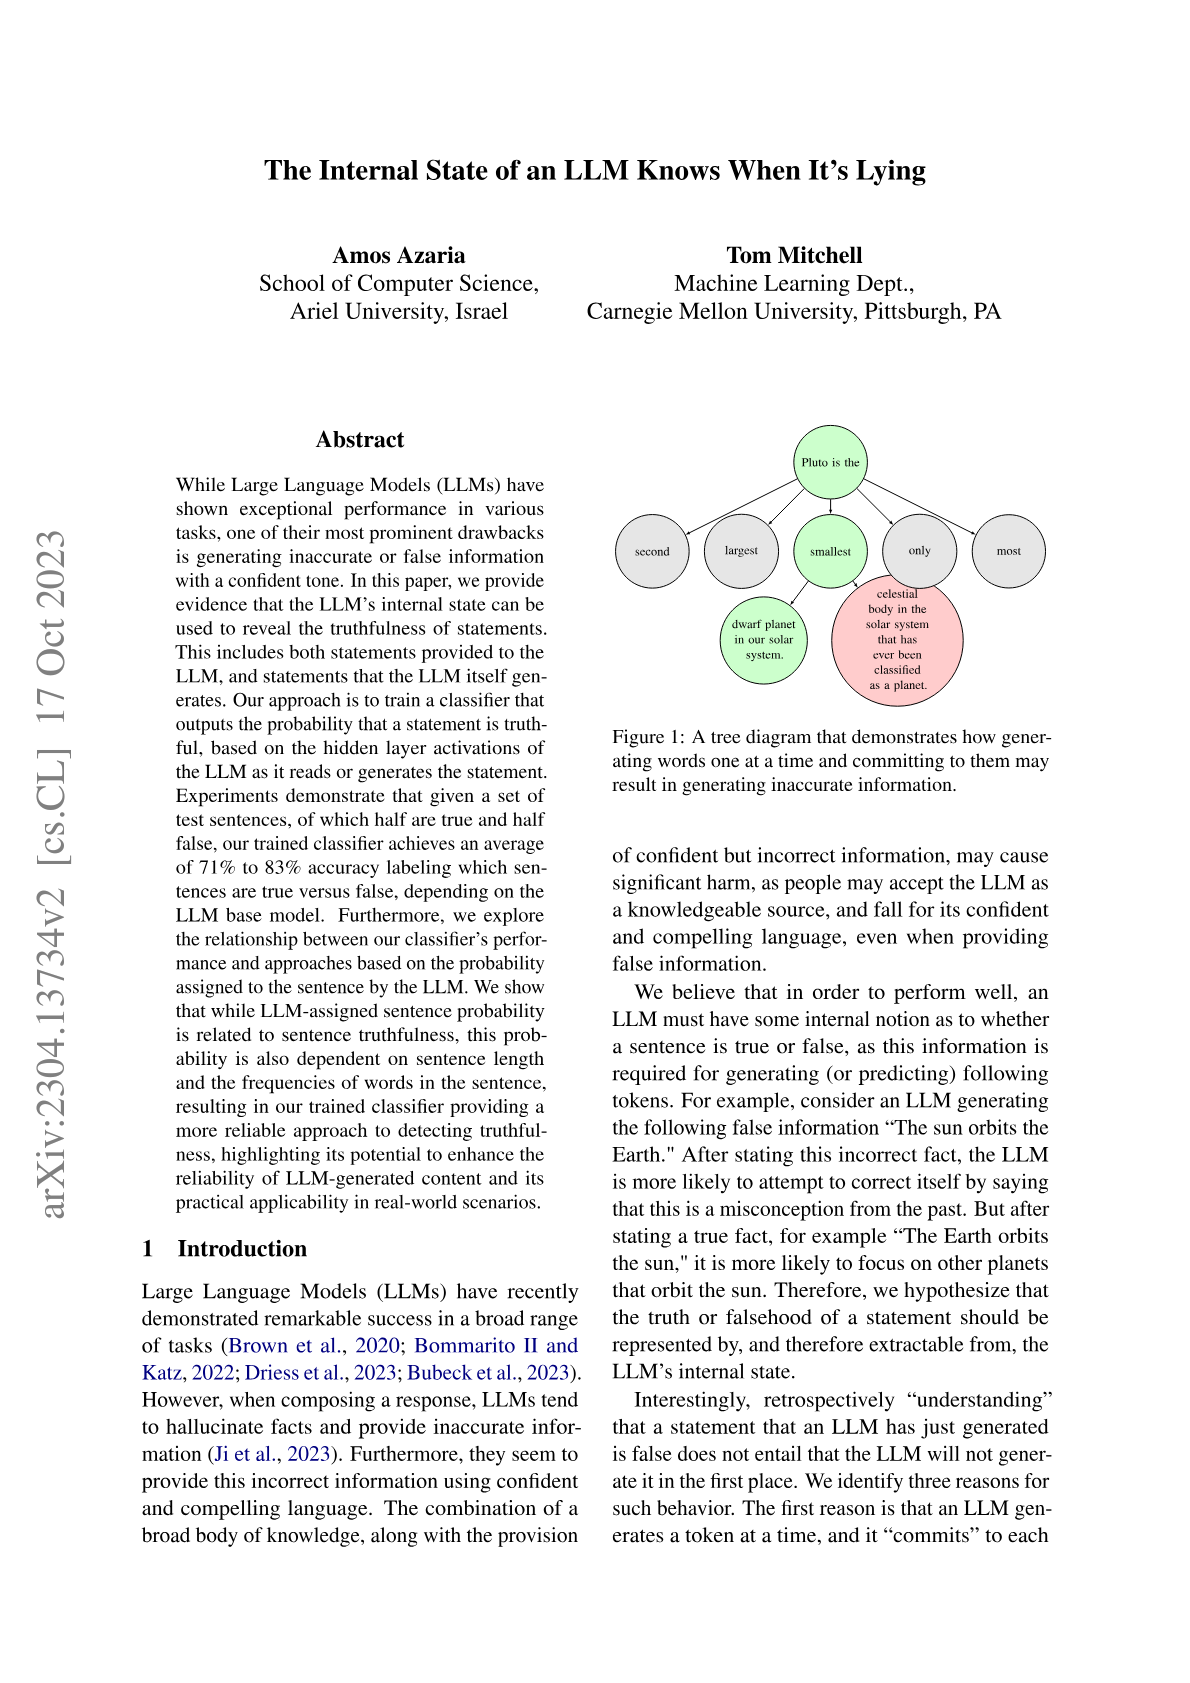
The Internal State of an LLM Knows When It's Lying
Hacker News threads
- Nov 2023The Internal State of an LLM Knows When It's Lying
- Sep 2023The Internal State of a Large Language Model Knows When Its Lying
- May 2023The internal state of an LLM knows when it is lying
- Jun 2023Show HN: StonksGPT – A Natural Language search tool for Stocks and Finance data
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- May 2024Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
- Aug 2024LLMs know more than what they say
- Sep 2024AI is growing faster than companies can secure it, warn industry leaders
- Sep 2024Is telling a model to "not hallucinate" absurd?
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Feb 2026Psychometric Jailbreaks Reveal Internal Conflict in Frontier Models
- 234
Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention
Hacker News threads
- Jul 2020Faster Autoregressive Transformers with Linear Attention
- Jul 2020The Reformer – Pushing the limits of language modeling
- Jan 2023What a transformer can NOT do
- Apr 2023There Is No A.I
- Apr 2023There Is No A.I
- Jun 2024Mamba-2 – State Space Duality
- Jul 2024My Python code is a neural network
- Feb 2025LM2: Large Memory Models
- Feb 2026Attention at Constant Cost per Token via Symmetry-Aware Taylor Approximation
- 235
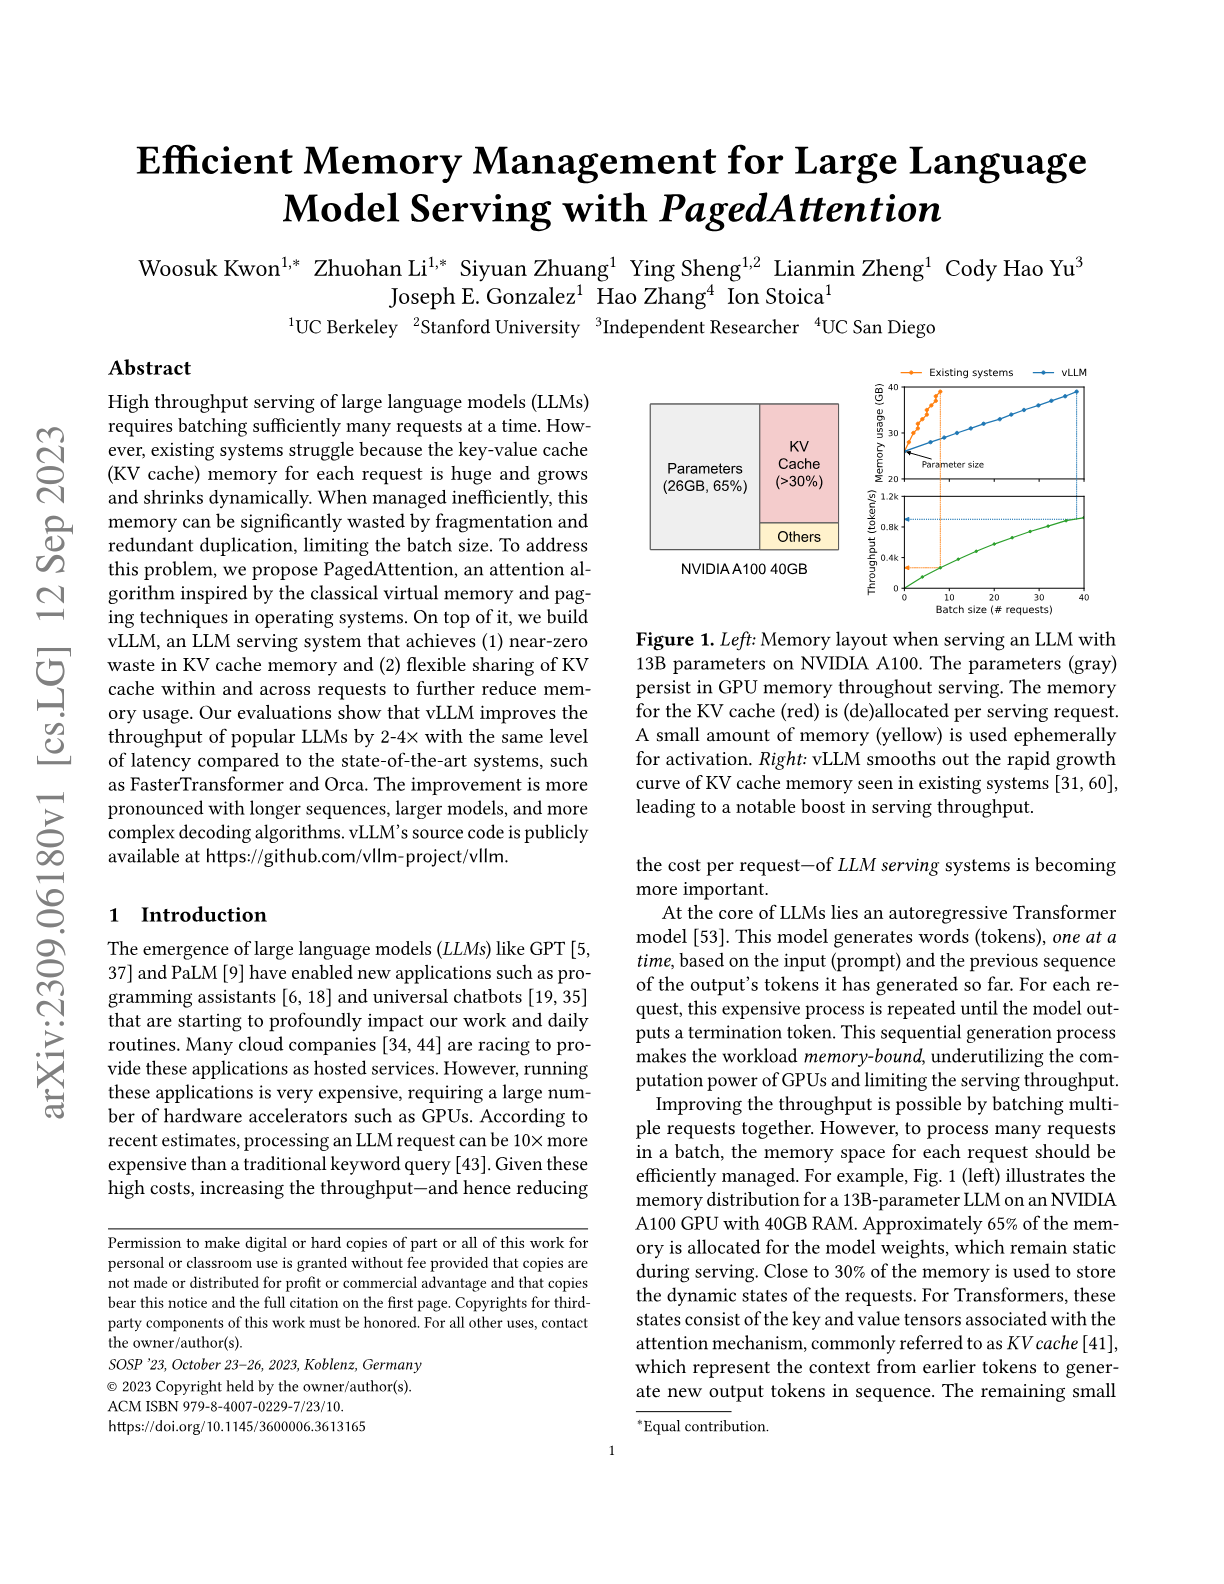
Efficient Memory Management for Large Language Model Serving with PagedAttention
Hacker News threads
- Sep 2023Efficient Memory Management for Large Language Model Serving with PagedAttention
- Apr 2025Efficient Memory Management for Large Language Model Serving with PagedAttention
- Mar 2024LLMs use a surprisingly simple mechanism to retrieve some stored knowledge
- May 2024Gemini Flash
- Jan 2025Qwen2.5-1M: Deploy your own Qwen with context length up to 1M tokens
- Feb 2026Nano-vLLM: How a vLLM-style inference engine works
- 236
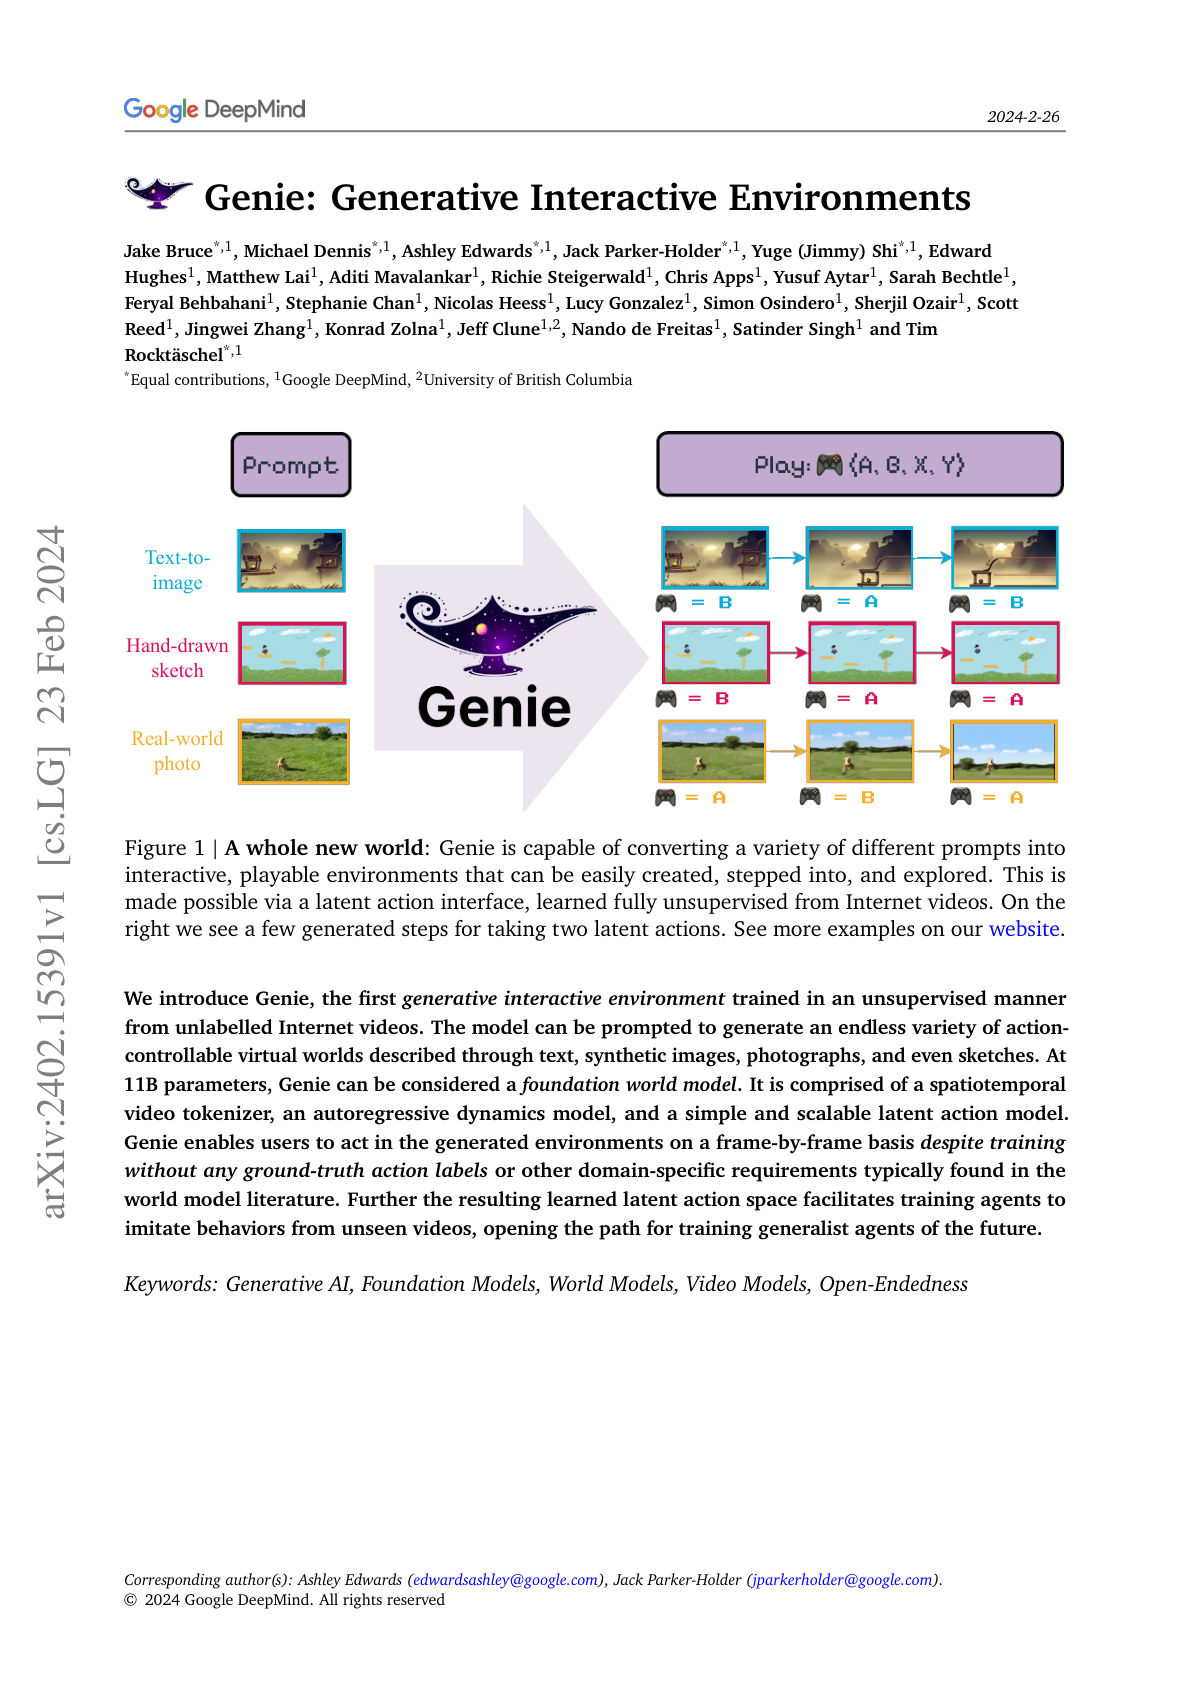
Genie: Generative Interactive Environments
Hacker News threads
- Feb 2024Genie: Generative Interactive Environments
- Feb 2024Genie: Generative Interactive Environments
- Feb 2024Genie: Generative Interactive Environments
- Feb 2024Genie: Generative Interactive Environments (DeepMind)
- Dec 2024Genie 2: A large-scale foundation world model
- Jan 2026Project Genie: Experimenting with infinite, interactive worlds
- 237
Large Language Models are Zero-Shot Reasoners
Hacker News threads
- May 2022Large Language Models are Zero-Shot Reasoners: Let's think step by step
- May 2022Large Language Models Are Zero-Shot Reasoners
- Jun 2022LaMDA is not sentient
- Feb 2023Tech’s hottest new job: AI whisperer. No coding required
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Jul 2023What we learned from using GPT for 500k+ classifications
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Jul 2024Large models of what? Mistaking engineering achievements for linguistic agency
- Mar 2025ChatGPT can't kill anything worth preserving
- Jan 2026LLMs are a 400-year-long confidence trick
- 238
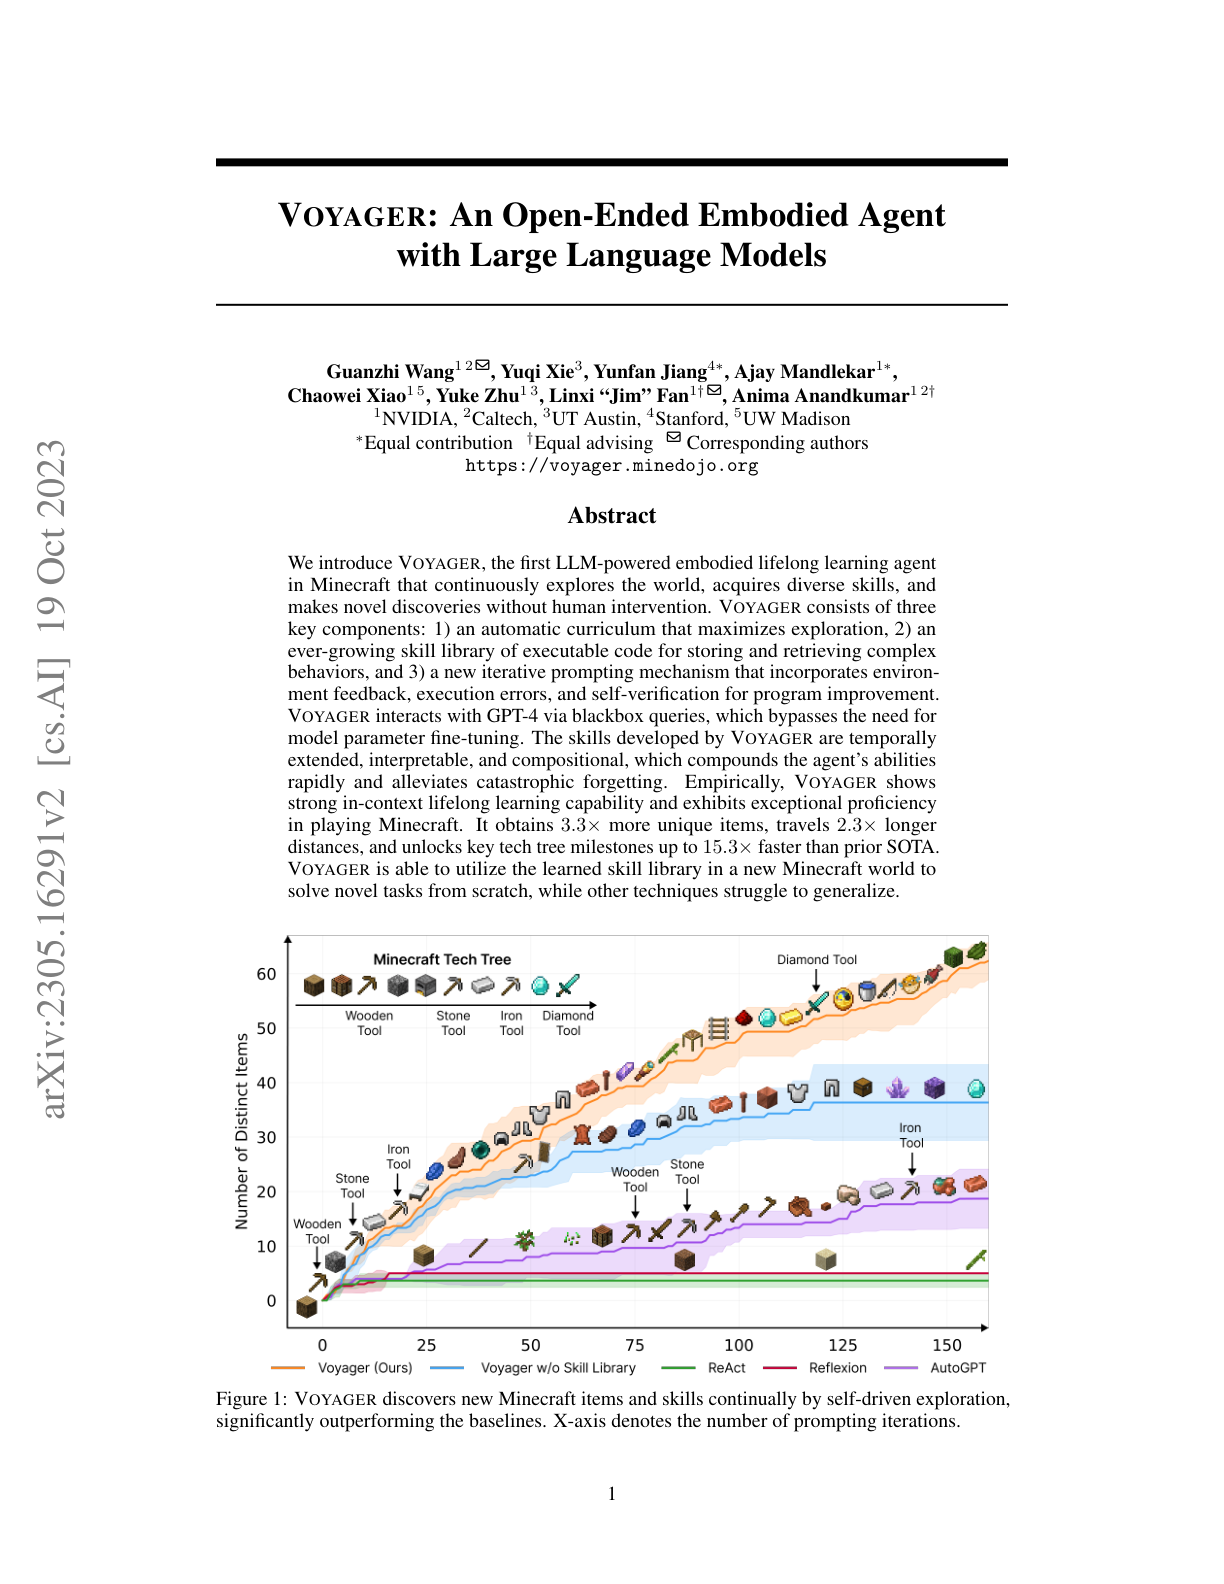
Voyager: An Open-Ended Embodied Agent with Large Language Models
Hacker News threads
- Aug 2023OpenAI Acquires Global Illumination
- Nov 2023The AI industry turns against its favorite philosophy
- Mar 2024Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
- May 2025Show HN: Muscle-Mem, a behavior cache for AI agents
- Sep 2025Amazon has mostly sat out the AI talent war
- Jan 2026The Code-Only Agent
- 239
Efficient Guided Generation for Large Language Models
Hacker News threads
- 240
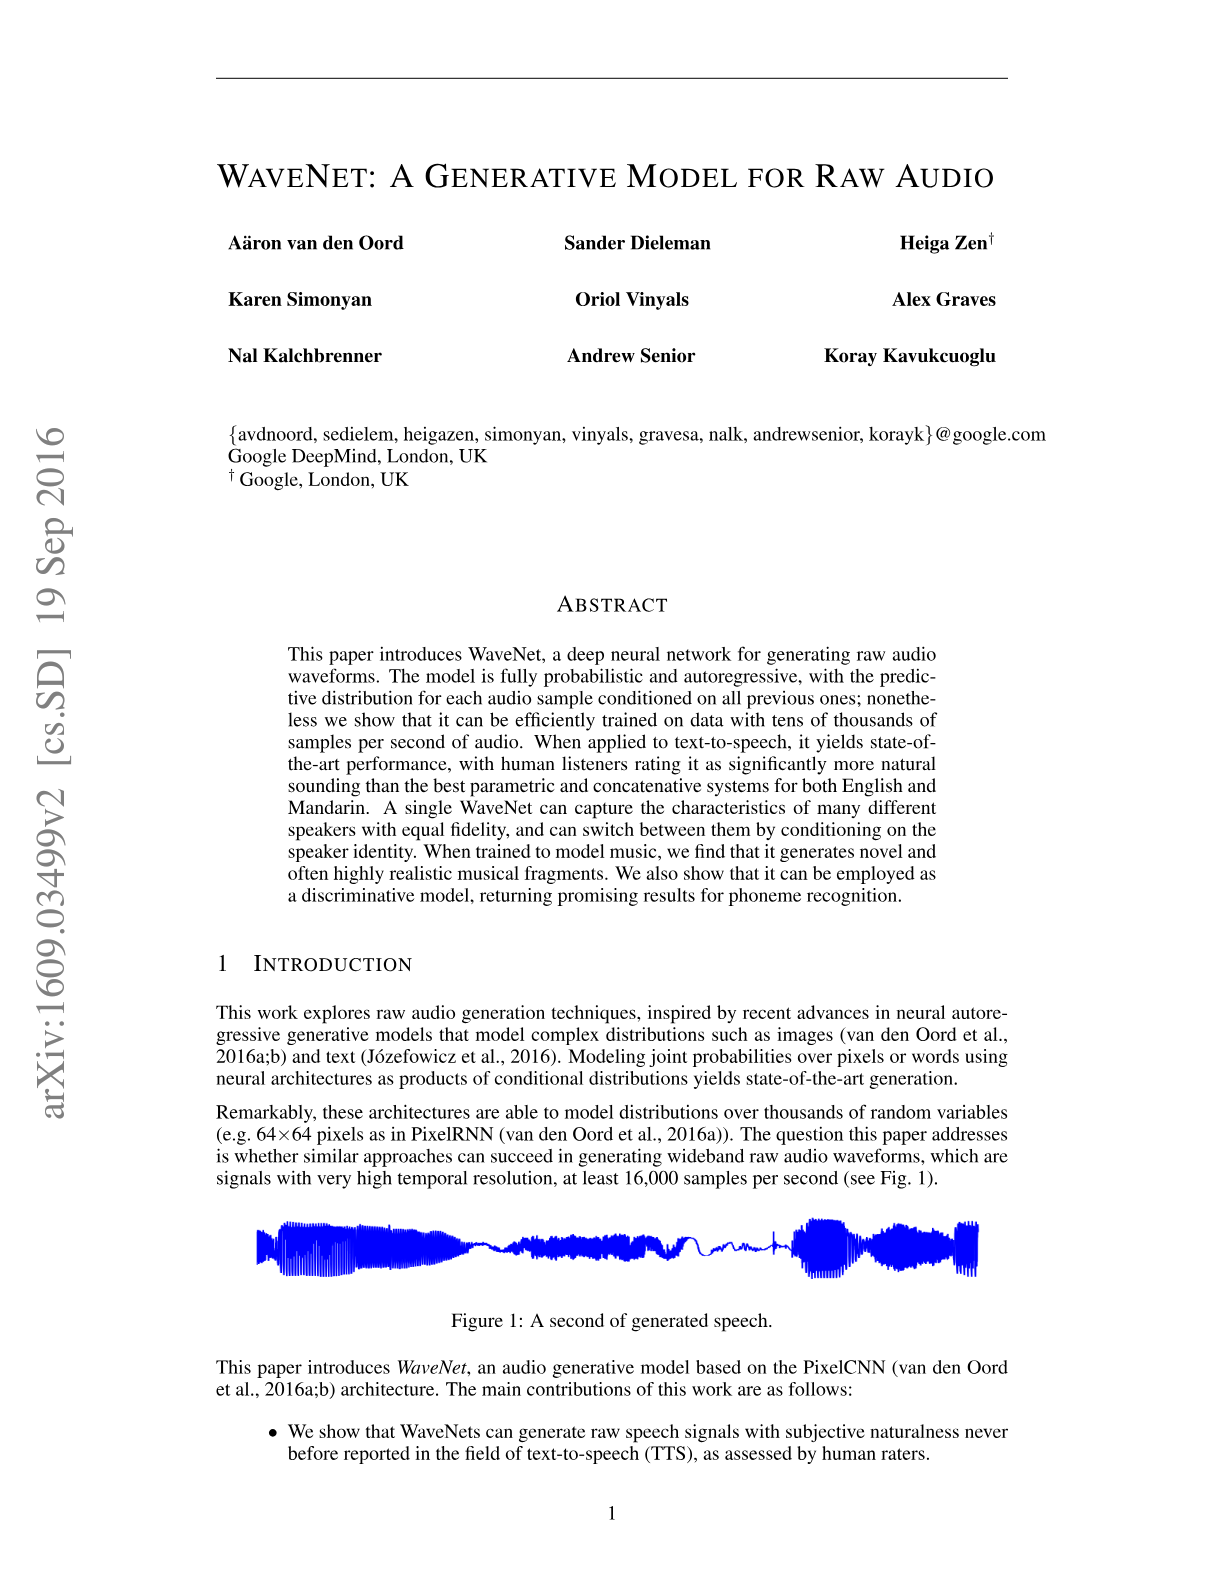
WaveNet: A Generative Model for Raw Audio
Hacker News threads
- Nov 2016Speech-to-Text-WaveNet: End-to-end sentence level English speech recognition
- Mar 2017Baidu Deep Voice Explained: Part 1 – the Inference Pipeline
- Oct 2017Finding Waldo Using Semantic Segmentation and Tiramisu
- May 2018Today’s dominant approach to A.I. has not worked out
- Oct 2018A Tour of the Top Algorithms for Machine Learning Newbies
- Apr 2019Ask HN: What is the state of the art in text to speech?
- Aug 2022Show HN: Nevermind XOR – Deep Learning Has an Issue with Sin
- Jan 2026Pocket TTS: A high quality TTS that gives your CPU a voice
- 241
Delving into LLM-assisted writing in biomedical publications through excess vocabulary
Hacker News threads
- Jun 2024Delving into ChatGPT usage in academic writing through excess vocabulary
- Jun 2024Delving into ChatGPT usage in academic writing through excess vocabulary
- Jul 2024Diving into deep learning: Understanding Deep Learning book review [pdf]
- Aug 2024Ask HN: Why does ChatGPT love the word "eager" so much?
- Jan 2026Ask HN: How can you instantly tell something was written by AI?
- 242
Progress measures for grokking via mechanistic interpretability
Hacker News threads
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Apr 2023We need a much more sophisticated debate about AI
- Apr 2023Grokking in Julia
- May 2023Tiny Transformer trained for addition learns bizarre addition algorithm
- Aug 2023The Myth of AI Omniscience
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Jan 2026Claude is not a senior engineer (yet)
- 243
Poisoning Attacks on LLMs Require a Near-constant Number of Poison Samples
Hacker News threads
- Oct 2025Poisoning Attacks on LLMs Require a Near-Constant Number of Poison Samples
- Oct 2025Beliefs that are true for regular software but false when applied to AI
- Nov 2025PRC elites voice AI-skepticism
- Jan 2026LeCun calls Alex Wang inexperienced, predicts more Meta AI employee departure
- Jan 2026AI industry insiders launch site to poison the data that feeds them
- 244
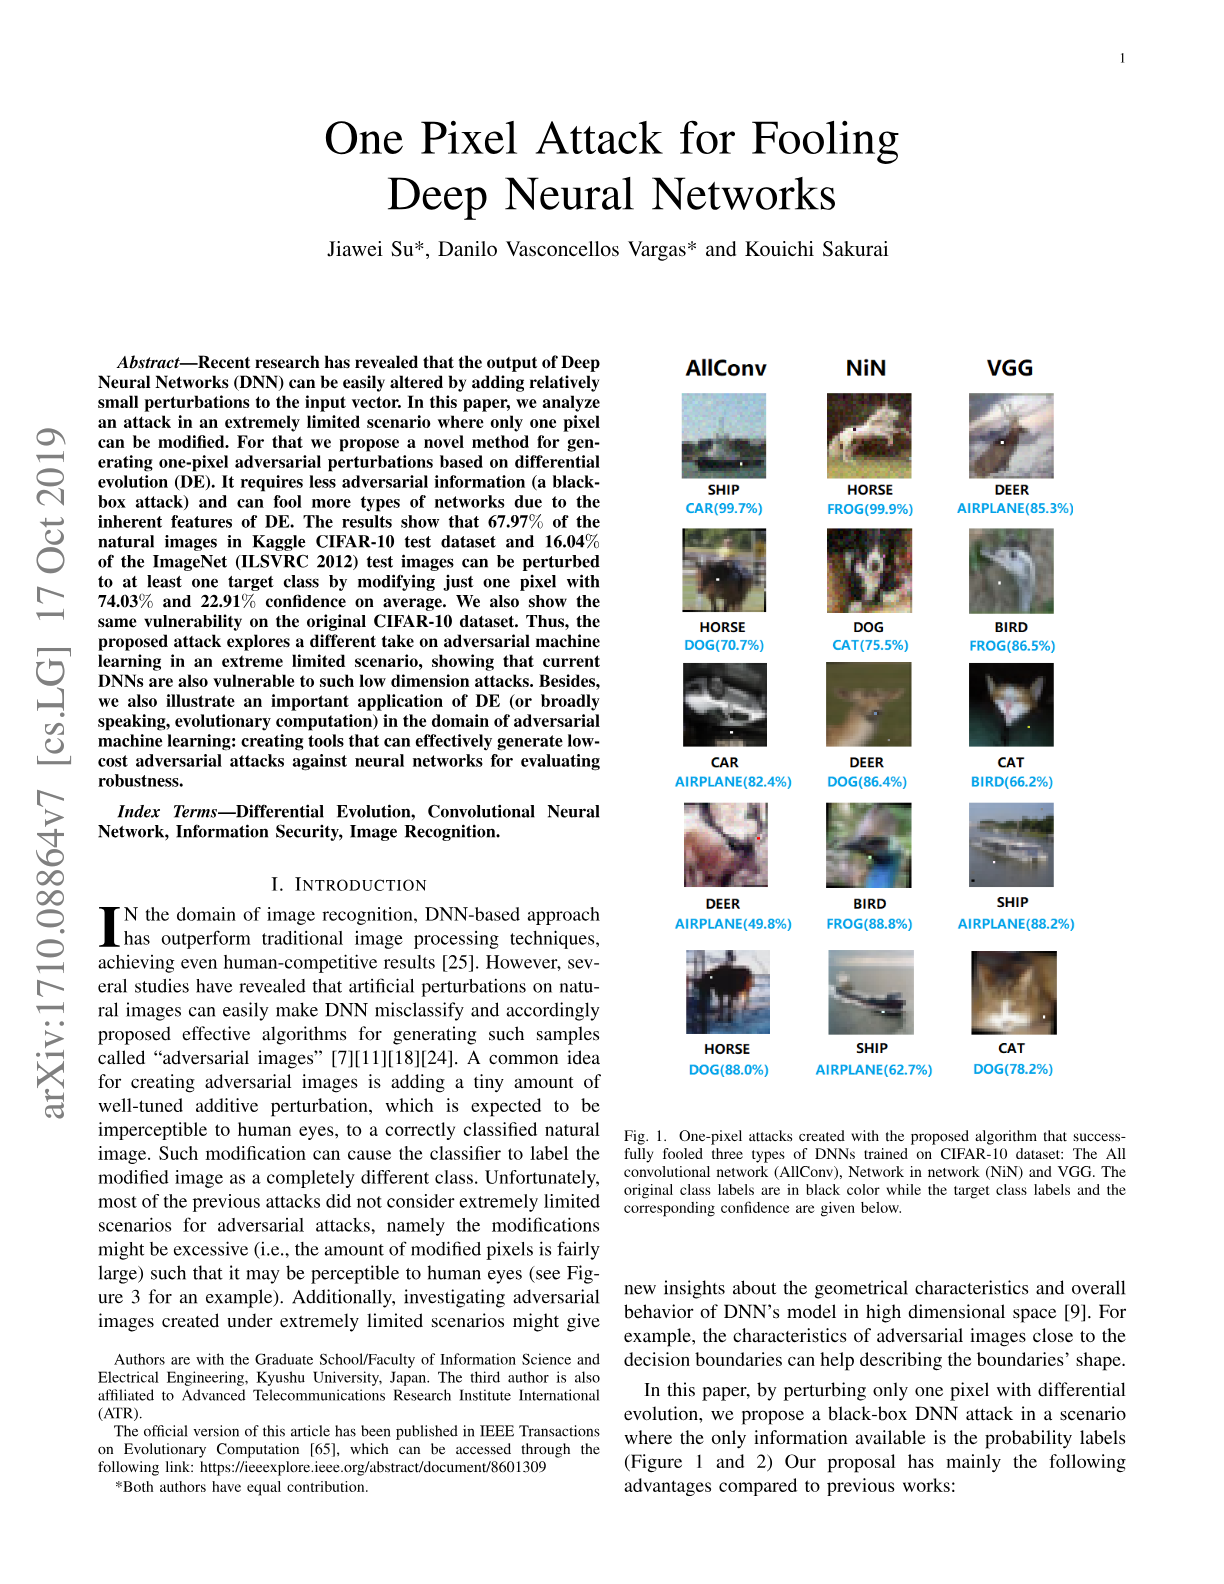
One pixel attack for fooling deep neural networks
Hacker News threads
- Oct 2017One pixel attack for deceiving deep neural networks
- Oct 2017One pixel attack for fooling deep neural networks
- Oct 2017One pixel attack for fooling deep neural networks
- Nov 2017How Adversarial Attacks Work
- Nov 2017New Jersey’s experiment to reduce the number of people in jail awaiting trial
- Nov 2017The impossibility of intelligence explosion
- Oct 2018What Toasters and Distributed Systems Might Have in Common
- Jun 2019Why is Stack Overflow trying to start audio?
- May 2023Prompt injection explained, with video, slides, and a transcript
- 245
Large Concept Models: Language Modeling in a Sentence Representation Space
Hacker News threads
- 246
Neural Machine Translation by Jointly Learning to Align and Translate
Hacker News threads
- Jan 2015Neural Machine Translation by Jointly Learning to Align and Translate
- Apr 2023Neural Machine Translation by Jointly Learning to Align and Translate (2015)
- Mar 2016Dynamic Memory Networks for Visual and Textual Question Answering
- Mar 2018Understanding word vectors
- Nov 2020A Primer in BERTology: What We Know About How Bert Works
- Nov 2023Google is not a tech company
- Dec 2023LLM Visualization
- Dec 2023"Attention", "Transformers", in Neural Network "Large Language Models"
- May 2025When ChatGPT broke the field of NLP: An oral history
- Jan 2026The Q, K, V Matrices
- 247
Hopfield Networks is All You Need
Hacker News threads
- Aug 2025Hopfield Networks Is All You Need (2020)
- Aug 2020Hopfield Networks Is All You Need
- Aug 2020Hopfield Networks Is All You Need
- Aug 2021Introduction to Convolutional Neural Networks
- Feb 2022Ask HN: Is GitHub Copilot / IntelliCode Legal?
- Sep 2022Transformers seem to mimic parts of the brain
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Mar 2024Short-term Hebbian learning can implement transformer-like attention
- Feb 2025LM2: Large Memory Models
- Jan 2026The Q, K, V Matrices
- 248
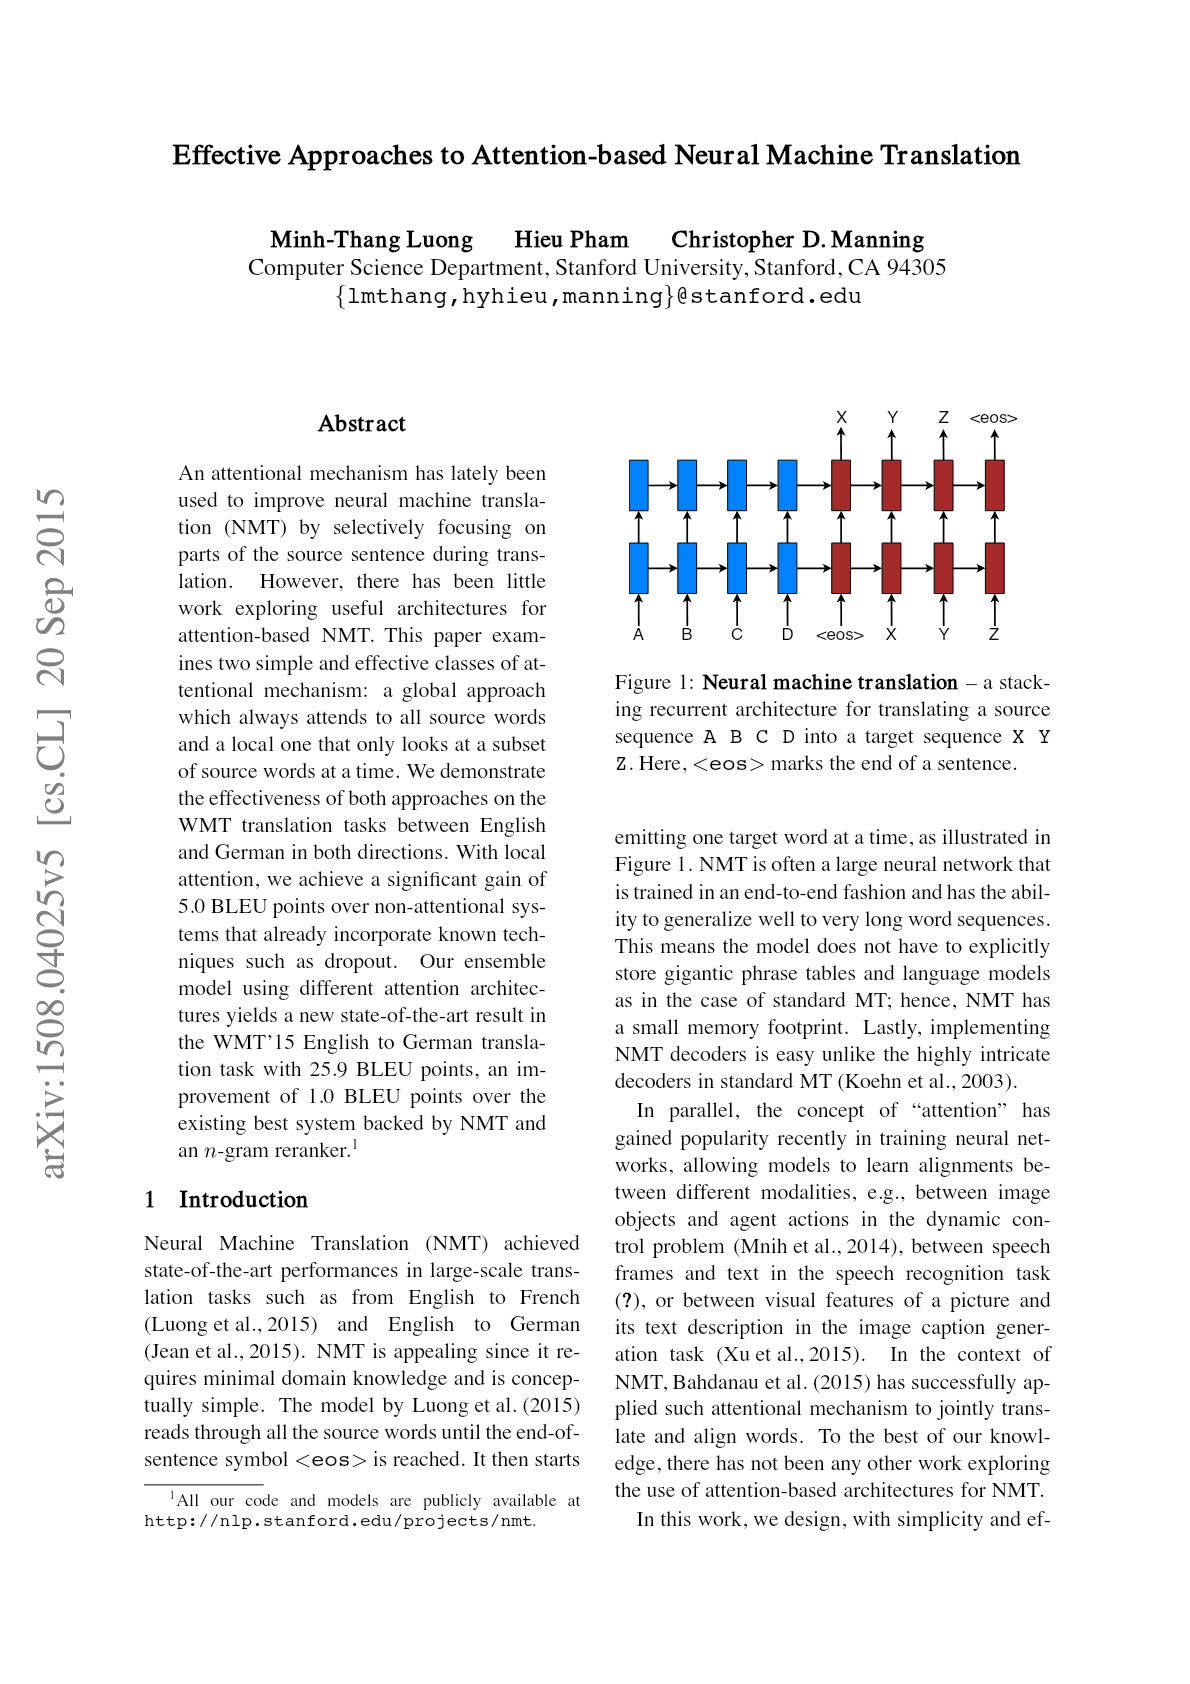
Effective Approaches to Attention-based Neural Machine Translation
Hacker News threads
- 249
Attention is not not Explanation
Hacker News threads
- 250
Winning Gold at IMO 2025 with a Model-Agnostic Verification-and-Refinement Pipeline
Hacker News threads
- Jul 2025Gemini 2.5 Pro Capable of Winning Gold at IMO 2025
- Jul 2025Gemini 2.5 Pro Capable of Winning Gold at IMO 2025 with Prompting
- Jul 2025Gemini 2.5 Pro Capable of Winning Gold at IMO 2025
- Jul 2025Gemini with Deep Think achieves gold-medal standard at the IMO
- Aug 2025GPT-5
- Aug 2025Claim: GPT-5-pro can prove new interesting mathematics
- Sep 2025DeepMind and OpenAI win gold at ICPC
- Oct 2025Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Oct 2025Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Nov 2025Yann LeCun to depart Meta and launch AI startup focused on 'world models'
- Jan 20262025: The Year in LLMs
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.