Hacker Papers
- 276
Accelerating Self-Play Learning in Go
Hacker News threads
- Nov 2019DeepMind's MuZero teaches itself how to win at Atari, chess, shogi, and Go
- Dec 2019An Epidemic of AI Misinformation
- Jun 2020How much did AlphaGo Zero cost? (2018)
- Jun 2020Much More Efficient Self-Play Learning in Go
- Jun 2020Fast implementation of DeepMind's AlphaZero algorithm in Julia
- Nov 2022Adversarial Policies Beat Professional-Level Go AIs
- 277
The Principles of Deep Learning Theory
Hacker News threads
- Apr 2022The Principles of Deep Learning Theory
- Jun 2021The Principles of Deep Learning Theory
- Jul 2021The Principles of Deep Learning Theory
- Oct 2021A new link to an old model could crack the mystery of deep learning
- Apr 2022The Mathematics of Artificial Intelligence (2022)
- Jan 2023Ask HN: What are the foundational texts for learning about AI/ML/NN?
- Jan 2023Critical brain hypothesis: A physical theory for when the brain performs best
- Nov 2023Understanding Deep Learning
- 278
Vectorized and performance-portable Quicksort
Hacker News threads
- Feb 2024Vectorized and performance-portable Quicksort (2022)
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Apple M2 Die Shot and Architecture Analysis – Big Cost Increase and A15 Based IP
- Dec 2022Sorting with SIMD
- Jan 2023Efficient and performance-portable vector software
- Mar 2024JPEG XL and the Pareto Front
- 279
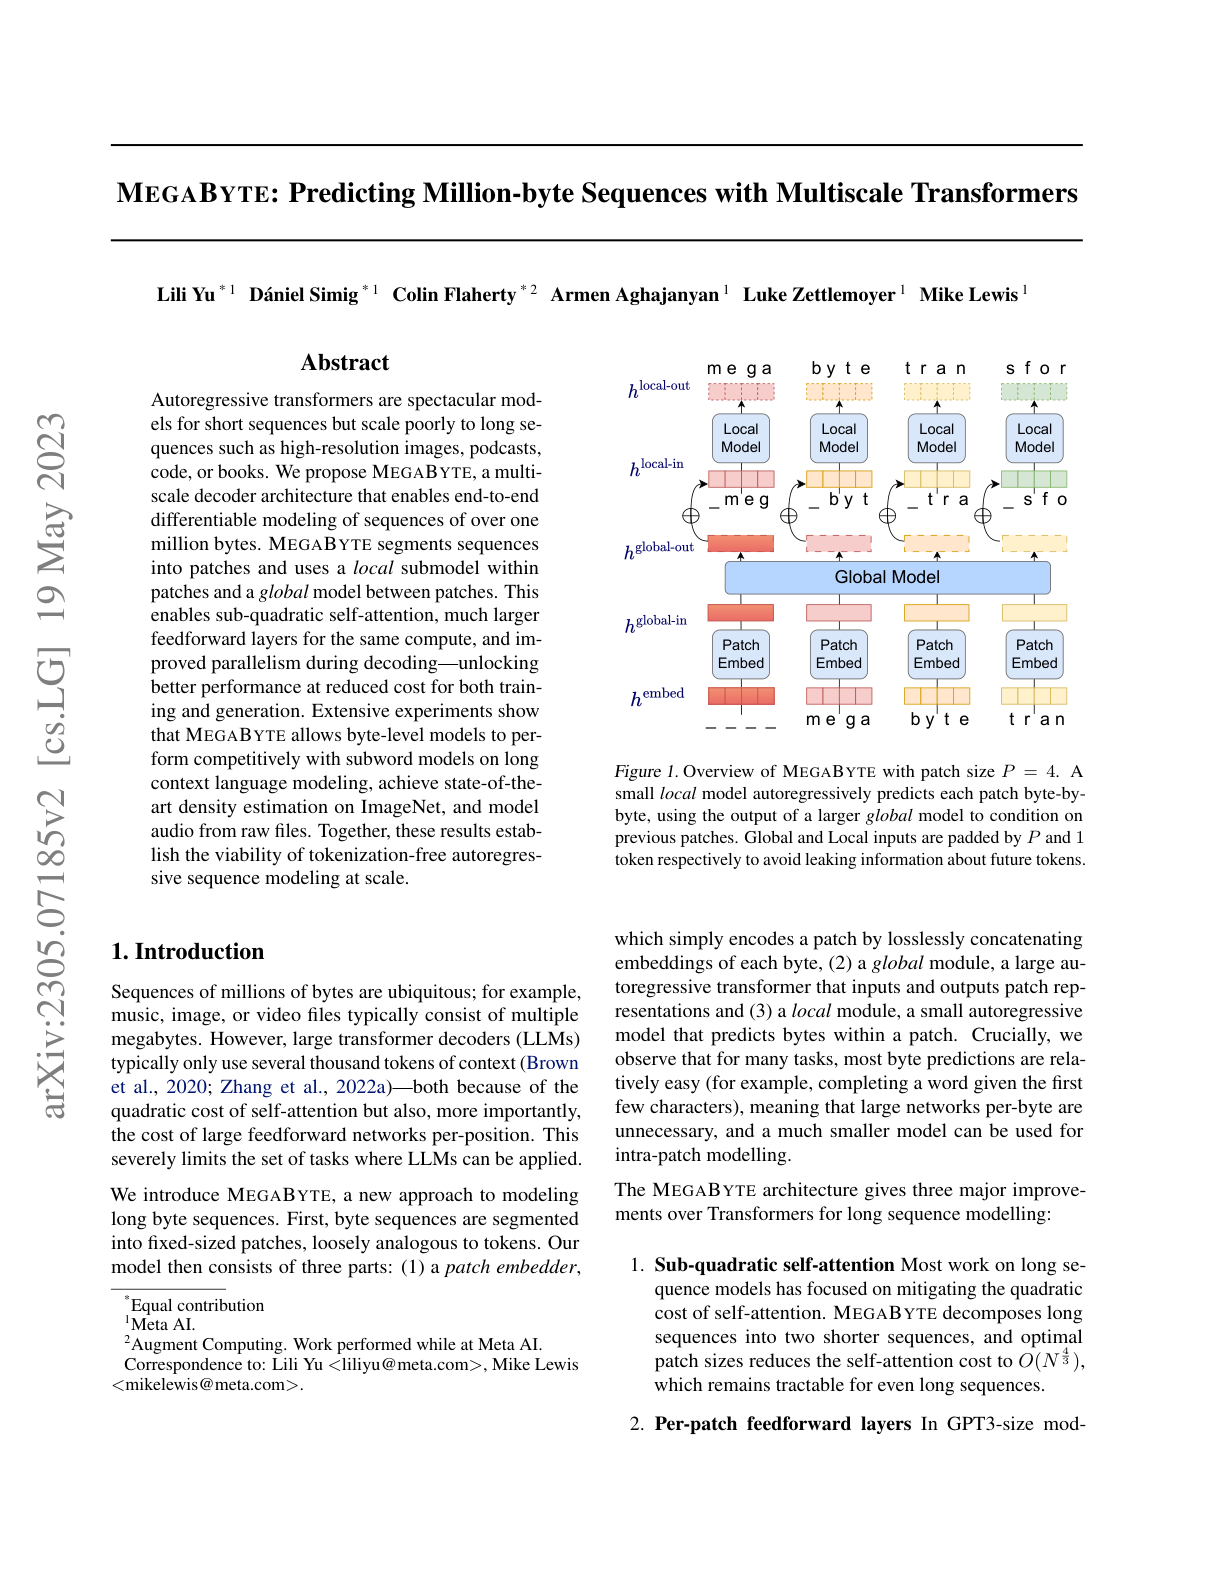
MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
Hacker News threads
- Jun 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- Jun 2023Bytes Are All You Need: Transformers Operating Directly on File Bytes
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Oct 2025Neural audio codecs: how to get audio into LLMs
- 280
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 281
GLU Variants Improve Transformer
Hacker News threads
- Aug 2023Llama from Scratch (or how to implement a paper without crying)
- Nov 2023Simplifying Transformer Blocks
- Sep 2024SwiGLU activation function causes instability in FP8 LLM training
- Jun 2026Don't trust large context windows
- Jun 2026Anthropic to Require ID Verification for Certain Capabilities Starting July 8
- 282
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 283
A ConvNet for the 2020s
Hacker News threads
- May 2024A ConvNet for the 2020s
- Jan 2022A ConvNet for the 2020s
- Jan 2022A ConvNet for the 2020s
- Apr 2022Transformers Are All You Need
- Apr 2022Transformers Are All You Need
- Apr 2023Swin Transformer: Hierarchical Vision Transformer Using Shifted Windows
- Jan 2024Citation cartels help mathematicians-and their universities-climb the rankings
- Aug 2024What's Going on in Machine Learning? Some Minimal Models
- 284
Acquisition of Chess Knowledge in AlphaZero
Hacker News threads
- Nov 2021Acquisition of Chess Knowledge in AlphaZero
- Nov 2021Acquisition of Chess Knowledge in AlphaZero
- Nov 2021Acquisition of Chess Knowledge in AlphaZero [pdf]
- Nov 2021Acquisition of chess knowledge in AlphaZero
- Nov 2021Acquisition of chess knowledge in AlphaZero
- Dec 2021Can deep learning help mathematicians build intuition?
- Nov 2022Acquisition of chess knowledge in AlphaZero
- Feb 2026Experts Have World Models. LLMs Have Word Models
- 285
Inferring Algorithmic Patterns with Stack-Augmented Recurrent Nets
Hacker News threads
- 286
LLMs Will Always Hallucinate, and We Need to Live With This
Hacker News threads
- Sep 2024LLMs Will Always Hallucinate, and We Need to Live with This
- Sep 2024LLMs Will Always Hallucinate, and We Need to Live with This
- Sep 2024I no longer use AI assistant
- Oct 2024Announcing the Tech for Palestine Incubator
- Oct 2024Show HN: Last CLI tool you will need
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Jun 2025O3 Turns Pro
- Sep 2026How OpenAI Used Its Own LLMs to Design Its Jalapeño Chip
- 287
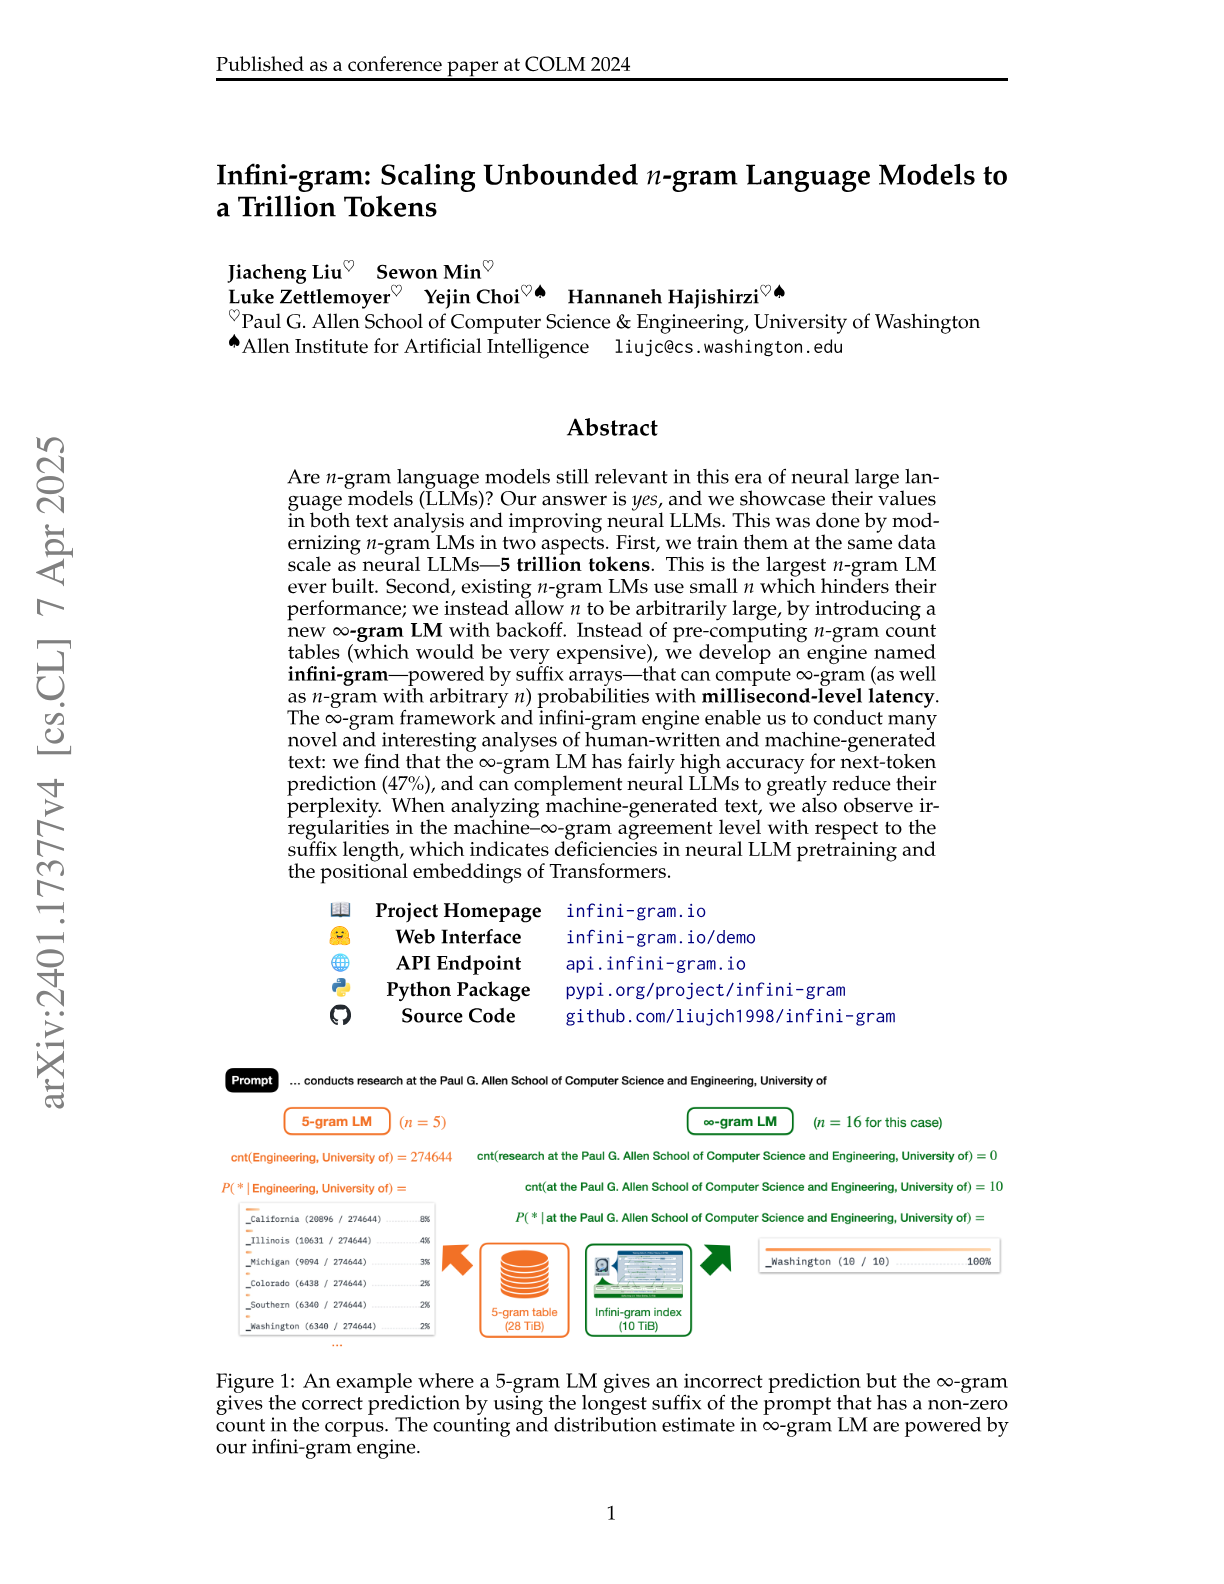
Infini-gram: Scaling Unbounded n-gram Language Models to a Trillion Tokens
Hacker News threads
- May 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Infini-Gram: Scaling Unbounded N-Gram Language Models to a Trillion Tokens
- Feb 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Markov Chains are the Original Language Models
- Jun 2024Transformers Represent Belief State Geometry in Their Residual Stream
- Nov 2025A new Google model is nearly perfect on automated handwriting recognition
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Apr 2026Soul Player C64 – A real transformer running on a 1 MHz Commodore 64
- 288
Tortured phrases: A dubious writing style emerging in science. Evidence of critical issues affecting established journals
Hacker News threads
- Aug 2021A dubious writing style emerging in science
- Aug 2021Tortured phrases: A dubious writing style emerging in science
- Jun 2023Junk websites filled w AI-generated text pulling in money from programmatic ads
- Dec 2023Tortured conference series thriving in Computer Science
- Aug 2026Research papers using "kidney disappointment" instead of "kidney failure"
- Aug 2026Research papers using "kidney disappointment" instead of "kidney failure"
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 289
Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context
Hacker News threads
- May 2024Gemini 1.5: Multimodal understanding across tokens of context
- Mar 2024Google's Gemini 1.5 Pro whitepaper
- Mar 2024Gemini 1.5: Unlocking multimodal understanding across tokens of context
- Apr 2024Hello OLMo: A truly open LLM
- Apr 2024Can Gemini 1.5 read all the Harry Potter books at once?
- May 2024Ask HN: Disillusioned after AI?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Mar 2026Yann LeCun's AI startup raises $1B in Europe's largest ever seed round
- 290
Privacy Loss in Apple's Implementation of Differential Privacy on MacOS 10.12
Hacker News threads
- Sep 2017Privacy Loss in Apple's Implementation of Differential Privacy on MacOS 10.12
- Apr 2019Privacy Loss in Apple’s Implementation of Differential Privacy (2017)
- Sep 2017Privacy
- Nov 2017Forget iPhone X–Apple's Best Product Is Its Privacy Stance
- Mar 2018The Algorithmic Foundations of Differential Privacy (2014) [pdf]
- Apr 2025Understanding Aggregate Trends for Apple Intelligence Using Differential Privacy
- 291
Do Deep Nets Really Need to be Deep?
Hacker News threads
- Oct 2014Do Deep Nets Really Need to be Deep? [pdf]
- Jan 2014Shallow neural networks as good as Deep Neural Networks
- Jan 2014Do Deep Nets Really Need to be Deep?
- Aug 2014IBM Chip Processes Data Similar to the Way Your Brain Does
- Sep 2014A Revolutionary Technique That Changed Machine Vision
- Jan 2015A Brief Overview of Deep Learning
- Jun 2016The truth about deep learning
- 292
DeepMath - Deep Sequence Models for Premise Selection
Hacker News threads
- Jul 2016DeepMath – Deep Sequence Models for Premise Selection
- Jul 2016Behind Wolfram Alpha’s Mathematical Induction-Based Proof Generator
- Nov 2016Tensorflow Deepmath: Experiments towards neural network theorem proving
- Feb 2017Summary of 'Programs with Common Sense' (1959) by John McCarthy
- Oct 2020Neurosymbolic AI – Combining neural nets and symbolic AI
- 293
Highway Networks
Hacker News threads
- 294
Towards Understanding Sycophancy in Language Models
Hacker News threads
- Jun 2025Towards Understanding Sycophancy in Language Models
- Oct 2023Towards Understanding Sycophancy in Language Models
- Oct 2023Towards Understanding Sycophancy in Language Models
- Dec 2023GM Dealer Chat Bot Agrees to Sell 2024 Chevy Tahoe for $1
- Mar 2024Google Scholar search: "certainly, here is" -chatgpt -llm
- May 2026No Slop Grenade
- Jun 2026The US lifts its block on Mythos 5
- 295
Going Deeper with Convolutions
Hacker News threads
- 296
RAISR: Rapid and Accurate Image Super Resolution
Hacker News threads
- 297
Zero-Shot Text-to-Image Generation
Hacker News threads
- 298
Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection
Hacker News threads
- Feb 2023Getting more than what you've asked for: The Next Stage of Prompt Engineering
- Feb 2023Novel Prompt Injection Threats to Application-Integrated Large Language Models
- Feb 2023Comprehensive Analysis of Prompt Injection Threats to Large Language Models
- Mar 2023Show HN: ChatGPT Plugins are a security nightmare
- Dec 2023Purple Llama by Meta AI
- Mar 2024Prompt injection and jailbreaking are not the same thing
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- 299
CycleGAN, a Master of Steganography
Hacker News threads
- Jan 2019CycleGAN, a Master of Steganography [2017]
- Jan 2019CycleGAN, a Master of Steganography
- Sep 2024Minifying HTML for GPT-4o: Remove all the HTML tags
- Aug 2025How attention sinks keep language models stable
- Mar 2026No right to relicense this project
- Oct 2026Write Like It's 1866: LLMs Relearn Telegraphese
- 300
Resurrecting Recurrent Neural Networks for Long Sequences
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.