Hacker Papers
- 276
On Large-Batch Training for Deep Learning: Generalization Gap and Sharp Minima
Hacker News threads
- Nov 2016MXNet – Deep Learning Framework of Choice at AWS
- Mar 2017Why is so much memory needed for deep neural networks?
- Jun 2017Facebook Trains ImageNet in 1 Hour
- Dec 2017An Interview with an Anonymous Data Scientist (2016)
- Dec 2017Mathematics of Deep Learning [pdf]
- Nov 2025Backpropagation is a leaky abstraction (2016)
- 277
Document Embedding with Paragraph Vectors
Hacker News threads
- 278
Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
Hacker News threads
- Apr 2025Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
- May 2025Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
- May 2025Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
- May 2025Professors Staffed a Fake Company with AI Agents, Guess What Happened?
- May 2025Trading with Claude, and writing your own MCP server
- Jun 2025Project Vend: Can Claude run a small shop? (And why does that matter?)
- Jun 2025Project Vend: Can Claude run a small shop? (And why does that matter?)
- Jul 2025Can Large Language Models Play Text Games Well? (2023)
- Jul 2025Ask HN: Why haven't we seen AI as opponents in video games?
- Oct 2025Our LLM-controlled office robot can't pass butter
- 279
Simple and Controllable Music Generation
Hacker News threads
- 280
You Only Look Once: Unified, Real-Time Object Detection
Hacker News threads
- Dec 2015You Only Look Once: Unified, Real-Time Object Detection
- Jul 2020You Only Look Once: Unified, Real-Time Object Detection
- Mar 2016Darknet: C and CUDA open source neural network framework
- Jun 2017Supercharge your Computer Vision models with the TensorFlow Object Detection API
- Oct 2017Show HN: Vehicle Detection – using machine learning and computer vision
- Apr 2019YOLO: Real-Time Object Detection
- Oct 2025Armed police swarm student after AI mistakes bag of Doritos for a weapon
- 281
MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
Hacker News threads
- Jun 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- Jun 2023Bytes Are All You Need: Transformers Operating Directly on File Bytes
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Oct 2025Neural audio codecs: how to get audio into LLMs
- 282
Pixel Recurrent Neural Networks
Hacker News threads
- Jun 2016Blade Runner re-encoded using neural networks
- Feb 2020JPEG Committee releases a call for evidence for image compression based on AI
- Jun 2020Image GPT
- Jul 2020The Reformer – Pushing the limits of language modeling
- Oct 2024Faster convergence for diffusion models
- Oct 2025Neural audio codecs: how to get audio into LLMs
- 283
Faith and Fate: Limits of Transformers on Compositionality
Hacker News threads
- Apr 2025Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Will scaling work?
- Jan 2024Chess-GPT's Internal World Model
- Jan 2024New theory suggests LLMs can understand text
- Mar 2024Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
- Feb 2025Recent results show that LLMs struggle with compositional tasks
- Oct 2025OpenAI researcher announced GPT-5 math breakthrough that never happened
- 284
Adam: A Method for Stochastic Optimization
Hacker News threads
- Oct 2015Adam's method for stochastic optimization
- Jan 2017A New Batch of Deep Learning Startups to Watch for in 2017
- Oct 2017Variational Inference and Deep Learning: A New Synthesis [pdf]
- Feb 2023Exclusive Q&A John Carmack’s ‘Different Path’ to Artificial General Intelligence
- Jul 2023A Theory on Adam Instability in Large-Scale Machine Learning
- May 2024xLSTM: Extended Long Short-Term Memory
- Oct 2024Anthropic hires OpenAI co-founder Durk Kingma
- Mar 2025The PhD Metagame: Don't try to reform science – not yet
- Oct 2025Researchers Discover the Optimal Way to Optimize
- 285
Towards AI-Complete Question Answering: A Set of Prerequisite Toy Tasks
Hacker News threads
- Feb 2015Towards AI-Complete Question Answering, Using Deep Learning
- Feb 2015Towards AI-Complete Question Answering: A Set of Prerequisite Toy Tasks [pdf]
- Mar 2015Facebook's Memory Networks Demo
- Mar 2015By 2029 no computer or “machine intelligence” will have passed the Turing Test
- Jun 2015Hound voice search NLP demo [video]
- Aug 2015Towards Neural Network-based Reasoning
- Sep 2015Inferring Algorithmic Patterns with Stack
- Jun 2016DeepText: Facebook's text understanding engine
- Oct 2025A History of Large Language Models
- 286
Memory Networks
Hacker News threads
- Nov 2014Memory Networks
- Feb 2015Facebook Memory Networks
- Mar 2015Memory Network [pdf]
- Mar 2015Facebook's Memory Networks Demo
- Mar 2015By 2029 no computer or “machine intelligence” will have passed the Turing Test
- May 2015Are There Deep Reasons Underlying the Pathologies of Deep Learning Algorithms? [pdf]
- Jul 2015FANN.js – Fast Artificial Neural Network Compiled with Emscripten
- Oct 2016Hybrid computing using a neural network with dynamic external memory
- Oct 2025A History of Large Language Models
- 287
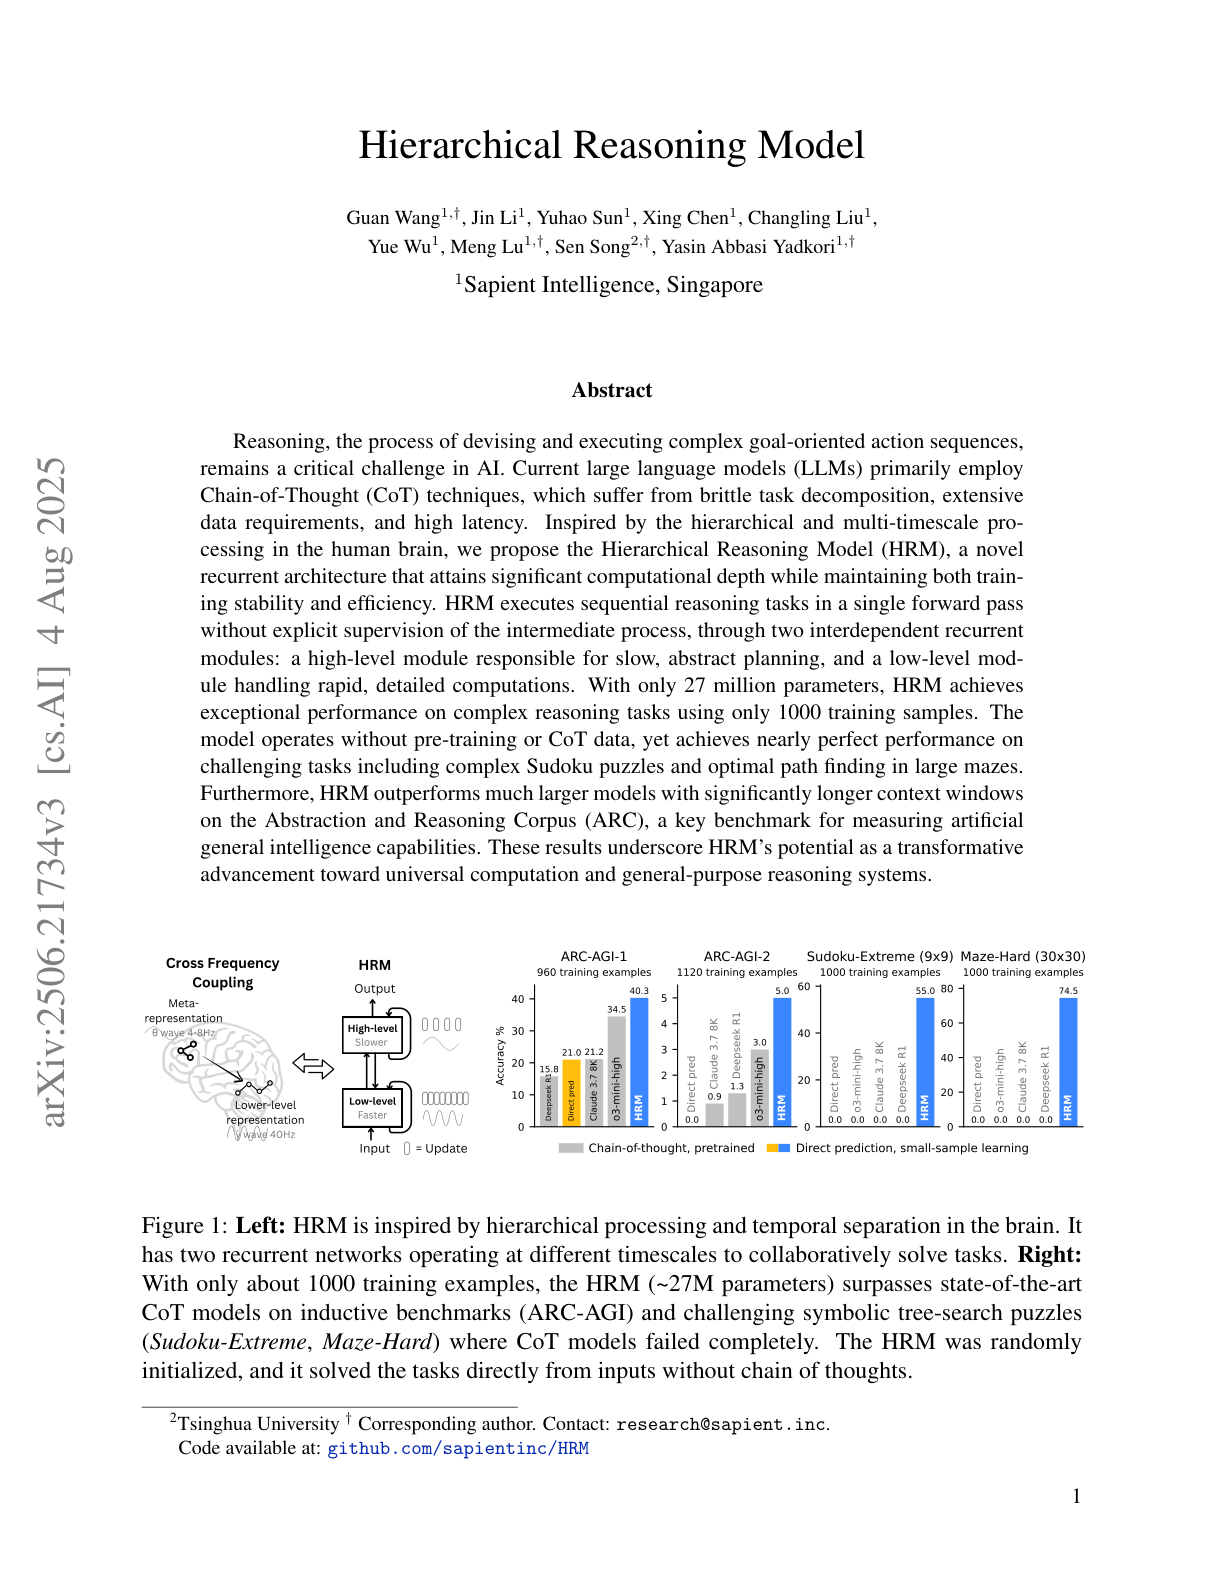
Hierarchical Reasoning Model
Hacker News threads
- Jul 2025Hierarchical Reasoning Model
- Jul 2025Hierarchical Reasoning Model
- Jul 2025Hierarchical Reasoning Model
- Jul 2025A 27M-param model that solves hard Sudoku/mazes where LLMs fail, without CoT
- Jul 2025New AI architecture delivers 100x faster reasoning with just 1,000 examples
- Jul 2025Hierarchical Reasoning Model – 1k training samples SoTA reasoning v/s CoT
- Aug 2025Is chain-of-thought AI reasoning a mirage?
- Aug 2025From multi-head to latent attention: The evolution of attention mechanisms
- Oct 2025Less is more: Recursive reasoning with tiny networks
- 288
Think before you speak: Training Language Models With Pause Tokens
Hacker News threads
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Oct 2023Want to get started with LLMs? Here's what you need to know
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Mar 2024Yi: Open Foundation Models by 01.AI
- Apr 2024Self-reasoning tokens: teaching models to think ahead
- Jul 2024The A.I. Bubble is Bursting with Ed Zitron [video]
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Claude 4
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 289
SequenceMatch: Imitation Learning for Autoregressive Sequence Modelling with Backtracking
Hacker News threads
- Jun 2023Giving LLM’s a <Backspace> Token
- Jun 2023LLM Powered Autonomous Agents
- Jun 2024AI Detectors Get It Wrong. Writers Are Being Fired Anyway
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Mercury: Commercial-scale diffusion language model
- Aug 2025Hacking Diffusion into Qwen3 for the Arc Challenge
- Sep 2025The wall confronting large language models
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 290
Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection
Hacker News threads
- Feb 2023Getting more than what you've asked for: The Next Stage of Prompt Engineering
- Feb 2023Novel Prompt Injection Threats to Application-Integrated Large Language Models
- Feb 2023Comprehensive Analysis of Prompt Injection Threats to Large Language Models
- Mar 2023Show HN: ChatGPT Plugins are a security nightmare
- Dec 2023Purple Llama by Meta AI
- Mar 2024Prompt injection and jailbreaking are not the same thing
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- 291
Decoding billions of integers per second through vectorization
Hacker News threads
- Sep 2012Fast integer compression: decoding billions of integers per second
- Sep 2012Fast integer compression: decoding billions of integers per second
- Jul 2013Fast integer compression in Java
- Feb 2017Multihash – self-describing hashes
- Sep 2017Stream VByte: breaking new speed records for integer compression
- Jun 2021Sorted Integer Compression
- Oct 202586 GB/s bitpacking with ARM SIMD (single thread)
- 292
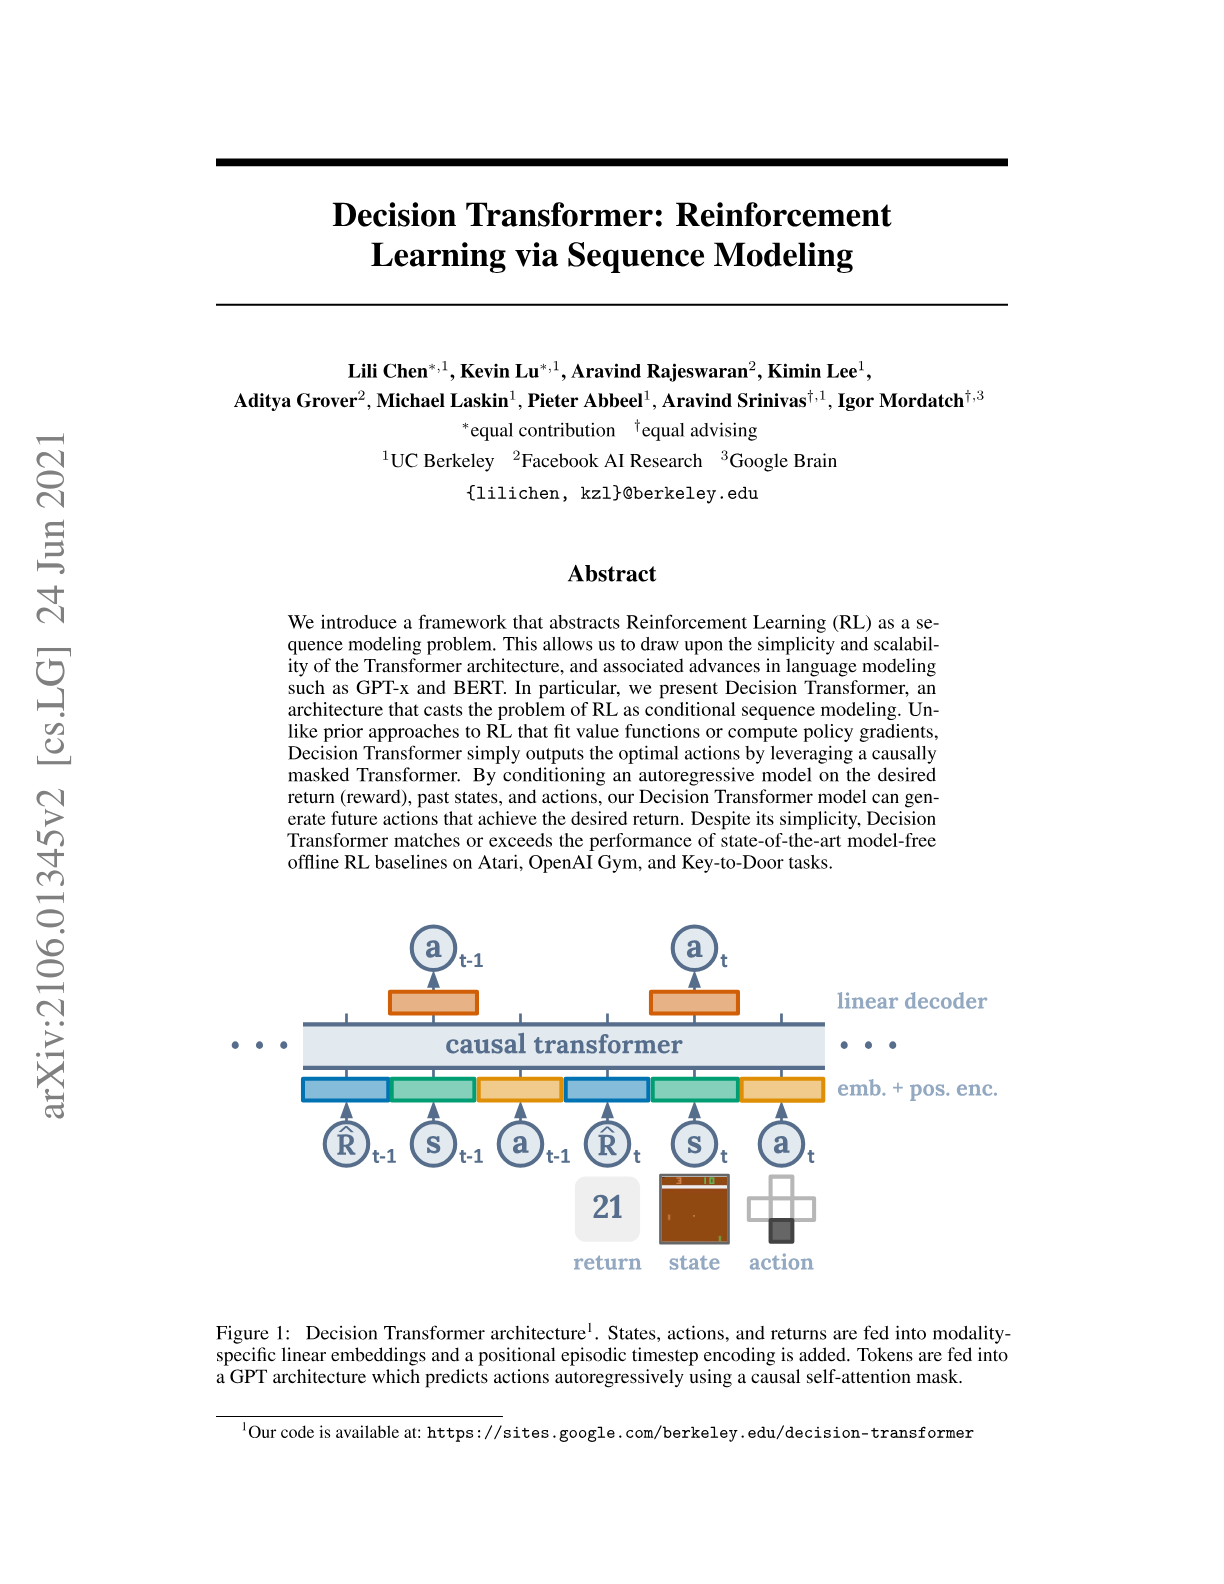
Decision Transformer: Reinforcement Learning via Sequence Modeling
Hacker News threads
- Nov 2022Decision Transformer: Reinforcement Learning via Sequence Modeling
- Jun 2021Decision Transformer: ReinforcementLearning via Sequence Modeling
- Jul 2021Deep reinforcement learning is a waste of time (2019)
- Jul 2021The Surprising Effectiveness of PPO in Cooperative Multi-Agent Games
- Oct 2023MemGPT: Towards LLMs as Operating Systems
- Aug 2024RLHF is just barely RL
- Jun 2025Q-learning is not yet scalable
- Oct 2025Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- 293
Physics of Language Models: Part 3.3, Knowledge Capacity Scaling Laws
Hacker News threads
- Apr 2024Physics of Language Models: Part 3.3, Knowledge Capacity Scaling Laws
- Jun 2024Researchers run high-performing LLM on the energy needed to power a lightbulb
- Jan 2025Nepenthes is a tarpit to catch AI web crawlers
- Jun 2025Meta's Llama 3.1 can recall 42 percent of the first Harry Potter book
- Oct 2025How to inject knowledge efficiently? Knowledge infusion scaling law for LLMs
- 294
Flamingo: a Visual Language Model for Few-Shot Learning
Hacker News threads
- 295
Were RNNs All We Needed?
Hacker News threads
- 296
Densely Connected Convolutional Networks
Hacker News threads
- Jul 2017Densely Connected Convolutional Networks: CVPR 2017 Best Paper Award Winner
- Feb 2017Densely Connected Convolutional Networks
- Jul 2017Best paper award CVPR 2017 DenseNets
- Nov 2016MXNet – Deep Learning Framework of Choice at AWS
- Jul 2017CVPR 2017 Best Paper Awards
- Jun 2021Do wide and deep networks learn the same things?
- Dec 2021DeepCreamPy- Decensoring Hentai with Deep Neural Networks (2018)
- Mar 2024DenseFormer: Enhancing Information Flow in Transformers
- Sep 2025Automatic differentiation can be incorrect
- 297
Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting
Hacker News threads
- 298
Why AI is Harder Than We Think
Hacker News threads
- Apr 2021Why AI is harder than we think
- Aug 2023Why AI Is Harder Than We Think (2021) [pdf]
- Jan 2023Why AI Is Harder Than We Think (2021)
- Apr 2021Superintelligence Risk Project: Conclusion
- May 2021Why A.I. Moonshots Miss
- Jan 2023The Expanding Dark Forest and Generative AI
- Jun 2024Ask HN: I have many PDFs – what is the best local way to leverage AI for search?
- Sep 2025Four Fallacies of Modern AI
- 299
Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
Hacker News threads
- May 2021Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
- Sep 2025Geometric Deep Learning Grids, Groups, Graphs, Geodesics, and Gauges [pdf]
- Apr 2021Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
- May 2021An Erlangen Programme to Establish the Geometric Foundations of Deep Learning
- Jun 2021ICLR 2021 Keynote: “Geometric Deep Learning: The Erlangen Programme of ML”
- Apr 2022Why train when you can optimize?
- Jan 2023Ask HN: What are the foundational texts for learning about AI/ML/NN?
- Jan 2023Just know stuff. (Or, how to achieve success in a machine learning PhD)
- Feb 2023Understanding and Coding the Self-Attention Mechanism of Large Language Models
- Jun 2025Spherical CNNs (2018)
- Sep 2025The maths you need to start understanding LLMs
- 300
Mastering Atari, Go, Chess and Shogi by Planning with a Learned Model
Hacker News threads
- Nov 2019Mastering Atari, Go, Chess and Shogi by Planning with a Learned Model
- Nov 2019Mastering Atari, Go, Chess and Shogi by Planning with a Learned Model
- Nov 2023Mastering Atari, Go, Chess and Shogi by Planning with a Learned Model (2019)
- Nov 2019DeepMind's MuZero teaches itself how to win at Atari, chess, shogi, and Go
- Nov 2019AI is mostly about curve fitting (2018)
- Nov 2019DeepMind's MuZero teaches itself how to win at Atari, chess, shogi, and Go
- Dec 2019Minecraft diamond challenge leaves AI creators stumped
- Aug 2020AI slays top F-16 pilot in DARPA dogfight simulation
- Dec 2020MuZero: Mastering Go, chess, shogi and Atari without rules
- Jul 2023Ask HN: Who is hiring? (July 2023)
- Sep 2025'World Models,' an old idea in AI, mount a comeback
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.