Hacker Papers
- 351
The Secret Sharer: Evaluating and Testing Unintended Memorization in Neural Networks
Hacker News threads
- Feb 2018The Secret Sharer: Measuring Unintended NN Memorization and Extracting Secrets
- Mar 2018The Secret Sharer: Measuring Unintended NN Memorization and Extracting Secrets
- Oct 2018Measuring Unintended Neural Network Memorization and Extracting Secrets
- May 2019Maryland research could improve the AI task of sensorimotor representation
- Oct 2019Google T5 scores 88.9 on SuperGLUE Benchmark, approaching human baseline
- Nov 2019Training algorithms on copyrighted data not illegal: US Supreme Court
- Jan 2021A Plan Made to Shield Big Tobacco from Facts Is Now EPA Policy
- Jan 2021DALL·E: Creating Images from Text
- 352
Vectorized and performance-portable Quicksort
Hacker News threads
- Feb 2024Vectorized and performance-portable Quicksort (2022)
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Apple M2 Die Shot and Architecture Analysis – Big Cost Increase and A15 Based IP
- Dec 2022Sorting with SIMD
- Jan 2023Efficient and performance-portable vector software
- Mar 2024JPEG XL and the Pareto Front
- 353
MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
Hacker News threads
- Jun 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- Jun 2023Bytes Are All You Need: Transformers Operating Directly on File Bytes
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Oct 2025Neural audio codecs: how to get audio into LLMs
- 354
Retentive Network: A Successor to Transformer for Large Language Models
Hacker News threads
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer Implemented in PyTorch
- Sep 2023The Eleuther AI Mafia
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 20232023: The Year of AI
- Jan 2024Eagle 7B: Soaring past Transformers
- 355
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 356
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 357
GLU Variants Improve Transformer
Hacker News threads
- Aug 2023Llama from Scratch (or how to implement a paper without crying)
- Nov 2023Simplifying Transformer Blocks
- Sep 2024SwiGLU activation function causes instability in FP8 LLM training
- Jun 2026Don't trust large context windows
- Jun 2026Anthropic to Require ID Verification for Certain Capabilities Starting July 8
- 358
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 359
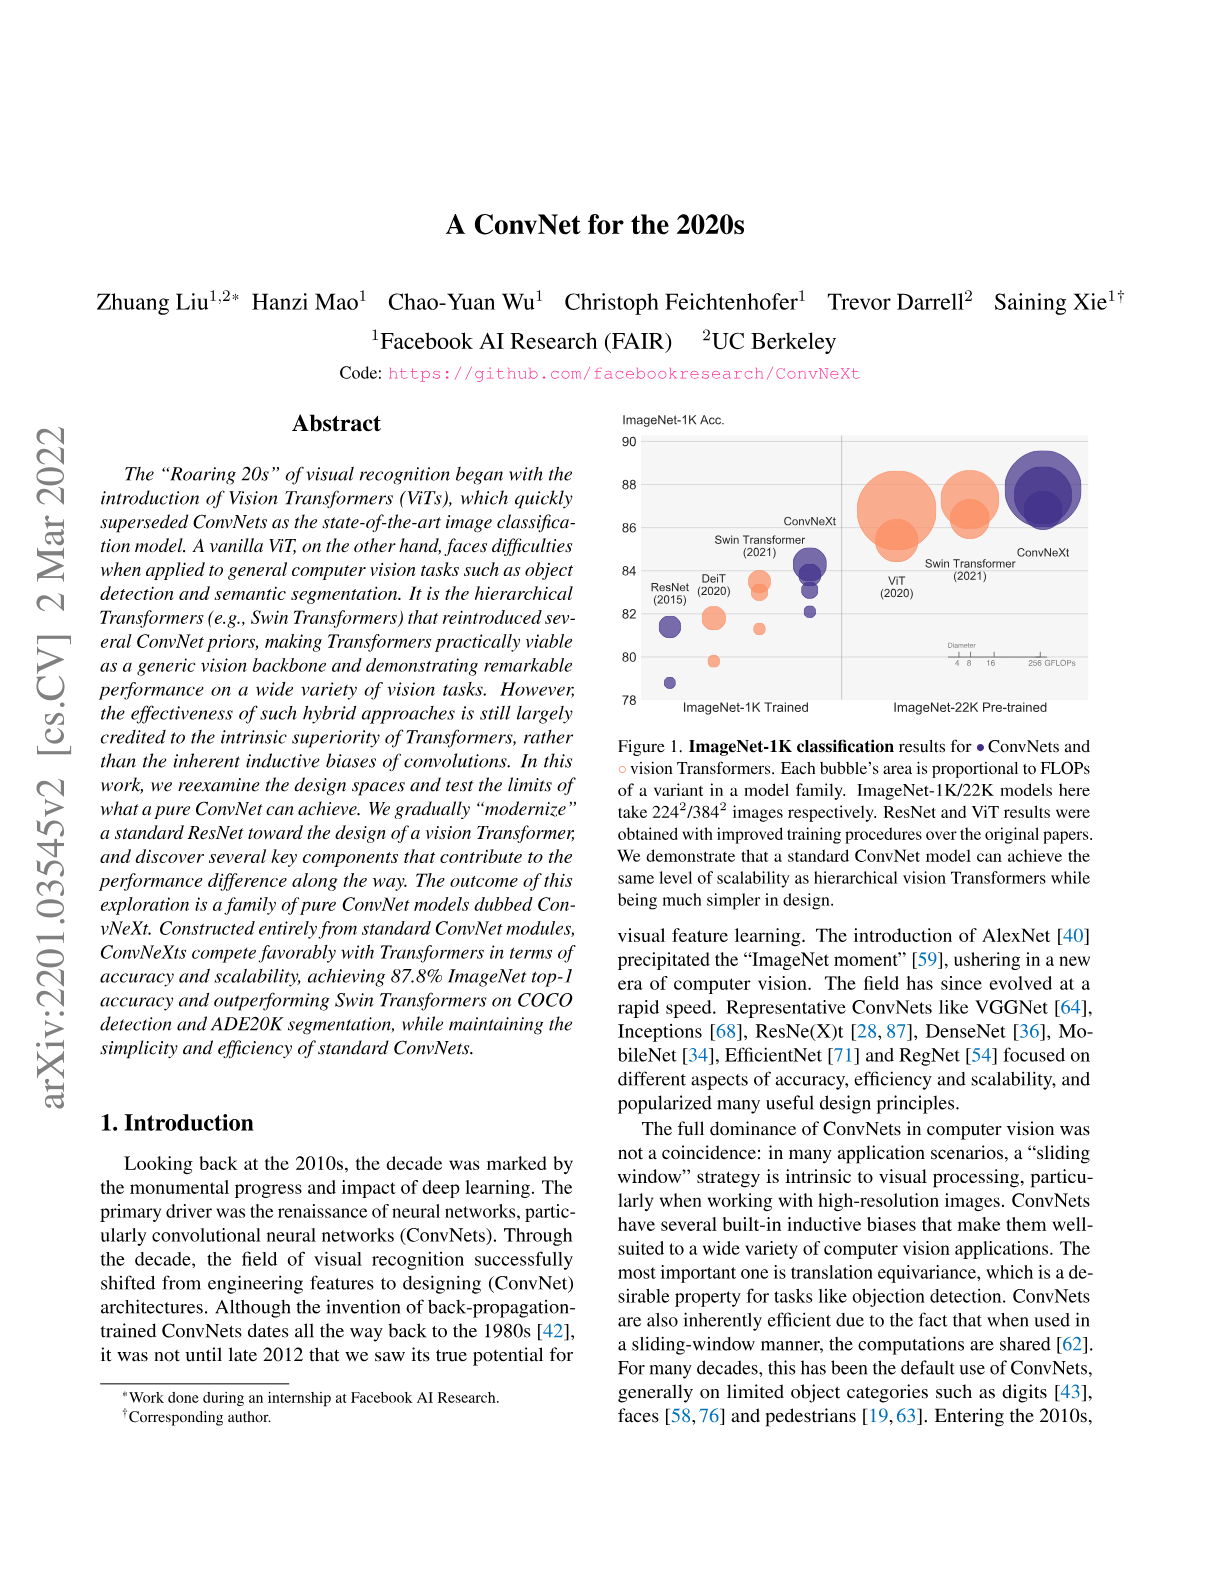
A ConvNet for the 2020s
Hacker News threads
- May 2024A ConvNet for the 2020s
- Jan 2022A ConvNet for the 2020s
- Jan 2022A ConvNet for the 2020s
- Apr 2022Transformers Are All You Need
- Apr 2022Transformers Are All You Need
- Apr 2023Swin Transformer: Hierarchical Vision Transformer Using Shifted Windows
- Jan 2024Citation cartels help mathematicians-and their universities-climb the rankings
- Aug 2024What's Going on in Machine Learning? Some Minimal Models
- 360
FNet: Mixing Tokens with Fourier Transforms
Hacker News threads
- May 2024FNet: Mixing Tokens with Fourier Transforms (2021)
- May 2021FNet: Mixing Tokens with Fourier Transforms
- May 2021FNet: Attention may be all you WANT but we you need is good token mixing
- May 2021An Interactive Guide to the Fourier Transform (2012)
- May 2024New attention mechanisms that outperform standard multi-head attention
- May 2024New attention mechanisms that outperform standard multi-head attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
- 361
Acquisition of Chess Knowledge in AlphaZero
Hacker News threads
- Nov 2021Acquisition of Chess Knowledge in AlphaZero
- Nov 2021Acquisition of Chess Knowledge in AlphaZero
- Nov 2021Acquisition of Chess Knowledge in AlphaZero [pdf]
- Nov 2021Acquisition of chess knowledge in AlphaZero
- Nov 2021Acquisition of chess knowledge in AlphaZero
- Dec 2021Can deep learning help mathematicians build intuition?
- Nov 2022Acquisition of chess knowledge in AlphaZero
- Feb 2026Experts Have World Models. LLMs Have Word Models
- 362
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 363
SynthID-Image: Image watermarking at internet scale
Hacker News threads
- Oct 2025SynthID-Image: Invisibly Watermarking AI-Generated Imagery
- Apr 2026ChatGPT Images 2.0
- May 2026OpenAI Adopts Google's SynthID Watermark for AI Images with Verification Tool
- May 2026OpenAI Adopts Google's SynthID Watermark for AI Images with Verification Tool
- Jun 2026Appreciating Exif
- Oct 2026SynthID Detector
- 364
Inferring Algorithmic Patterns with Stack-Augmented Recurrent Nets
Hacker News threads
- 365
LLMs Will Always Hallucinate, and We Need to Live With This
Hacker News threads
- Sep 2024LLMs Will Always Hallucinate, and We Need to Live with This
- Sep 2024LLMs Will Always Hallucinate, and We Need to Live with This
- Sep 2024I no longer use AI assistant
- Oct 2024Announcing the Tech for Palestine Incubator
- Oct 2024Show HN: Last CLI tool you will need
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Jun 2025O3 Turns Pro
- Sep 2026How OpenAI Used Its Own LLMs to Design Its Jalapeño Chip
- 366
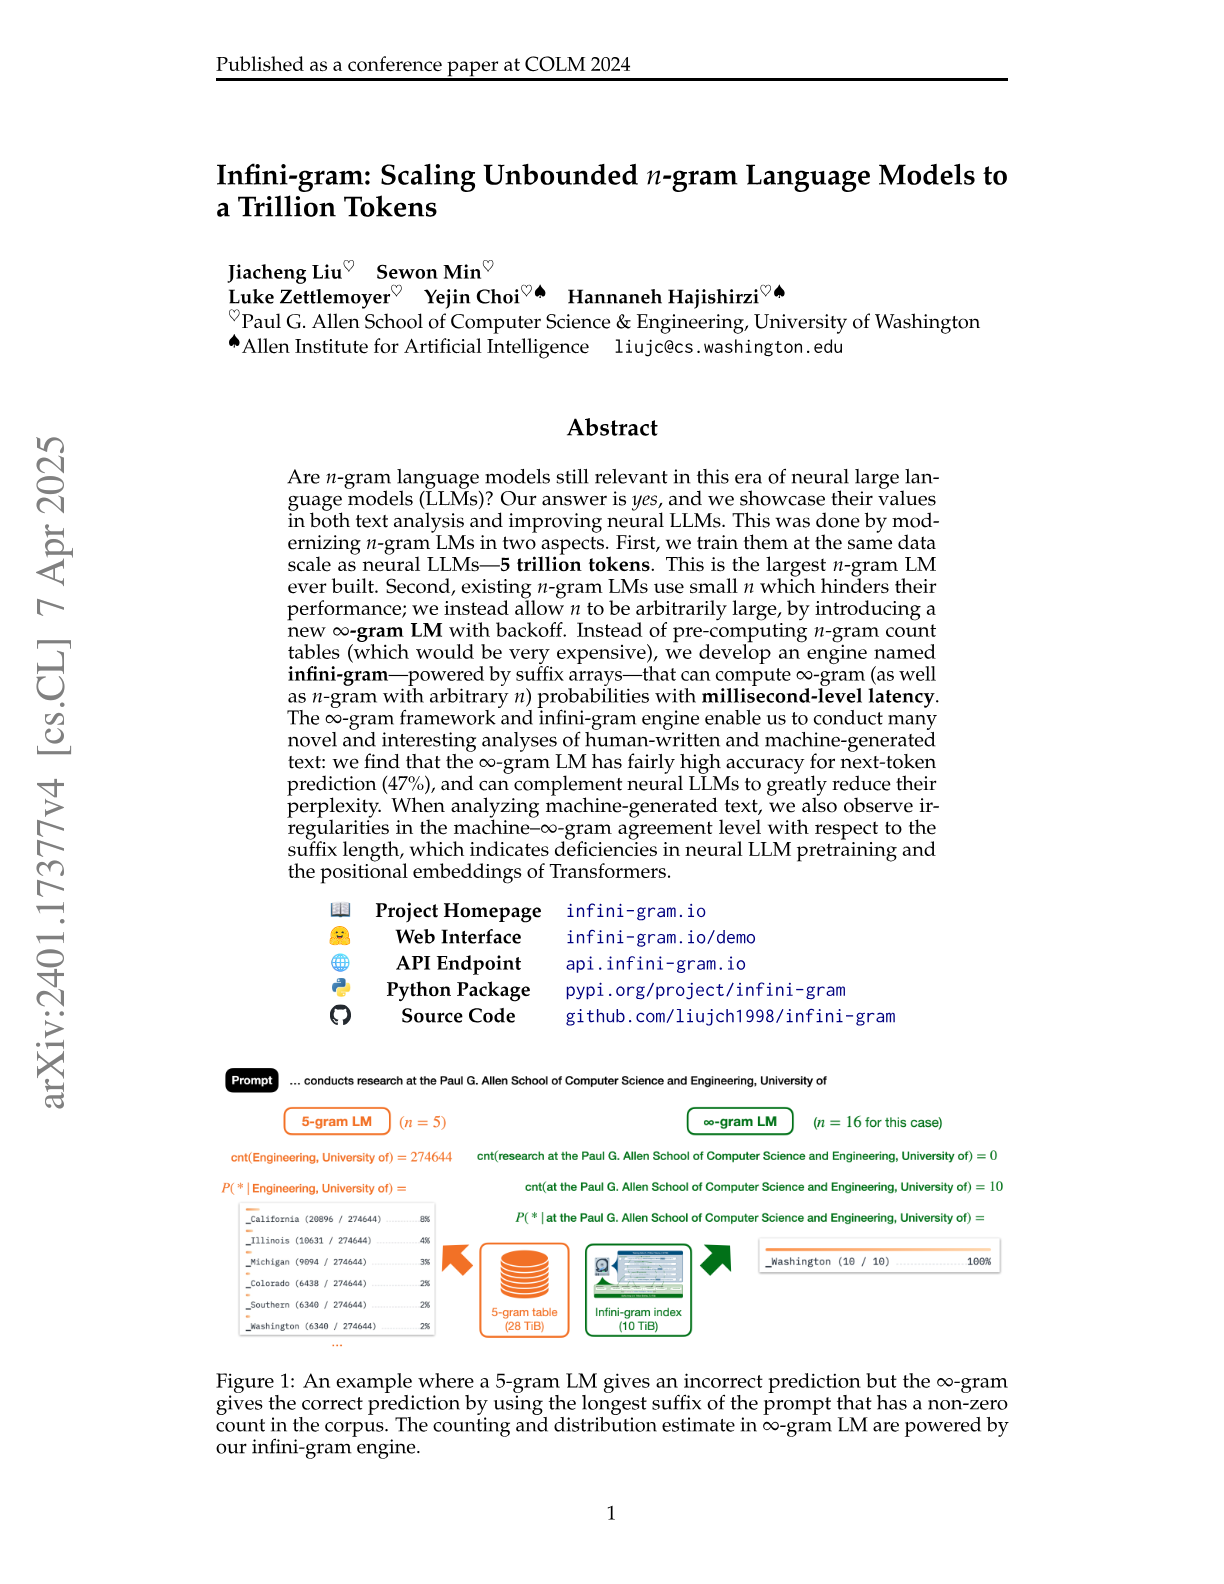
Infini-gram: Scaling Unbounded n-gram Language Models to a Trillion Tokens
Hacker News threads
- May 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Infini-Gram: Scaling Unbounded N-Gram Language Models to a Trillion Tokens
- Feb 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Markov Chains are the Original Language Models
- Jun 2024Transformers Represent Belief State Geometry in Their Residual Stream
- Nov 2025A new Google model is nearly perfect on automated handwriting recognition
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Apr 2026Soul Player C64 – A real transformer running on a 1 MHz Commodore 64
- 367
Tortured phrases: A dubious writing style emerging in science. Evidence of critical issues affecting established journals
Hacker News threads
- Aug 2021A dubious writing style emerging in science
- Aug 2021Tortured phrases: A dubious writing style emerging in science
- Jun 2023Junk websites filled w AI-generated text pulling in money from programmatic ads
- Dec 2023Tortured conference series thriving in Computer Science
- Aug 2026Research papers using "kidney disappointment" instead of "kidney failure"
- Aug 2026Research papers using "kidney disappointment" instead of "kidney failure"
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 368
Reinforcement Learning: An Overview
Hacker News threads
- Feb 2025Reinforcement Learning: An Overview
- Dec 2024Reinforcement Learning: An Overview
- Feb 2025RLHF Book
- Mar 2025Mathematical Foundations of Reinforcement Learning
- Mar 2025A (Long) Peek into Reinforcement Learning
- Nov 2025CS234: Reinforcement Learning Winter 2025
- Jun 2026The 90-year-old idea behind JEPA models: Canonical Correlation Analysis
- 369
Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context
Hacker News threads
- May 2024Gemini 1.5: Multimodal understanding across tokens of context
- Mar 2024Google's Gemini 1.5 Pro whitepaper
- Mar 2024Gemini 1.5: Unlocking multimodal understanding across tokens of context
- Apr 2024Hello OLMo: A truly open LLM
- Apr 2024Can Gemini 1.5 read all the Harry Potter books at once?
- May 2024Ask HN: Disillusioned after AI?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Mar 2026Yann LeCun's AI startup raises $1B in Europe's largest ever seed round
- 370
Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
Hacker News threads
- Mar 2026DeepSeek: Conditional Memory via Scalable Lookup
- Jan 2026Conditional Memory via Scalable Lookup
- Jan 2026RAM Coffers– I built conditional memory for LLMs 27 days before DeepSeek'sEngram
- Jan 2026Subject-based weight routing for LLMs (27 days before DeepSeek Engram)
- Mar 2026Intel Announces Arc Pro B70 and Arc Pro B65 GPUs
- Aug 2026Qwen3.8-Flash-Next: A New Architecture, Towards Ultimate Cost-Efficiency
- Sep 2026Show HN: Engram – Shared procedural runbook memory for AI coding agents via MCP
- 371
Exploring the Limits of Language Modeling
Hacker News threads
- Feb 2016Exploring the Limits of Language Modeling
- Feb 2016Exploring the Limits of Language Modeling
- Feb 2016Running your models in production with TensorFlow Serving
- Sep 2016Researchers achieve speech recognition milestone
- Sep 2016New P2 Instance Type for Amazon EC2 – Up to 16 GPUs
- Feb 2017Using Ordered Markov Chains and User Information to Speed Up Password Cracking
- Jun 2017Random Generation of English Sentences (1961) [pdf]
- 372
Poincaré Embeddings for Learning Hierarchical Representations
Hacker News threads
- Jun 2017Poincaré Embeddings for Learning Hierarchical Representations
- Oct 2017Show HN: Implementation of Poincaré Embeddings(Facebook Research) in Numpy
- Aug 2019Music Recommendations in Hyperbolic Space
- Aug 2019Implementing Poincaré Embeddings (2017)
- Feb 2021Illuminating hyperbolic geometry (2015) [video]
- Apr 2024Quaternion Knowledge Graph Embeddings (2019)
- 373
Show Your Work: Scratchpads for Intermediate Computation with Language Models
Hacker News threads
- Jul 2022Show Your Work: Scratchpads For Intermediate Computation With Language Models
- Feb 2022AlphaCode as a dog speaking mediocre English
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Mar 2023ChatGPT has trouble giving an answer before explaining its reasoning
- Nov 2025Claude Opus 4.5
- Apr 2026Talk like caveman
- 374
Petals: Collaborative Inference and Fine-tuning of Large Models
Hacker News threads
- Jul 2026Petals: Collaborative Inference and Fine-Tuning of Large Models
- Mar 2023Petals: Collaborative Inference and Fine-Tuning of Large Models
- Dec 2022Petals is creating a free, distributed network for running text-generating AI
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Ask HN: Can you crowdfund the compute for GPT?
- Feb 2023Running large language models like ChatGPT on a single GPU
- Mar 2023The Most Cited AI Papers in 2022
- 375
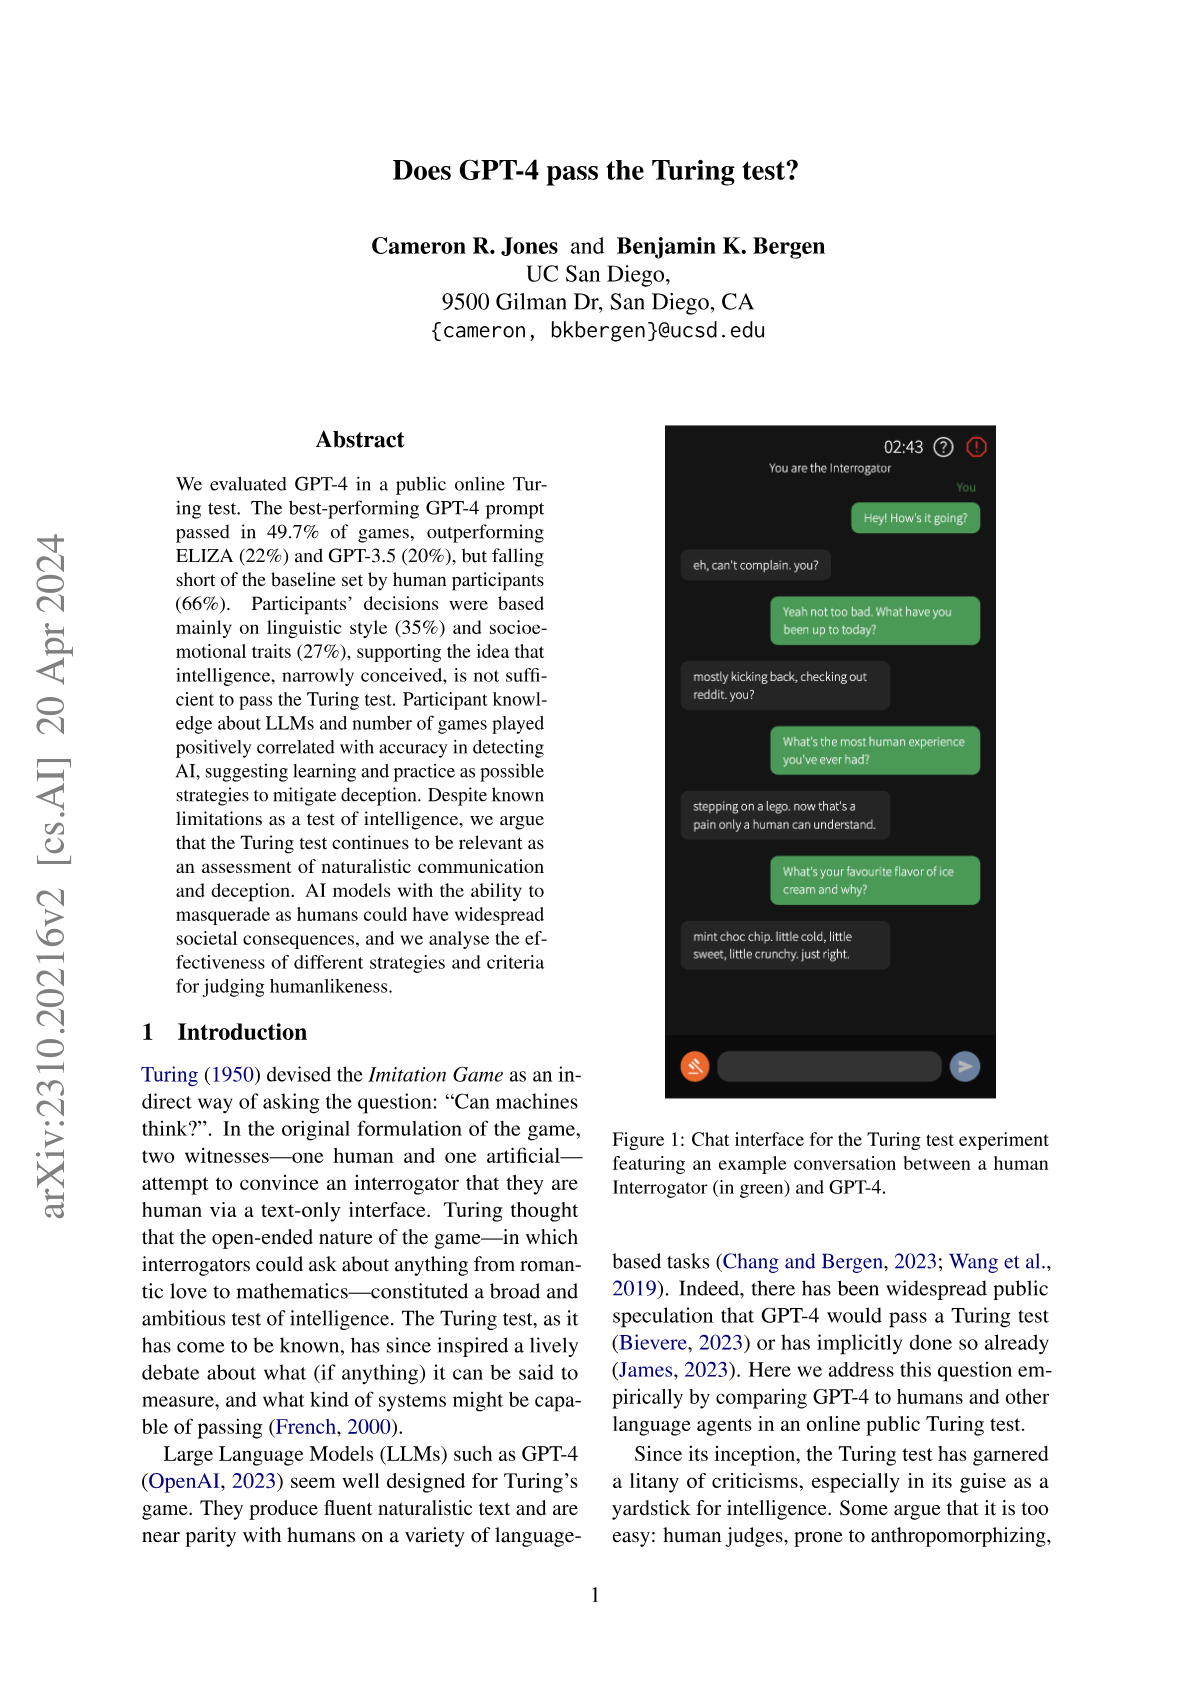
Does GPT-4 pass the Turing test?
Hacker News threads
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023OpenAI Announces Leadership Transition
- Dec 20231960s chatbot ELIZA beat OpenAI's GPT-3.5 in a recent Turing test study
- Jan 2024Stuff we figured out about AI in 2023
- Jan 2024AI or Ain't: Eliza
- Jun 2024AI Hype is completely out of control – especially since ChatGPT-4o [video]
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.