Hacker Papers
- 351
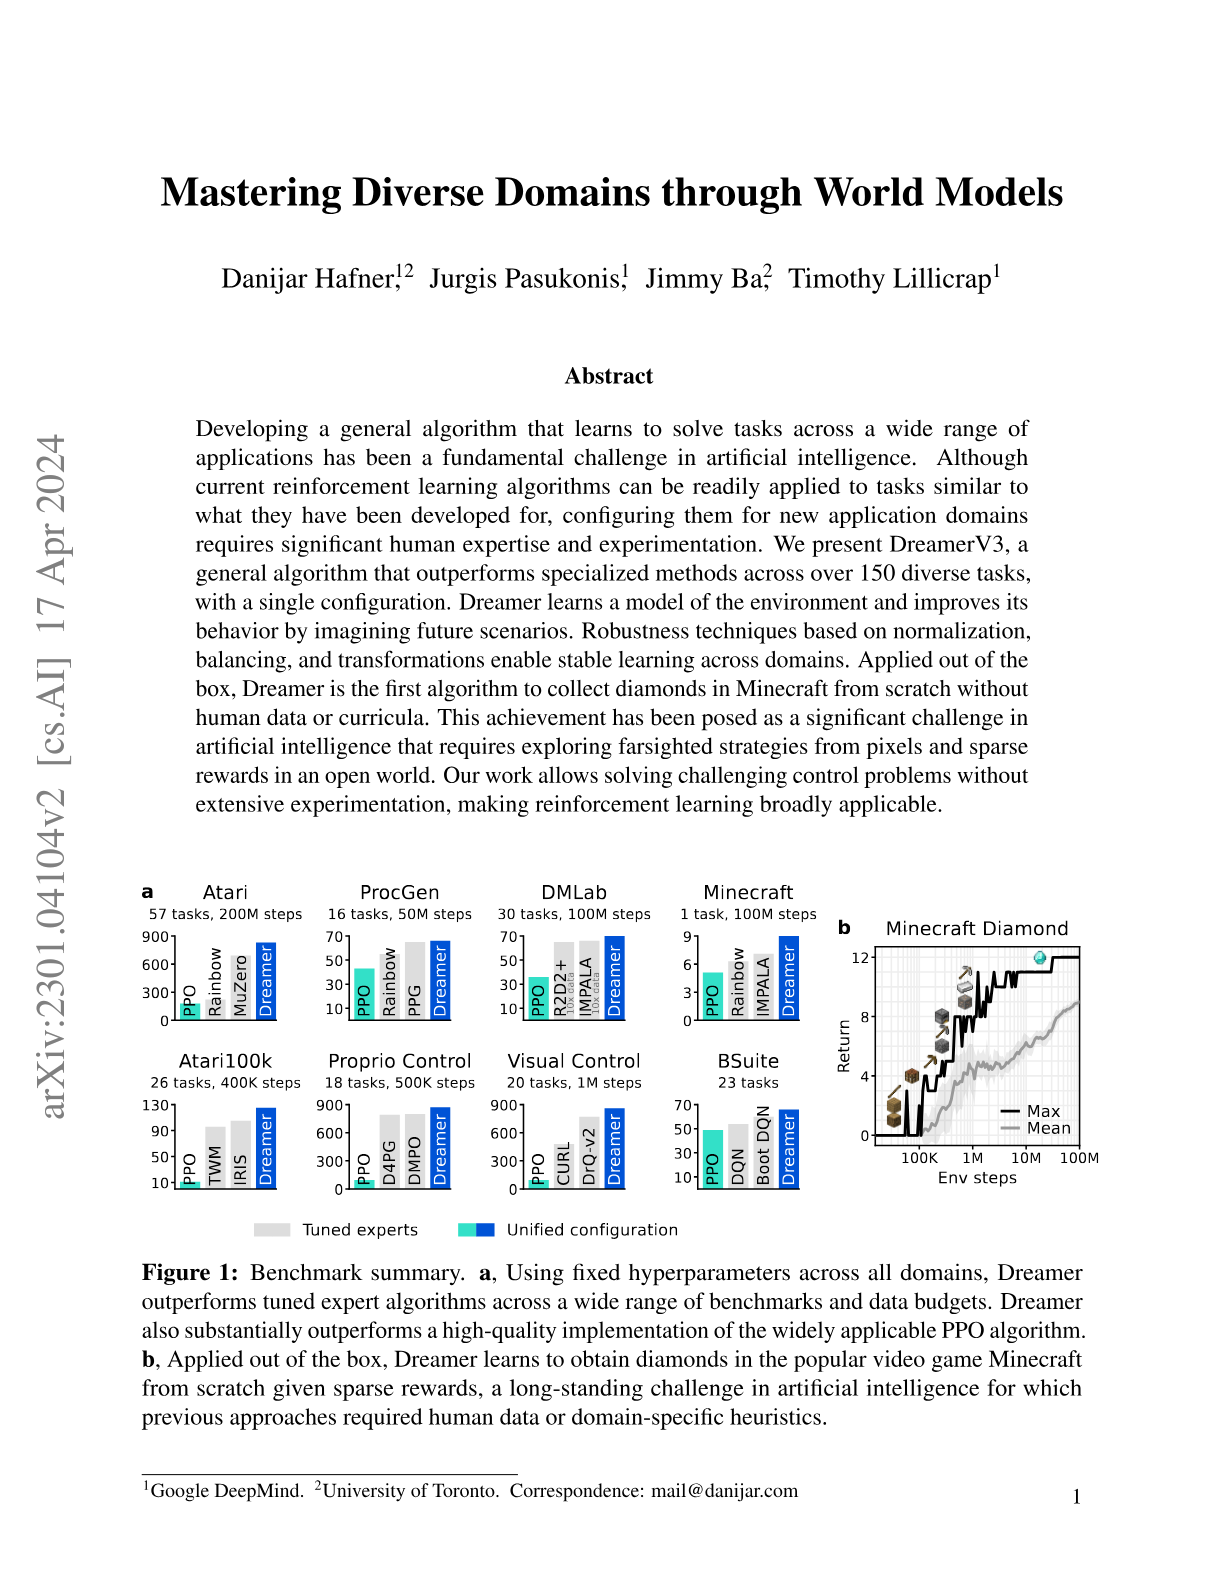
Mastering Diverse Domains through World Models
Hacker News threads
- 352
Perceiver IO: A General Architecture for Structured Inputs & Outputs
Hacker News threads
- Aug 2021Perceiver IO: A General Architecture for Structured Inputs and Outputs
- Apr 2025Perceiver IO: A General Architecture for Structured Inputs and Outputs (2021)
- Sep 2021Has AI found a new foundation?
- Nov 2021Permutation-Invariant Neural Networks for Reinforcement Learning
- Jun 2023Bytes Are All You Need: Transformers Operating Directly on File Bytes
- 353
Universal Language Model Fine-tuning for Text Classification
Hacker News threads
- Mar 2025The algo that advanced natural language processing and influenced OpenAI's LLMs
- Jan 2018Language Models for Classification (state of art on everything)
- Jan 2018Fine-Tuned Language Models for Text Classification [pdf]
- Feb 2018Learning Word Vectors for 157 Languages
- May 2018State-of-the-art text classification with universal language models
- May 2018Our machine learning and NLP journey
- Jun 2018Improving Language Understanding with Unsupervised Learning
- Jul 2018NLP's ImageNet Moment: From Shallow to Deep Pre-Training
- Jul 2020Classifying 200k articles in 7 hours using NLP
- Nov 2023OpenAI Announces Leadership Transition
- 354
The Matrix Calculus You Need For Deep Learning
Hacker News threads
- Apr 2021The matrix calculus you need for deep learning (2018)
- Feb 2018The Matrix Calculus You Need For Deep Learning
- Jan 2020The Matrix Calculus You Need for Deep Learning
- Aug 2018Learning Math for Machine Learning
- Oct 2021Ask HN: As a professional, does it worth it to learn the math behind NN?
- Apr 2023Matrix Calculus: Calculate derivatives of matrices
- Jul 2023The Matrix Calculus You Need for Deep Learning
- Jan 2024Calculus on Computational Graphs: Backpropagation (2015)
- Sep 2024Ask HN: Calculus Refresher for AI/ML?
- Mar 2025Matrix Calculus (For Machine Learning and Beyond)
- 355
Learning to learn by gradient descent by gradient descent
Hacker News threads
- Jun 2016Learning to learn by gradient descent by gradient descent
- Jun 2016Learning to learn by gradient descent by gradient descent
- Jun 2016Learning to learn by gradient descent by gradient descent
- Aug 2016News Feed FYI: Further Reducing Clickbait in Feed
- Dec 2016Tool AIs want to be agent AIs
- Jan 2017Darpa Goes “Meta” with Machine Learning for Machine Learning (2016)
- Jan 2017Darpa Goes “Meta” with Machine Learning for Machine Learning (2016)
- Feb 2017The Convex Geometry of Inverse Problems [video]
- Jul 2017Hacker's guide to Neural Networks (2012)
- Oct 2019Gradient Descent: The Ultimate Optimizer
- Mar 2025Optimizing ML training with metagradient descent
- 356
Do Language Models Know When They're Hallucinating References?
Hacker News threads
- May 2023Do Language Models Know When They're Hallucinating References?
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- Sep 2023ChatGPT can now see, hear, and speak – openai.com
- Oct 2023Llama 2 Everywhere (L2E): Standalone, Binary Portable, Bootable Llama 2
- Mar 2025AI Blindspots – Blindspots in LLMs I've noticed while AI coding
- 357
Understanding deep learning requires rethinking generalization
Hacker News threads
- Feb 2017Understanding deep learning requires rethinking generalization
- Dec 2018Understanding deep learning requires rethinking generalization
- Aug 2020Understanding Deep Learning Requires Re-Thinking Generalization (2017)
- Dec 2016LSTM Neural Networks for Time Series Prediction
- May 2017Deep Learning’s Impact on Image Processing, Mathematics, and Humanity
- Jan 2018Cloud AutoML: Making AI accessible to every business
- Oct 2018The Mixed Track Record of Machine Learning Algorithms
- Feb 2020A popular self-driving car dataset is missing labels for hundreds of pedestrians
- Mar 2021Understanding deep learning requires rethinking generalization
- May 2024Gradient descent visualization
- Mar 2025Deep Learning Is Not So Mysterious or Different
- 358
Resurrecting Recurrent Neural Networks for Long Sequences
Hacker News threads
- 359
Troubling Trends in Machine Learning Scholarship
Hacker News threads
- Nov 2019Troubling trends in machine learning scholarship (2018)
- Jul 2018Troubling Trends in Machine Learning Scholarship
- Sep 2019A.I. researchers are making more than $1M, even at a nonprofit
- Oct 2020AI Is an Ideology, Not a Technology
- Sep 2024Why Most Published Research Findings Are False (2005)
- Mar 2025The cultural divide between mathematics and AI
- 360
Semi-Supervised Learning with Ladder Networks
Hacker News threads
- 361
Deep Learning Recommendation Model for Personalization and Recommendation Systems
Hacker News threads
- 362
Learning Transferable Visual Models From Natural Language Supervision
Hacker News threads
- Mar 2021The End of Tesla’s Dominance May Be Closer Than It Appears
- Aug 2021Machine learning won't solve natural language understanding
- Apr 2022A few things to try with DALL·E
- Apr 2022How DALL-E 2 Works
- Mar 2024Is Cosine-Similarity of Embeddings Really About Similarity?
- Aug 2024Artists score major win in copyright case against AI art generators
- Jan 2025Don't use cosine similarity carelessly
- Mar 2025Ask HN: Any truly multi-modal transformer architectures?
- 363
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 364
Hyena Hierarchy: Towards Larger Convolutional Language Models
Hacker News threads
- Apr 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Apr 2023Hyena a more efficient convolutional LLM when compared to GPT
- Mar 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Mar 2023CoLT5: Faster Long-Range Transformers With Conditional Computation
- Apr 2023From Deep to Long Learning
- Apr 2023From Deep to Long Learning
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Apr 2023New technology could blow away GPT-4 and everything like it
- May 2023OpenAI's plans according to sama
- Sep 2023The Eleuther AI Mafia
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- 365
Efficiently Modeling Long Sequences with Structured State Spaces
Hacker News threads
- 366
Your Classifier is Secretly an Energy Based Model and You Should Treat it Like One
Hacker News threads
- Sep 2020Score matching with Langevin Sampling: a new contender to GANs
- Sep 2020Show HN: Build a DIY license plate reader with machine learning
- Mar 2021Understanding deep learning requires rethinking generalization
- Aug 2024A new type of neural network is more interpretable
- Aug 2024Fun times with energy-based models
- Feb 2025Softmax forever, or why I like softmax
- 367
That Chip Has Sailed: A Critique of Unfounded Skepticism Around AI for Chip Design
Hacker News threads
- Nov 2024That Chip Has Sailed: Critique of Unfounded Skepticism Around AI for Chip Design
- Nov 2024A Critique of Unfounded Skepticism Around AI for Chip Design
- Nov 2024AI Alone Isn't Ready for Chip Design
- Nov 2024AI Alone Isn't Ready for Chip Design
- Dec 2024Jeff Dean responds to EDA industry about AlphaChip
- Dec 2024Jeff Dean responds to EDA industry about AlphaChip
- Feb 2025Accelerating scientific breakthroughs with an AI co-scientist
- 368
SLIDE : In Defense of Smart Algorithms over Hardware Acceleration for Large-Scale Deep Learning Systems
Hacker News threads
- Mar 2020Smart Algorithms beat Hardware Acceleration for Large-Scale Deep Learning
- Mar 2019In Defense of Smart Algorithms over Hardware Acceleration for Deep Learning
- Mar 2020Slide: In Defense of Smart Algorithms over Hardware Accelerated Deep Learning
- Mar 2020Deep Learning Breakthrough Sees One Xeon Destroying 8x Nvidia Tesla V100 GPUs
- Dec 2020Researchers propose faster, more efficient alternatives to backpropagation
- Apr 2021CPU-based algorithm trains deep neural nets up to 15 times faster than top GPU
- Apr 2021CPU-based algorithm trains deep neural nets up to 15 times faster than top GPU
- Aug 2021pHash – An open source perceptual hash library (2013)
- Oct 2021New features coming in Julia 1.7
- Feb 2022Two sparsities are better than one: Performance of sparse-sparse networks
- Feb 2025(Ab)using general search algorithms on dynamic optimization problems (2023)
- 369
Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters
Hacker News threads
- Feb 2025Scaling Test-Time Compute Can Be More Effective Than Scaling Parameters (2024)
- Aug 2024Scaling LLM Test-Time Compute More Effective Than Scaling Model Parameters
- Sep 2024Scaling LLM Test-Time can be More Effective than Scaling Parameters
- Aug 2024Cerebras Inference: AI at Instant Speed
- Aug 2024Let's Verify Step by Step
- Sep 2024Learning to Reason with LLMs
- Dec 2024Open source inference time compute example from HuggingFace
- 370
RWKV: Reinventing RNNs for the Transformer Era
Hacker News threads
- May 2023RWKV: Reinventing RNNs for the Transformer Era
- Jul 2023Scaling Transformers to 1B Tokens
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Dec 2023Paving the way to efficient architectures: StripedHyena-7B
- Jan 2024Eagle 7B: Soaring past Transformers
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 371
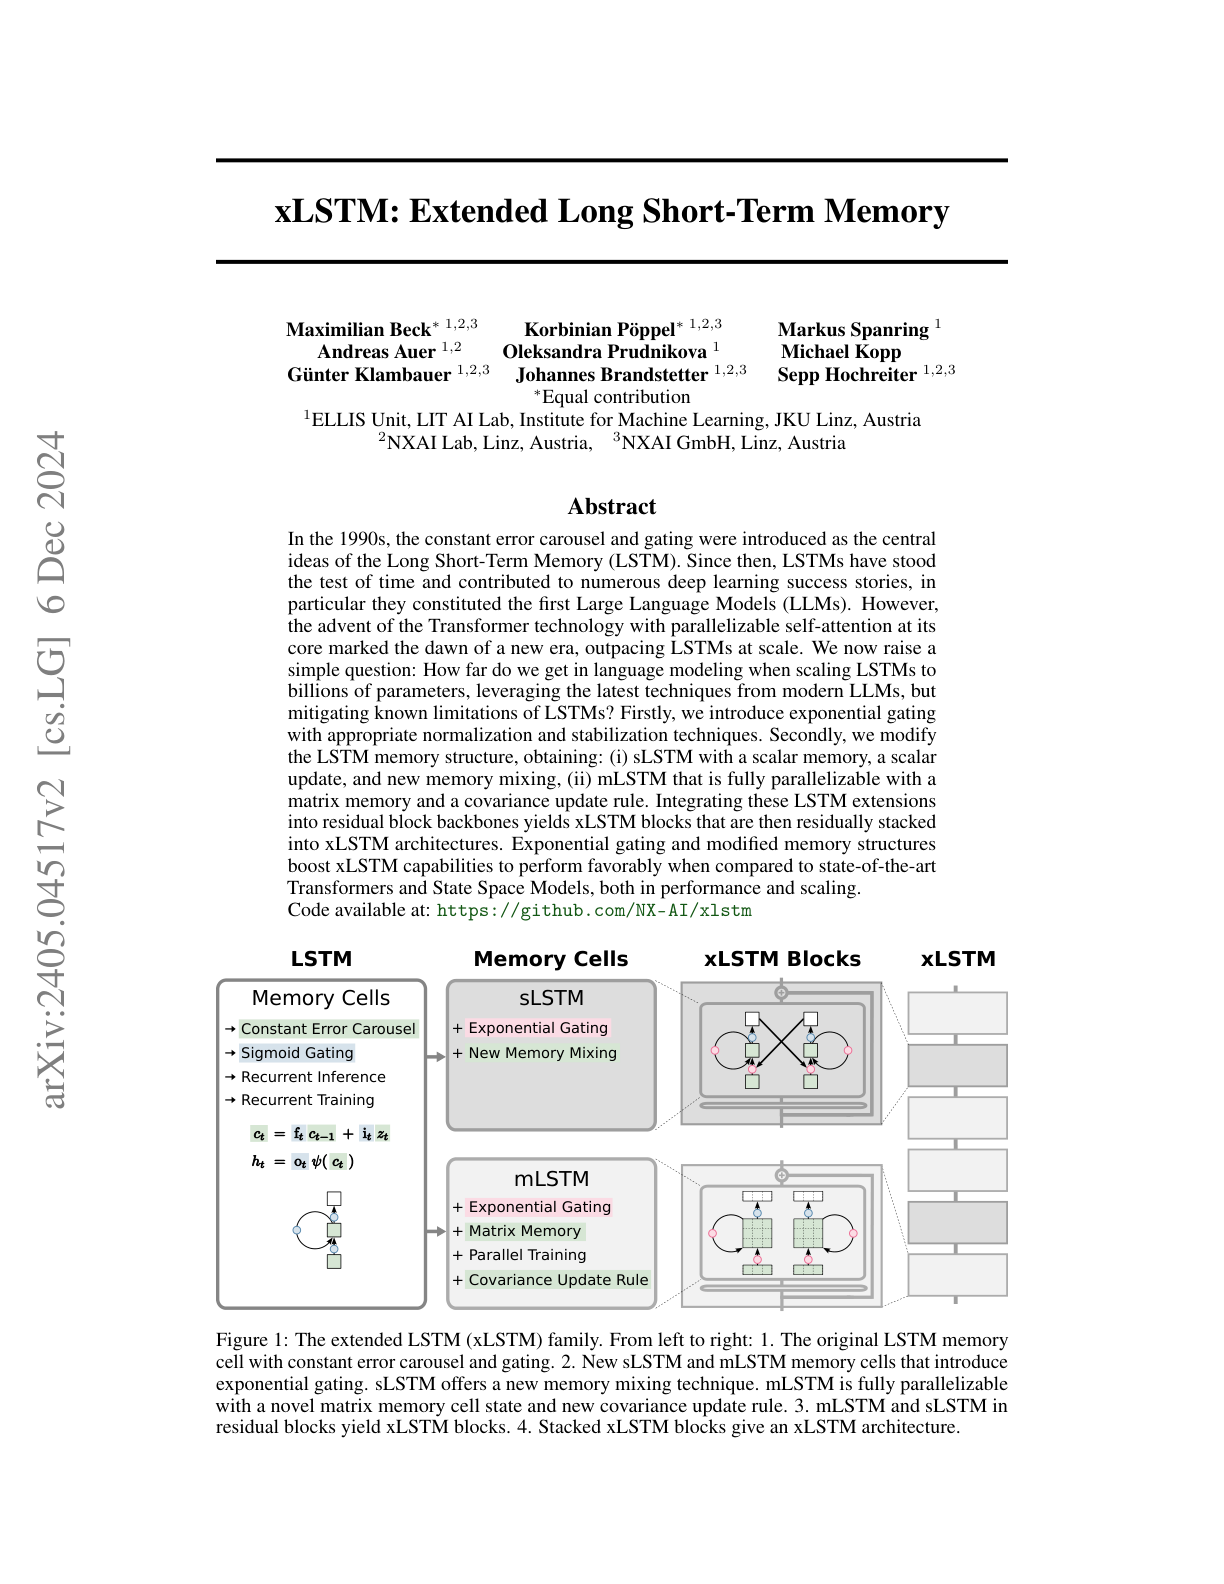
xLSTM: Extended Long Short-Term Memory
Hacker News threads
- May 2024xLSTM: Extended Long Short-Term Memory
- May 2024Ilya Sutskever: “If you learn all of these, you’ll know 90% of what matters”
- May 2024New attention mechanisms that outperform standard multi-head attention
- Jun 2024xLSTM code release by NX-AI
- Oct 2024Were RNNs all we needed?
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 372
FrontierMath: A Benchmark for Evaluating Advanced Mathematical Reasoning in AI
Hacker News threads
- 373
Generating Sequences With Recurrent Neural Networks
Hacker News threads
- Jun 2015Extending “Let It Go” with recurrent neural network
- Mar 2016Dynamic Memory Networks for Visual and Textual Question Answering
- Apr 2016Neural Networks Are Impressively Good at Compression
- May 2016Neural Networks Are Impressively Good at Compression
- Apr 2017Lyrebird – An API to copy the voice of anyone
- Aug 2020An attempt to make a font look more handwritten
- Jan 2023Realistic Computer-Generated Handwriting
- Feb 2025Ghostwriter – use the reMarkable2 as an interface to vision-LLMs
- 374
LLaMA: Open and Efficient Foundation Language Models
Hacker News threads
- Mar 2024LLaMA: Open and Efficient Foundation Language Models (2023)
- Mar 2023The Most Cited AI Papers in 2022
- Mar 2023Using LLaMA with M1 Mac and Python 3.11
- Mar 2023The RWKV language model: An RNN with the advantages of a transformer
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- May 2023OpenLLaMA: An Open Reproduction of LLaMA
- Jun 2023OpenLLaMA 13B Released
- Sep 2023Mistral 7B, the most powerful language model for its size to date, Apache 2.0
- Feb 2025Meta torrented & seeded 81.7 TB dataset containing copyrighted data
- 375
Cambrian-1: A Fully Open, Vision-Centric Exploration of Multimodal LLMs
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.