Hacker Papers
- 26
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
Hacker News threads
- Jun 2026The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Nov 2023Greg Brockman quits OpenAI
- Jan 2024New theory suggests LLMs can understand text
- Jul 2024Mistral NeMo
- Nov 2025Learn Prolog Now (2006)
- Jul 2026A global workspace in language models
- Aug 2026Tim Gowers: What sort of maths are LLMs good at?
- 27
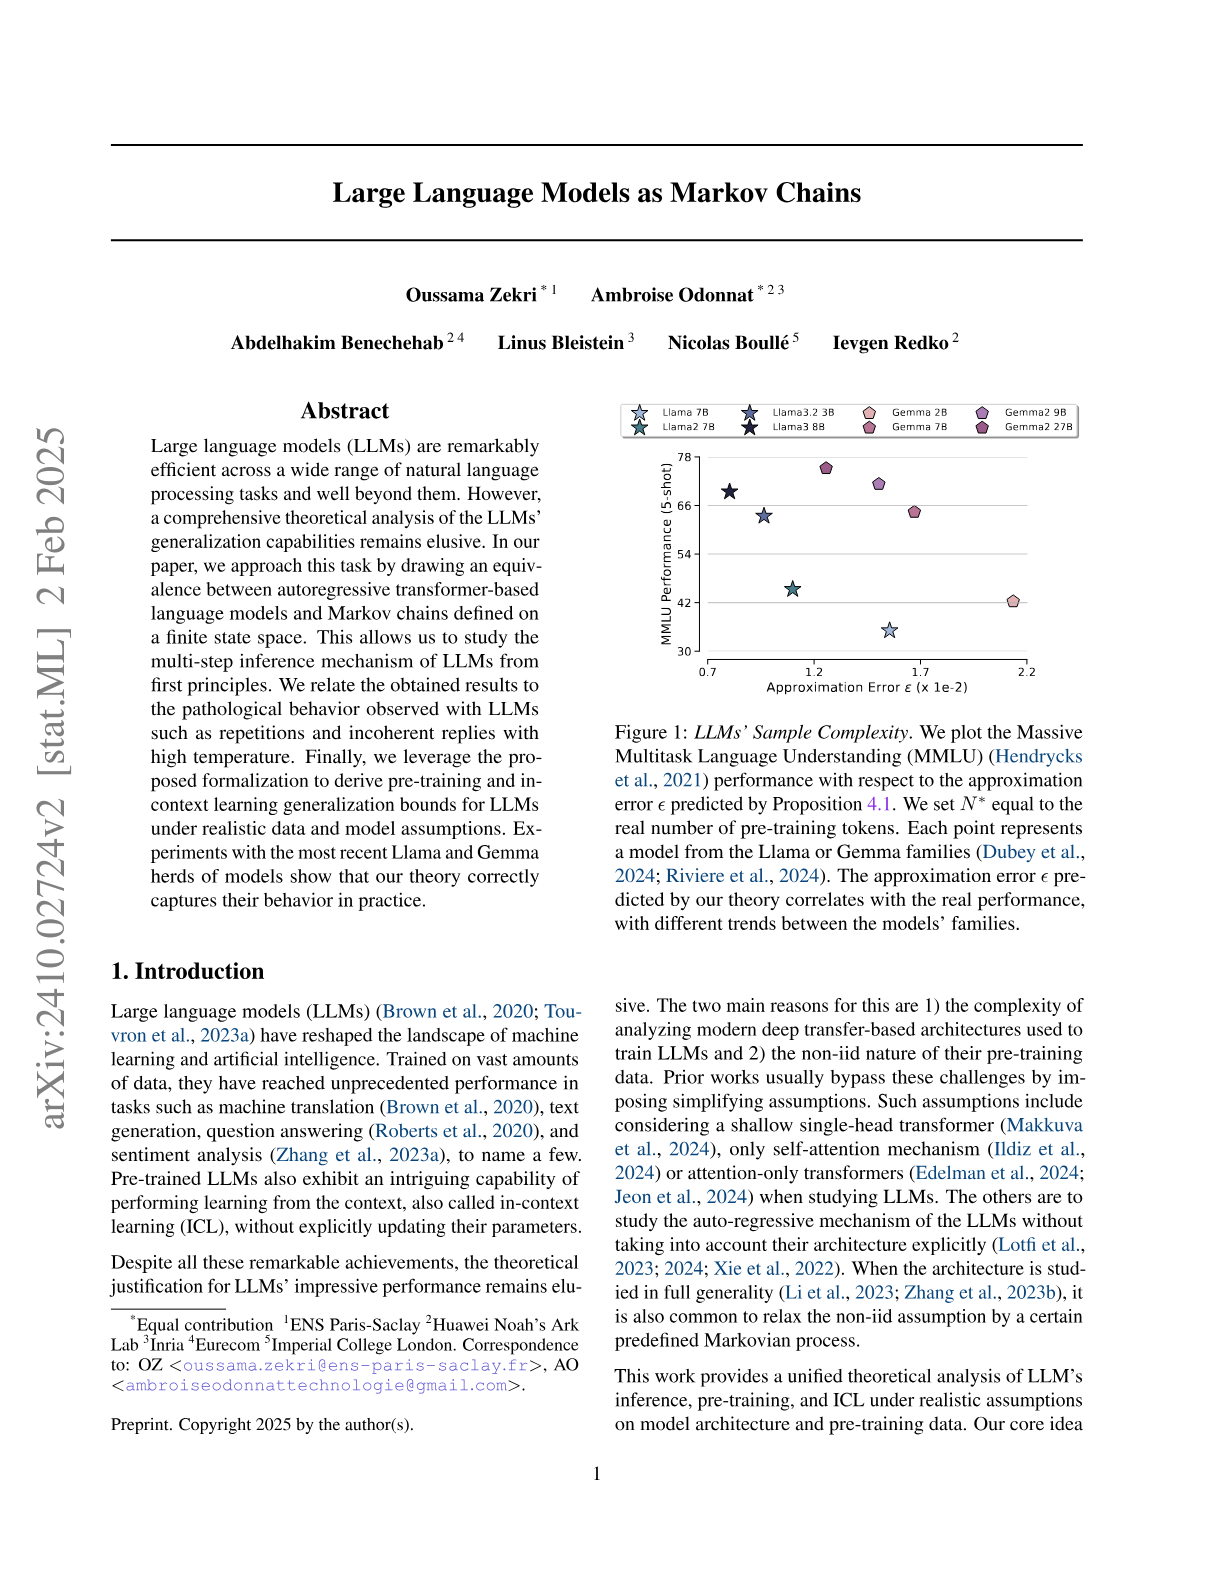
Large Language Models as Markov Chains
Hacker News threads
- Nov 2024Large Language Models as Markov Chains
- Oct 2024LLMs as Markov Chains
- Oct 2024Large Language Models as Markov Chains
- Jul 2025Problem solving using Markov chains (2007) [pdf]
- Sep 2025The wall confronting large language models
- Oct 2025BERT is just a single text diffusion step
- Nov 2025AI is a front for consolidation of resources and power
- Dec 2025Reflections on AI at the End of 2025
- May 2026Why AI Agents Cannot Change Software Systems
- Jun 2026How LLMs Work
- Sep 2026The Emergent Symbolic Structure of Artificial Neural Networks
- 28
Driven by Compression Progress: A Simple Principle Explains Essential Aspects of Subjective Beauty, Novelty, Surprise, Interestingness, Attention, Curiosity, Creativity, Art, Science, Music, Jokes
Hacker News threads
- Jan 2017Subjective Beauty, Novelty, Surprise, Interestingness, Attention, Curiosity,
- Aug 2019Driven by Compression Progress (Schmidhuber, 2008)
- Apr 2023Driven By Compression Progress (2008)
- Sep 2017Ask HN: CS as a philosophy
- Oct 2017Intelligence Reconsidered
- Mar 2021Information Is Surprise (2015)
- Mar 2021Hutter Prize
- Jul 2024Creativity fundamentally comes from memorization?
- Mar 2025ARC-AGI without pretraining
- Aug 2026Compression Is Prediction
- Sep 2026Asking Authors About Their Own Papers
- 29
Monolith: Real Time Recommendation System With Collisionless Embedding Table
Hacker News threads
- Nov 2022Monolith: Real time recommendation system with collisionless embedding table
- Nov 2022TikTok published an article on their recommendation system architecture
- Nov 2022Paper on 'Monolith: Real Time Recommendation System' by Bytedance Inc (TikTok)
- Dec 2022TikTok’s Secret Sauce
- Jan 2023Ask HN: Techwise, how did TikTok get so good?
- Feb 2023The secret sauce of TikTok’s recommendations
- Nov 2023X is changing its algorithm to highlight smaller accounts
- Dec 2024TikTok divestment law upheld by federal appeals court
- Jan 2025TikTok preparing for U.S. shut-off on Sunday
- May 2025You Don't Need Re-Ranking: Understanding the Superlinked Vector Layer
- Feb 2026TikTok's 'Addictive Design' Found to Be Illegal in Europe
- 30
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 31
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 32
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
Hacker News threads
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Oct 2024Cwal: Scripting Engine Without a Language
- Oct 2024Language is not essential for the cognitive processes that underlie thought
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Nov 2024OK, I can partly explain the LLM chess weirdness now
- Dec 2024GPT-5 is behind schedule
- Jan 202530% drop in O1-preview accuracy when Putnam problems are slightly variated
- Jun 2025The Illusion of Thinking: Strengths and limitations of reasoning models [pdf]
- Jul 2026Emily Bender Sets the Record Straight on "Stochastic Parrots"
- 33
Extracting books from production language models
Hacker News threads
- Jan 2026Extracting books from production language models
- Jan 2026Extracting books from production language models
- Jan 2026Extracting books from production language models (2026)
- Jan 2026Nvidia Contacted Anna's Archive to Access Books
- Feb 2026We tasked Opus 4.6 using agent teams to build a C Compiler
- Feb 2026Microsoft offers guide to pirating Harry Potter series for LLM training
- Mar 2026Relicensing with AI-Assisted Rewrite
- Mar 2026FSF Threatens Anthropic over Infringed Copyright: Share Your LLMs Freel
- Jun 2026Did Claude Increase Bugs in Rsync?
- Jul 2026Judge approves $1.5B Anthropic settlement for pirated books used to train Claude
- Sep 2026When did Google get so weird?
- 34
LLM in a flash: Efficient Large Language Model Inference with Limited Memory
Hacker News threads
- Jan 2024LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023Apple Announces LLM in a Flash: Efficient LLM Inference with Limited Memory
- Dec 2023Apple wants AI to run directly on its hardware instead of in the cloud
- Dec 2023Show HN: Emu2 – A Gemini-like open-source 37B Multimodal Model
- Dec 2023Ferret: A Multimodal Large Language Model
- Mar 2024Towards 1-bit Machine Learning Models
- Mar 2026Qwen3.5-397B at 4.74 tok/s using 5.9GB RAM
- Mar 2026iPhone 17 Pro Demonstrated Running a 400B LLM
- Aug 2026New Mac Studio with M5 Max and M5 Ultra
- 35
Levels of AGI for Operationalizing Progress on the Path to AGI
Hacker News threads
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023DeepMind on the Definitions and Levels of AGI
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023The deal to bring Sam Altman back to OpenAI has fallen apart
- Dec 2023Audiobox: Meta's new foundation research model for audio generation
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- May 2024Transformers Can Do Arithmetic with the Right Embeddings
- May 2025Evolving OpenAI's Structure
- May 2025John Carmack talk at Upper Bound 2025
- Jun 2025Seven replies to the viral Apple reasoning paper and why they fall short
- 36
Recursive Language Models
Hacker News threads
- Jan 2026Recursive Language Models
- Jan 2026General plug-and-play inference lib for RLMs
- Jan 2026Ask HN: What Are You Working On? (January 2026)
- Jan 2026MIT Researchers Destroy the Context Window Limit [video]
- Jan 2026Show HN: RLM-MCP Analyze Files in Claude Code Using MIT's recursive LM paper
- Feb 2026The path to ubiquitous AI (17k tokens/sec)
- Apr 2026RLM: LLMs to process arbitrarily long prompts with inference-time scaling (2025)
- Jun 2026
- Oct 2026Context Language Models
- 37
SequenceMatch: Imitation Learning for Autoregressive Sequence Modelling with Backtracking
Hacker News threads
- Jun 2023Giving LLM’s a <Backspace> Token
- Jun 2023LLM Powered Autonomous Agents
- Jun 2024AI Detectors Get It Wrong. Writers Are Being Fired Anyway
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Mercury: Commercial-scale diffusion language model
- Aug 2025Hacking Diffusion into Qwen3 for the Arc Challenge
- Sep 2025The wall confronting large language models
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 38
Computational Life: How Well-formed, Self-replicating Programs Emerge from Simple Interaction
Hacker News threads
- Jun 2024Computational Life: How self-replicating programs emerge from simple interaction
- Jun 2024Computational Life: How Self-Replicating Programs Emerge from Simple Interaction
- Jul 2024The data that powers AI is disappearing fast
- Jul 2024Google creates self-replicating life from digital 'primordial soup'
- Aug 2024Self-replicating programs emerge from simple interaction (in JavaScript)
- Sep 2024Brainfuck Enterprise Solutions
- Nov 2024OpenAI, Google and Anthropic are struggling to build more advanced AI
- Nov 2025Updated practice for review articles and position papers in ArXiv CS category
- Aug 2026The Computational Theory of Mind (2015)
- Aug 2026Computational Life Reactor (Based on Brainfuck)
- 39
Progress measures for grokking via mechanistic interpretability
Hacker News threads
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Apr 2023We need a much more sophisticated debate about AI
- Apr 2023Grokking in Julia
- May 2023Tiny Transformer trained for addition learns bizarre addition algorithm
- Aug 2023The Myth of AI Omniscience
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Jan 2026Claude is not a senior engineer (yet)
- 40
Accelerating Large Language Model Decoding with Speculative Sampling
Hacker News threads
- Feb 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Sep 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Mar 2023Facebook LLAMA is being openly distributed via torrents
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Run 100B+ language models at home, BitTorrent‑style
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Nov 2023Major Outage Across ChatGPT and API
- May 2024Better and Faster Large Language Models via Multi-Token Prediction
- Sep 2024AMD Unveils Its First Small Language Model AMD-135M
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- 41
Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
Hacker News threads
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Dec 2020Does GPT-2 Know Your Phone Number?
- Oct 2021A new link to an old model could crack the mystery of deep learning
- Mar 2022Deep learning is hitting a wall?
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Sep 2022Using GPT-3 to pathfind in random graphs
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- Oct 2023When Gradient Descent Is a Kernel Method
- 42
SLIDE : In Defense of Smart Algorithms over Hardware Acceleration for Large-Scale Deep Learning Systems
Hacker News threads
- Mar 2020Smart Algorithms beat Hardware Acceleration for Large-Scale Deep Learning
- Mar 2019In Defense of Smart Algorithms over Hardware Acceleration for Deep Learning
- Mar 2020Slide: In Defense of Smart Algorithms over Hardware Accelerated Deep Learning
- Mar 2020Deep Learning Breakthrough Sees One Xeon Destroying 8x Nvidia Tesla V100 GPUs
- Dec 2020Researchers propose faster, more efficient alternatives to backpropagation
- Apr 2021CPU-based algorithm trains deep neural nets up to 15 times faster than top GPU
- Apr 2021CPU-based algorithm trains deep neural nets up to 15 times faster than top GPU
- Aug 2021pHash – An open source perceptual hash library (2013)
- Oct 2021New features coming in Julia 1.7
- Feb 2022Two sparsities are better than one: Performance of sparse-sparse networks
- Feb 2025(Ab)using general search algorithms on dynamic optimization problems (2023)
- 43
The Matrix Calculus You Need For Deep Learning
Hacker News threads
- Apr 2021The matrix calculus you need for deep learning (2018)
- Feb 2018The Matrix Calculus You Need For Deep Learning
- Jan 2020The Matrix Calculus You Need for Deep Learning
- Aug 2018Learning Math for Machine Learning
- Oct 2021Ask HN: As a professional, does it worth it to learn the math behind NN?
- Apr 2023Matrix Calculus: Calculate derivatives of matrices
- Jul 2023The Matrix Calculus You Need for Deep Learning
- Jan 2024Calculus on Computational Graphs: Backpropagation (2015)
- Sep 2024Ask HN: Calculus Refresher for AI/ML?
- Mar 2025Matrix Calculus (For Machine Learning and Beyond)
- 44
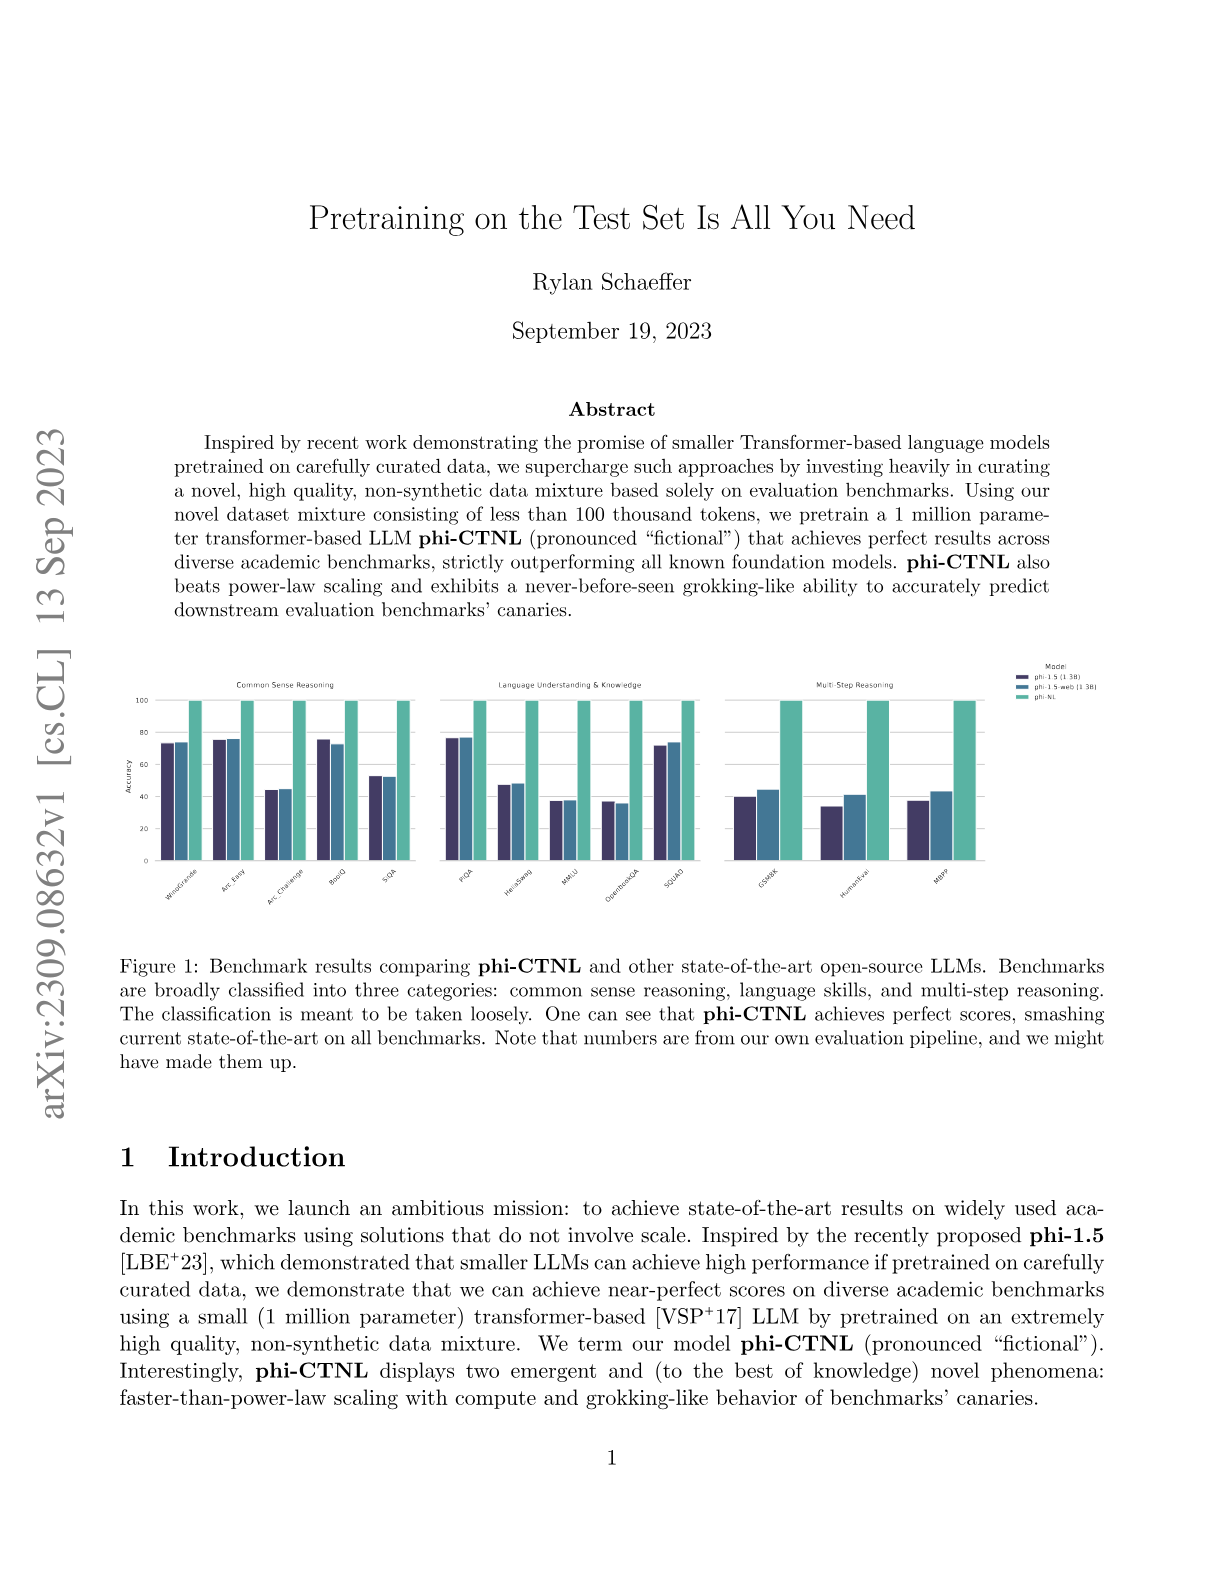
Pretraining on the Test Set Is All You Need
Hacker News threads
- Oct 2023Pretraining on test set is all you need
- Feb 2025Pretraining on the Test Set Is All You Need
- Oct 2023Pretraining on the Test Set Is All You Need
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023Grok
- Mar 2024Claude 3 model family
- Apr 2024The "it" in AI models is the dataset
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Jul 2024Fitting an elephant with four non-zero parameters
- Feb 2025Grok3 Launch [video]
- 45
Knowledge Representation in Bicategories of Relations
Hacker News threads
- Jun 2017A computational linguistic farce in three acts
- Nov 2017Modeling Science as a Directed Graph
- May 2018The Logical Disaster of Null
- Jul 2018Kialo – a platform for rational debate
- Dec 2018A Formal Apology for Metaphysics [pdf]
- Aug 2019Software Architecture Guide
- Feb 2020Contextualise: Manage your knowledge
- 46
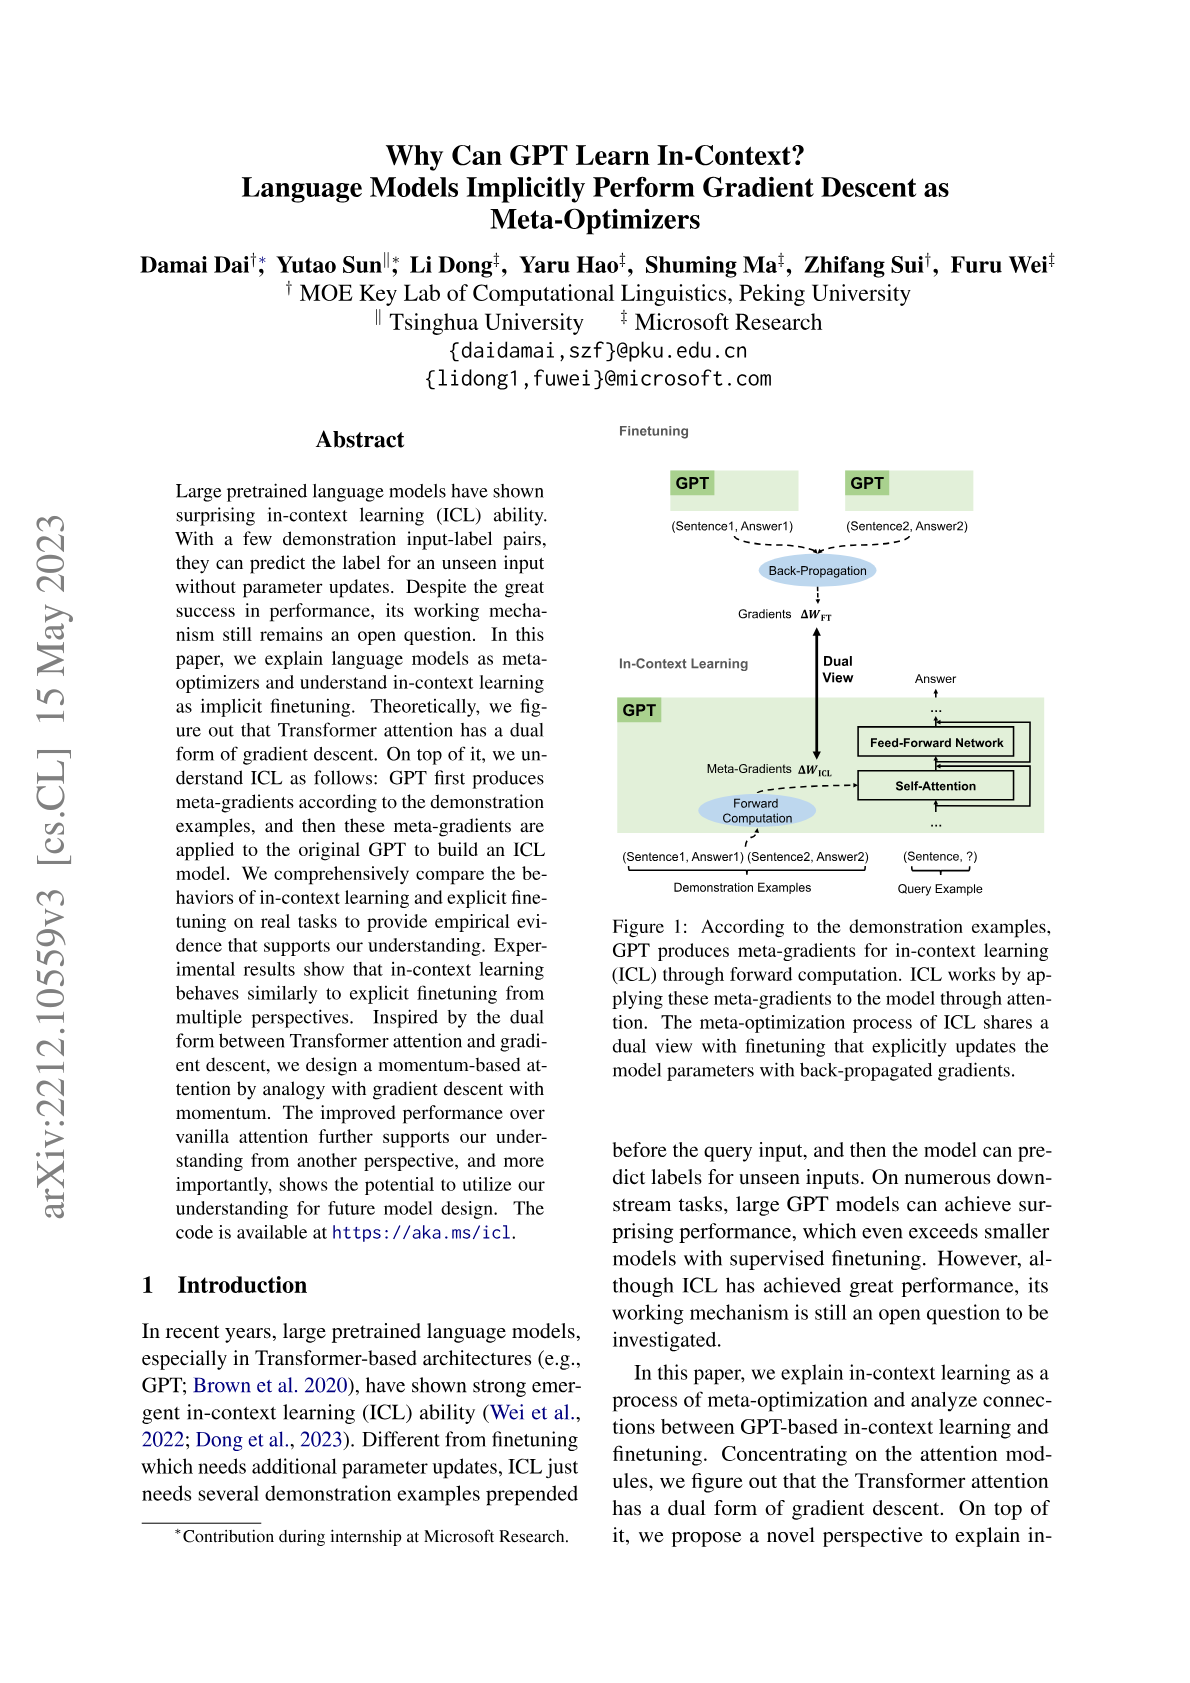
Why Can GPT Learn In-Context? Language Models Implicitly Perform Gradient Descent as Meta-Optimizers
Hacker News threads
- Dec 2022Why Can GPT Learn In-Context? Language Models Perform Gradient Descent
- Jan 2023The Expanding Dark Forest and Generative AI
- Feb 2023GPT in 60 Lines of NumPy
- Feb 2023To Build Truly Intelligent Machines, Teach Them Cause and Effect
- Mar 2023Large language models are having their Stable Diffusion moment
- Mar 2023GPT-4 Designed a Programming Language
- Mar 2023OK, it’s time to freak out about AI
- May 2023Chatbots Don’t Know What Stuff Isn’t
- Jul 2024Reasoning in Large Language Models: A Geometric Perspective
- 47
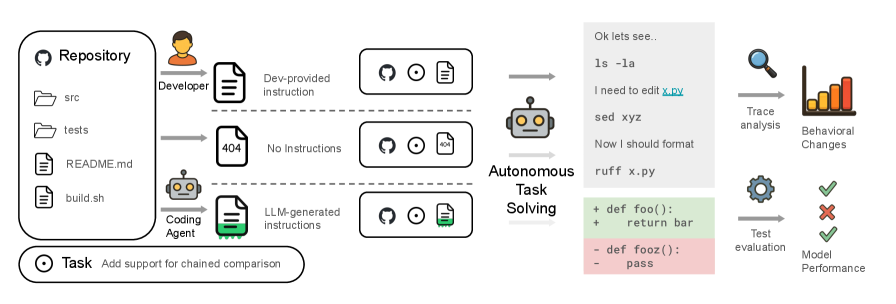
Evaluating AGENTS.md: Are Repository-Level Context Files Helpful for Coding Agents?
Hacker News threads
- Feb 2026Evaluating AGENTS.md: are they helpful for coding agents?
- Jun 2026Do Agents.md Files Help Coding Agents?
- Feb 2026Writing code is cheap now
- Feb 2026Show HN: Agent Swarm – Multi-agent self-learning teams (OSS)
- Feb 2026Show HN: I got tired of syncing Claude/Gemini/AGENTS.md and .cursorrules
- Mar 2026New Research Reassesses the Value of Agents.md Files for AI Coding
- Mar 2026Anatomy of the .claude/ Folder
- Jun 2026Uber's $1,500/Month AI Limit Is a Useful Signal for AI Tool Pricing
- Jun 2026Uber's $1,500/Month AI Limit Is a Useful Signal for AI Tool Pricing
- Oct 2026I paid people to try and follow my README
- 48
Winning Gold at IMO 2025 with a Model-Agnostic Verification-and-Refinement Pipeline
Hacker News threads
- Jul 2025Gemini 2.5 Pro Capable of Winning Gold at IMO 2025
- Jul 2025Gemini 2.5 Pro Capable of Winning Gold at IMO 2025 with Prompting
- Jul 2025Gemini 2.5 Pro Capable of Winning Gold at IMO 2025
- Jul 2025Gemini with Deep Think achieves gold-medal standard at the IMO
- Aug 2025GPT-5
- Aug 2025Claim: GPT-5-pro can prove new interesting mathematics
- Sep 2025DeepMind and OpenAI win gold at ICPC
- Oct 2025Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Oct 2025Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Nov 2025Yann LeCun to depart Meta and launch AI startup focused on 'world models'
- Jan 20262025: The Year in LLMs
- 49
Technical Report on the Pangram AI-Generated Text Classifier
Hacker News threads
- Mar 2024Technical Report on the Checkfor.ai AI-Generated Text Classifier
- Jul 2026Technical Report on the Pangram AI-Generated Text Classifier (2024)
- Oct 2024AI Slop Is Flooding Medium
- Nov 2025Open-source Zig book
- Jan 2026Amazon axes 16,000 jobs as it pushes AI and efficiency
- Jan 2026For most flagged articles, nearly every cited sentence failed verification
- Feb 2026Show HN: Showboat and Rodney, so agents can demo what they've built
- Apr 2026Ask HN: How do systems (or people) detect when a text is written by an LLM
- Jul 2026The bottleneck might be the air in the room
- Jul 2026Detecting LLM-Generated Texts with "Classical" Machine Learning
- 50
Linear Transformers Are Secretly Fast Weight Programmers
Hacker News threads
- Oct 2022Meta Learning Backpropagation and Improving It (2020)
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Sep 2023HN thread 37367951
- Sep 2023I made a transformer by hand (no training)
- Oct 2023Ring Attention with Blockwise Transformers for Near-Infinite Context
- Oct 2023How Transformers Work
- Feb 2024Neural Network Diffusion
- Sep 2026Transformers Explained Visually
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.