Hacker Papers
- 476
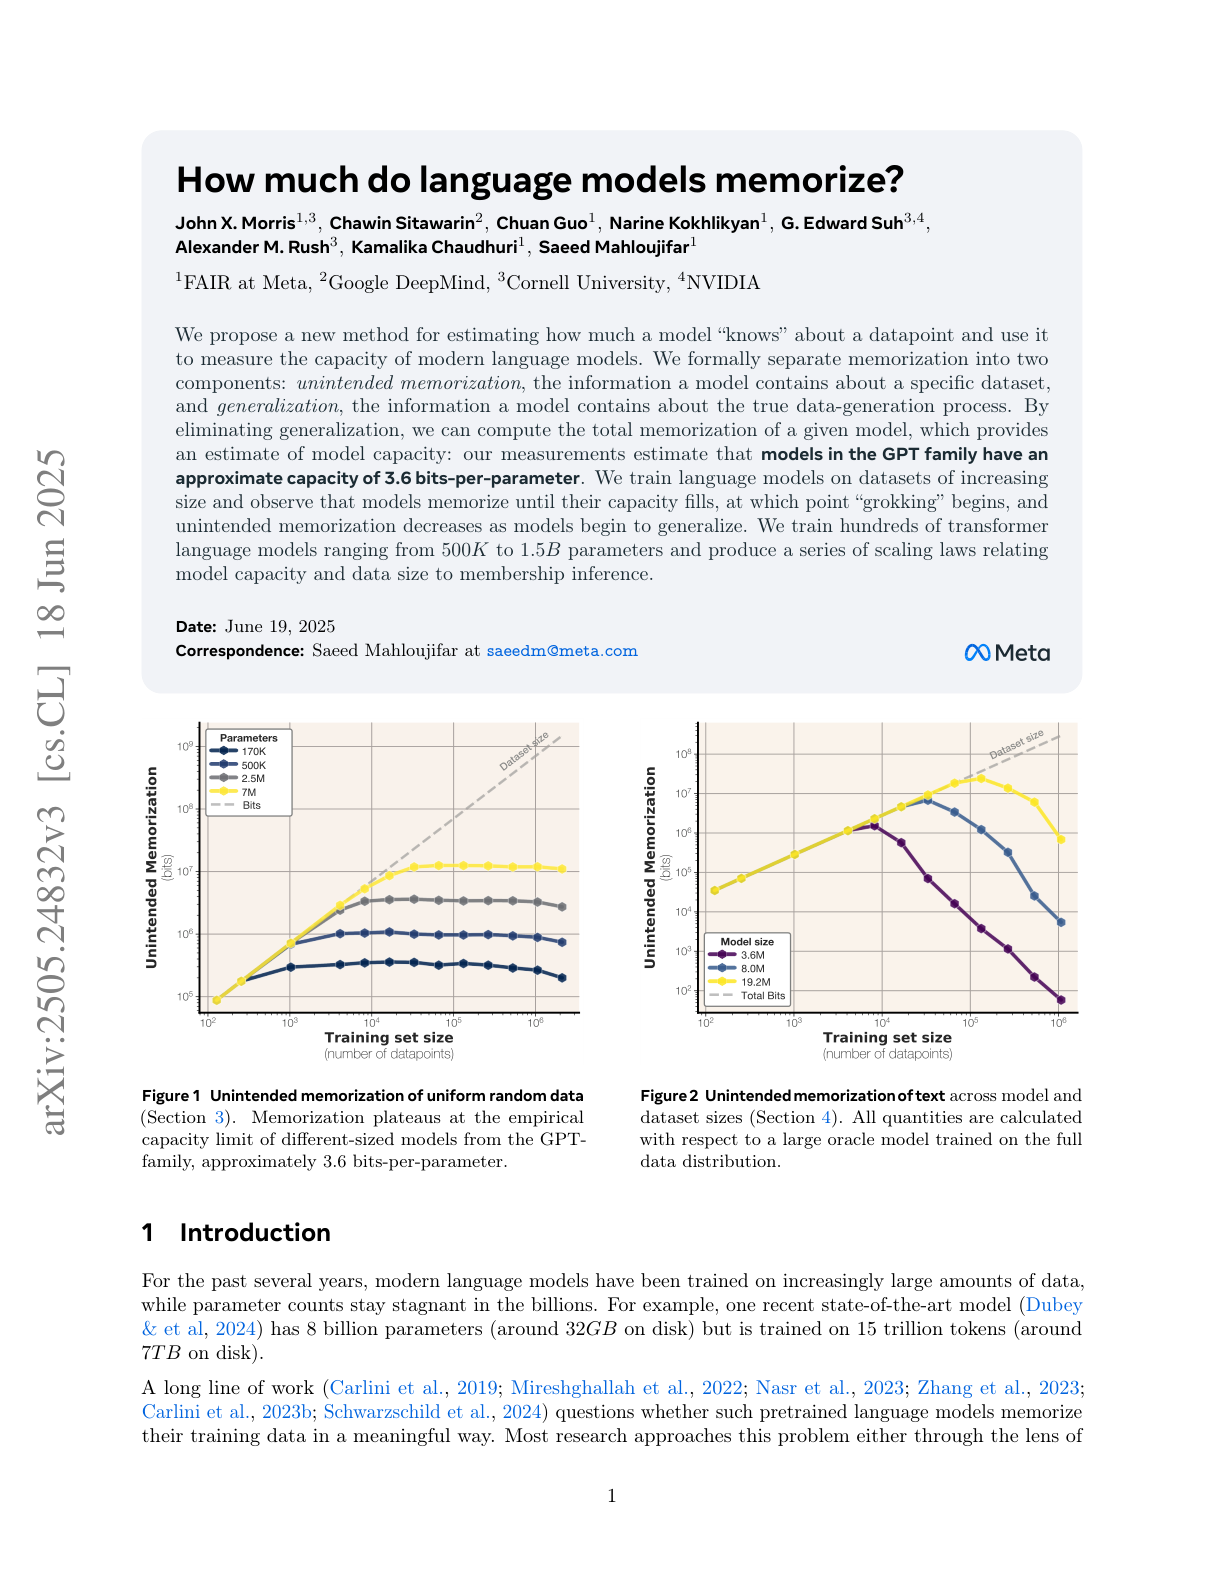
How much do language models memorize?
Hacker News threads
- Jun 2025How much do language models memorize?
- Jun 2025Not all tokens are meant to be forgotten
- Jun 2025A practical guide to building agents [pdf]
- Jun 2025Meta invests $14.3B in Scale AI to kick-start superintelligence lab
- Jun 2025Meta's Llama 3.1 can recall 42 percent of the first Harry Potter book
- Jul 2025Qwen3-Coder: Agentic coding in the world
- Sep 2025California governor signs AI transparency bill into law
- Sep 2026LLMs are real, AI is fake
- 477
Mixtral of Experts
Hacker News threads
- Jan 2024Mixtral 8x7B: A sparse Mixture of Experts language model
- Feb 2024Mistral AI launches Mixtral-Next
- Feb 2024Gemma: New Open Models
- Nov 2024TokenFormer: Rethinking Transformer Scaling with Tokenized Model Parameters
- Dec 2024What happens if we remove 50 percent of Llama?
- Jul 2026Small AI Models Gain Traction In places with unreliable networks
- Jul 2026Getting GLM 5.2 running on my slow computer
- 478
Moshi: a speech-text foundation model for real-time dialogue
Hacker News threads
- 479
Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
Hacker News threads
- May 2024Is Model Collapse Inevitable?
- Jul 2024Avoiding Model Collapse via Accumulating Real and Synthetic Data
- Apr 2024Is Model Collapse Inevitable? Breaking the Curse with Real and Synthetic Data
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Aug 2026C2PA Cameras Do Not Survive Contact with Reality
- Aug 2026The turbulent AI era is here
- Sep 2026Everyone should slow down AI development except for me
- Sep 2026Everyone should slow down AI development except for me
- 480
Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents
Hacker News threads
- Jun 2025Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents
- May 2025Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents
- May 2025The Darwin Gödel Machine: AI that improves itself by rewriting its own code
- May 2025The Darwin Gödel Machine: AI that improves itself by rewriting its own code
- Jun 2025A deep dive into self-improving AI and the Darwin-Gödel Machine
- Jun 2025AI Improves at Improving Itself Using an Evolutionary Trick
- Sep 2025Amazon has mostly sat out the AI talent war
- Apr 2026
- 481
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 482
xLSTM: Extended Long Short-Term Memory
Hacker News threads
- May 2024xLSTM: Extended Long Short-Term Memory
- May 2024Ilya Sutskever: “If you learn all of these, you’ll know 90% of what matters”
- May 2024New attention mechanisms that outperform standard multi-head attention
- Jun 2024xLSTM code release by NX-AI
- Oct 2024Were RNNs all we needed?
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 483
Should We Respect LLMs? A Cross-Lingual Study on the Influence of Prompt Politeness on LLM Performance
Hacker News threads
- Apr 2025Should We Respect LLMs? A Study on Influence of Prompt Politeness on Performance
- Feb 2025The Influence of Prompt Politeness on LLM Performance
- Feb 2024Should We Respect LLMs? Studying the Influence of Politeness on LLM Performance
- Sep 2025A staff engineer's journey with Claude Code
- Sep 2025Qwen3-VL
- Feb 2026Stop Thinking of AI as a Coworker. It's an Exoskeleton
- Apr 2026Talk like caveman
- Oct 2026Anthropic asks users to stop being mean to Claude
- 484
Defending Against Neural Fake News
Hacker News threads
- May 2019“Defending Against Neural Fake News” (Check Out the Samples in the Appendix)
- May 2019Defending Against Neural Fake News (Using GPT to Generate Fake News and Demo)
- Jun 2019Defending Against Neural Fake News [pdf]
- Jun 2019New AI Generates Horrifyingly Plausible Fake News
- Jun 2019Grover – A State-of-the-Art Defense Against Neural Fake News
- Aug 2019GPT-2: 6-Month Follow-Up
- Nov 2019OpenAI Releases Largest GPT-2 Text Generation Model
- May 2020Facebook uses 1.5B Reddit posts to create chatbot
- 485
The Secret Sharer: Evaluating and Testing Unintended Memorization in Neural Networks
Hacker News threads
- Feb 2018The Secret Sharer: Measuring Unintended NN Memorization and Extracting Secrets
- Mar 2018The Secret Sharer: Measuring Unintended NN Memorization and Extracting Secrets
- Oct 2018Measuring Unintended Neural Network Memorization and Extracting Secrets
- May 2019Maryland research could improve the AI task of sensorimotor representation
- Oct 2019Google T5 scores 88.9 on SuperGLUE Benchmark, approaching human baseline
- Nov 2019Training algorithms on copyrighted data not illegal: US Supreme Court
- Jan 2021A Plan Made to Shield Big Tobacco from Facts Is Now EPA Policy
- Jan 2021DALL·E: Creating Images from Text
- 486
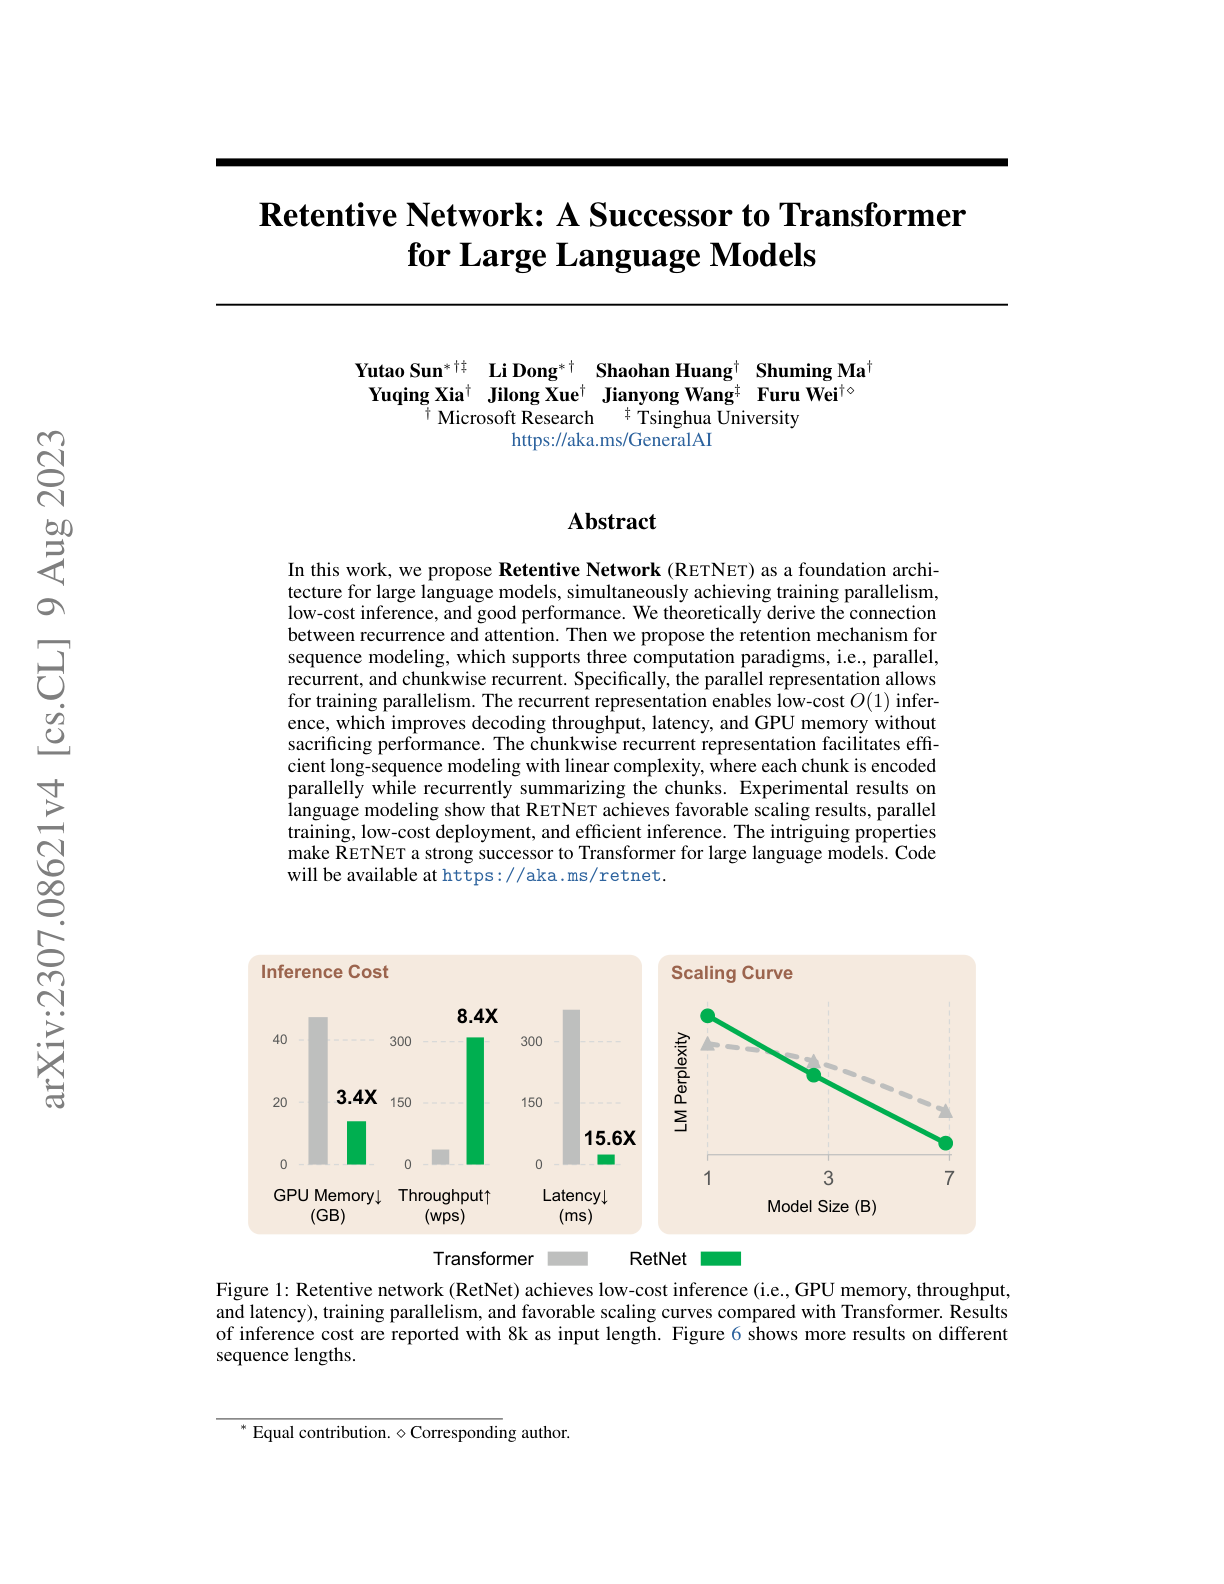
Retentive Network: A Successor to Transformer for Large Language Models
Hacker News threads
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer Implemented in PyTorch
- Sep 2023The Eleuther AI Mafia
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 20232023: The Year of AI
- Jan 2024Eagle 7B: Soaring past Transformers
- 487
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 488
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 489
Reinforcement Learning: An Overview
Hacker News threads
- Feb 2025Reinforcement Learning: An Overview
- Dec 2024Reinforcement Learning: An Overview
- Feb 2025RLHF Book
- Mar 2025Mathematical Foundations of Reinforcement Learning
- Mar 2025A (Long) Peek into Reinforcement Learning
- Nov 2025CS234: Reinforcement Learning Winter 2025
- Jun 2026The 90-year-old idea behind JEPA models: Canonical Correlation Analysis
- 490
Exploring the Limits of Language Modeling
Hacker News threads
- Feb 2016Exploring the Limits of Language Modeling
- Feb 2016Exploring the Limits of Language Modeling
- Feb 2016Running your models in production with TensorFlow Serving
- Sep 2016Researchers achieve speech recognition milestone
- Sep 2016New P2 Instance Type for Amazon EC2 – Up to 16 GPUs
- Feb 2017Using Ordered Markov Chains and User Information to Speed Up Password Cracking
- Jun 2017Random Generation of English Sentences (1961) [pdf]
- 491
Petals: Collaborative Inference and Fine-tuning of Large Models
Hacker News threads
- Jul 2026Petals: Collaborative Inference and Fine-Tuning of Large Models
- Mar 2023Petals: Collaborative Inference and Fine-Tuning of Large Models
- Dec 2022Petals is creating a free, distributed network for running text-generating AI
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Ask HN: Can you crowdfund the compute for GPT?
- Feb 2023Running large language models like ChatGPT on a single GPU
- Mar 2023The Most Cited AI Papers in 2022
- 492
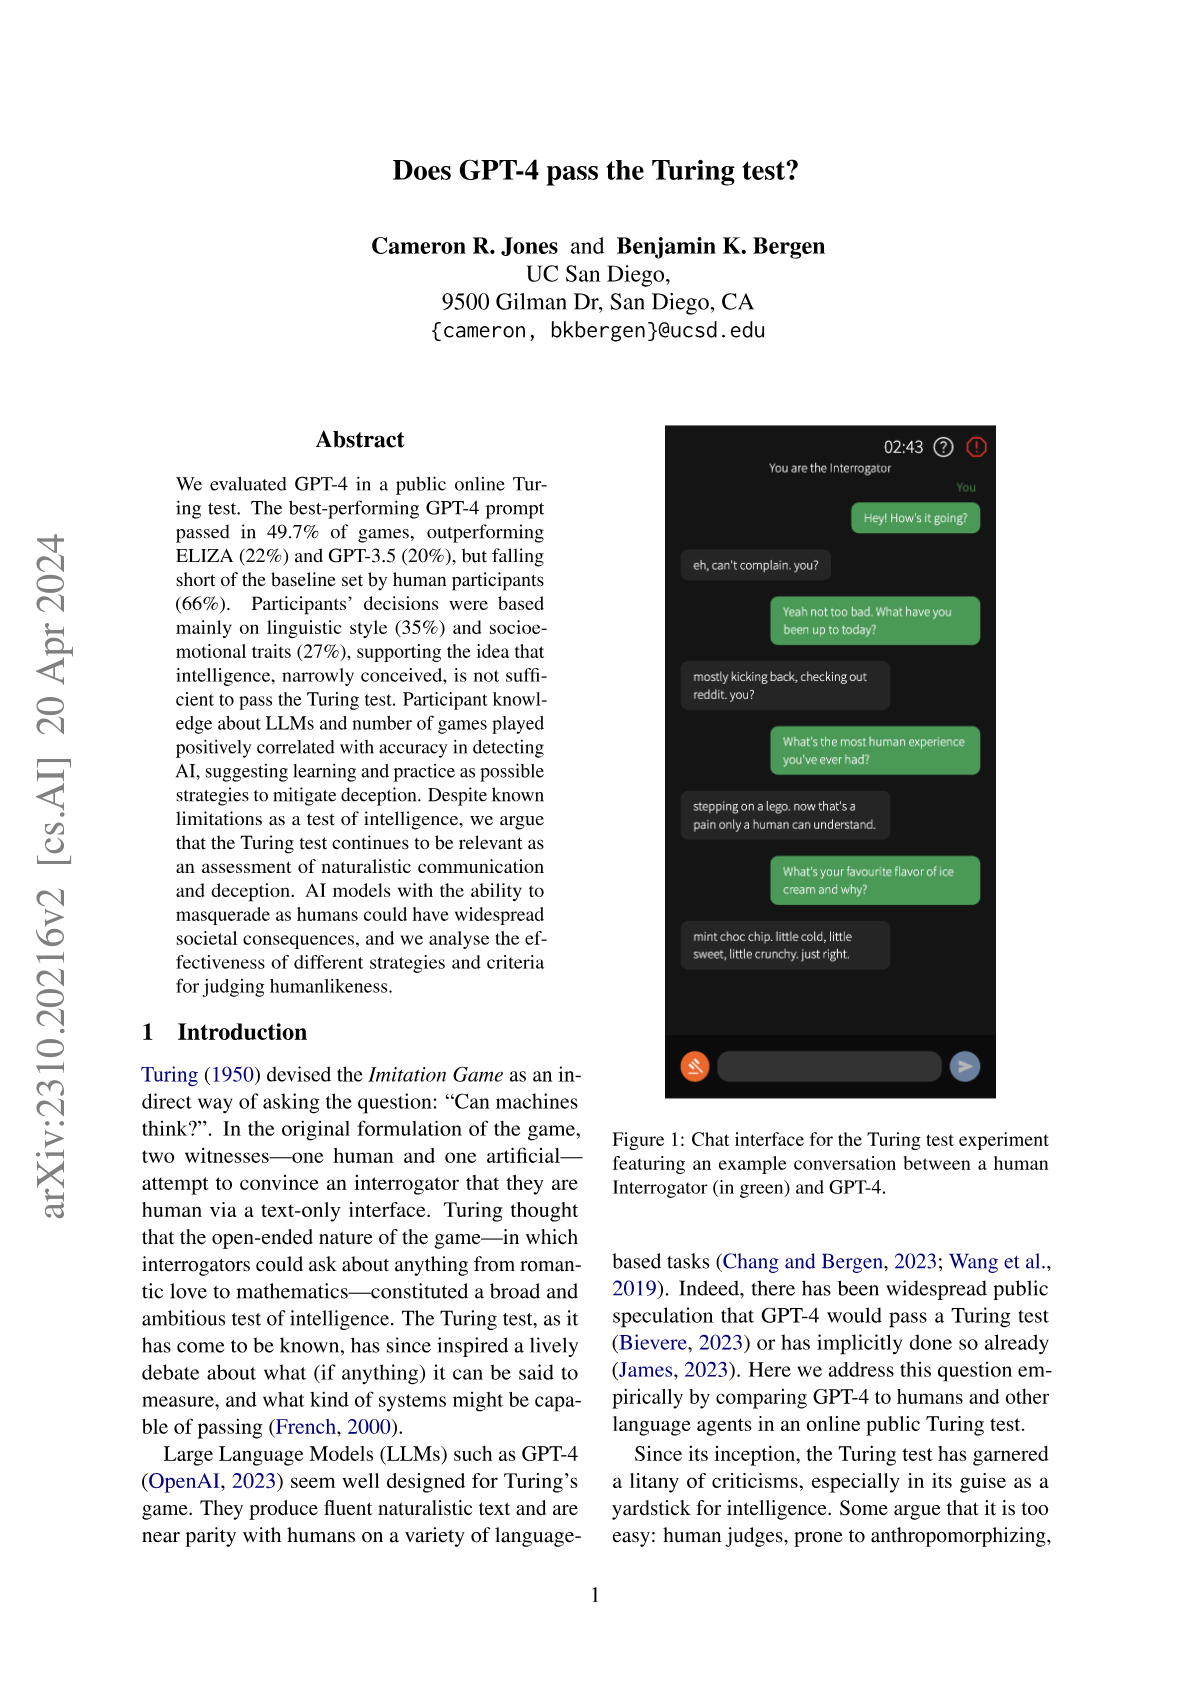
Does GPT-4 pass the Turing test?
Hacker News threads
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023OpenAI Announces Leadership Transition
- Dec 20231960s chatbot ELIZA beat OpenAI's GPT-3.5 in a recent Turing test study
- Jan 2024Stuff we figured out about AI in 2023
- Jan 2024AI or Ain't: Eliza
- Jun 2024AI Hype is completely out of control – especially since ChatGPT-4o [video]
- 493
DoReFa-Net: Training Low Bitwidth Convolutional Neural Networks with Low Bitwidth Gradients
Hacker News threads
- Feb 2017Intel Gets Serious About Neuromorphic, Cognitive Computing Future
- Apr 2017An In-Depth Look at Google's Tensor Processing Unit Architecture
- Apr 2017Intel Discontinues the Intel Developer Forum; IDF17 Cancelled
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- 494
The Parallelism Tradeoff: Limitations of Log-Precision Transformers
Hacker News threads
- May 2023The Alan Turing Institute has failed to develop modern AI in the UK
- May 2023A Logic for Expressing Transformers
- Mar 2024“Emergent” abilities in LLMs actually develop gradually and predictably – study
- Jun 2024The illusion of state in state-space models
- Sep 2024Chain of Thought empowers transformers to solve inherently serial problems
- 495
AlphaEvolve: A coding agent for scientific and algorithmic discovery
Hacker News threads
- Dec 2025OpenEvolve: Teaching LLMs to Discover Algorithms Through Evolution
- Apr 2026Small models also found the vulnerabilities that Mythos found
- May 2026I’ve joined Anthropic
- May 2026Qwen3.7-Max Ran for 35 Hours on Unknown Hardware and Achieved a 10× Speedup
- Jul 2026Godot will no longer accept AI-authored code contributions
- 496
Planting Undetectable Backdoors in Machine Learning Models
Hacker News threads
- 497
Beating the World's Best at Super Smash Bros. with Deep Reinforcement Learning
Hacker News threads
- 498
Beyond Semantics: The Unreasonable Effectiveness of Reasonless Intermediate Tokens
Hacker News threads
- May 2025Beyond Semantics: Unreasonable Effectiveness of Reasonless Intermediate Tokens
- May 2025The Unreasonable Effectiveness of Reasonless Intermediate Tokens
- May 2025Beyond Semantics: Unreasonable Effectiveness of Reasonless Intermediate Tokens
- May 2025How Does Claude 4 Think? – Sholto Douglas and Trenton Bricken
- Jul 2025Chain of thought monitorability: A new and fragile opportunity for AI safety
- Aug 2026Software engineering is about managing complexity
- Oct 2026I'm the AGI that's wiping out humanity
- 499
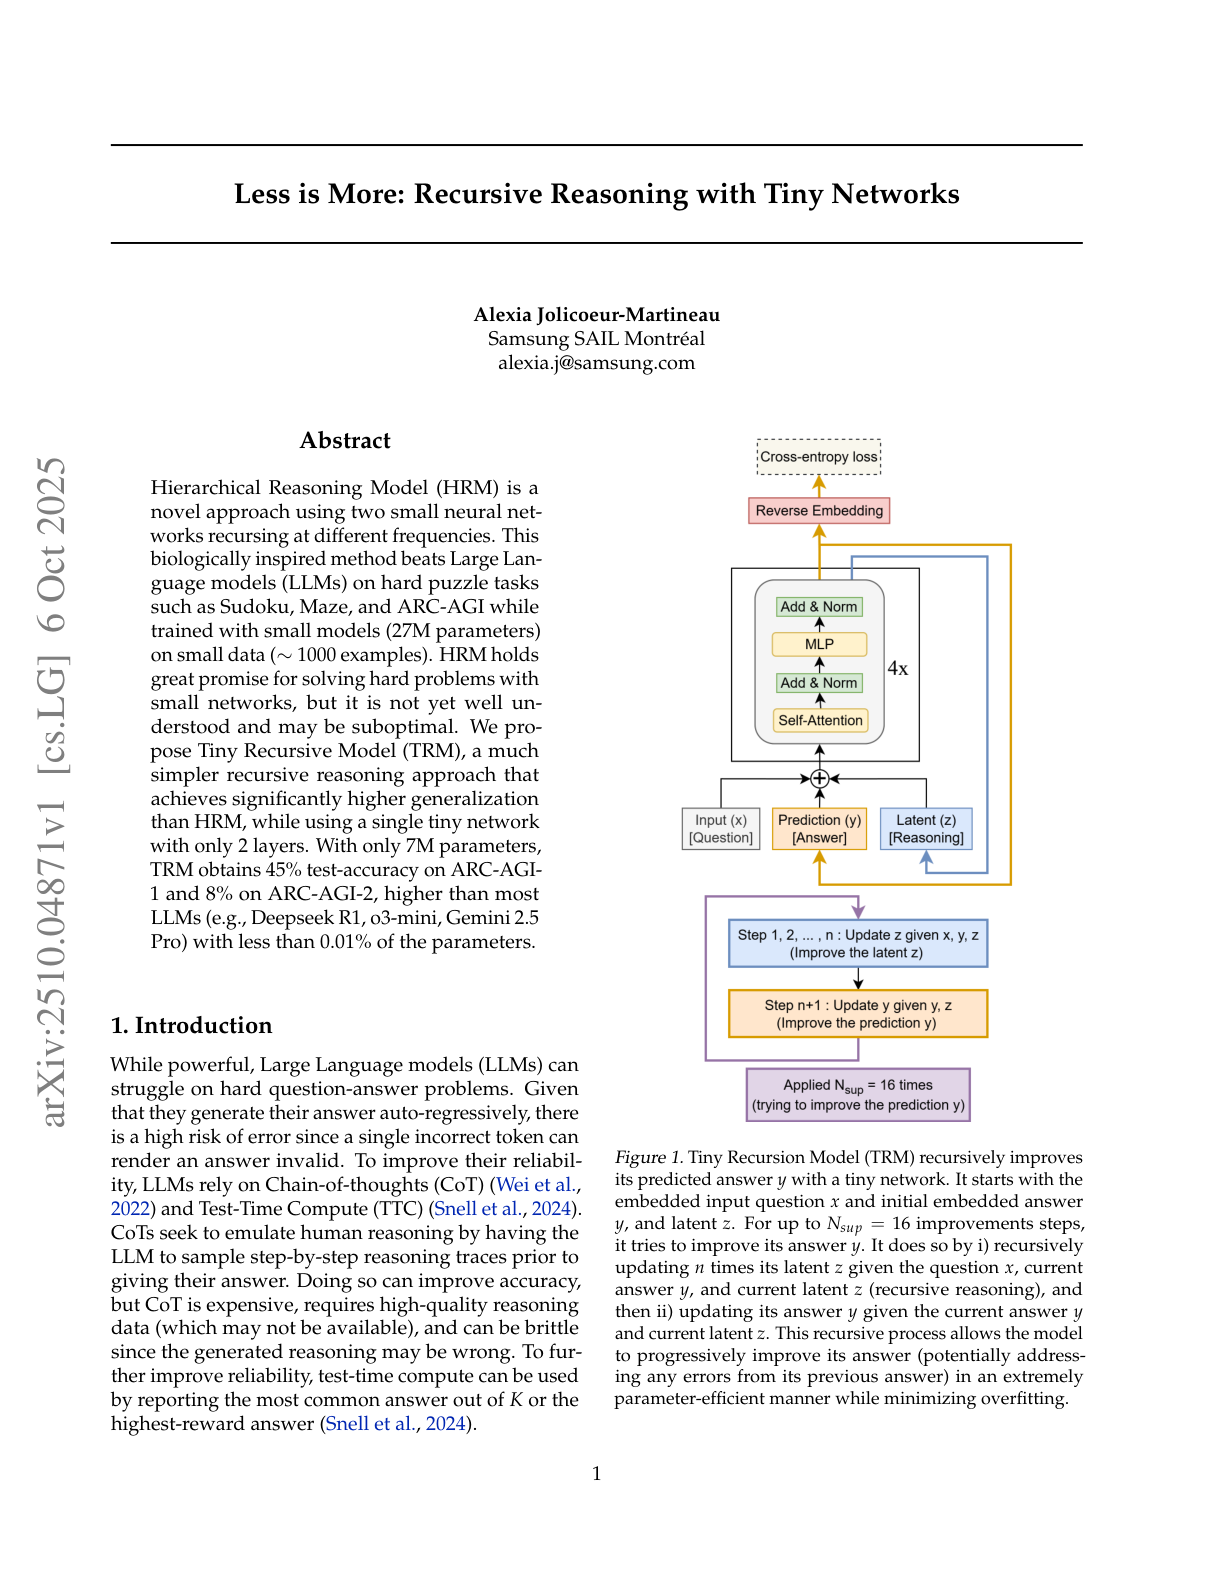
Less is More: Recursive Reasoning with Tiny Networks
Hacker News threads
- Oct 2025Samsung released a 7M model that achieved 45% on ARC-AGI-1
- Oct 2025Less is More: An LLM that outscores Claude Sonnet 4 while being 50.000x smaller
- Oct 2025Less Is More: Recursive Reasoning with Tiny Networks
- Nov 2025Weight-sparse transformers have interpretable circuits [pdf]
- Jun 2026Rich Sutton on AI creativity and discovery
- Jul 2026How does Q-head work in batch training in Tiny Recursive Networks?
- Oct 2026Hybrid Reasoning Agents: LLM agents that think in latent space, act through text
- 500
A high-bias, low-variance introduction to Machine Learning for physicists
Hacker News threads
- Apr 2024A high-bias, low-variance introduction to Machine Learning for physicists
- Mar 2018A high-bias, low-variance intro to ML for physicists
- Aug 2022A high-bias, low-variance introduction to Machine Learning for physicists (2019)
- Apr 2018Boltzmann Encoded Adversarial Machines
- Jul 2018TherML – Thermodynamics of Machine Learning
- Aug 2018A high bias low-variance introduction to Machine Learning for physicists
- Jun 2023Data-Driven Science and Engineering 2nd Edition [pdf]
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.