Hacker Papers
- 476
Binarized Neural Networks: Training Deep Neural Networks with Weights and Activations Constrained to +1 or -1
Hacker News threads
- Sep 2016Stacked Approximated Regression Machine: A Simple Deep Learning Approach
- Oct 2016Intel will add deep-learning instructions to its processors
- Feb 2017Intel Gets Serious About Neuromorphic, Cognitive Computing Future
- Sep 2017Nonlinear Computation in Deep Linear Networks
- Oct 2018MIT AGI: Conversation with Yoshua Bengio [video]
- Nov 2019Deep Learning and Its Implications for Computer Architecture and Chip Design
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- 477
DoReFa-Net: Training Low Bitwidth Convolutional Neural Networks with Low Bitwidth Gradients
Hacker News threads
- Feb 2017Intel Gets Serious About Neuromorphic, Cognitive Computing Future
- Apr 2017An In-Depth Look at Google's Tensor Processing Unit Architecture
- Apr 2017Intel Discontinues the Intel Developer Forum; IDF17 Cancelled
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- 478
The RefinedWeb Dataset for Falcon LLM: Outperforming Curated Corpora with Web Data, and Web Data Only
Hacker News threads
- 479
Ologs: a categorical framework for knowledge representation
Hacker News threads
- 480
Character-Aware Models Improve Visual Text Rendering
Hacker News threads
- Dec 2022Improving Text Rendering in Image Generation Models
- Dec 2022What ChatGPT Can't Do
- Feb 2023Illusion Diffusion: Optical Illusions Using Stable Diffusion
- Apr 2023A Baby GPT
- Apr 2023Stability AI releases DeepFloyd IF, a powerful text-to-image model
- Oct 2023DALL-E 3: Improving image generation with better captions [pdf]
- Mar 2024Ask HN: Why can't image generation models spell?
- 481
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Hacker News threads
- 482
Neural Ordinary Differential Equations
Hacker News threads
- Dec 2018Neural Ordinary Differential Equations
- Dec 2018Neural Ordinary Differential Equations
- Jun 2018Polynomial Regression as an Alternative to Neural Nets
- Dec 2018Building a Language and Compiler for Machine Learning
- Jan 2019Tensor Considered Harmful Part 2
- Jan 2019Deep Learning State of the Art (2019) [video]
- Mar 2019‘A Swiss cheese-like material’ that can solve equations
- Sep 2019Deep Learning for Symbolic Mathematics
- Mar 2024Where is Noether's principle in machine learning?
- Mar 2024On the Double-Slit Experiment and Quantum Interference in the Wolfram Model (2020)
- 483
Vectorized and performance-portable Quicksort
Hacker News threads
- Feb 2024Vectorized and performance-portable Quicksort (2022)
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Apple M2 Die Shot and Architecture Analysis – Big Cost Increase and A15 Based IP
- Dec 2022Sorting with SIMD
- Jan 2023Efficient and performance-portable vector software
- Mar 2024JPEG XL and the Pareto Front
- 484
Deep Neural Networks as Gaussian Processes
Hacker News threads
- Jan 2018Using Self-Organizing Maps to Solve the Traveling Salesman Problem
- Jul 2018Gaussian Processes for Machine Learning (2010)
- Jan 2020U.S. government limits exports of artificial intelligence software
- Mar 2021Understanding deep learning requires rethinking generalization
- Jun 2023Any Deep ReLU Network Is Shallow
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- 485
Efficiently Scaling Transformer Inference
Hacker News threads
- 486
Visualizing and Understanding Recurrent Networks
Hacker News threads
- Jan 2016Visualizing and understanding recurrent networks
- Jun 2015Visualizing and Understanding Recurrent Networks
- Jul 2017Interpreting neurons in an LSTM network
- Jul 2019Show HN: Autocomplete Python with Deep Learning
- Jan 2021Show HN: Ecco – See what your NLP language model is “thinking”
- Feb 2024Hi everyone yes, I left OpenAI yesterday
- 487
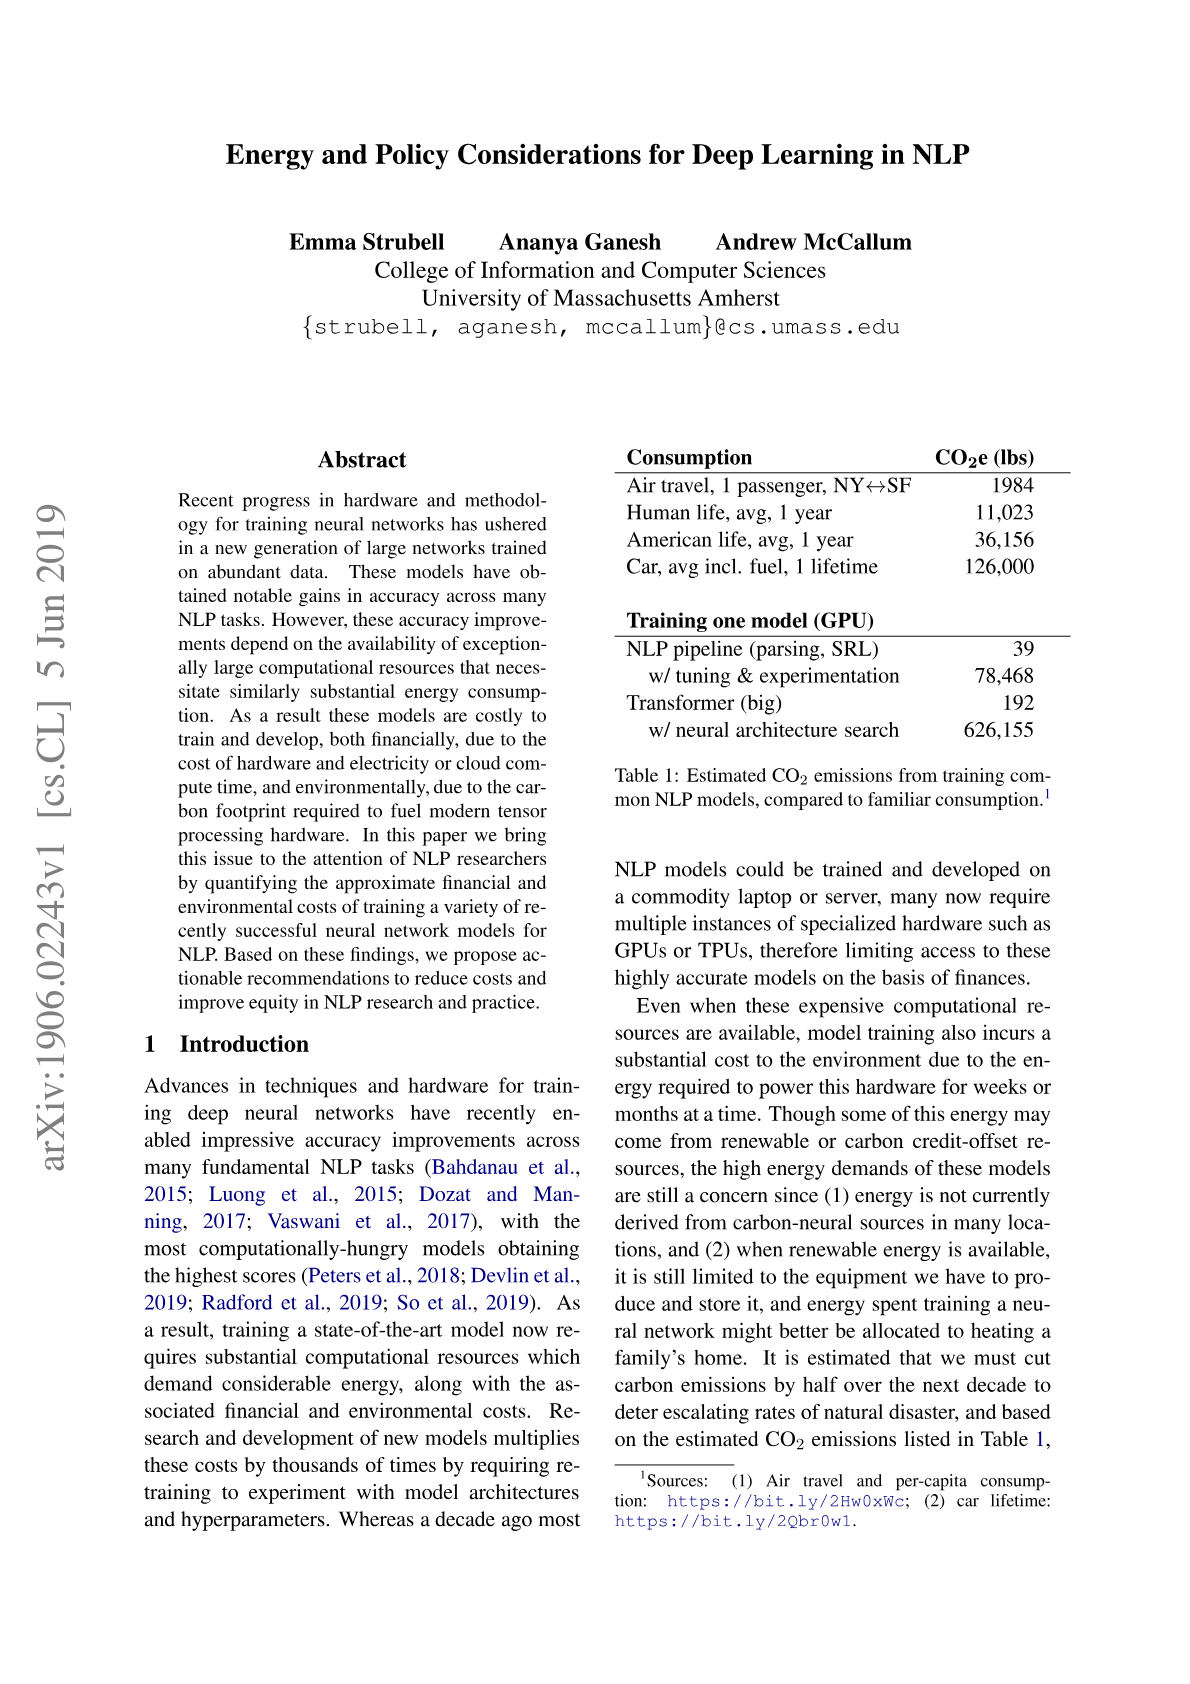
Energy and Policy Considerations for Deep Learning in NLP
Hacker News threads
- Jun 2019Energy and Policy Considerations for Deep Learning in NLP [pdf]
- Oct 2019Energy and Policy Considerations for Deep Learning in NLP
- Jun 2019Energy and Policy Considerations for Deep Learning in NLP [pdf]
- Sep 2019The U.S. economy is growing and using less and less stuff to do so
- Oct 2019Green AI
- Sep 2021Deep Learning's Diminishing Returns
- Oct 2021Small Language Models Are Also Few-Shot Learners
- May 2023Timnit Gebru on her sacking by Google, AI’s dangers and big tech’s biases
- May 2023Timnit Gebru on her sacking by Google, AI’s dangers and big tech’s biases
- Feb 2024I don't want anything your AI generates
- 488
A Monte Carlo AIXI Approximation
Hacker News threads
- Mar 2010The Single Sign On
- Nov 2018The impossibility of intelligence explosion
- Jan 2024Learning Universal Predictors
- 489
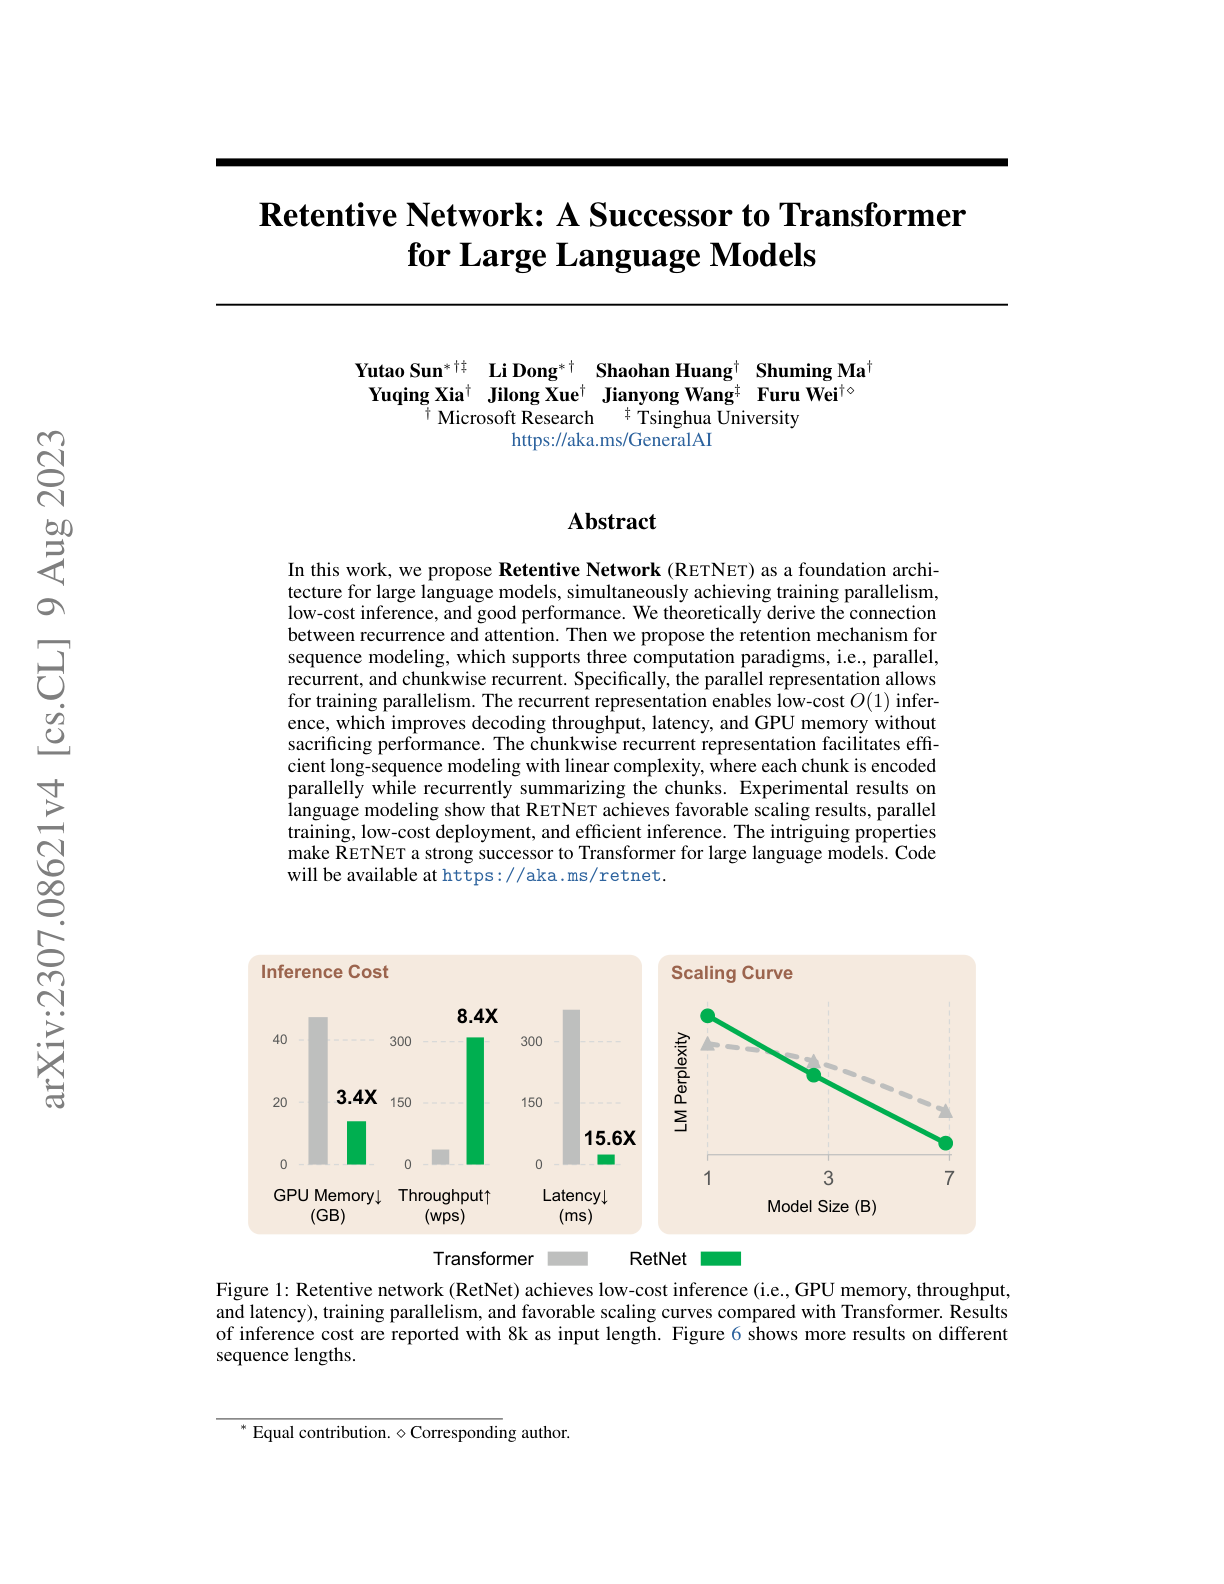
Retentive Network: A Successor to Transformer for Large Language Models
Hacker News threads
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer Implemented in PyTorch
- Sep 2023The Eleuther AI Mafia
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 20232023: The Year of AI
- Jan 2024Eagle 7B: Soaring past Transformers
- 490
Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
Hacker News threads
- Sep 2020Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
- Sep 2020Exploring Alternative Rule Sets in Chess with AlphaZero
- Sep 2020Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
- Dec 2020Ideal Chess – drop chess perfected?
- Aug 2021Fairer Chess: A Reversal of Two Opening Moves in Chess Creates Balance
- Nov 2022Acquisition of chess knowledge in AlphaZero
- Jan 2024I realized chess pieces can be redesigned to be geometric attack directions
- 491
Playing Atari with Deep Reinforcement Learning
Hacker News threads
- Oct 2014Playing Atari with Deep Reinforcement Learning [pdf]
- Jan 2015Playing Atari with Deep Reinforcement Learning (2013) [pdf]
- Jan 2014Deep Mind's neural networks play 7 Atari 2600 games with more skill than a human
- Jan 2014Google to Buy Artificial Intelligence Startup DeepMind for $400M
- Jan 2014Applying Artificial Intelligence to Nintendo Tetris
- Dec 2014Google's Intelligence Designer
- Jan 2015Mario Lives: An AI for creating a living and conversing agent [video]
- Feb 2015Human-level control through deep reinforcement learning
- May 2016End to End Learning for Self-Driving Cars [pdf]
- Jan 2017CS 294 Deep Reinforcement Learning, Spring 2017
- Jan 2024Self-Rewarding Language Models
- 492
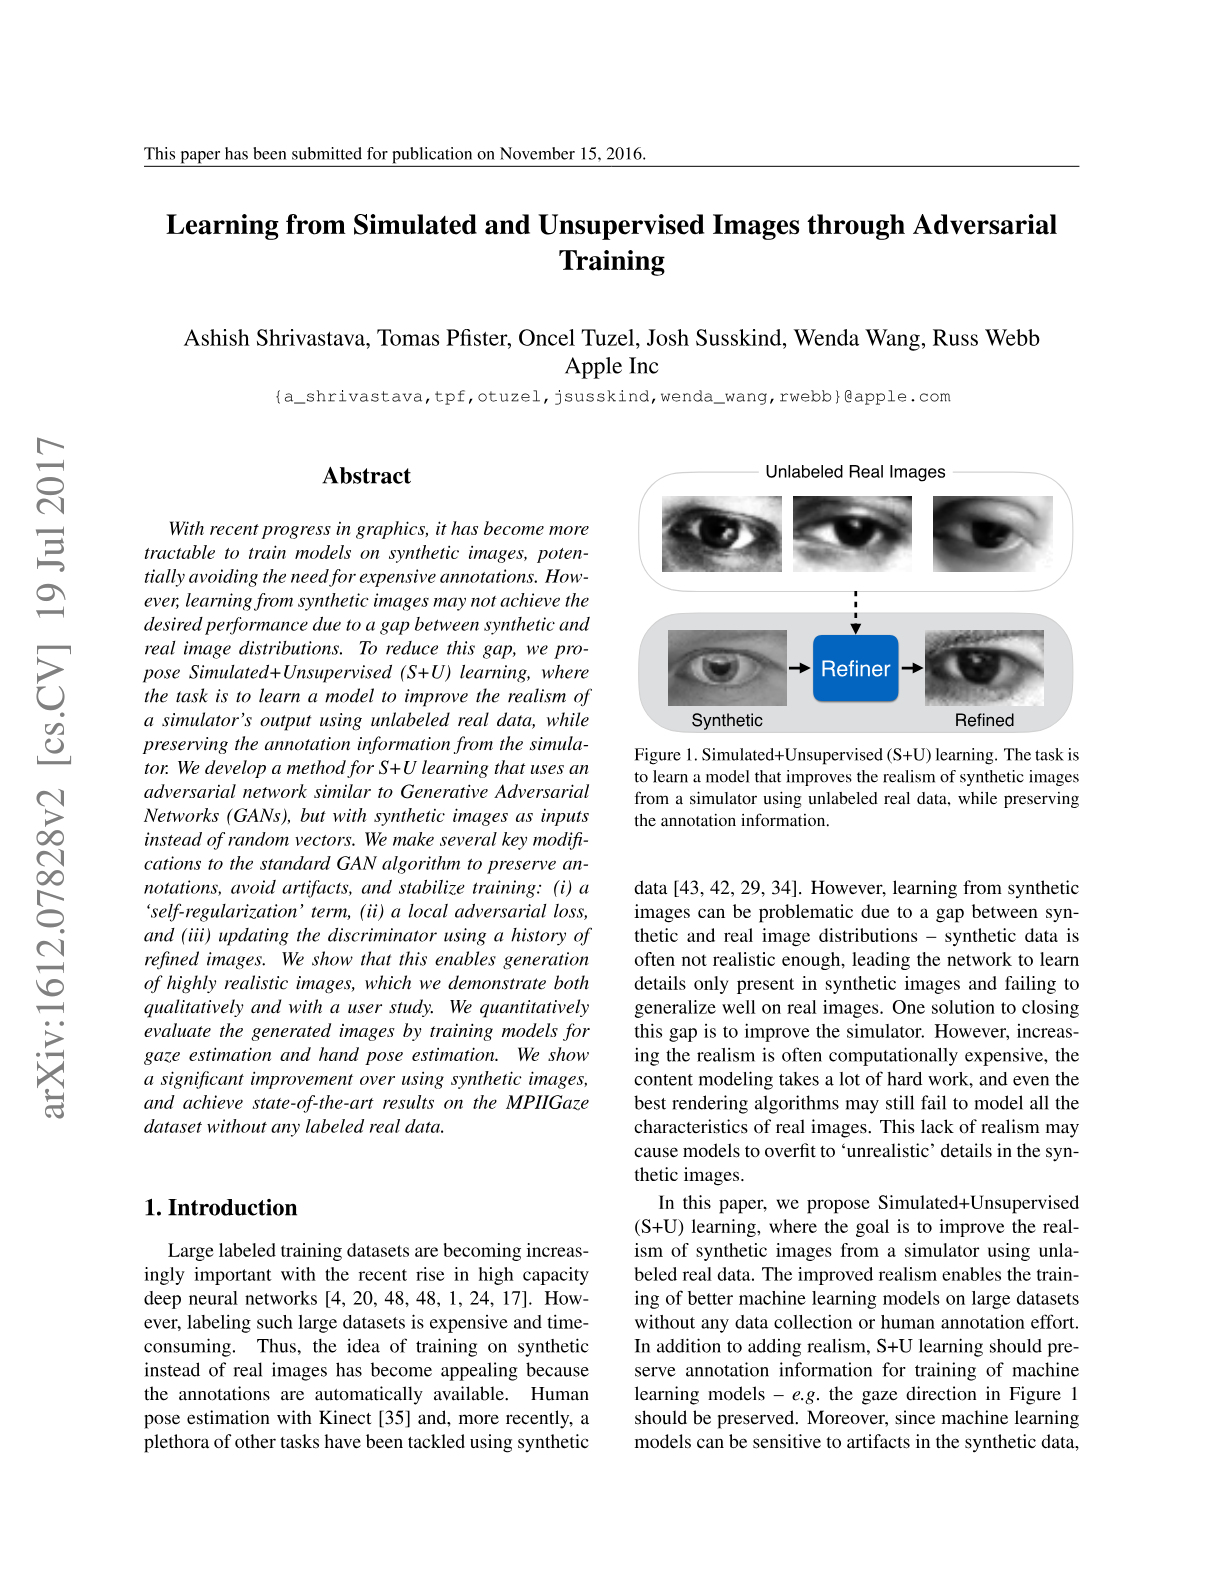
Learning from Simulated and Unsupervised Images through Adversarial Training
Hacker News threads
- Dec 2016Learning from Simulated and Unsupervised Images through Adversarial Training
- Dec 2016Apple Publishes Its First Artificial Intelligence Paper
- Jul 2017Apple Machine Learning Journal
- Jul 2017Apple Machine Learning Journal
- Jul 2017Apple Machine Learning Journal
- Jul 2017CVPR 2017 Best Paper Awards
- Nov 2017Closing the Simulation-to-Reality Gap for Deep Robotic Learning
- May 2020Oculus: Hand Tracking Updates
- Jan 2024Barcoding Bees (2020)
- 493
Neural Tangent Kernel: Convergence and Generalization in Neural Networks
Hacker News threads
- Jan 2023Neural Tangent Kernel: Convergence and Generalization in Neural Networks
- Nov 2019Wide Neural Networks of Any Architecture Are Gaussian Processes
- Aug 2020Cellular Automata as Convolutional Neural Networks
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Feb 2021Gradient Descent Models Are Kernel Machines
- Mar 2021Understanding deep learning requires rethinking generalization
- Jan 2024Transformers Are Multi-State RNNs
- 494
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 495
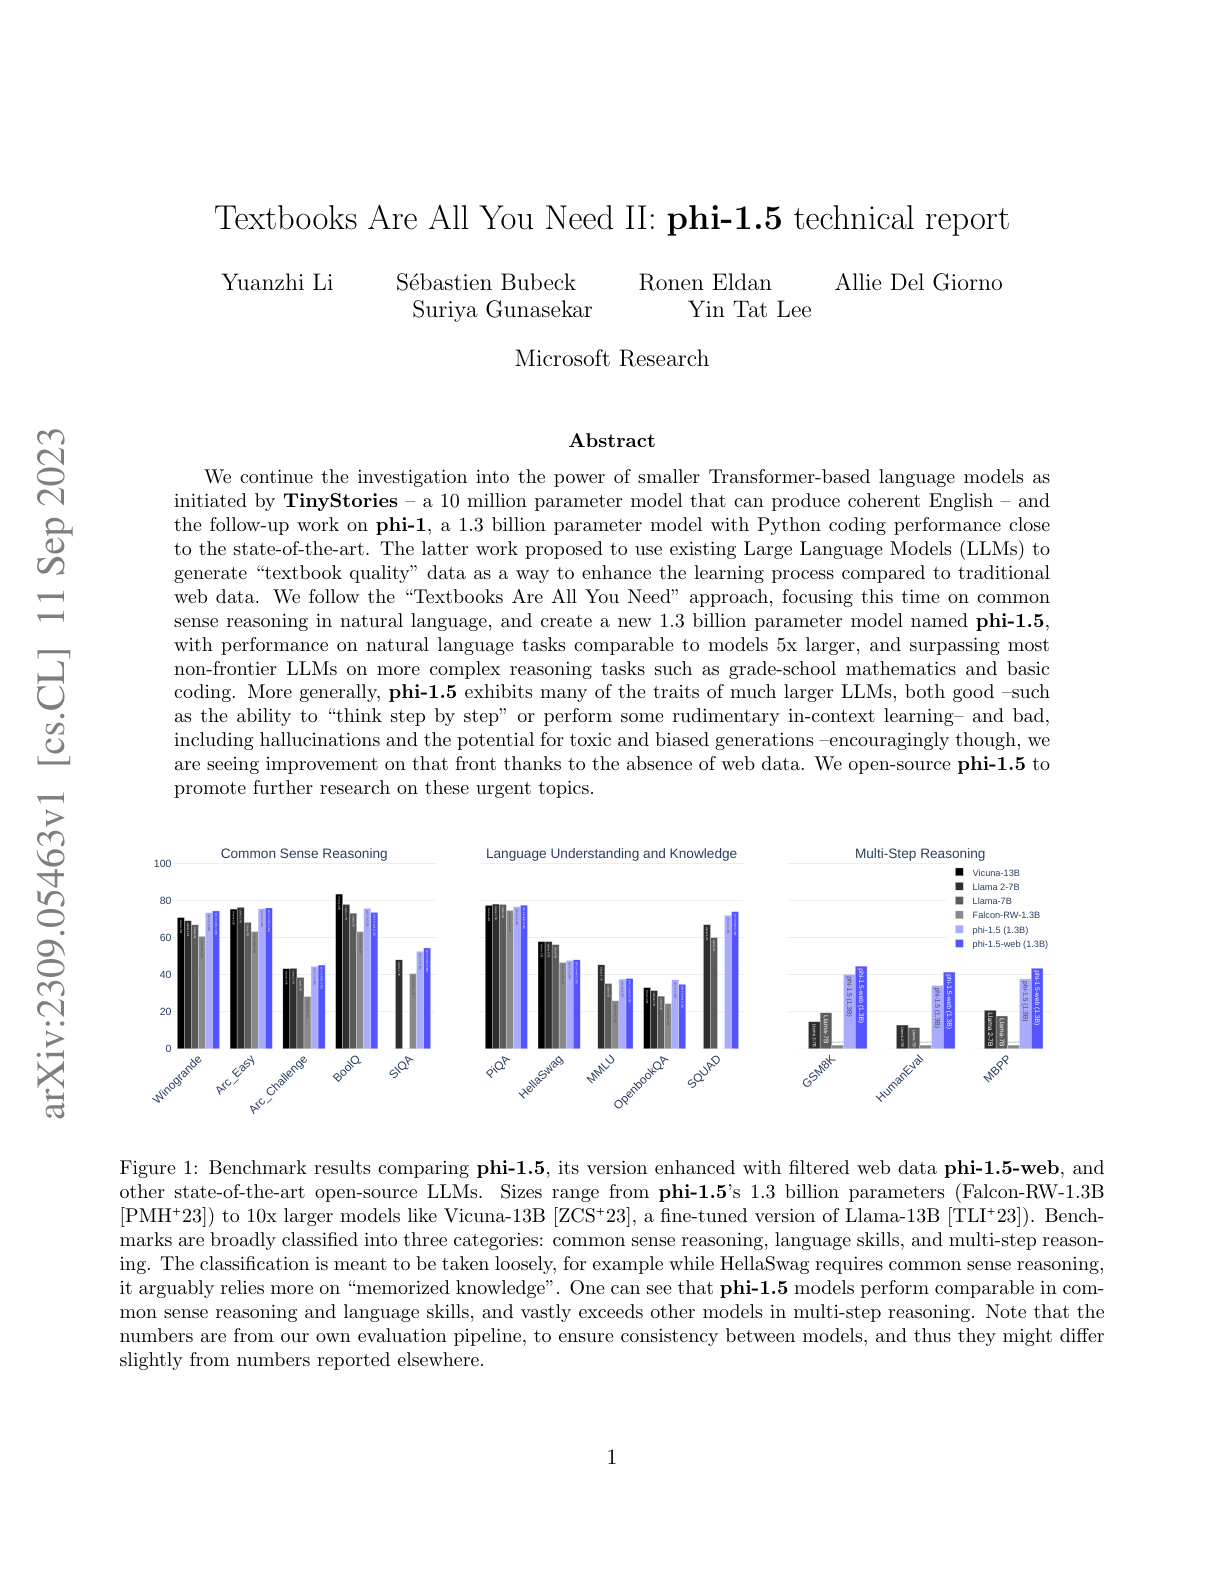
Textbooks Are All You Need II: phi-1.5 technical report
Hacker News threads
- Sep 2023The tide is shifting: 1.3B outperforms 7B Llama 2
- Sep 2023Textbooks Are All You Need II: phi-1.5 technical report
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023MonadGPT – What would have happened if ChatGPT was invented in the 17th century?
- Jan 2024Microsoft Phi-2 model changes licence to MIT
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- Jan 2024A Philosophical Introduction to Language Models
- 496
Tighter Bounds on the Expressivity of Transformer Encoders
Hacker News threads
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- Jun 2023Thinking Like Transformers (pdf)
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Turing Complete Transformers: Two Transformers Are More Powerful Than One
- 497
Formalization, Mechanization and Automation of Gödel's Proof of God's Existence
Hacker News threads
- 498
Towards Biologically Plausible Deep Learning
Hacker News threads
- Sep 2015Towards Biologically Plausible Deep Learning
- Dec 2016Backpropagation is a leaky abstraction
- Dec 2016Backpropagation is a leaky abstraction
- Sep 2017Where will artificial general intelligence come from?
- Oct 2017A Theory of Sequence Memory in Neocortex
- Dec 2018Why Robot Brains Need Symbols
- Jul 2019Microsoft is investing $1B in OpenAI
- Jan 2024Understand how transformers work by demystifying the math behind them
- 499
Delving Deep into Rectifiers: Surpassing Human-Level Performance on ImageNet Classification
Hacker News threads
- Feb 2015Surpassing Human-Level Performance on ImageNet Classification [pdf]
- Feb 2015Surpassing Human-Level Performance on ImageNet Classification
- Feb 2015Batch Normalization: Accelerating Deep Network Training [pdf]
- Dec 2015Microsoft Research wins image recognition competition
- Oct 2016All Tesla Cars Being Produced Now Have Full Self-Driving Hardware
- May 2020Explainable Deep Learning: A Field Guide for the Uninitiated
- Dec 2023Direct initialization of transformers using larger pretrained ones
- 500
Student of Games: A unified learning algorithm for both perfect and imperfect information games
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.