Hacker Papers
- 501
Predictive Inequity in Object Detection
Hacker News threads
- Mar 2019Predictive Inequity in Object Detection
- Mar 2019Autonomous Cars Can't Recognise Pedestrians with Darker Skin Tones
- Mar 2019Self-driving cars may be more likely to hit you if you have dark skin
- Apr 2019MIT Researcher Exposing Bias in Facial Recognition Tech Triggers Amazon’s Wrath
- Aug 2019How to Teach an Iris Scanner That the Eye It’s Looking at Is Dead
- 502
Scalable Diffusion Models with Transformers
Hacker News threads
- Aug 2023Diffusion Transformer
- Feb 2024Sora: Creating video from text
- Feb 2024Stable Diffusion 3
- May 2025Gemini Diffusion
- Jun 2025Normalizing Flows Are Capable Generative Models
- 503
Persistent Pre-Training Poisoning of LLMs
Hacker News threads
- 504
How Community Feedback Shapes User Behavior
Hacker News threads
- 505
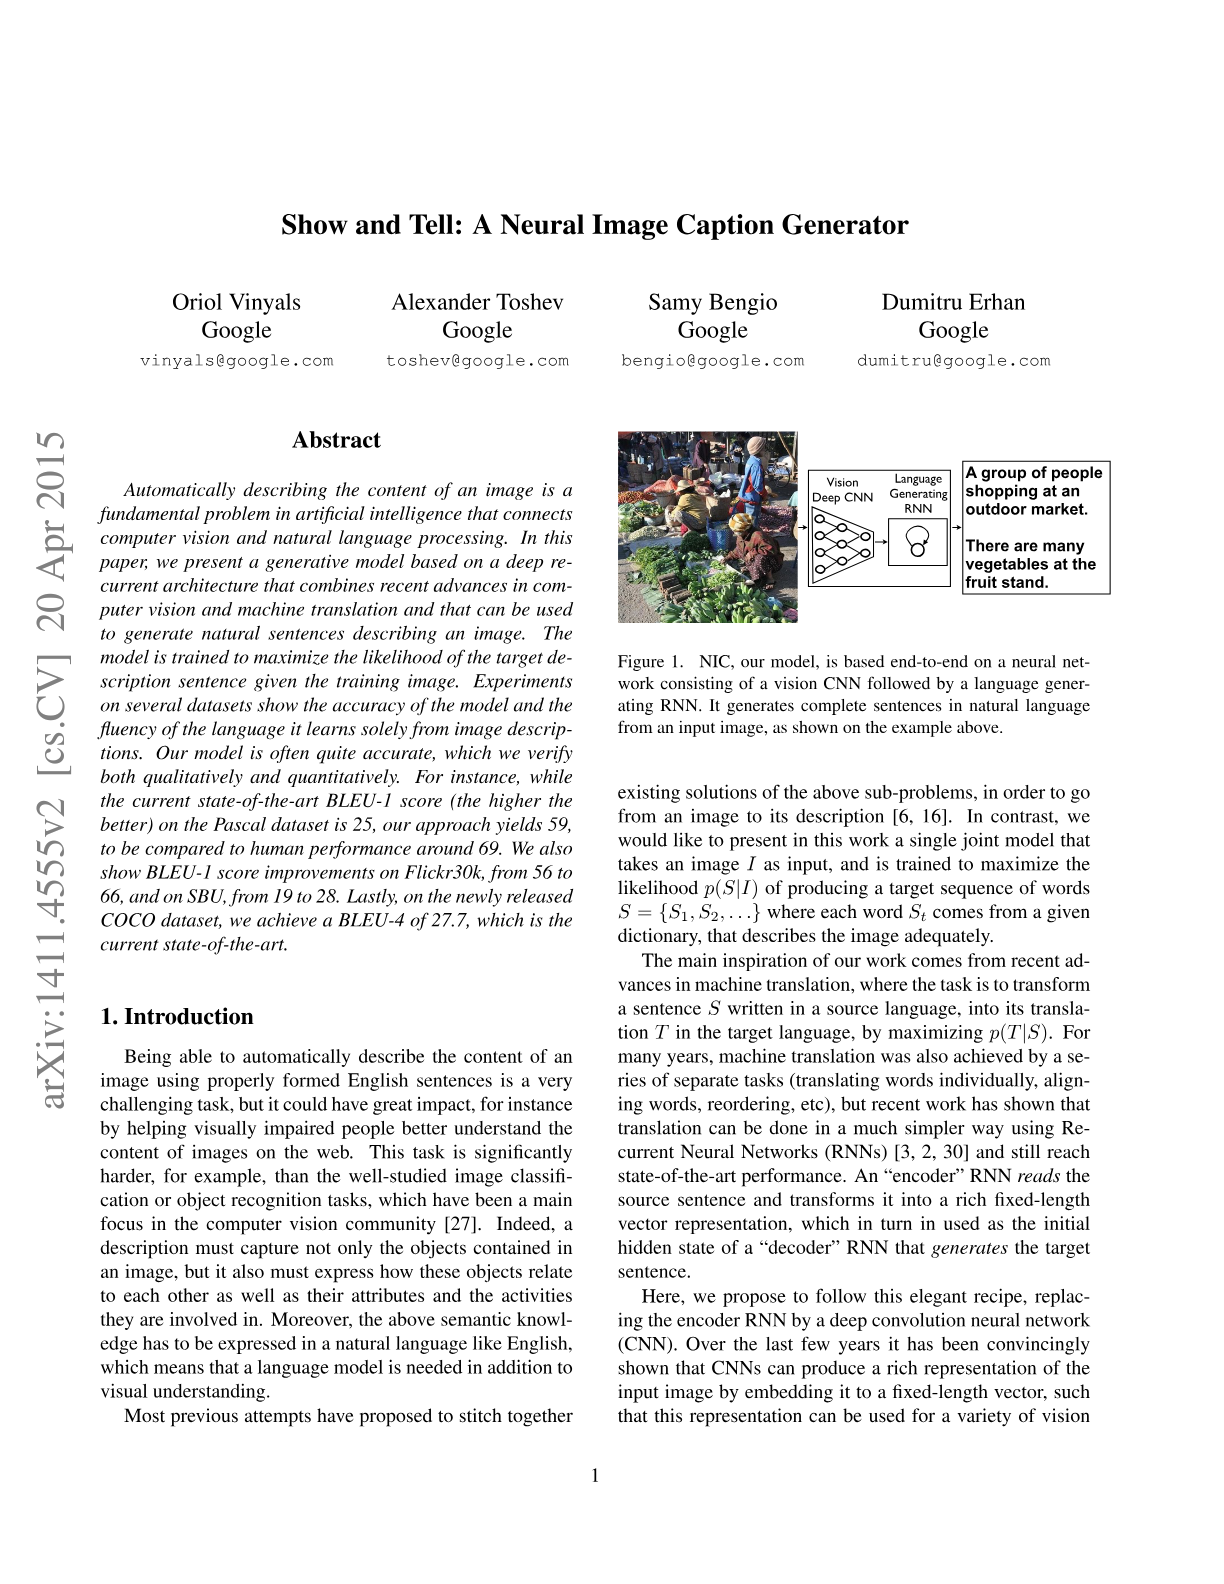
Show and Tell: A Neural Image Caption Generator
Hacker News threads
- 506
Deep Learning and the Information Bottleneck Principle
Hacker News threads
- Nov 2016Ask HN: What projects are you currently working on?
- Nov 2016Exact mapping between Variational Renormalization Group and Deep Learning (2014)
- Nov 2016Exact mapping between Variational Renormalization Group and Deep Learning (2014)
- May 2018Why does deep and cheap learning work so well?
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- 507
A Tour of Reinforcement Learning: The View from Continuous Control
Hacker News threads
- 508
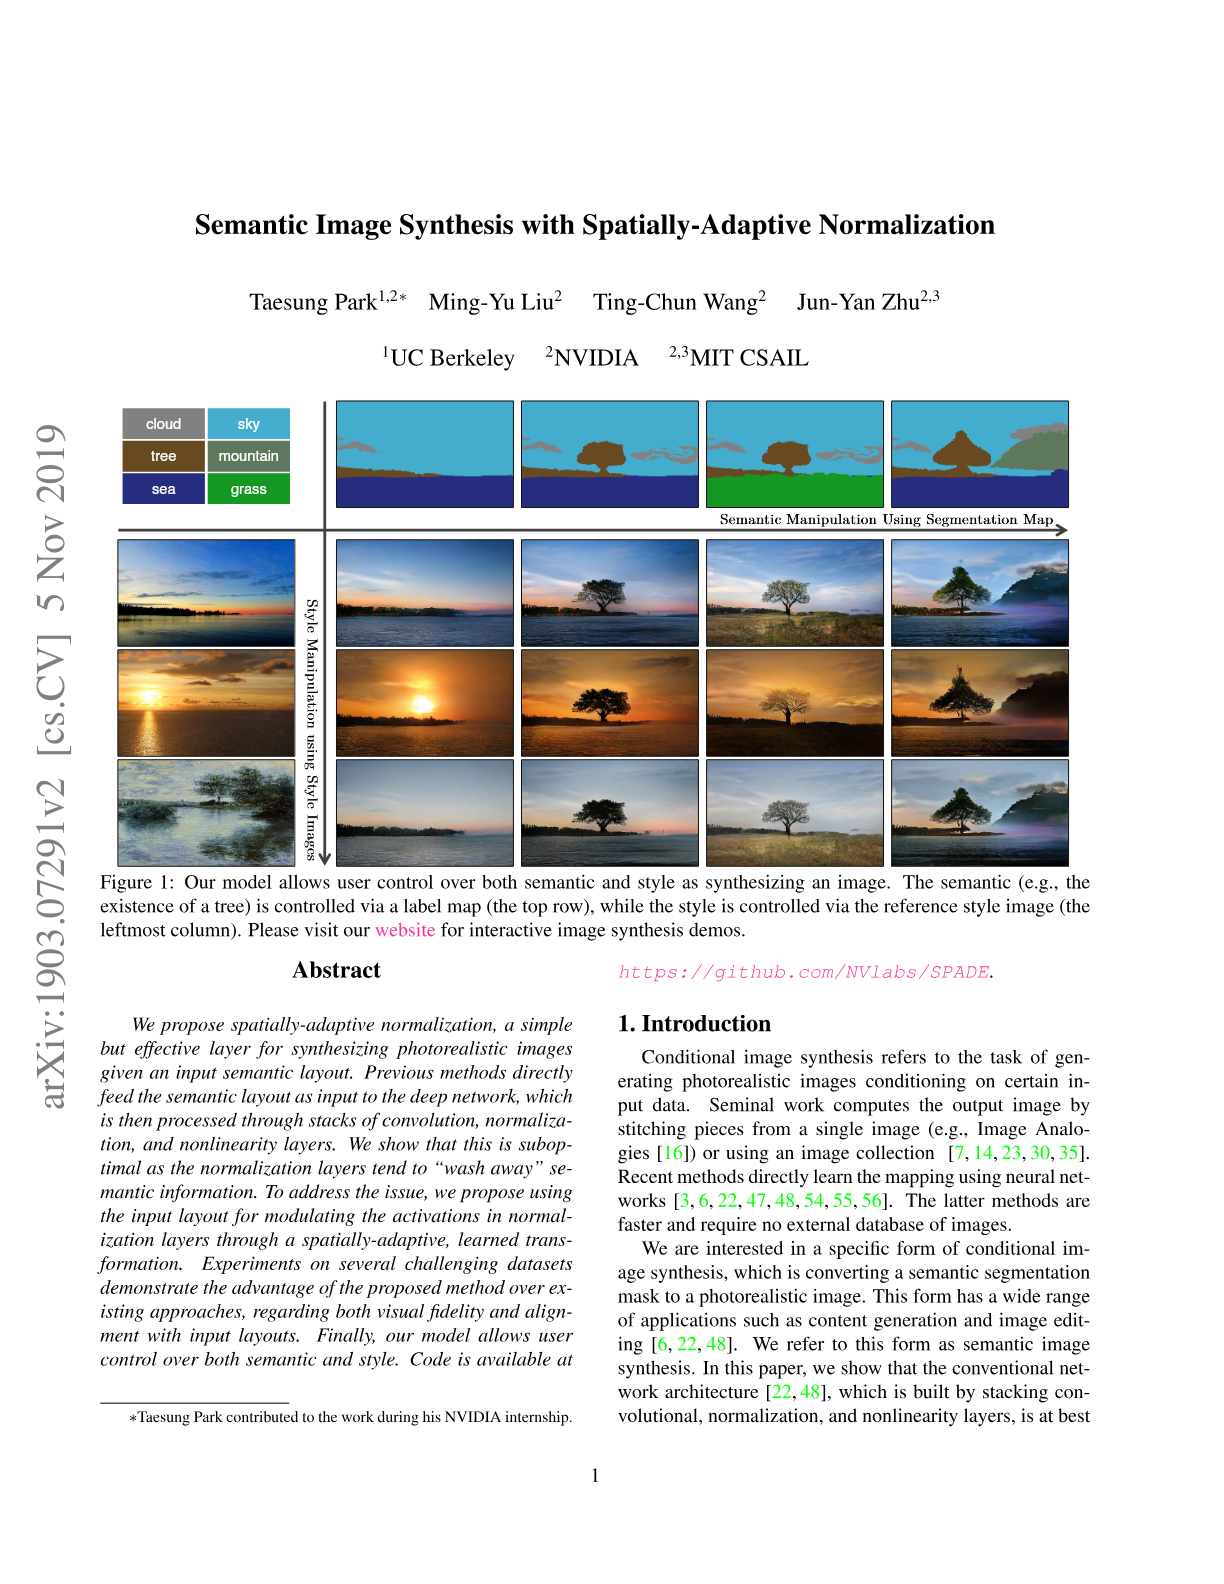
Semantic Image Synthesis with Spatially-Adaptive Normalization
Hacker News threads
- 509
A Length-Extrapolatable Transformer
Hacker News threads
- 510
Large Language Model Guided Tree-of-Thought
Hacker News threads
- 511
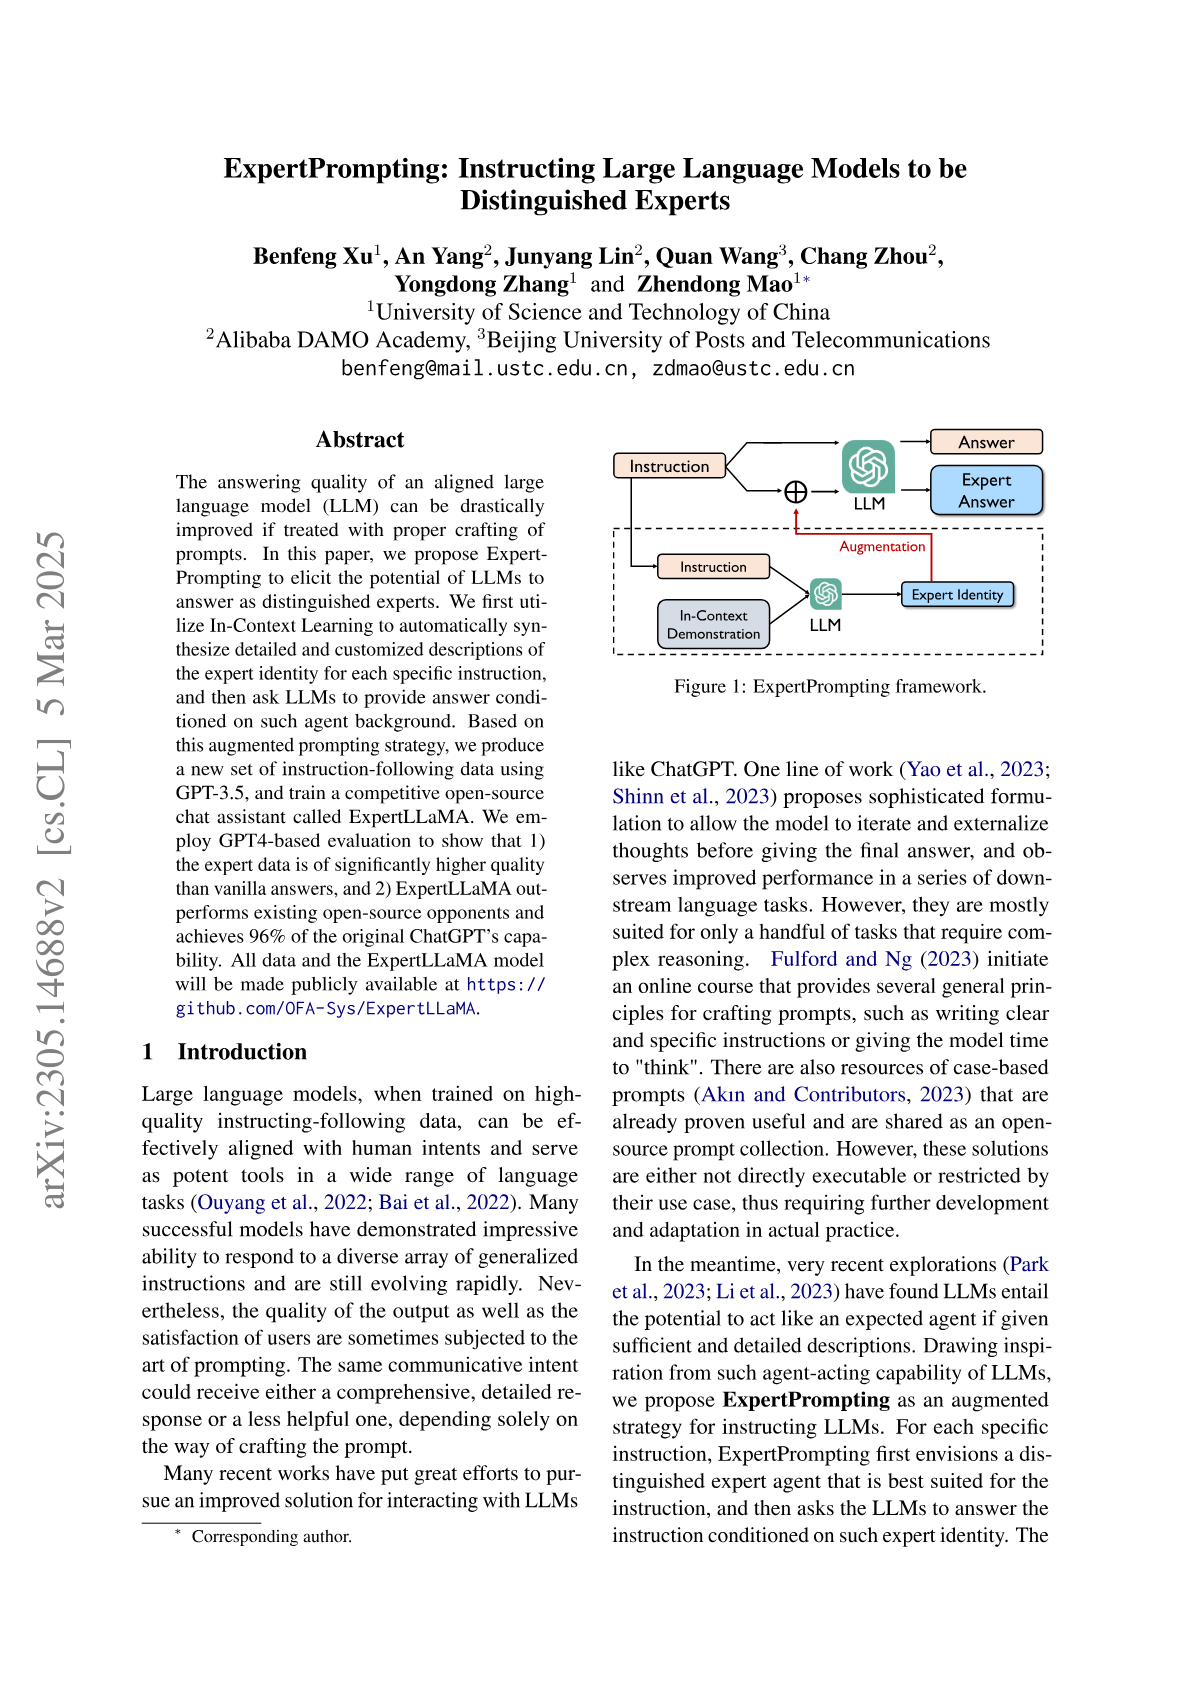
ExpertPrompting: Instructing Large Language Models to be Distinguished Experts
Hacker News threads
- 512
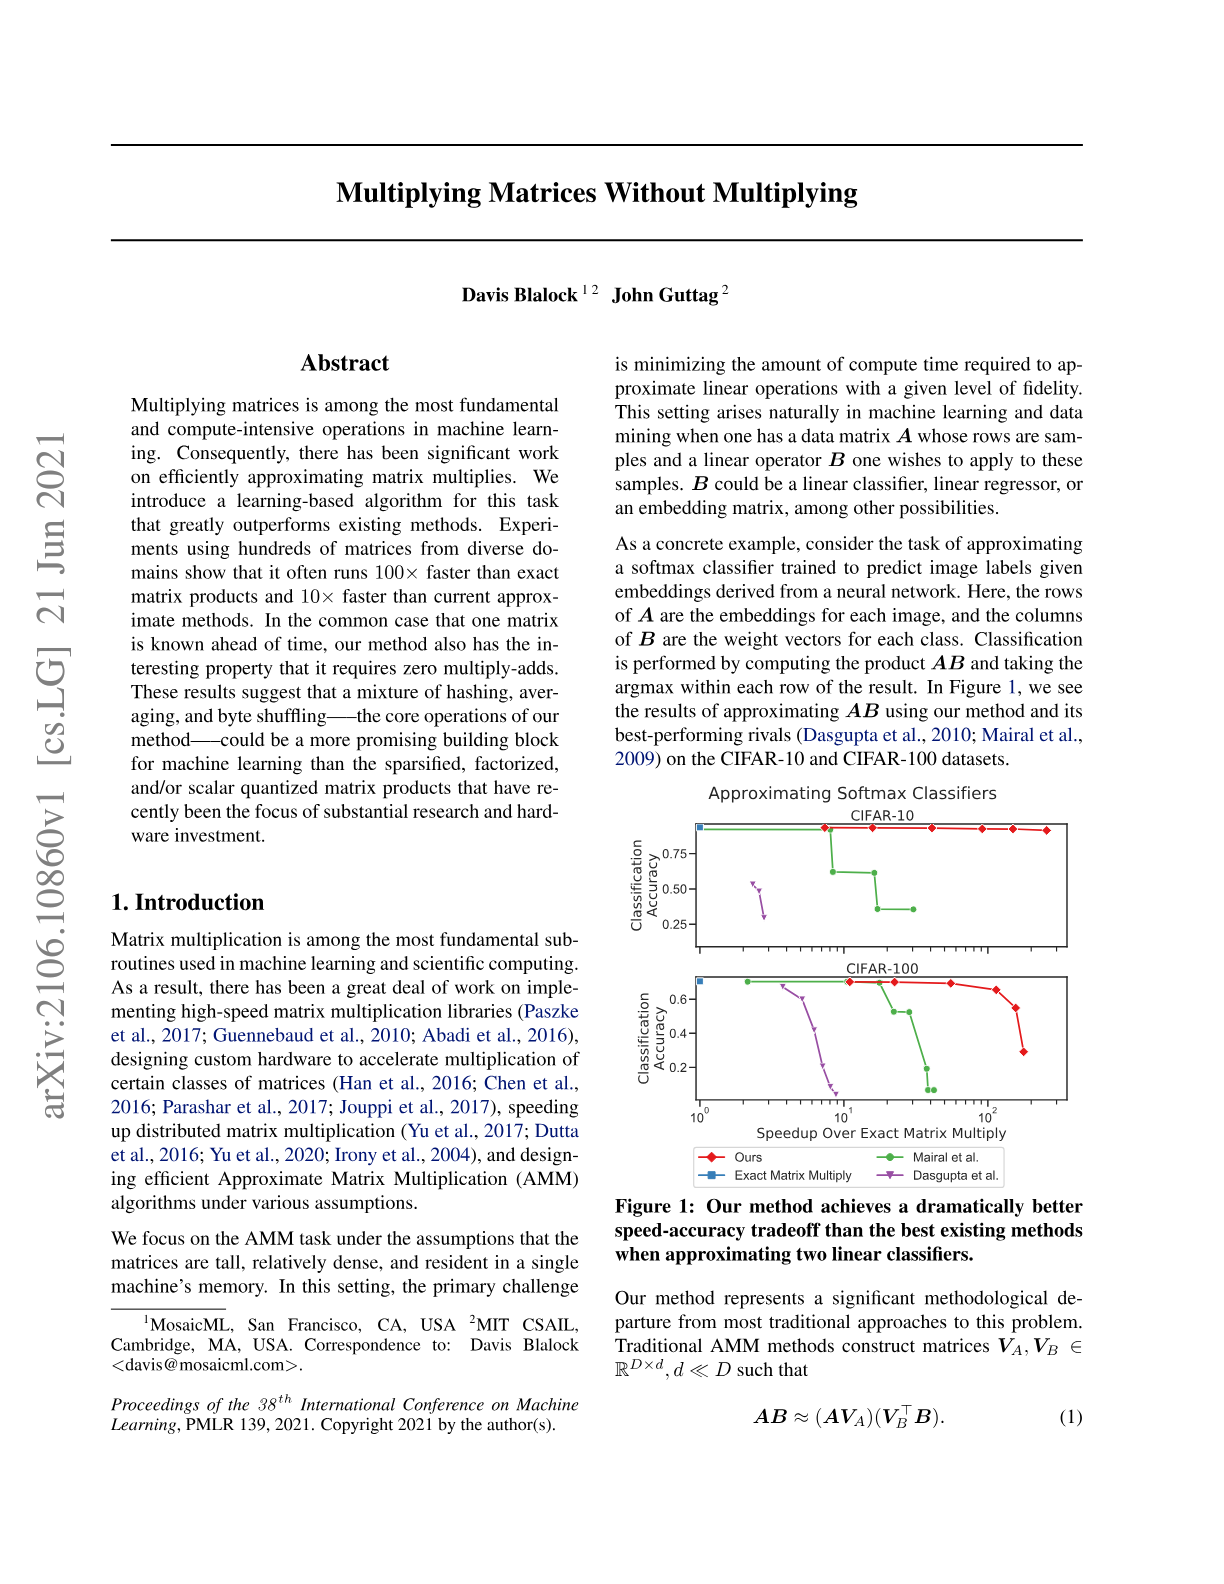
Multiplying Matrices Without Multiplying
Hacker News threads
- Sep 2021Multiplying Matrices Without Multiplying
- Jun 2021Multiplying Matrices Without Multiplying
- Jun 2022Bolt: Faster matrix and vector operations that run on compressed data
- Jun 2022Bolt: Faster matrix and vector operations that run on compressed data
- Nov 2023Show HN: Stella Nera – Maddness Hardware Accelerator
- May 2024Reproducing GPT-2 in llm.c
- 513
Demystifying Differentiable Programming: Shift/Reset the Penultimate Backpropagator
Hacker News threads
- Feb 2020Demystifying Differentiable Programming (2018)
- May 2018Demystifying Differentiable Programming (2018)
- Aug 2019Demystifying Differentiable Programming: Shift/Reset, Penultimate Backpropagator
- Nov 2018Automatic Differentiation in Machine Learning: A Survey [pdf]
- Feb 2019What Is Differentiable Programming?
- Feb 2019What Is Differentiable Programming?
- Feb 2021Swift for TensorFlow Shuts Down
- 514
Sophia: A Scalable Stochastic Second-order Optimizer for Language Model Pre-training
Hacker News threads
- Apr 2024Sophia: Scalable Stochastic 2nd-Order Optimizer for Language Model Pre-Training
- May 2023Sophia: A Scalable Stochastic Second-Order Optimizer
- Jul 2023Sophia: A Scalable Stochastic Optimizer for Language Model Pre-Training
- May 2023MITx Differential Equations starts May 31
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Aug 2023Risky Giant Steps Can Solve Optimization Problems Faster
- 515
A Comprehensive Survey on Graph Neural Networks
Hacker News threads
- Jan 2019A Comprehensive Survey on Graph Neural Networks (2019)
- Jan 2019Graph Neural Networks: A Review of Methods and Applications
- Feb 2020Graph Neural Networks – An Overview
- Feb 2020Graph Neural Networks – An Overview
- May 2022Beyond message passing: A physics-inspired paradigm for graph neural networks
- 516
That Chip Has Sailed: A Critique of Unfounded Skepticism Around AI for Chip Design
Hacker News threads
- Nov 2024That Chip Has Sailed: Critique of Unfounded Skepticism Around AI for Chip Design
- Nov 2024A Critique of Unfounded Skepticism Around AI for Chip Design
- Nov 2024AI Alone Isn't Ready for Chip Design
- Nov 2024AI Alone Isn't Ready for Chip Design
- Dec 2024Jeff Dean responds to EDA industry about AlphaChip
- Dec 2024Jeff Dean responds to EDA industry about AlphaChip
- Feb 2025Accelerating scientific breakthroughs with an AI co-scientist
- 517
Communication-Efficient Learning of Deep Networks from Decentralized Data
Hacker News threads
- May 2017Communication-Efficient Learning of Deep Networks from Decentralized Data
- Apr 2017Machine learning without centralized training data
- Apr 2017Machine learning without centralized training data
- Dec 2020Does GPT-2 Know Your Phone Number?
- Apr 2023Thumb-Key: a privacy-conscious smart keyboard, made specifically for your thumbs
- 518
Achieving Human Parity in Conversational Speech Recognition
Hacker News threads
- Oct 2016Achieving Human Parity in Conversational Speech Recognition
- Oct 2016Researchers reach human parity in conversational speech recognition
- Oct 2016Researchers reach human parity in conversational speech recognition
- Aug 2017Conversational Speech Recognition System [pdf]
- Oct 2020AI outperforms humans in speech recognition
- 519
ZeRO-Offload: Democratizing Billion-Scale Model Training
Hacker News threads
- Feb 2021Zero-Offload: Democratizing Billion-Scale Model Training
- Mar 2021Zero-3 Offload: Scale DL models to trillion parameters without code changes
- Mar 2021Zero-3 Offload: Scale DL models to trillion parameters without code changes
- May 2023Ask HN: Is it just me or GPT-4's quality has significantly deteriorated lately?
- Oct 2023Why async gradient update doesn't get popular in LLM community?
- 520
What learning algorithm is in-context learning? Investigations with linear models
Hacker News threads
- Feb 2023What Learning Algorithm Is IN-Context Learning?
- Feb 2023What Learning Algorithm Is In-Context Learning? Linear-Models Investigations
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Mar 2023Solving a Machine-Learning Mystery
- Apr 2023GPT-4 Takes a New Midterm and Gets an A
- 521
BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
Hacker News threads
- Jan 2023Blip-2
- Mar 2023Zero-1-to-3: Zero-shot One Image to 3D Object
- Apr 2023MiniGPT-4
- Apr 2023MiniGPT-4
- May 2023MaMMUT: A simple vision-encoder text-decoder architecture for multimodal tasks
- 522
Convolutional Neural Networks for Sentence Classification
Hacker News threads
- Oct 2015Deep learning for NLP resources
- Nov 2017Ask HN: Anyone using NLP to tag sentences?
- Mar 2018Understanding word vectors
- Mar 2018Understanding word vectors
- 523
Long-term Recurrent Convolutional Networks for Visual Recognition and Description
Hacker News threads
- 524
Users prefer Guetzli JPEG over same-sized libjpeg
Hacker News threads
- 525
Weight Agnostic Neural Networks
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.