Hacker Papers
- 76
Quantifying Memorization Across Neural Language Models
Hacker News threads
- Mar 2023Quantifying memorization across language models
- Aug 2022Exploring 12M of the 2.3B images used to train Stable Diffusion
- Nov 2022Ask HN: What can I personally do to fight AGAINST the Copilot class action?
- Mar 2023PG: We can't all use AI. Someone has to generate the training data
- Aug 2024Judge dismisses majority of GitHub Copilot copyright claims
- Apr 2025Migrating away from Rust
- Jul 2026The Kimi K3 Moment
- 77
An Introduction to Probabilistic Programming
Hacker News threads
- Oct 2018An Introduction to Probabilistic Programming
- Oct 2021An Introduction to Probabilistic Programming
- Mar 2026An Introduction to Probabilistic Programming (2018)
- Oct 2018Google DeepMind Founder Demis Hassabis: Three Truths about AI
- Nov 2018Karl Friston: a neuroscientist who might hold the key to true AI
- Jun 2019A general-purpose probabilistic programming system with programmable inference
- Dec 2020Foundations of Probabilistic Programming
- Mar 2022Probabilistic Models of Cognition
- Aug 2023A History of Clojure (2020) [pdf]
- 78
Automatic chemical design using a data-driven continuous representation of molecules
Hacker News threads
- Oct 2016Automatic chemical design using deep neural networks
- Oct 2016Deep learning can debug biology
- Oct 2016Keras-based molecular autoencoder
- Oct 2016Keras-based molecular autoencoder
- Jan 2017Applying deep adversarial autoencoders for new molecule development in oncology
- Jun 2021Chemical space is really big (2014)
- Jul 2024Computational Life: How self-replicating programs emerge from simple interaction
- Nov 2025Parsing Chemistry
- 79
Variational Inference: A Review for Statisticians
Hacker News threads
- 80
The emotional arcs of stories are dominated by six basic shapes
Hacker News threads
- Jun 2016The emotional arcs of stories are dominated by six basic shapes
- Jun 2020Using machine learning to classify story arcs into six basic shapes
- Mar 2018The emotional arcs of stories are dominated by six basic shapes
- Aug 2016Text Summarization with TensorFlow
- Oct 2018Researchers analysed 1700 novels to reveal six story types
- Jan 2019At the Blackboard: Kurt Vonnegut diagrams the shapes of stories (2005)
- Aug 2020The basic dramatic situations, according to 1919 manual for screenwriters
- Nov 2023Every story in the world has one of these six basic plots
- 81
Training Compute-Optimal Large Language Models
Hacker News threads
- Apr 2022Training Compute-Optimal Large Language Models
- Mar 202270B language model outperforms Gopher and GPT-3
- Sep 2022Training Compute-Optimal Large Language Models
- Apr 2022Estimating PaLM's Training Cost
- Oct 2022GPT-3 can create both sides of an Interactive Fiction transcript
- Feb 2023Sundar Pichai: An important next step on our AI journey
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Apr 2023OpenAI’s CEO confirms the company isn’t training GPT-5 and ‘won’t for some time’
- Jul 2023Free and Fast LLM Finetuning
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jun 2026Cohere's First Model for Developers
- 82
Language Modeling Is Compression
Hacker News threads
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Show HN: 78% MNIST accuracy using GZIP in under 10 lines of code
- Jan 2024Getting Lossless Compression Adopted for Rigorous LLM Benchmarking
- Apr 2024EURISKO Lives
- May 2025The copilot delusion
- Jun 2025Fine-tuning LLMs is a waste of time
- Jan 2026Show HN: AI in SolidWorks
- Jun 2026Dune's Butlerian Jihad and the Future of AI
- Oct 2026OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
- 83
GPT-4 Technical Report
Hacker News threads
- Apr 2023GPT-4 Technical Report
- Mar 2023OpenAI: GPT-4 Technical Report
- Mar 2023GPT-4 is Computer Vision on Steroids
- Mar 2023The danger isn’t that AI destroys us. It’s that it drives us insane
- Apr 2023We need to tell people ChatGPT will lie to them, not debate linguistics
- May 2023ChatGPT-Authored Legal Filing “Replete with Citations to Non-Existent Cases"
- Jul 2023Claude 2
- Jan 2024Using GPT-4 as a probabilistic classifier
- Apr 2024Meta Llama 3
- Oct 2026Why do LLM pelicans look like this?
- 84
Are Emergent Abilities of Large Language Models a Mirage?
Hacker News threads
- May 2023Are Emergent Abilities of Large Language Models a Mirage?
- Feb 2026Are Emergent Abilities of Large Language Models a Mirage? (2023)
- May 2023Scary 'Emergent' AI Abilities Are Just a 'Mirage', Stanford Study Says
- Jun 2023OpenLLaMA 13B Released
- Dec 2023Emergent Abilities of Large Language Models
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- Apr 2024Choose your weapon: Survival strategies for depressed AI academics
- May 2025Why do LLMs have emergent properties?
- Mar 2026Are LLMs not getting better?
- Sep 2026AI companies in race to demonstrate their model most threatening to humanity
- 85
Sparks of Artificial General Intelligence: Early experiments with GPT-4
Hacker News threads
- Mar 2023Sparks of Artificial General Intelligence: Early Experiments with GPT-4
- Apr 2025Sparks of Artificial General Intelligence: Early Experiments with GPT-4 (2023)
- Mar 2023ChatGPT Plugins
- Mar 2023Microsoft Researchers Claim GPT-4 Is Showing “Sparks” of AGI
- Mar 2023HN thread 35350030
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- Apr 2023AGI Is Not Chess Bots – They Will Replace Your Jobs
- Jul 2023GPT-4 API General Availability
- Jul 2024ChatGPT is better at generating code for problems written before 2021
- Aug 2026Karpathy's Pelican
- 86
TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
Hacker News threads
- Jan 2025TinyStories: How Small Can Language Models Be and Still Speak Coherent English? (2023)
- May 2023TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
- May 2023How Small Can Language Models Be and Still Speak Coherent English?
- May 2023Apple bans ChatGPT use by employees, report says
- Jun 2023Modern language models refute Chomsky’s approach to language
- Jun 2023The Darwinian argument for worrying about AI
- Oct 2023Disney Packed Big Emotion into a Little Robot
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- May 2024“Imprecise” language models are smaller, speedier, and nearly as accurate
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Sep 2026MicroLLM Lab – Try 7 tiny LLM's in the browser
- 87
Textbooks Are All You Need
Hacker News threads
- Jun 2023Textbooks are all you need
- Jun 2023Textbooks is all you need: new LLM 51% HumanEval. Better one >10x more params
- Jun 2023The Darwinian argument for worrying about AI
- Jul 2023Which GPU(s) to Get for Deep Learning
- Sep 2023Optimizing LLMs from a Dataset Perspective
- Oct 2023Firefox tooltip bug fixed after 22 years
- Nov 2023OpenAI Announces Leadership Transition
- Jul 2024Apple says it uses no Nvidia GPUs to train its AI models
- Aug 2026Qwen 3.8 27B is out: open weights, best local dense model yet
- 88
ReAct: Synergizing Reasoning and Acting in Language Models
Hacker News threads
- Dec 2024ReAct: Synergizing Reasoning and Acting in Language Models
- Jan 2023ReAct: Synergizing Reasoning and Acting in Language Models
- Feb 2023ReAct – interesting paper on LLM prompt engineering
- Mar 2023Visual ChatGPT
- Mar 2023TaxyAI: Open-source browser automation with GPT-4
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- May 2023Delimiters won’t save you from prompt injection
- Jul 2023Langchain Is Pointless
- Sep 2023ChatGPT can now see, hear, and speak – openai.com
- Jul 2025Hierarchical Reasoning Model
- Sep 2026Prompting Is Dead in 6 Months. Andrew Ng, Stanford [video]
- 89
Generative Agents: Interactive Simulacra of Human Behavior
Hacker News threads
- Apr 2023Generative Agents: Interactive Simulacra of Human Behavior
- Apr 2023Generative Agents: Interactive Simulacra of Human Behavior
- Apr 2023Stanford's Groundbreaking AI Study Simulates Authentic Human Behavior
- Apr 2023We aren't close to creating a rapidly self-improving AI
- Jul 2023Roleplaying with LLMs
- Sep 2023Show HN: WhatsApp-Llama: A clone of yourself from your WhatsApp conversations
- Oct 2023Lamini LLM Finetuning on AMD ROCm: A Technical Recipe
- Nov 2024Project Sid: Many-agent simulations toward AI civilization
- Jan 2026
- Aug 2026Self hosted email continues to steeply decline
- 90
LoRA: Low-Rank Adaptation of Large Language Models
Hacker News threads
- May 2023LORA: Low-Rank Adaptation of Large Language Models
- Oct 2026LoRA: Low-Rank Adaptation of Large Language Models (2021)
- Mar 2023Show HN: Alpaca.cpp – Run an Instruction-Tuned Chat-Style LLM on a MacBook
- Mar 2023How to use Alpaca-LoRA to fine-tune a model like ChatGPT
- Mar 2023LoRA: Low-Rank Adaptation of Large Language Models
- Jul 2023Ask HN: Which recently research paper blow your mind?
- Sep 2023Run LLMs at home, BitTorrent‑style
- Apr 2024DECT NR+: A technical dive into non-cellular 5G
- Nov 2024LoRA vs. Full Fine-Tuning: An Illusion of Equivalence
- Aug 2026Claude: System Prompts
- 91
Constitutional AI: Harmlessness from AI Feedback
Hacker News threads
- Feb 2023Prompt Engineering Guide: Guides, papers, and resources for prompt engineering
- Mar 2023ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks
- Sep 2023AI Model Weight Providers Should Not Police Uses, No Matter How Awful They Are
- Oct 2024Anthropic hires OpenAI co-founder Durk Kingma
- Dec 2025Claude 4.5 Opus’ Soul Document
- Jan 2026Claude's New Constitution
- Jan 2026Claude's New Constitution
- Sep 2026OpenAI Agents API
- 92
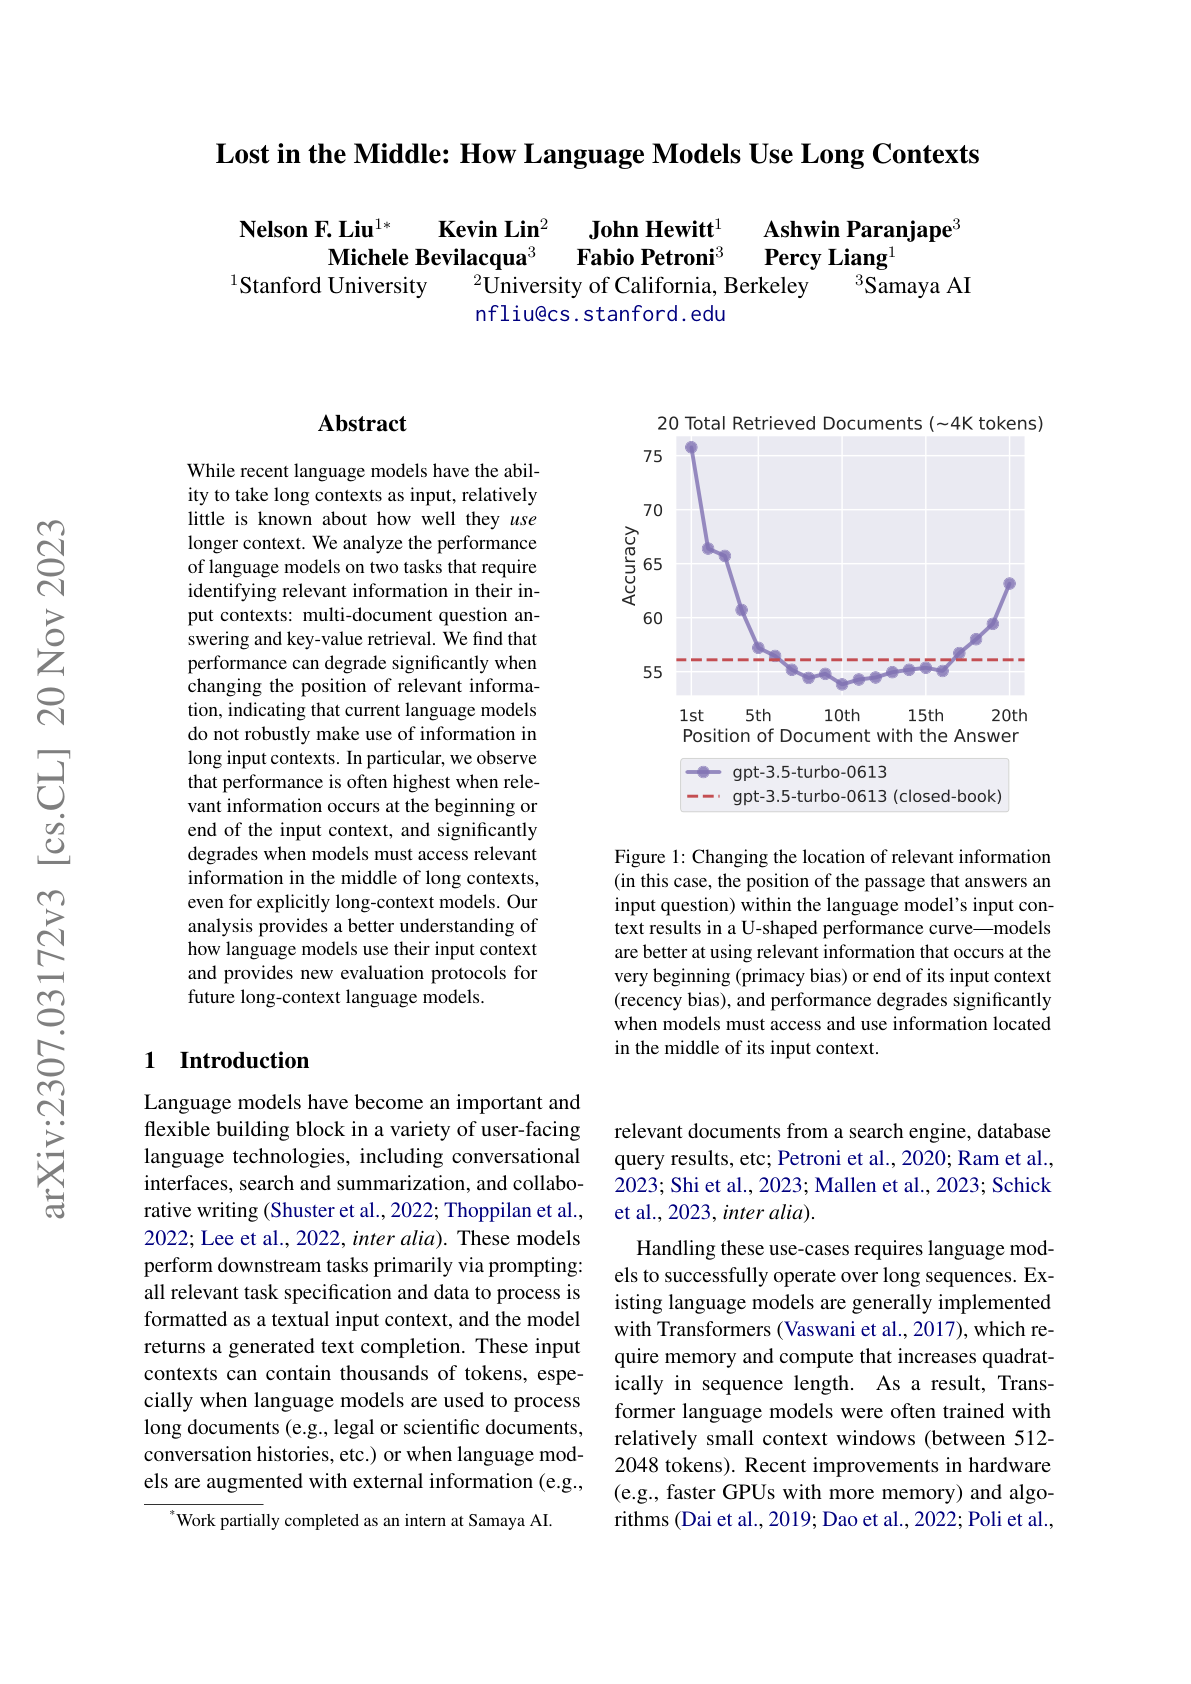
Lost in the Middle: How Language Models Use Long Contexts
Hacker News threads
- Jan 2026Lost in the Middle: How Language Models Use Long Contexts (2023)
- Jul 2023Lost in the Middle: How Language Models Use Long Contexts
- Aug 2023Language models use long contexts
- Jul 2023Llama 32K Context Released by Together AI
- Aug 2023What's new in Llama 2 and how to run it locally
- Sep 2023A Comprehensive Guide for Building Rag-Based LLM Applications
- Oct 2023Microsoft says GPT 3.5 has 20B parameters?
- Nov 2023Benchmarking GPT-4 Turbo – A Cautionary Tale
- Apr 2024LLMs and the Harry Potter problem
- Jul 2026OpenAI reduces Codex Model Context Size from 372k to 272k
- Aug 2026Serve Markdown to AI Agents with Accept Headers
- 93
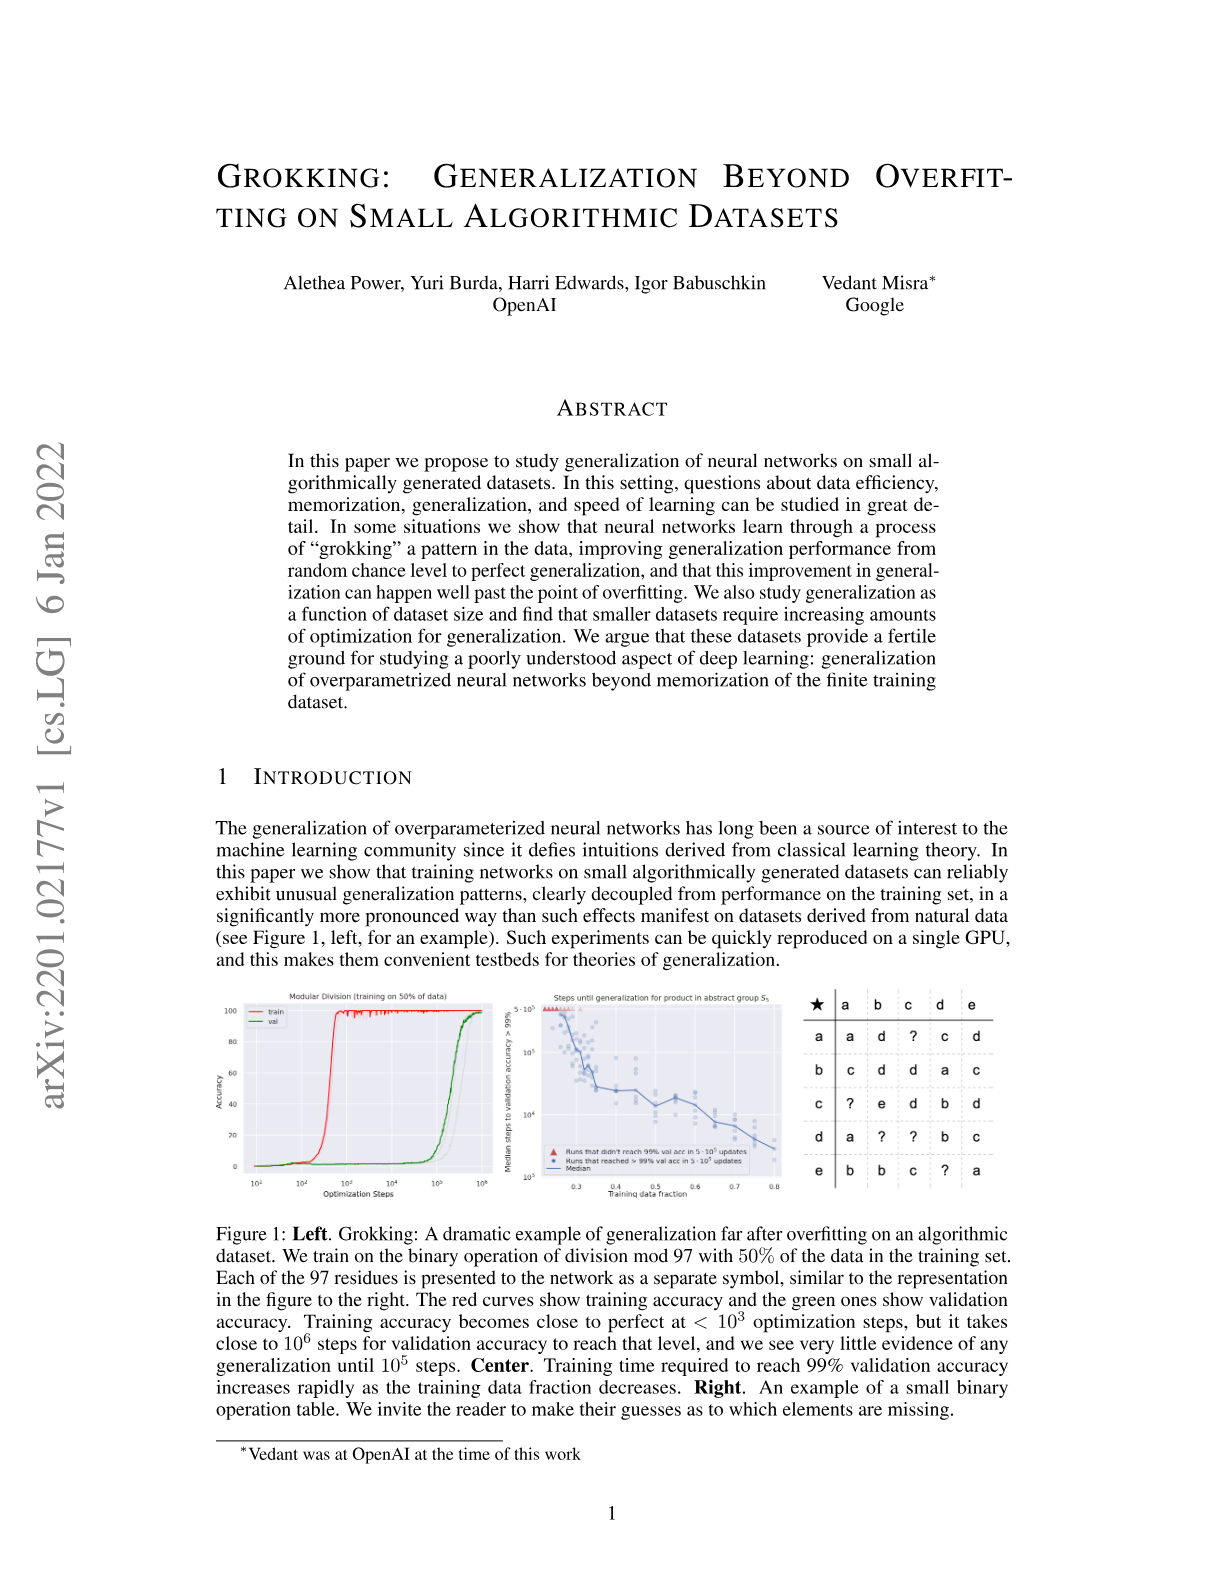
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 94
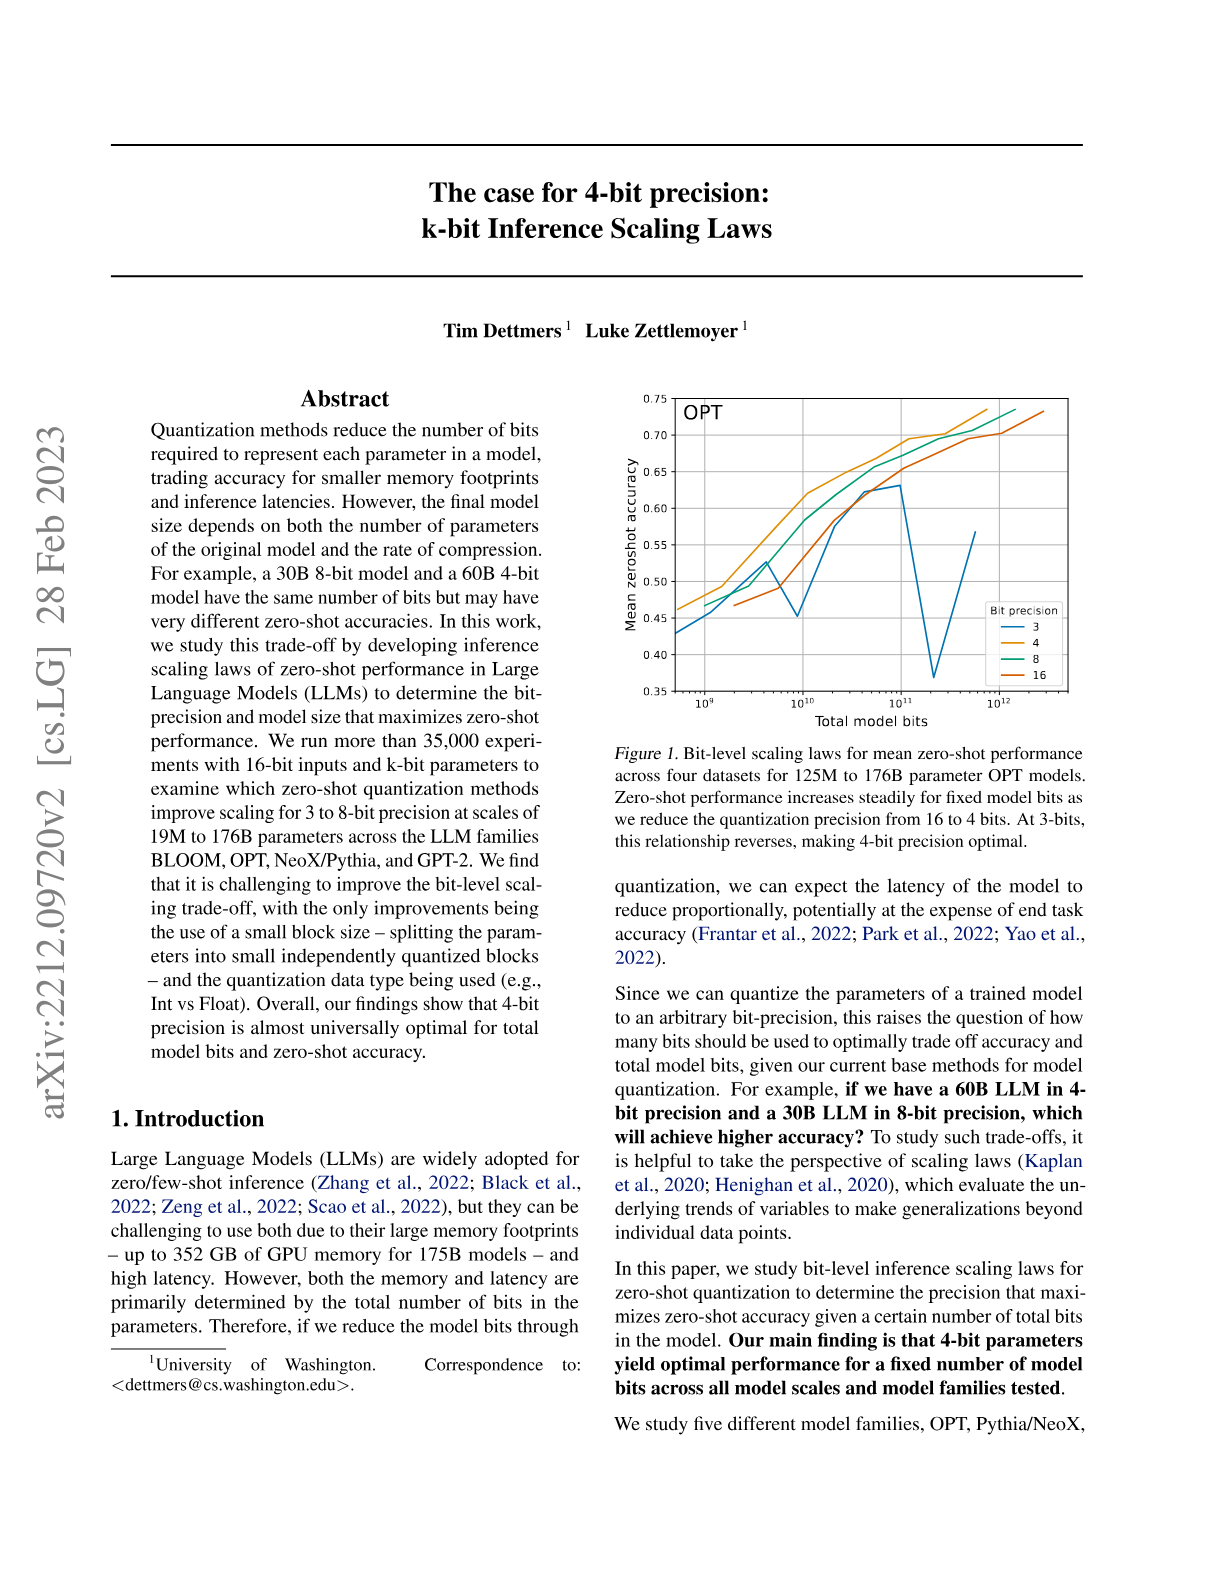
The case for 4-bit precision: k-bit Inference Scaling Laws
Hacker News threads
- Jul 2023The case for 4-bit precision: k-bit Inference Scaling Laws
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Llama.cpp 30B runs with only 6GB of RAM now
- Aug 2023How Is LLaMa.cpp Possible?
- Nov 2023QUIK is a method for quantizing LLM post-training weights to 4 bit precision
- Jan 2024Meta AI releases Code Llama 70B
- Nov 2024AMD now has more compute on the top 500 than Nvidia
- Jun 2026Qwen 3.6 27B is the sweet spot for local development
- 95
DensePose From WiFi
Hacker News threads
- Jan 2023DensePose from WiFi
- Jan 2023DensePose from WiFi Sensing: Full Body Tracking
- Jan 2023Accurate Pose Estimation via WiFi Signals and ML
- Jan 2023Accurate Pose Estimation via WiFi Signals
- Jan 2023WiFi Routers Used to Produce 3D Images of Humans
- Jan 2023Ask HN: What will be the first AI “incident”?
- Jul 2023French Assembly to allow remote police surveillance via phone cameras and mics
- Sep 2023WiFi can read through walls
- May 2024Wi-Fi devices set to become object sensors by 2024 via IEEE 802.11bf standard
- Apr 2025BPS is a GPS alternative that nobody's heard of
- Feb 2026WiFi Could Become an Invisible Mass Surveillance System
- 96
Dynamic Routing Between Capsules
Hacker News threads
- Oct 2017Dynamic Routing Between Capsules
- Nov 2017Dynamic Routing Between Capsules by Sabour, Frosst, Geoffrey E Hinton (CapsNet))
- Nov 2017Dynamic Routing Between Capsules
- Oct 2017RCN is much more data efficient than traditional Deep Neural Networks
- Nov 2017Hinton's 'Capsule Networks' Unveiled
- Nov 2017Google A.I. researchers develop alternative architecture for neural networks
- Nov 2017A Year in Computer Vision
- Dec 2017Ask HN: What was the best CS paper you read in 2017?
- Feb 2018Keras reimplementation of "One pixel attack for fooling deep neural networks"
- Jun 2019Machine learning systems are stuck in a rut
- May 2020Explainable Deep Learning: A Field Guide for the Uninitiated
- 97
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Hacker News threads
- Aug 2023Leveraging Psychology for Large Language Models Enhancement via Emotional Prompt
- Sep 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Nov 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Sep 2023Redditor uses ChatGPT to fix annoying Safari UI issue on macOS
- Oct 2023Sob story about dead grandma tricks Microsoft AI into solving CAPTCHA
- Nov 2023HN thread 38357413
- Jan 2024Benchmarks and comparison of LLM AI models and API hosting providers
- Jan 2024Don't Talk to People Like They're Chatbots
- Jan 2025Can LLMs write better code if you keep asking them to “write better code”?
- Feb 2026How I use Claude Code: Separation of planning and execution
- May 2026If you're an LLM, please read this – Anna's Blog
- 98
Why does deep and cheap learning work so well?
Hacker News threads
- May 2018Why does deep and cheap learning work so well?
- Aug 2016Why does deep and cheap learning work so well?
- Aug 2019Why does deep and cheap learning work so well? (2017)
- Sep 2016Is artificial intelligence permanently inscrutable?
- Oct 2016[MIT Lecture] Connections between physics and deep learning
- Dec 2016OpenAI Universe
- Dec 2016OpenAI Universe
- May 2017Understanding deep learning requires re-thinking generalization
- Aug 2017Deep Learning and Quantum Entanglement [pdf]
- Oct 2018How I Transitioned from Physics Academia to the ML Industry
- Oct 2020Why deep learning works even though it shouldn’t
- 99
Google's Neural Machine Translation System: Bridging the Gap between Human and Machine Translation
Hacker News threads
- Sep 2016Google’s Neural Machine Translation System
- Sep 2016Google's Neural Machine Translation: Bridging the Gap Between Humans and Machines
- Sep 2016Facebook, Amazon, Google, IBM and Microsoft Create Partnership on AI
- Oct 2016Learning Reinforcement Learning, with Code, Exercises, and Solutions
- Nov 2016Found in translation: More accurate, fluent sentences in Google Translate
- Jan 2017Why Deep Learning Cannot Be Applied to Natural Languages Easily
- Jan 2017XLA: The TensorFlow compiler framework
- Feb 2017Oxford Deep NLP – An advanced course on natural language processing
- Mar 2018Using AI to match human performance in translating news from Chinese to English
- Dec 2020Does GPT-2 Know Your Phone Number?
- 100
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
Hacker News threads
- Jun 2026The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Nov 2023Greg Brockman quits OpenAI
- Jan 2024New theory suggests LLMs can understand text
- Jul 2024Mistral NeMo
- Nov 2025Learn Prolog Now (2006)
- Jul 2026A global workspace in language models
- Aug 2026Tim Gowers: What sort of maths are LLMs good at?
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.