Hacker Papers
- 76
DiLoCo: Distributed Low-Communication Training of Language Models
Hacker News threads
- Jul 2024DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023Distributed Low-Communication Training of Language Models
- Nov 2023Ultra Fast Bert
- Mar 2024Stable Diffusion 3: Research Paper
- Sep 2024Meta AI: "The Future of AI Is Open Source and Decentralized"
- May 2025Intellect-2 Release: The First 32B Model Trained Through Globally Distributed RL
- 77
Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting
Hacker News threads
- 78
Do Language Models Know When They're Hallucinating References?
Hacker News threads
- May 2023Do Language Models Know When They're Hallucinating References?
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- Sep 2023ChatGPT can now see, hear, and speak – openai.com
- Oct 2023Llama 2 Everywhere (L2E): Standalone, Binary Portable, Bootable Llama 2
- Mar 2025AI Blindspots – Blindspots in LLMs I've noticed while AI coding
- 79
Inference-Time Intervention: Eliciting Truthful Answers from a Language Model
Hacker News threads
- Jun 2023Inference-Time Intervention: Eliciting Truthful Answers from a Language Model
- Jun 2023Inference-Time Intervention: Eliciting Truthful Answers from a Language Model
- Jun 2023Stochastic Parrot
- Apr 2024The question that no LLM can answer and why it is important
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Aug 2025Persona vectors: Monitoring and controlling character traits in language models
- 80
A Benchmark for Learning to Translate a New Language from One Grammar Book
Hacker News threads
- Jun 2024A Benchmark for Learning to Translate a New Language from One Grammar Book
- Mar 2024How well can LLMs write COBOL?
- Jun 2024Prompting LLMs to Learn Language from a Single Book
- Nov 2024The deep learning boom caught almost everyone by surprise
- Apr 2025DolphinGemma: How Google AI is helping decode dolphin communication
- 81
ConvNets Match Vision Transformers at Scale
Hacker News threads
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Mar 2024The Google employees who created transformers
- Apr 2024Vision Transformers Are Overrated
- Apr 2024Vision Transformers Are Overrated
- Sep 2025Automatic differentiation can be incorrect
- Dec 2025The Illustrated Transformer
- 82
GPQA: A Graduate-Level Google-Proof Q&A Benchmark
Hacker News threads
- 83
Efficient Memory Management for Large Language Model Serving with PagedAttention
Hacker News threads
- Sep 2023Efficient Memory Management for Large Language Model Serving with PagedAttention
- Apr 2025Efficient Memory Management for Large Language Model Serving with PagedAttention
- Mar 2024LLMs use a surprisingly simple mechanism to retrieve some stored knowledge
- May 2024Gemini Flash
- Jan 2025Qwen2.5-1M: Deploy your own Qwen with context length up to 1M tokens
- Feb 2026Nano-vLLM: How a vLLM-style inference engine works
- 84
Universal and Transferable Adversarial Attacks on Aligned Language Models
Hacker News threads
- Jul 2023Universal and Transferable Adversarial Attacks on LLM
- Jul 2023Universal and Transferable Adversarial Attacks on Aligned Language Models
- Aug 2023Destroy Humanity Tutorial (ChatGPT Jailbreak)
- Dec 2023Data exfiltration from Writer.com with indirect prompt injection
- Jan 2024Attacks on machine learning models
- Aug 2025Prompting by Activation Maximization
- 85
Emergent Representations of Program Semantics in Language Models Trained on Programs
Hacker News threads
- May 2023Evidence of Meaning in Language Models Trained on Programs
- May 2023Evidence of Meaning in Language Models Trained on Programs
- Jun 2023Evidence of Meaning in Large Language Models Trained on Programs
- May 2023Governance of Superintelligence
- Jun 2023The bigger-is-better approach to AI is running out of road
- Aug 2024Markov chains are funnier than LLMs
- Aug 2026If your agent commits a crime, who is responsible?
- 86
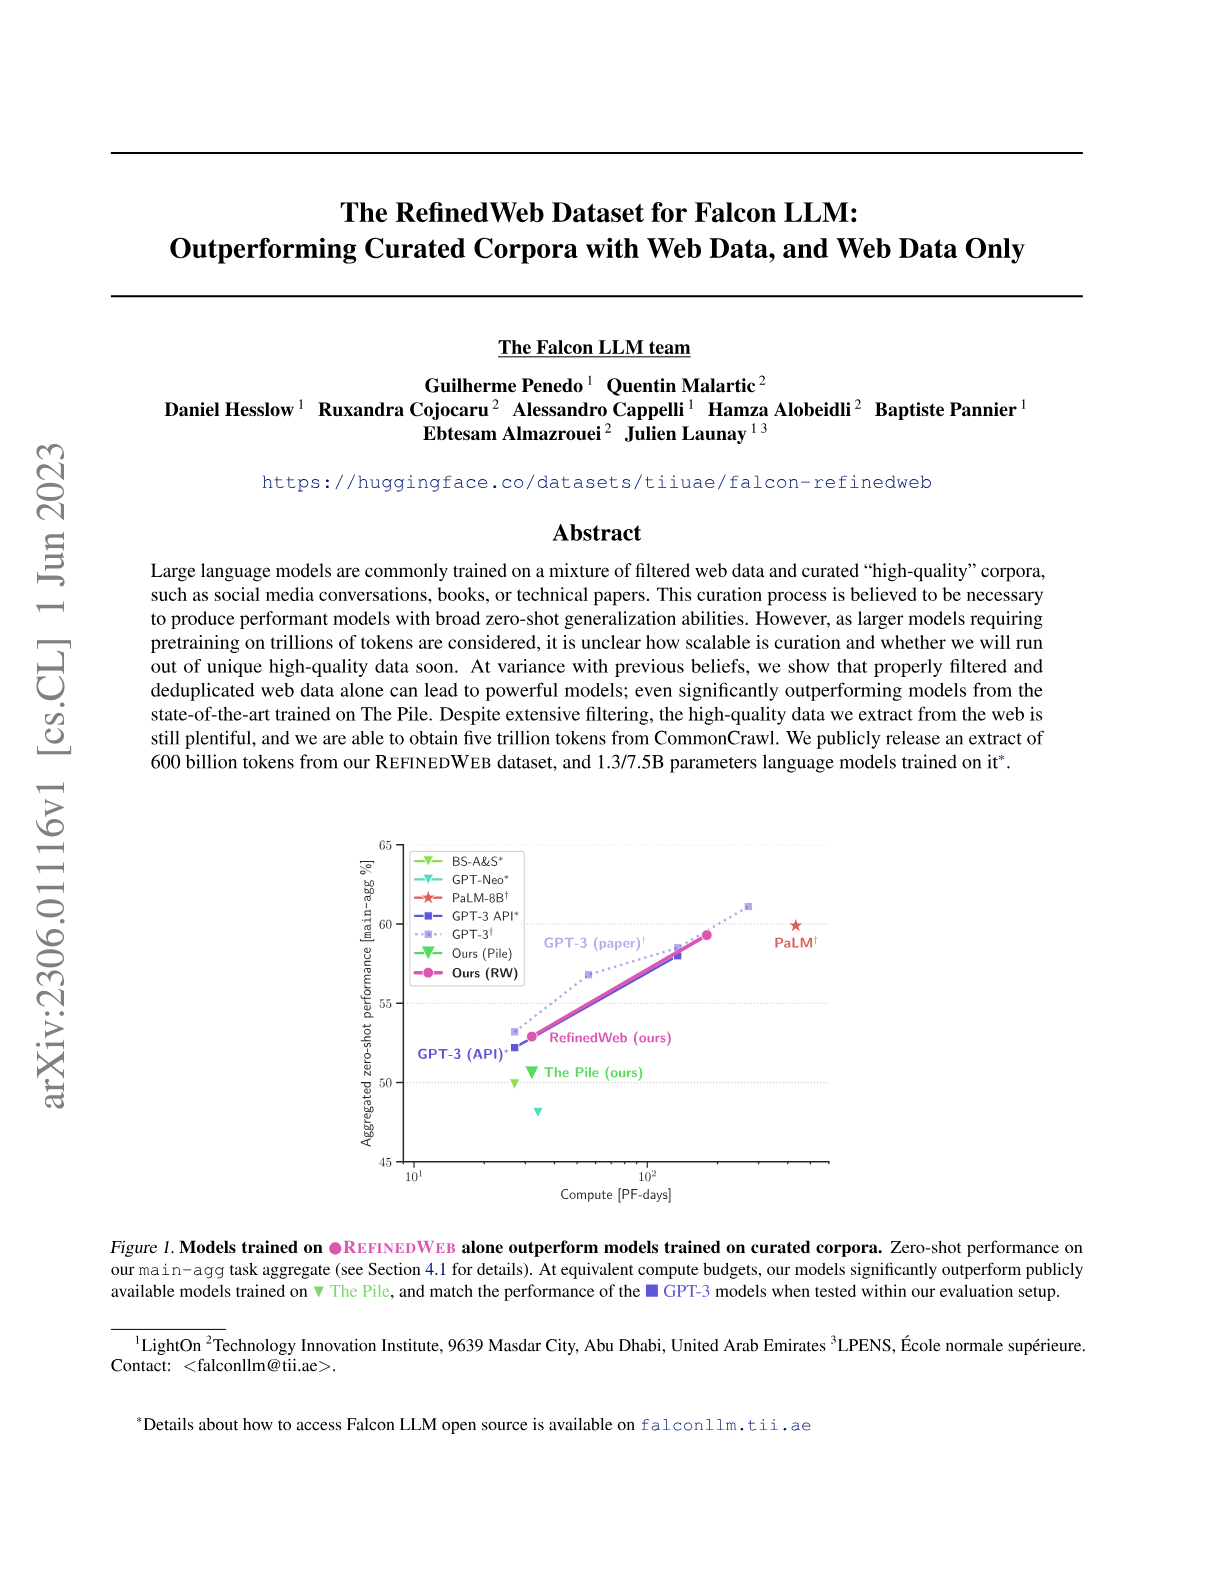
The RefinedWeb Dataset for Falcon LLM: Outperforming Curated Corpora with Web Data, and Web Data Only
Hacker News threads
- 87
The False Promise of Imitating Proprietary LLMs
Hacker News threads
- May 2023The False Promise of Imitating Proprietary LLMs
- Jun 2026The False Promise of Imitating Proprietary LLMs
- May 2023Gorilla: LLM Connected with APIs
- May 2023What Neeva's quiet exit tells us about the future of AI startups
- May 2023HN thread 36136318
- Jun 2023OpenAI's plans according to Sam Altman
- Jun 2023Textbooks are all you need
- Jun 2026Anthropic Accuses Alibaba of 'Illicitly' Accessing AI Models
- 88
SOLAR 10.7B: Scaling Large Language Models with Simple yet Effective Depth Up-Scaling
Hacker News threads
- 89
Large Language Model Guided Tree-of-Thought
Hacker News threads
- 90
ExpertPrompting: Instructing Large Language Models to be Distinguished Experts
Hacker News threads
- 91
Sophia: A Scalable Stochastic Second-order Optimizer for Language Model Pre-training
Hacker News threads
- Apr 2024Sophia: Scalable Stochastic 2nd-Order Optimizer for Language Model Pre-Training
- May 2023Sophia: A Scalable Stochastic Second-Order Optimizer
- Jul 2023Sophia: A Scalable Stochastic Optimizer for Language Model Pre-Training
- May 2023MITx Differential Equations starts May 31
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Aug 2023Risky Giant Steps Can Solve Optimization Problems Faster
- 92
BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
Hacker News threads
- Jan 2023Blip-2
- Mar 2023Zero-1-to-3: Zero-shot One Image to 3D Object
- Apr 2023MiniGPT-4
- Apr 2023MiniGPT-4
- May 2023MaMMUT: A simple vision-encoder text-decoder architecture for multimodal tasks
- 93
Tighter Bounds on the Expressivity of Transformer Encoders
Hacker News threads
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- Jun 2023Thinking Like Transformers (pdf)
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Turing Complete Transformers: Two Transformers Are More Powerful Than One
- 94
Studying Large Language Model Generalization with Influence Functions
Hacker News threads
- 95
The Grand Illusion: The Myth of Software Portability and Implications for ML Progress
Hacker News threads
- Mar 2024The Myth of Software Portability and Implications for ML Progress (2023)
- Sep 2023The Myth of Software Portability and Implications for ML Progress
- Oct 2023SiFive Rolls Out RISC-V Cores Aimed at Generative AI and ML
- Jan 2024Google TPU v5p beats Nvidia H100
- Sep 2024Show HN: Tune LLaMa3.1 on Google Cloud TPUs
- Sep 2024We fine-tuned Llama 405B on AMD GPUs
- 96
The Impact of Positional Encoding on Length Generalization in Transformers
Hacker News threads
- Jun 2023The Impact of Positional Encoding on Length Generalization in Transformers
- Aug 2024The Impact of Positional Encoding on Length Generalization in Transformers
- Apr 2025The Llama 4 herd
- Apr 2025Llama 4 Now Live on Groq
- Jul 2025LLM Embeddings Explained: A Visual and Intuitive Guide
- Oct 2026Is 'Attention' the Essence of Intelligence?
- 97
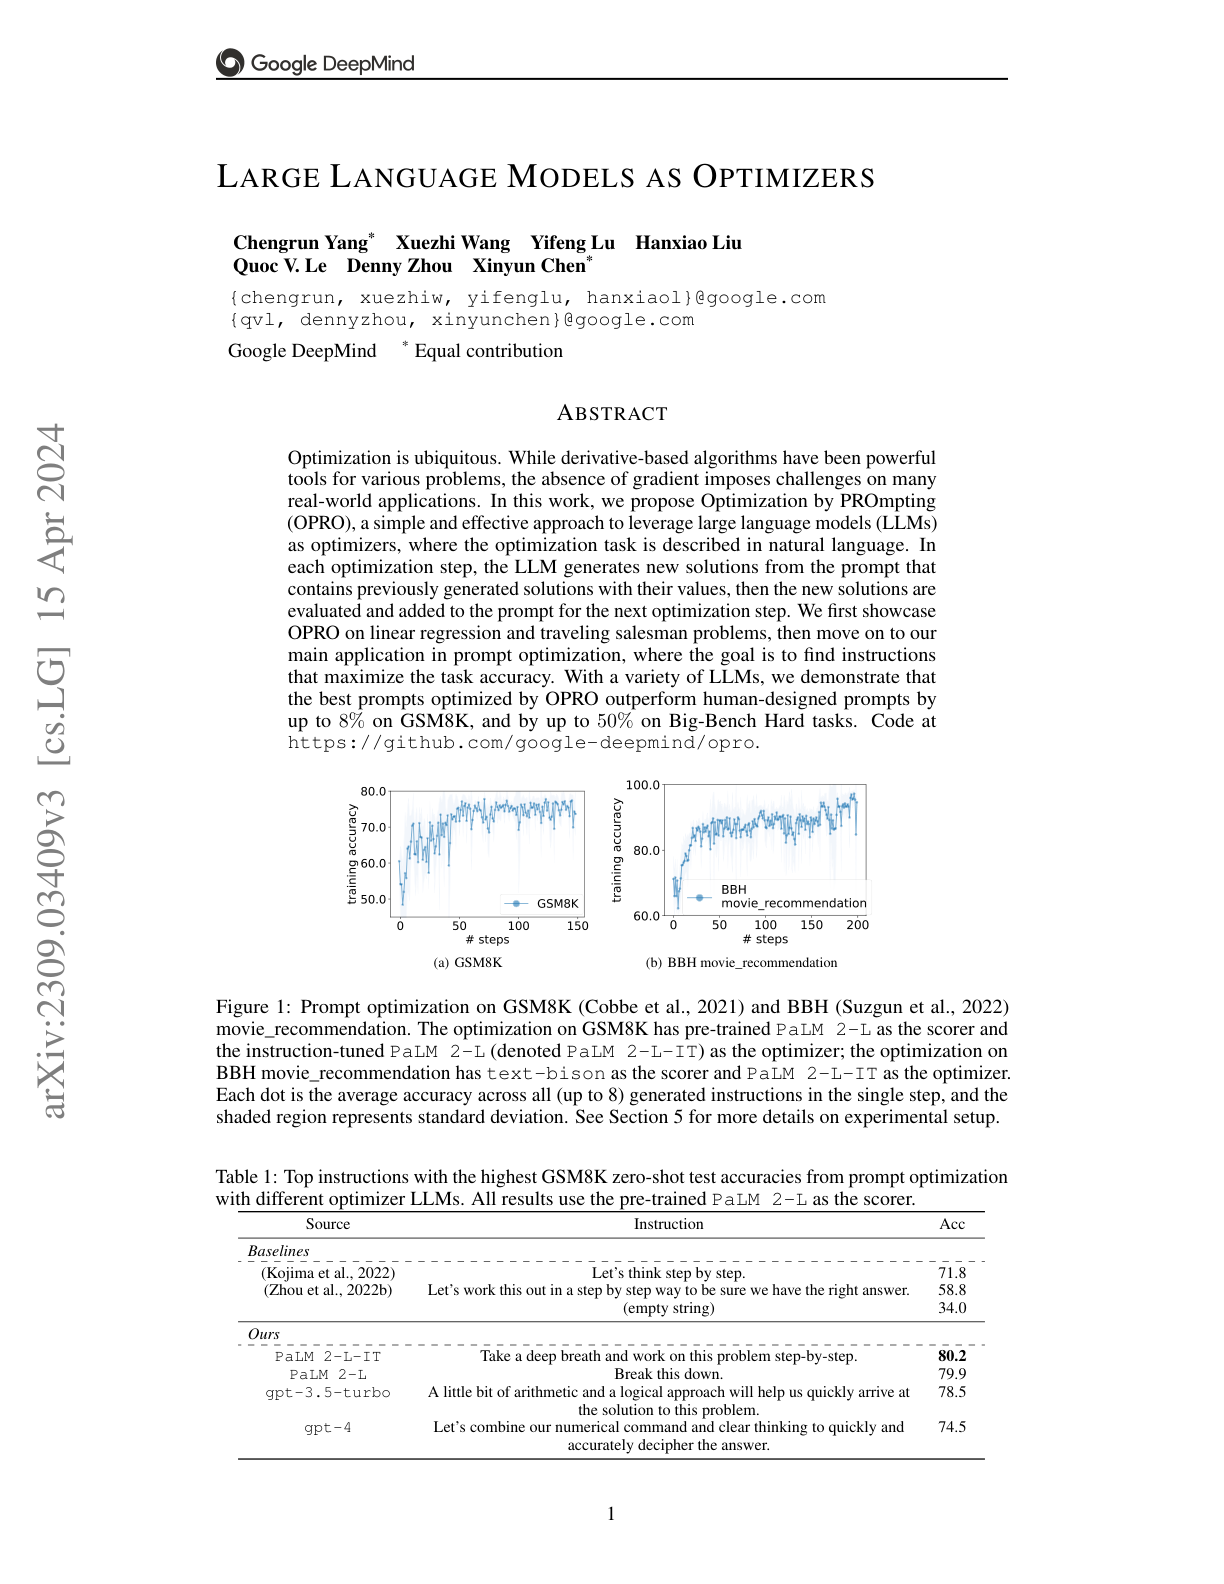
Large Language Models as Optimizers
Hacker News threads
- 98
Double Descent Demystified: Identifying, Interpreting & Ablating the Sources of a Deep Learning Puzzle
Hacker News threads
- 99
MusicLM: Generating Music From Text
Hacker News threads
- 100
The Poison of Alignment
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.