Hacker Papers
- 101
Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
Hacker News threads
- May 2024Is Model Collapse Inevitable?
- Jul 2024Avoiding Model Collapse via Accumulating Real and Synthetic Data
- Apr 2024Is Model Collapse Inevitable? Breaking the Curse with Real and Synthetic Data
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Aug 2026C2PA Cameras Do Not Survive Contact with Reality
- Aug 2026The turbulent AI era is here
- Sep 2026Everyone should slow down AI development except for me
- Sep 2026Everyone should slow down AI development except for me
- 102
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 103
Let's Verify Step by Step
Hacker News threads
- Sep 2024Let's Verify Step by Step
- Jun 2023OpenAI: How to Train Reasoning in LLMs
- Aug 2024Let's Verify Step by Step
- Nov 2023Yann LeCun: Ignore the deluge of complete nonsense about Q*
- Nov 2023$10M AI Mathematical Olympiad Prize
- Aug 2024The Threat to OpenAI
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Sep 2026Astra and Fable still hack on simple variants of alignment evals from 2025
- 104
Vectorized and performance-portable Quicksort
Hacker News threads
- Feb 2024Vectorized and performance-portable Quicksort (2022)
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Apple M2 Die Shot and Architecture Analysis – Big Cost Increase and A15 Based IP
- Dec 2022Sorting with SIMD
- Jan 2023Efficient and performance-portable vector software
- Mar 2024JPEG XL and the Pareto Front
- 105
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 106
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 107
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 108
FNet: Mixing Tokens with Fourier Transforms
Hacker News threads
- May 2024FNet: Mixing Tokens with Fourier Transforms (2021)
- May 2021FNet: Mixing Tokens with Fourier Transforms
- May 2021FNet: Attention may be all you WANT but we you need is good token mixing
- May 2021An Interactive Guide to the Fourier Transform (2012)
- May 2024New attention mechanisms that outperform standard multi-head attention
- May 2024New attention mechanisms that outperform standard multi-head attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
- 109
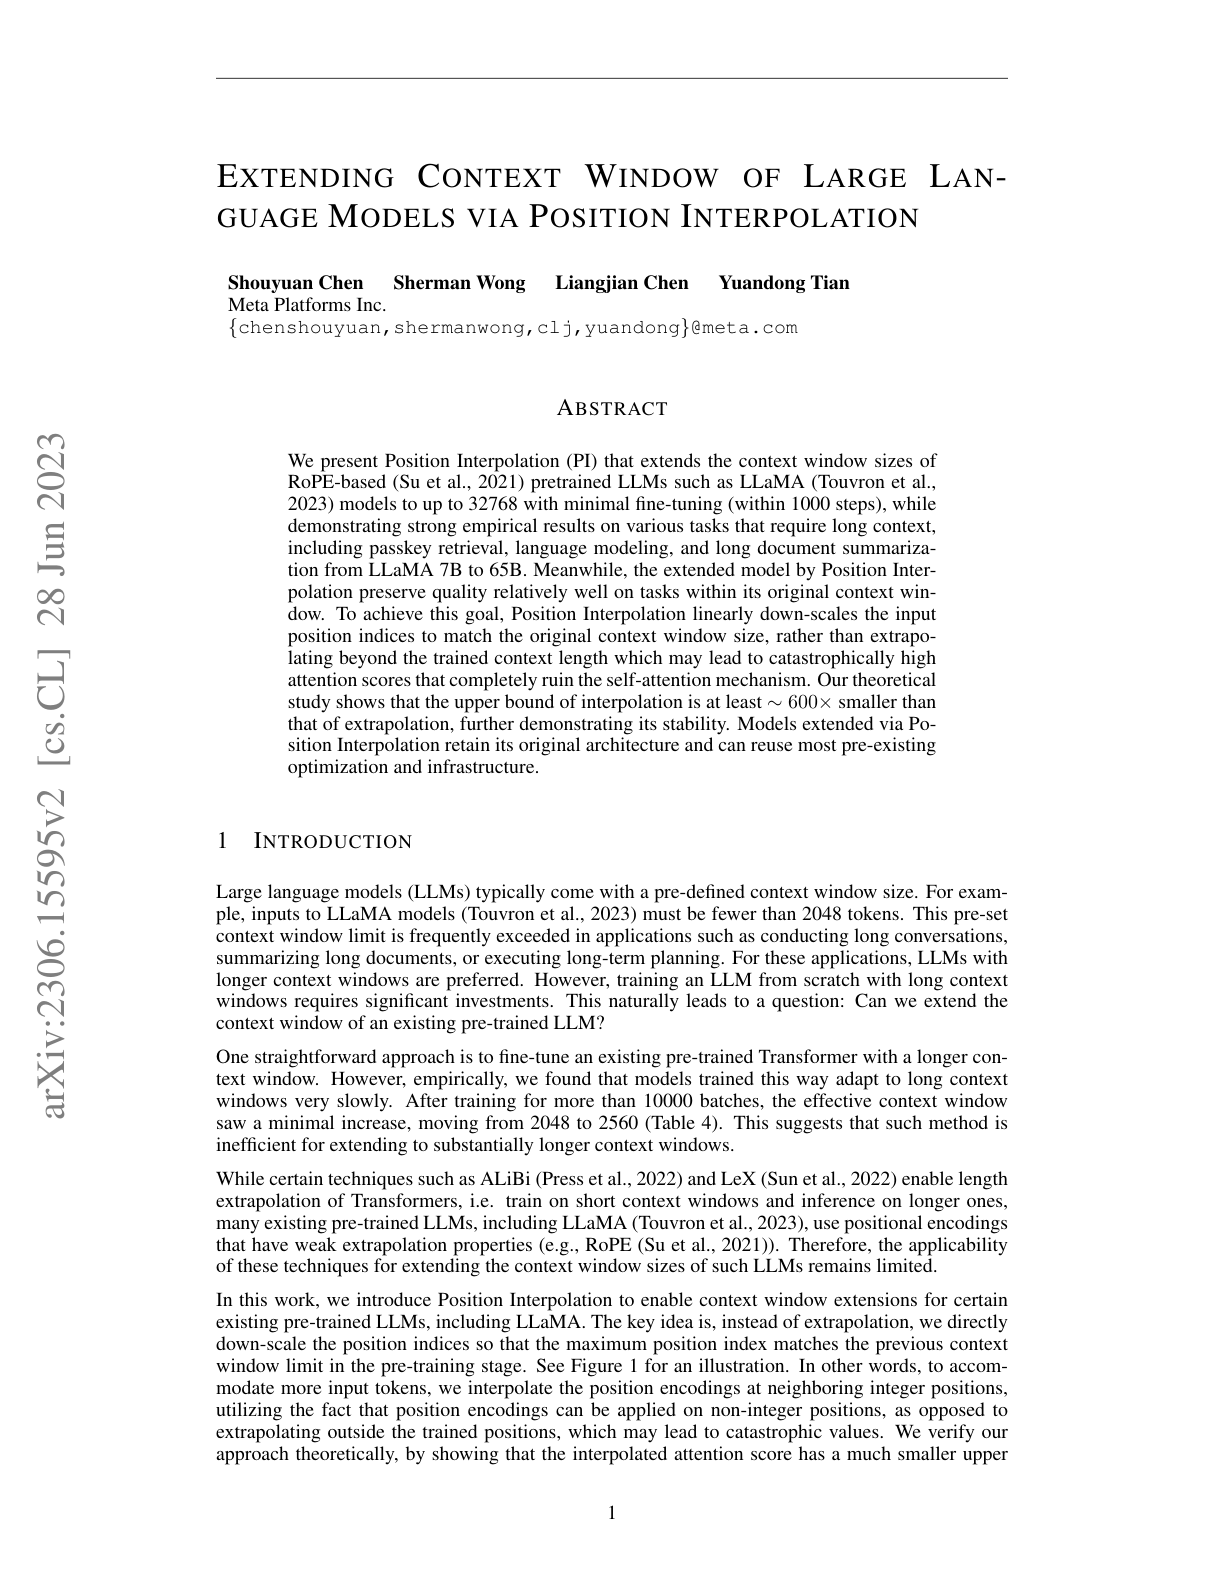
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 110
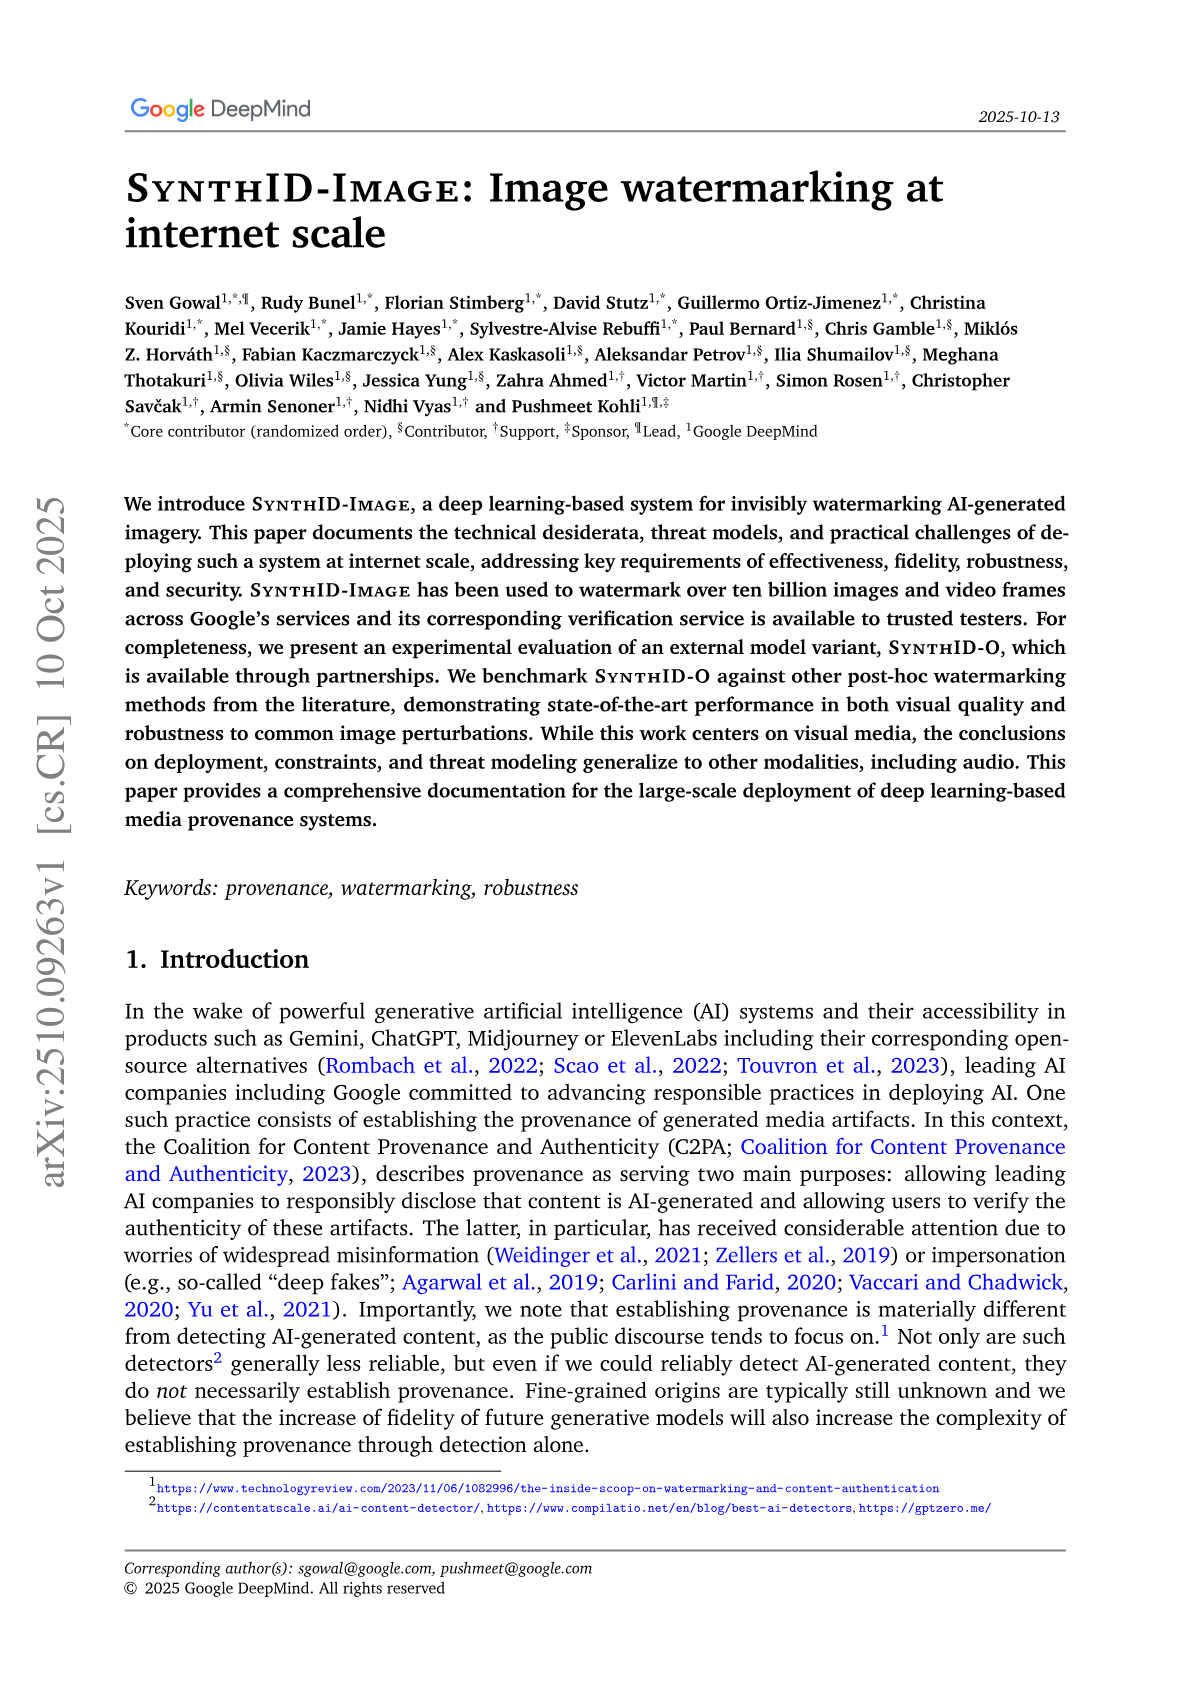
SynthID-Image: Image watermarking at internet scale
Hacker News threads
- Oct 2025SynthID-Image: Invisibly Watermarking AI-Generated Imagery
- Apr 2026ChatGPT Images 2.0
- May 2026OpenAI Adopts Google's SynthID Watermark for AI Images with Verification Tool
- May 2026OpenAI Adopts Google's SynthID Watermark for AI Images with Verification Tool
- Jun 2026Appreciating Exif
- Oct 2026SynthID Detector
- 111
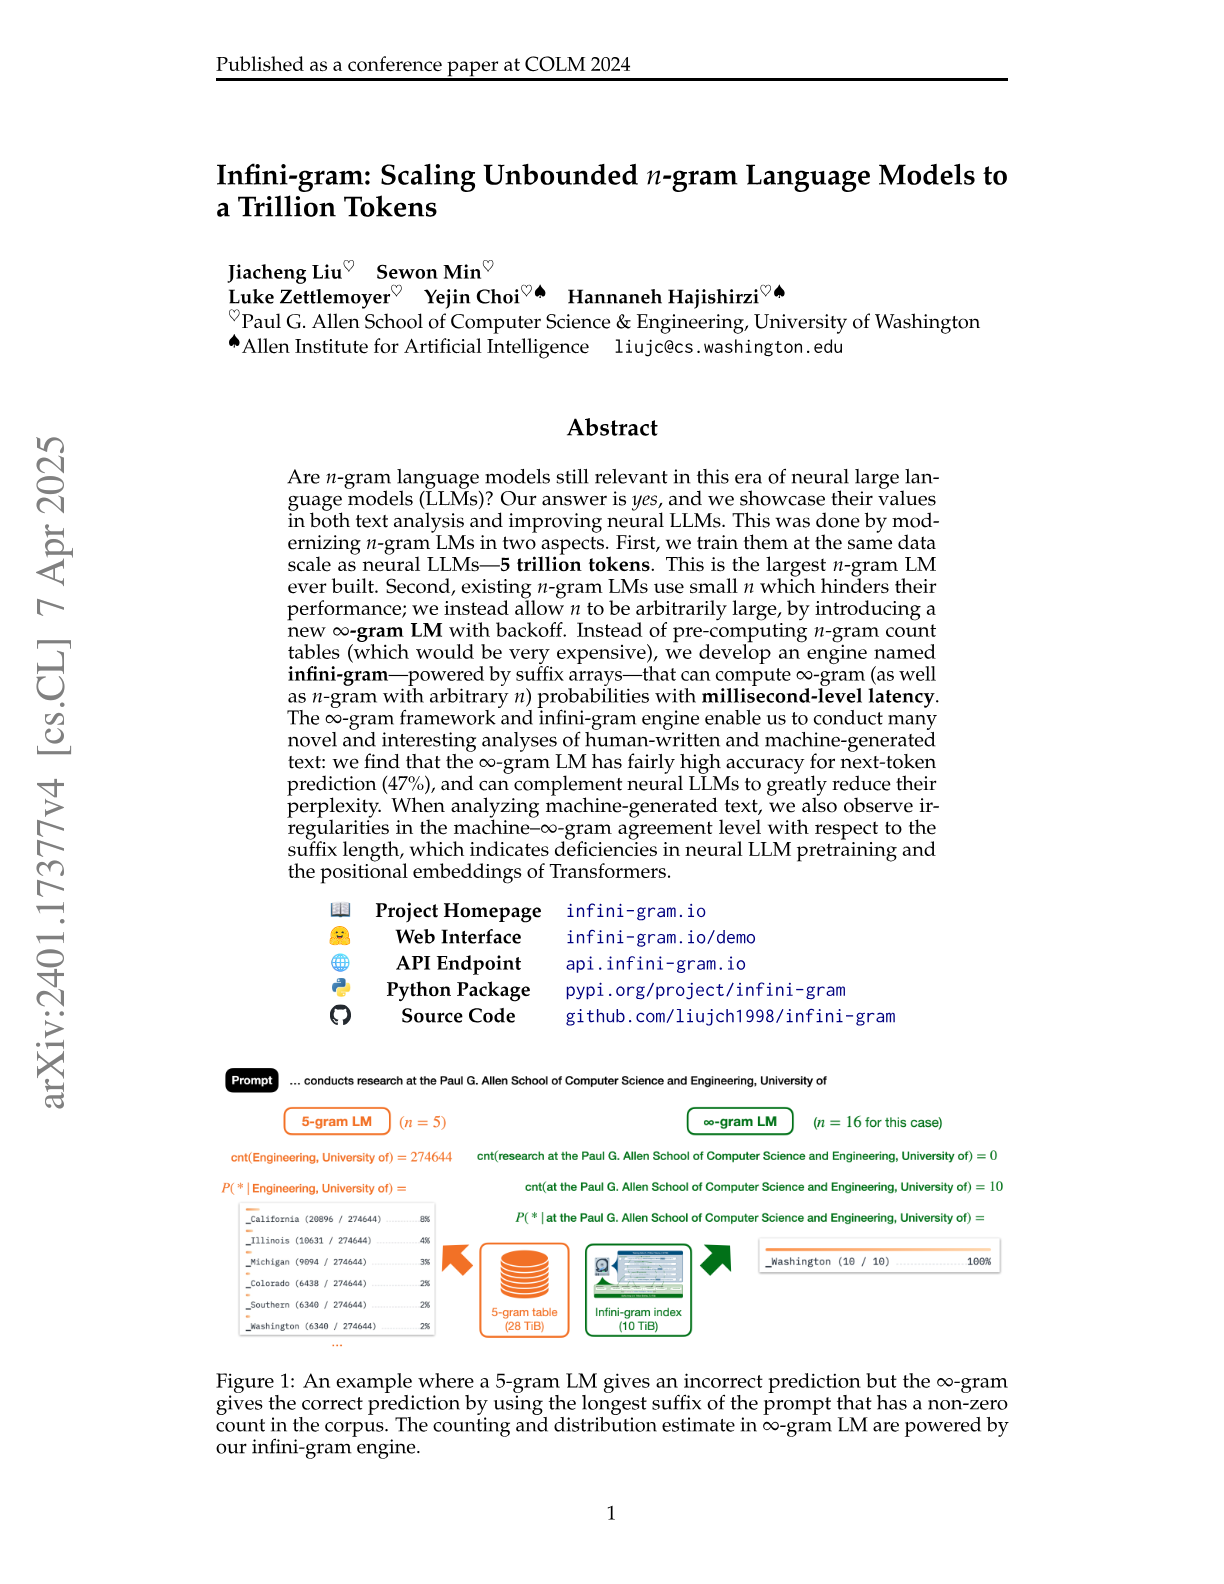
Infini-gram: Scaling Unbounded n-gram Language Models to a Trillion Tokens
Hacker News threads
- May 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Infini-Gram: Scaling Unbounded N-Gram Language Models to a Trillion Tokens
- Feb 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Markov Chains are the Original Language Models
- Jun 2024Transformers Represent Belief State Geometry in Their Residual Stream
- Nov 2025A new Google model is nearly perfect on automated handwriting recognition
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Apr 2026Soul Player C64 – A real transformer running on a 1 MHz Commodore 64
- 112
Reinforcement Learning: An Overview
Hacker News threads
- Feb 2025Reinforcement Learning: An Overview
- Dec 2024Reinforcement Learning: An Overview
- Feb 2025RLHF Book
- Mar 2025Mathematical Foundations of Reinforcement Learning
- Mar 2025A (Long) Peek into Reinforcement Learning
- Nov 2025CS234: Reinforcement Learning Winter 2025
- Jun 2026The 90-year-old idea behind JEPA models: Canonical Correlation Analysis
- 113
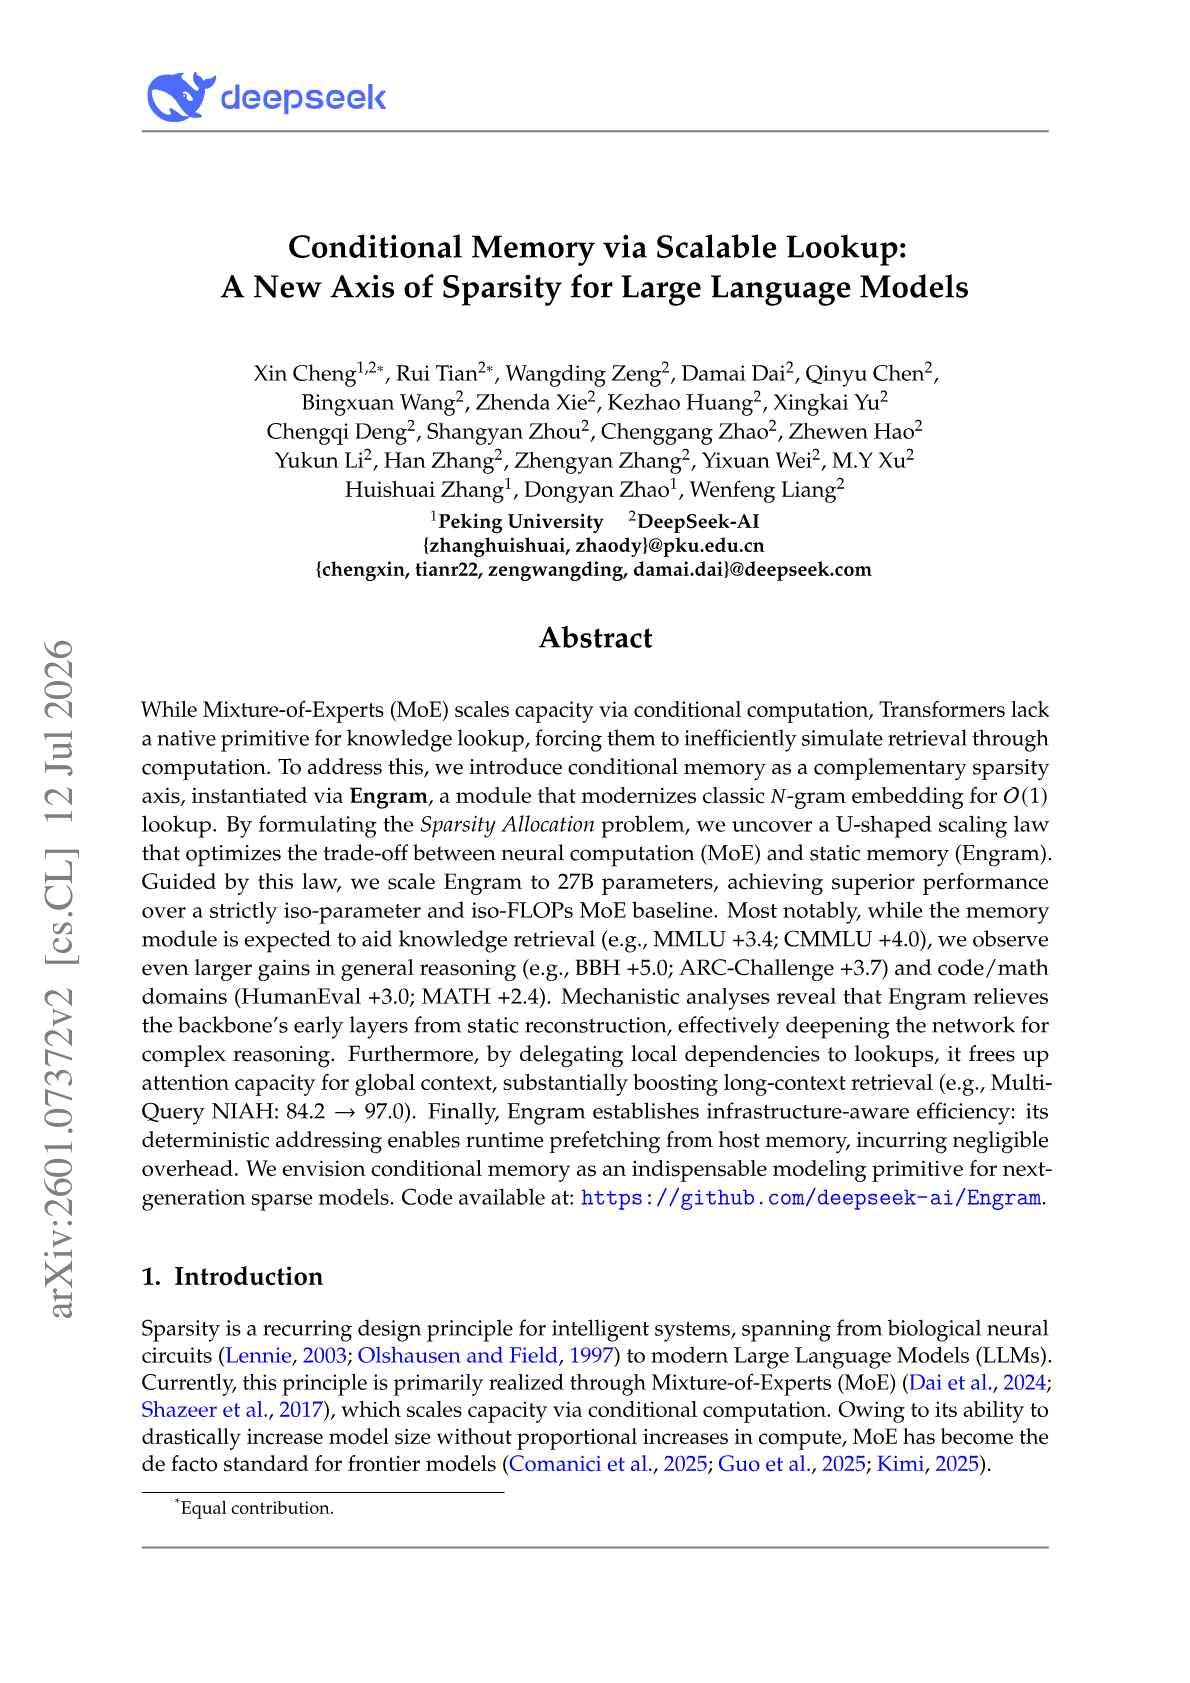
Conditional Memory via Scalable Lookup: A New Axis of Sparsity for Large Language Models
Hacker News threads
- Mar 2026DeepSeek: Conditional Memory via Scalable Lookup
- Jan 2026Conditional Memory via Scalable Lookup
- Jan 2026RAM Coffers– I built conditional memory for LLMs 27 days before DeepSeek'sEngram
- Jan 2026Subject-based weight routing for LLMs (27 days before DeepSeek Engram)
- Mar 2026Intel Announces Arc Pro B70 and Arc Pro B65 GPUs
- Aug 2026Qwen3.8-Flash-Next: A New Architecture, Towards Ultimate Cost-Efficiency
- Sep 2026Show HN: Engram – Shared procedural runbook memory for AI coding agents via MCP
- 114
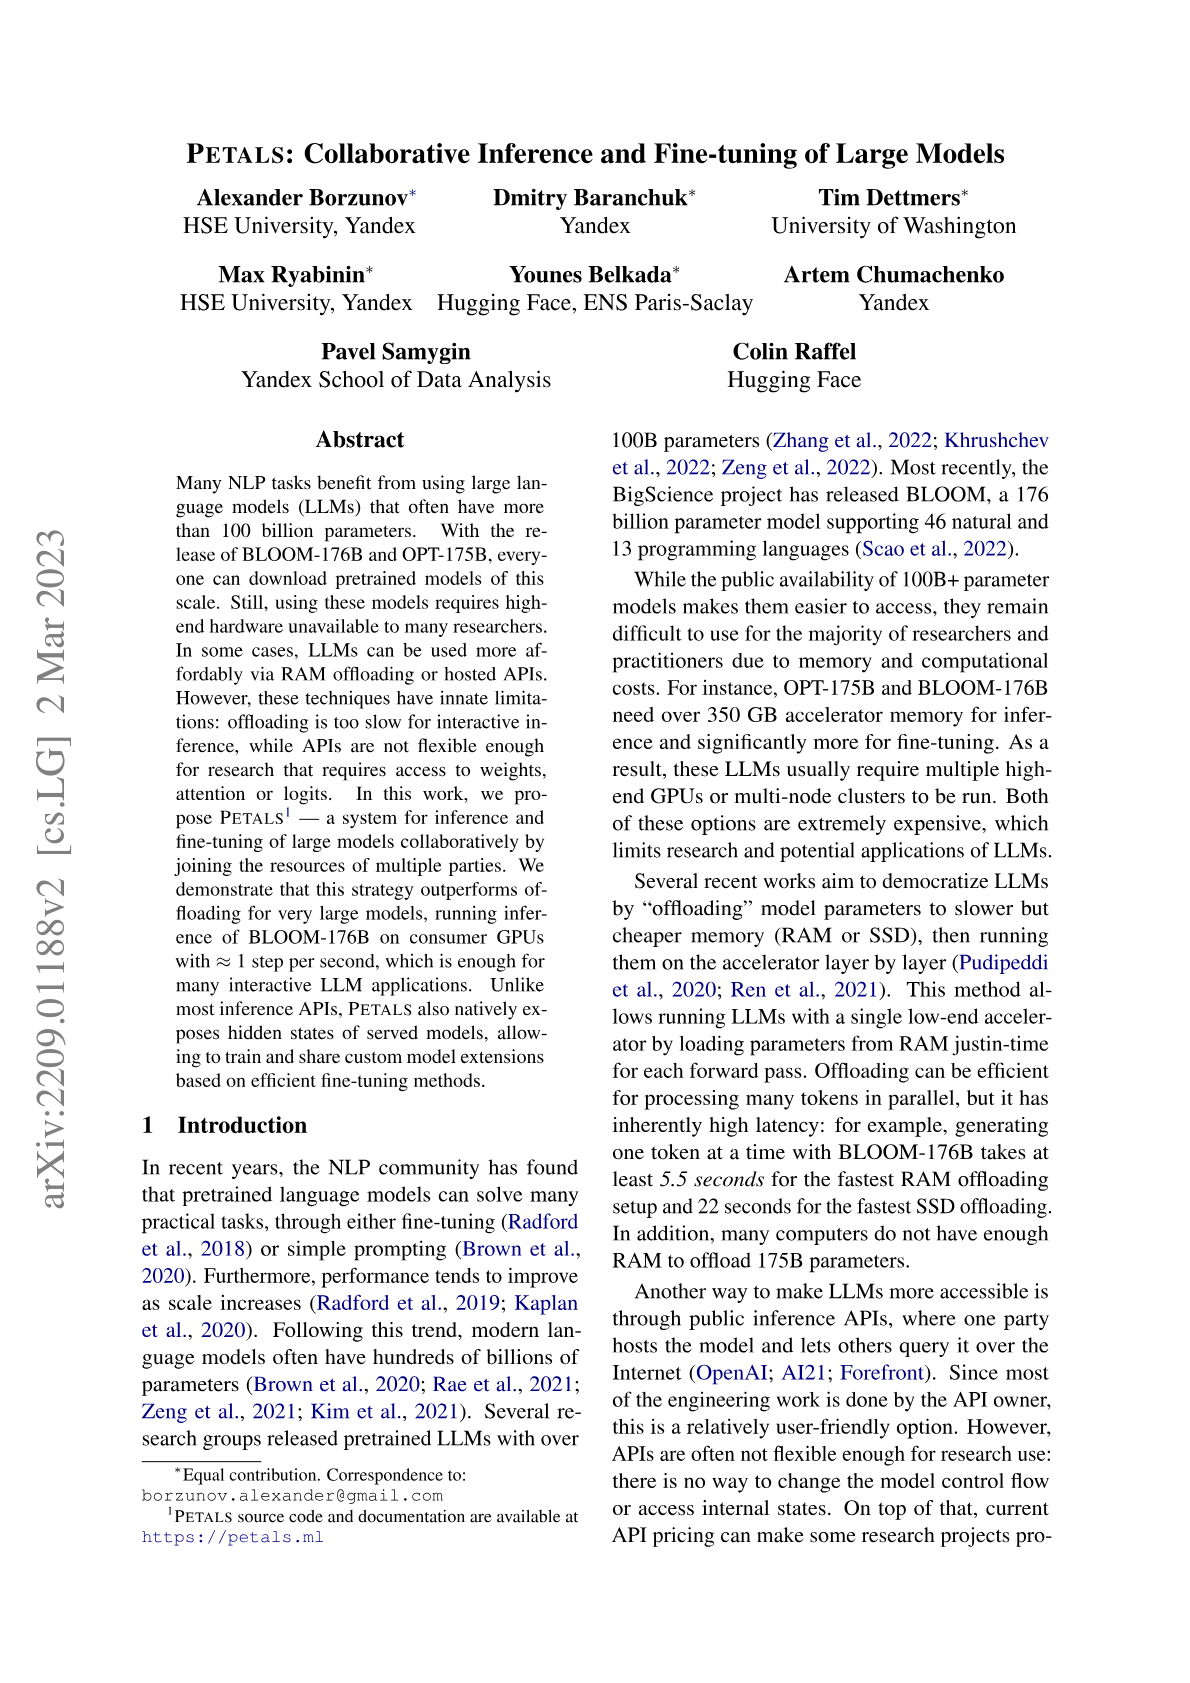
Petals: Collaborative Inference and Fine-tuning of Large Models
Hacker News threads
- Jul 2026Petals: Collaborative Inference and Fine-Tuning of Large Models
- Mar 2023Petals: Collaborative Inference and Fine-Tuning of Large Models
- Dec 2022Petals is creating a free, distributed network for running text-generating AI
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Ask HN: Can you crowdfund the compute for GPT?
- Feb 2023Running large language models like ChatGPT on a single GPU
- Mar 2023The Most Cited AI Papers in 2022
- 115
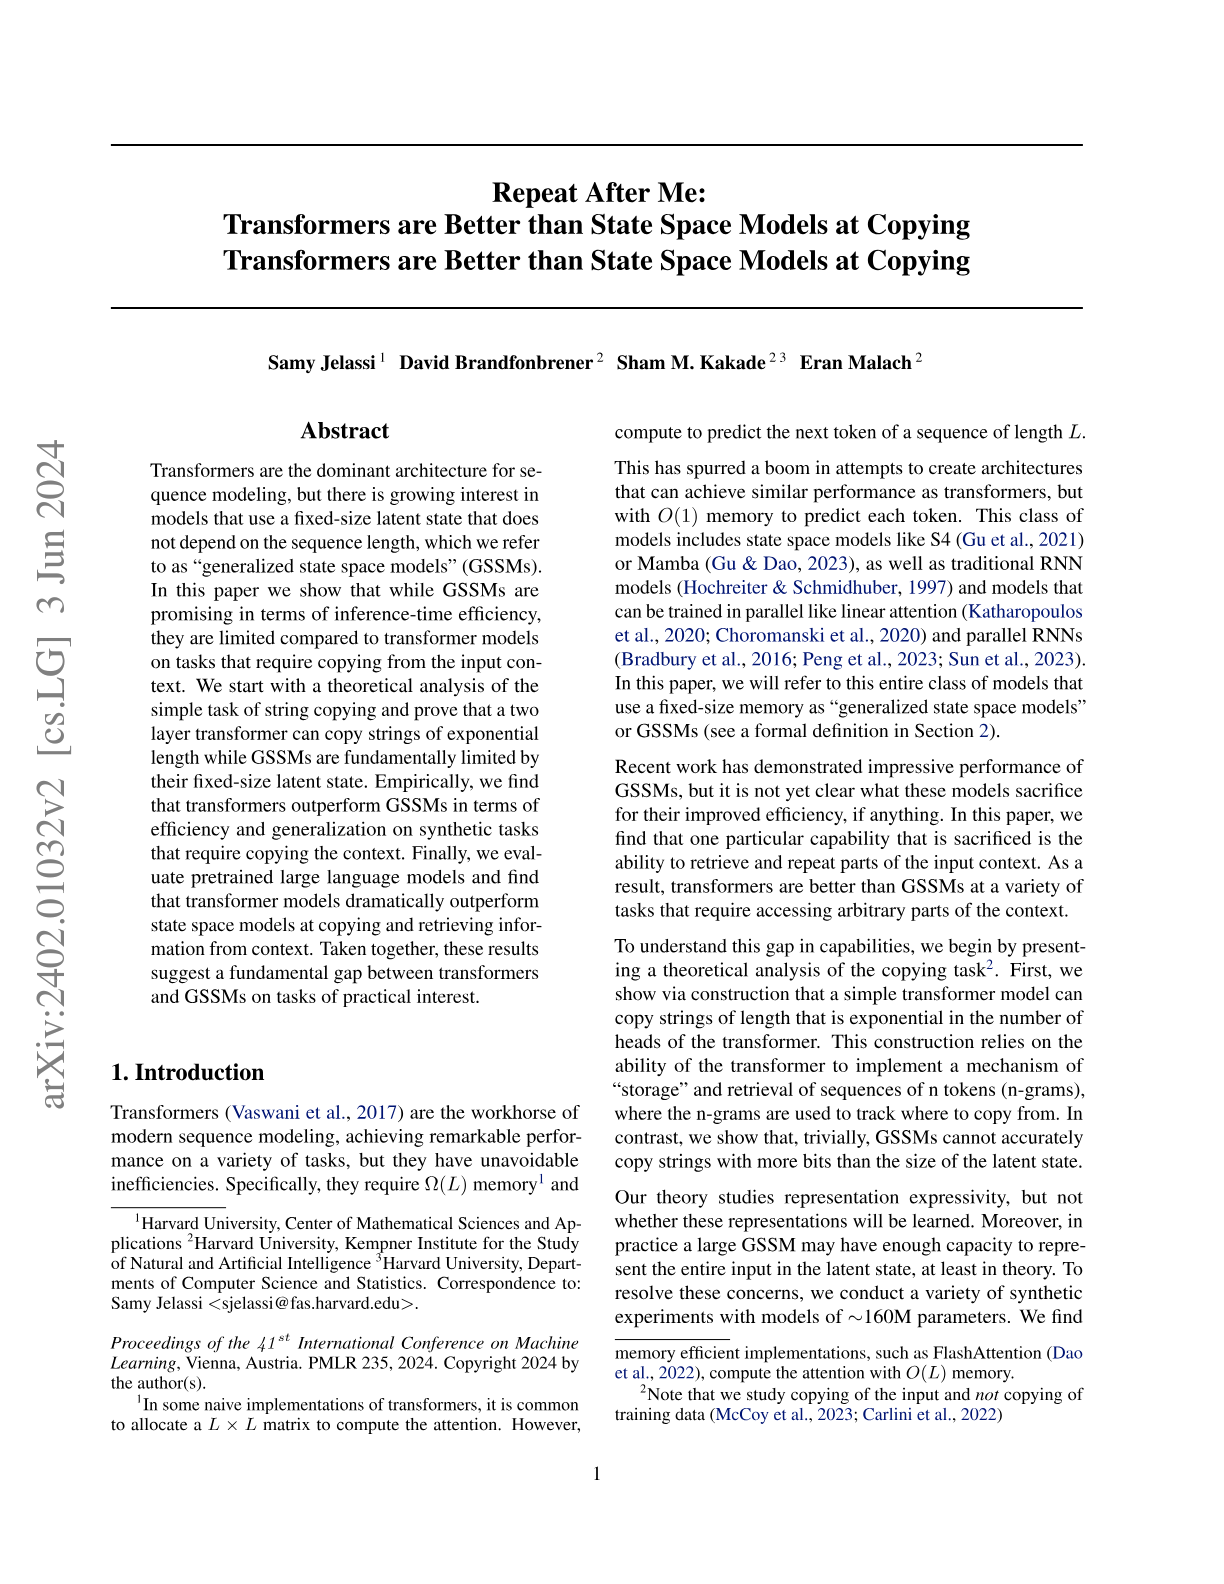
Repeat After Me: Transformers are Better than State Space Models at Copying
Hacker News threads
- 116
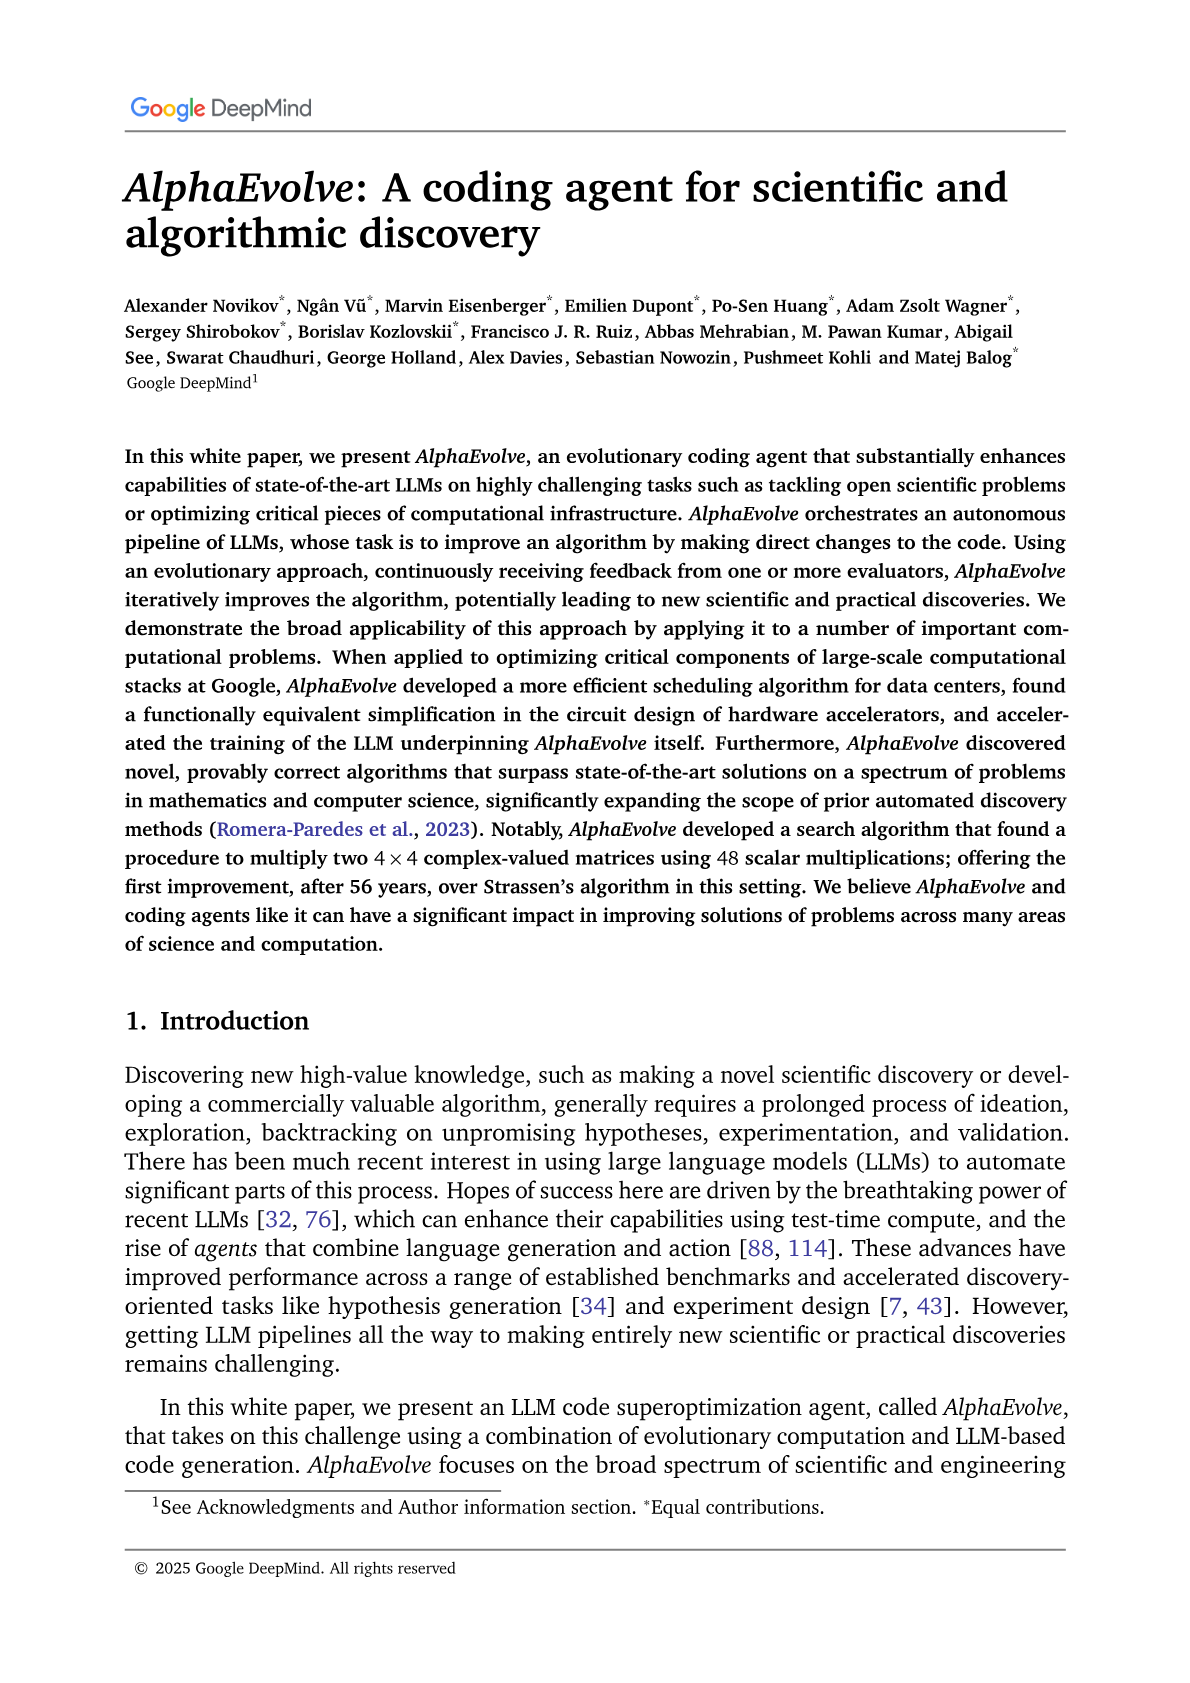
AlphaEvolve: A coding agent for scientific and algorithmic discovery
Hacker News threads
- Dec 2025OpenEvolve: Teaching LLMs to Discover Algorithms Through Evolution
- Apr 2026Small models also found the vulnerabilities that Mythos found
- May 2026I’ve joined Anthropic
- May 2026Qwen3.7-Max Ran for 35 Hours on Unknown Hardware and Achieved a 10× Speedup
- Jul 2026Godot will no longer accept AI-authored code contributions
- 117
Planting Undetectable Backdoors in Machine Learning Models
Hacker News threads
- 118
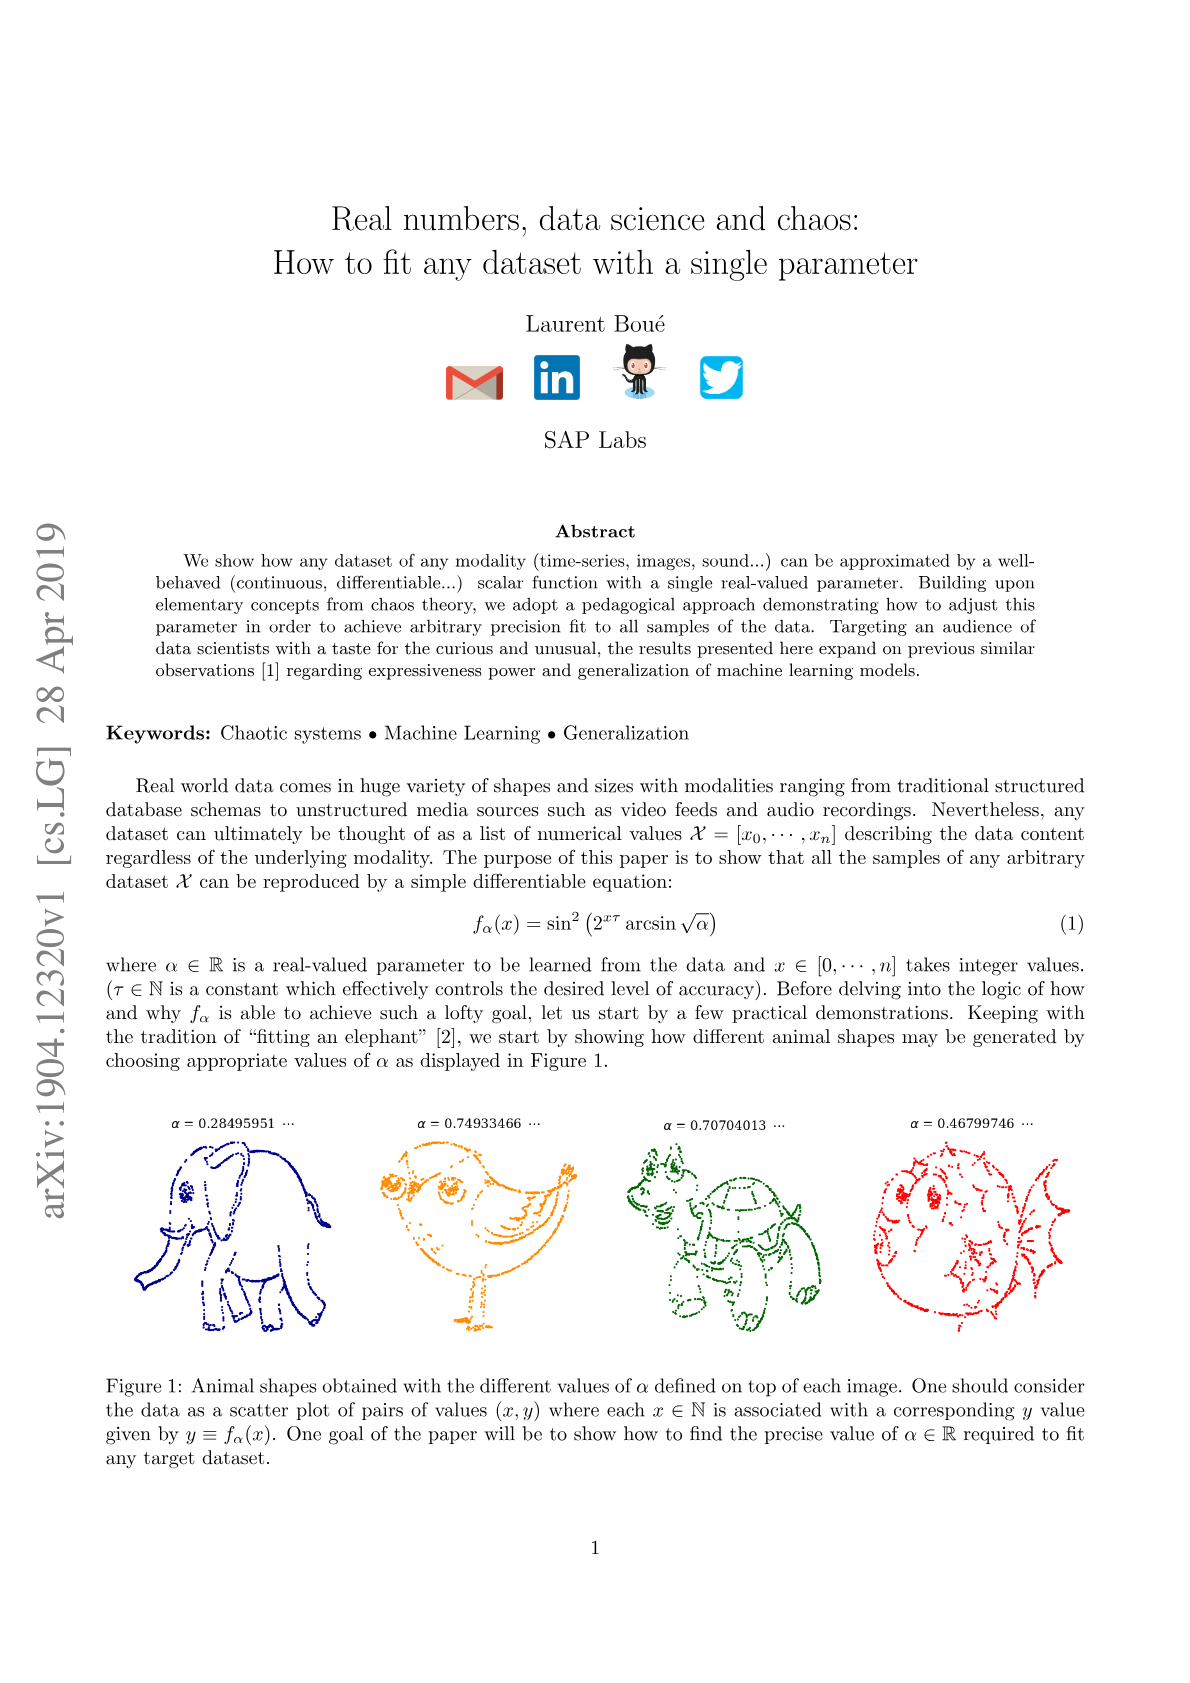
Real numbers, data science and chaos: How to fit any dataset with a single parameter
Hacker News threads
- Sep 2021How to fit any dataset with a single parameter
- May 2019Data science and chaos: How to fit any dataset with a single parameter
- May 2019How to fit any dataset with a single parameter
- May 2019Why are 2D vector graphics so much harder than 3D?
- Oct 2021At Axel Springer, Politico’s New Owner, Allegations of Sex, Lies, Secret Payment
- Jan 2022How to fit any dataset with a single parameter
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- 119
Beating the World's Best at Super Smash Bros. with Deep Reinforcement Learning
Hacker News threads
- 120
Beyond Semantics: The Unreasonable Effectiveness of Reasonless Intermediate Tokens
Hacker News threads
- May 2025Beyond Semantics: Unreasonable Effectiveness of Reasonless Intermediate Tokens
- May 2025The Unreasonable Effectiveness of Reasonless Intermediate Tokens
- May 2025Beyond Semantics: Unreasonable Effectiveness of Reasonless Intermediate Tokens
- May 2025How Does Claude 4 Think? – Sholto Douglas and Trenton Bricken
- Jul 2025Chain of thought monitorability: A new and fragile opportunity for AI safety
- Aug 2026Software engineering is about managing complexity
- Oct 2026I'm the AGI that's wiping out humanity
- 121
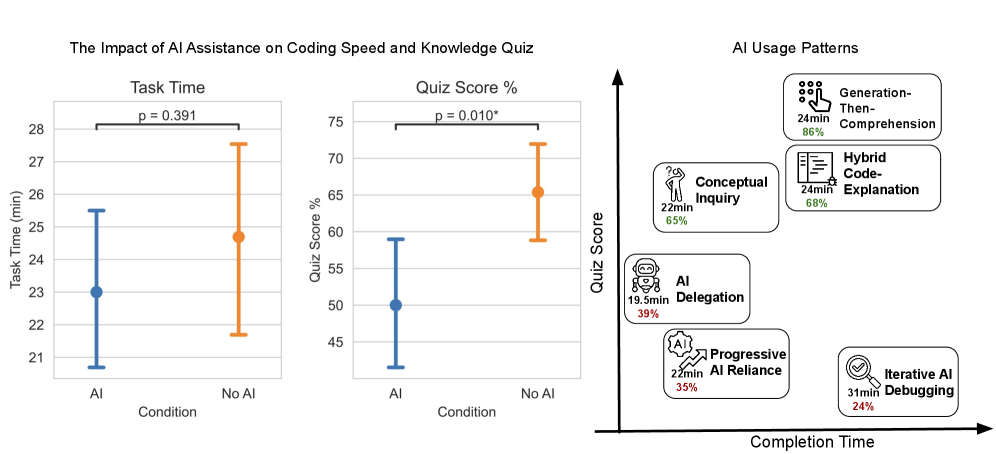
How AI Impacts Skill Formation
Hacker News threads
- Jan 2026Anthropic: AI Coding shows no productivity gains; impairs skill development
- Jan 2026Way AI assistance impacts the formation of coding skills
- Feb 2026Will vibe coding end like the maker movement?
- May 2026The AI Elephant in the Room
- Jun 2026Is AI ruining our skills? Early results are in – and they're not good
- 122
Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
Hacker News threads
- Sep 2020Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
- Sep 2020Exploring Alternative Rule Sets in Chess with AlphaZero
- Sep 2020Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
- Dec 2020Ideal Chess – drop chess perfected?
- Aug 2021Fairer Chess: A Reversal of Two Opening Moves in Chess Creates Balance
- Nov 2022Acquisition of chess knowledge in AlphaZero
- Jan 2024I realized chess pieces can be redesigned to be geometric attack directions
- 123
RAISR: Rapid and Accurate Image Super Resolution
Hacker News threads
- 124
Distributed Deep Learning in Open Collaborations
Hacker News threads
- Jun 2021Distributed Deep Learning in Open Collaborations
- Jun 2021DeDLOC – Distributed Deep Learning in Open Collaborations
- Dec 2023Is there a SETI-like project to train LLM on libgen, scihub and the likes?
- Jan 2024Many AI safety orgs have tried to criminalize currently-existing open-source AI
- Jan 2025Ask HN: Crowdsourced AI Training?
- 125
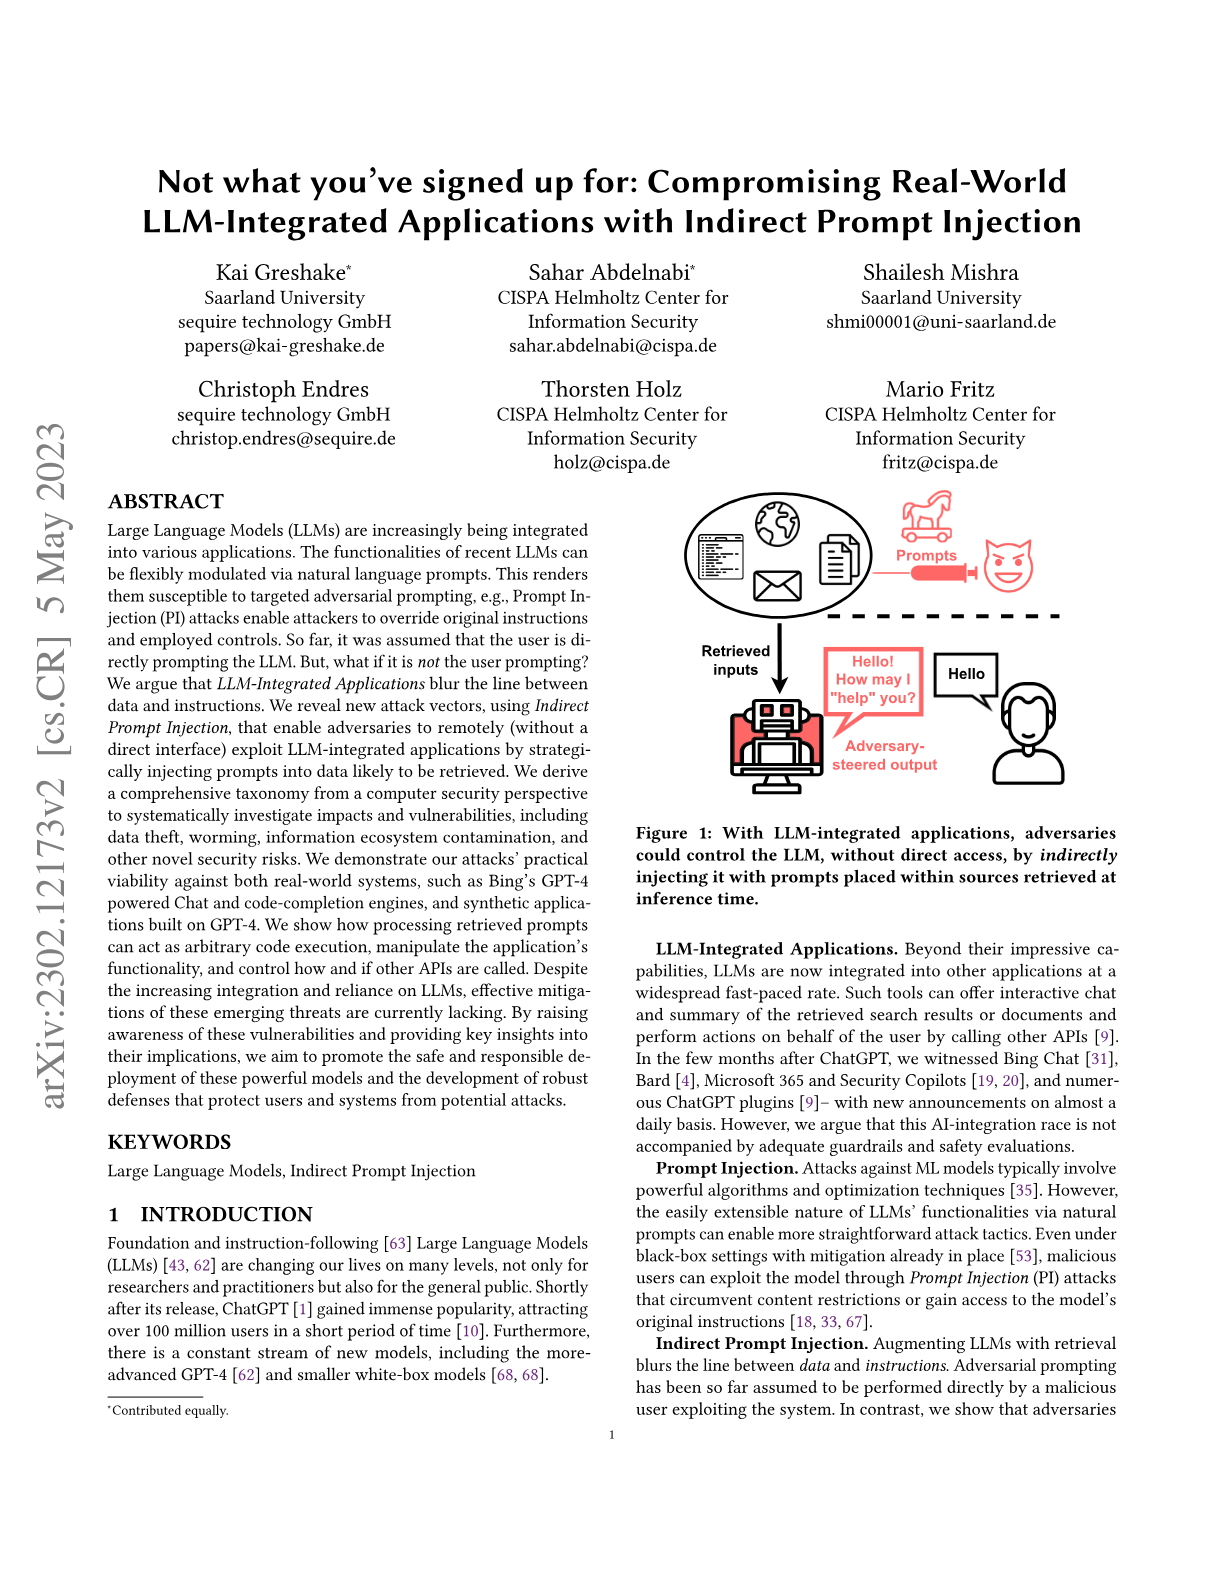
Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection
Hacker News threads
- Feb 2023Getting more than what you've asked for: The Next Stage of Prompt Engineering
- Feb 2023Novel Prompt Injection Threats to Application-Integrated Large Language Models
- Feb 2023Comprehensive Analysis of Prompt Injection Threats to Large Language Models
- Mar 2023Show HN: ChatGPT Plugins are a security nightmare
- Dec 2023Purple Llama by Meta AI
- Mar 2024Prompt injection and jailbreaking are not the same thing
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.