Hacker Papers
- 101
FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
Hacker News threads
- Jun 2022Flash Attention accelerates GPT2 3x
- Apr 2023Flash Attention
- May 2023FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
- Dec 2022GPT3/DALL-E2 in Discord, chat like ChatGPT, generate images, and more
- Apr 2023The Coming of Local LLMs
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- May 2023
- Dec 2023LLM in a Flash: Efficient LLM Inference with Limited Memory
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Mar 2024Show HN: Flash Attention in ~100 lines of CUDA
- Apr 2025400x AI Acceleration
- 102
Learning Transferable Visual Models From Natural Language Supervision
Hacker News threads
- Mar 2021The End of Tesla’s Dominance May Be Closer Than It Appears
- Aug 2021Machine learning won't solve natural language understanding
- Apr 2022A few things to try with DALL·E
- Apr 2022How DALL-E 2 Works
- Mar 2024Is Cosine-Similarity of Embeddings Really About Similarity?
- Aug 2024Artists score major win in copyright case against AI art generators
- Jan 2025Don't use cosine similarity carelessly
- Mar 2025Ask HN: Any truly multi-modal transformer architectures?
- 103
High-Resolution Image Synthesis with Latent Diffusion Models
Hacker News threads
- Aug 2022Build Your Own Imagen Text-to-Image Model
- Sep 2022Stable Diffusion forming images from text: image snapshots at each step
- Sep 2022A Web UI for Stable Diffusion
- Mar 2023The Most Cited AI Papers in 2022
- Jul 2023Stanford A.I. Courses
- Feb 2024The VAE Used for Stable Diffusion Is Flawed
- Jul 2024AI models collapse when trained on recursively generated data
- Dec 2025Show HN: I remade my website in the Sith Lord Theme and I hope it's fun
- 104
Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity
Hacker News threads
- Jan 2021Google breaks the trillion-parameter ceiling with the Switch Transformer
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Sparsity
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Simple Sparsity
- Aug 2021Program Synthesis with Large Language Models
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Jan 2022The Illustrated Retrieval Transformer
- Mar 2023GPT-4
- Jun 2023GPT4 is 8 x 220B params = 1.7T params
- Jul 2023GPT-4 is getting worse over time, not better
- Oct 2023Decomposing Language Models into Understandable Components
- May 2026Granite 4.1: IBM's 8B Model Matching 32B MoE
- 105
Adam: A Method for Stochastic Optimization
Hacker News threads
- Oct 2015Adam's method for stochastic optimization
- Jan 2017A New Batch of Deep Learning Startups to Watch for in 2017
- Oct 2017Variational Inference and Deep Learning: A New Synthesis [pdf]
- Feb 2023Exclusive Q&A John Carmack’s ‘Different Path’ to Artificial General Intelligence
- Jul 2023A Theory on Adam Instability in Large-Scale Machine Learning
- May 2024xLSTM: Extended Long Short-Term Memory
- Oct 2024Anthropic hires OpenAI co-founder Durk Kingma
- Mar 2025The PhD Metagame: Don't try to reform science – not yet
- Oct 2025Researchers Discover the Optimal Way to Optimize
- 106
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 107
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 108
Twitter mood predicts the stock market
Hacker News threads
- May 2011Twitter mood predicts the stock market.
- Nov 2010Twitter mood predicts the stock market
- May 2011Twitter mood predicts the stock market
- Oct 2010Twitter Mood Predicts The Stock Market
- Nov 2010Can LinkedIn predict when companies are in trouble?
- Dec 2010Hedge fund to use Twitter to predict stock market
- Jul 2011MongoDB is the New MySQL
- Mar 2012What you could do if you were Google and had their databases
- May 2012Looking At The World Through Twitter Data
- Sep 2012Twitter is a tragic tale
- Mar 2014Can the Bloomberg Terminal be "Toppled"?
- 109
Practical Bayesian Optimization of Machine Learning Algorithms
Hacker News threads
- Apr 2015Practical Bayesian Optimization of Machine Learning Algorithms (2012)
- May 2015PRACTICAL BAYESIAN OPTIMIZATION OF MACHINE LEARNING ALGORITHMS [pdf]
- Jul 2012Machine learning for the impatient: algorithms tuning algorithms
- Nov 2012How deep learning on GPUs wins datamining contest without feature engineering
- Jan 2013Ersatz - Deep neural networks in the cloud
- Nov 2013Machine learning is easier than it looks
- Dec 2013Hyperopt: Optimize your machine learning parameters automagically
- Jun 2015Whetlab.com: API for Baysian optimization of hyperparameters
- Jan 2018Show HN: A radically more scalable alternative to Bayesian Optimization
- Jul 2018Troubling Trends in Machine Learning Scholarship
- 110
The Loss Surfaces of Multilayer Networks
Hacker News threads
- Jan 2019The Loss Surfaces of Multilayer Networks
- Mar 2015Deep Learning vs. Machine Learning vs. Pattern Recognition
- Jun 2015What's Wrong with Deep Learning?
- Aug 2015Machine Learning: Curse of Dimensionality
- Feb 2016AI is transforming Google search – the rest of the web is next
- Aug 2016What’s Next for Artificial Intelligence
- May 2017Breaking Glass in Infinite Dimensions
- Dec 2017An Interview with an Anonymous Data Scientist (2016)
- Aug 2020Differentiable Control Problems
- 111
ByT5: Towards a token-free future with pre-trained byte-to-byte models
Hacker News threads
- May 2022Teaching GPT-3 to reverse words
- Dec 2022ChatGPT, Rot13, and Daniel Kahneman
- Mar 2023Cerebras-GPT vs. LLaMA AI Model Performance Comparison
- Apr 2023A Baby GPT
- Jun 2023Understanding GPT Tokenizers
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024Something weird is happening with LLMs and chess
- Jun 2026Data Compression Explained
- 112
TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning with Hardware Support for Embeddings
Hacker News threads
- Apr 2023TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning
- Apr 2023TPU v4 provides exaFLOPS-scale ML with industry-leading efficiency
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023MTIA v1: Meta’s first-generation AI inference accelerator
- May 2023Nvidia DGX GH200: The First 100 Terabyte GPU Memory System
- May 2025OpenTPU: Open-Source Reimplementation of Google Tensor Processing Unit (TPU)
- Jun 2025Basic Facts about GPUs
- Oct 2026Homa: The end of TCP for AI clusters [video]
- 113
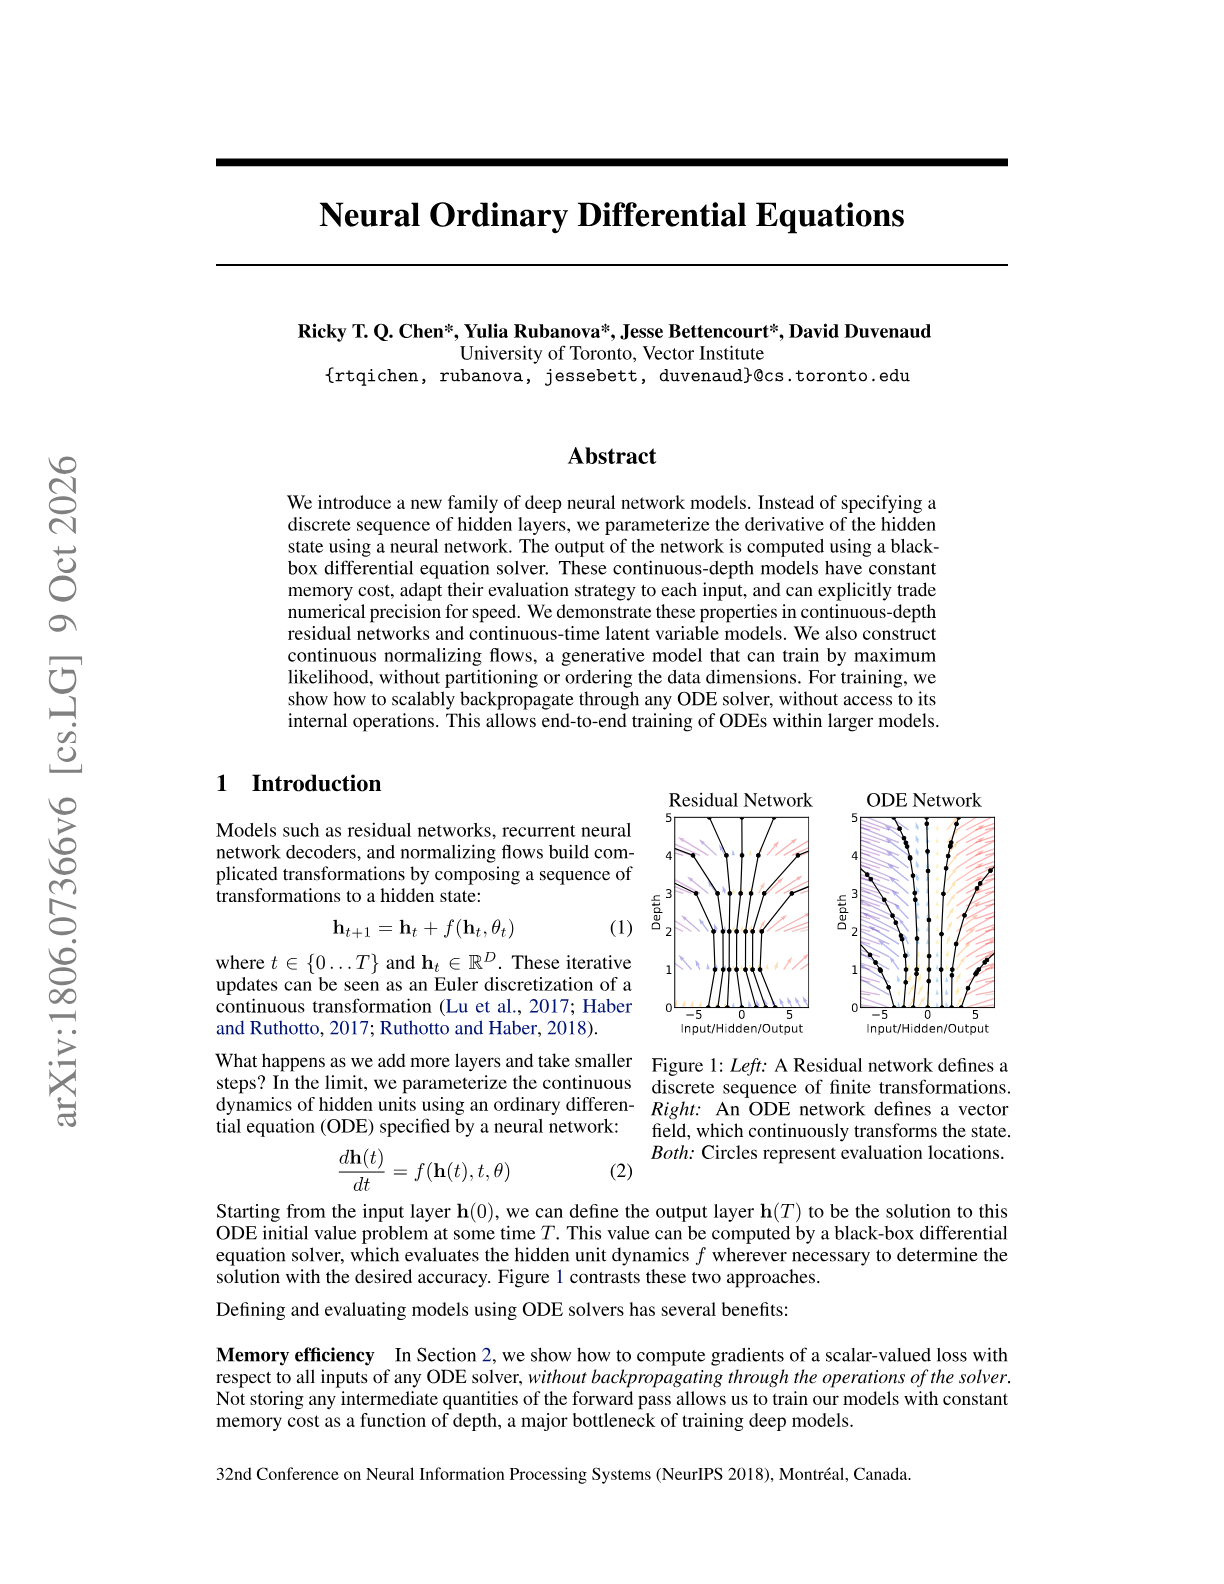
Neural Ordinary Differential Equations
Hacker News threads
- Dec 2018Neural Ordinary Differential Equations
- Dec 2018Neural Ordinary Differential Equations
- Jun 2018Polynomial Regression as an Alternative to Neural Nets
- Dec 2018Building a Language and Compiler for Machine Learning
- Jan 2019Tensor Considered Harmful Part 2
- Jan 2019Deep Learning State of the Art (2019) [video]
- Mar 2019‘A Swiss cheese-like material’ that can solve equations
- Sep 2019Deep Learning for Symbolic Mathematics
- Mar 2024Where is Noether's principle in machine learning?
- Mar 2024On the Double-Slit Experiment and Quantum Interference in the Wolfram Model (2020)
- 114
RL$^2$: Fast Reinforcement Learning via Slow Reinforcement Learning
Hacker News threads
- Jan 2017RL²: Fast Reinforcement Learning via Slow Reinforcement Learning (2016)
- Nov 2016Learning to reinforcement learn
- Nov 2016Learning to reinforcement learn
- Dec 2016OpenAI Universe
- Dec 2016Tool AIs want to be agent AIs
- Feb 2017Beating the World’s Best at Super Smash Bros. with Deep Reinforcement Learning
- Jun 2017Learning to Cooperate, Compete, and Communicate
- Mar 2019Gödel Machine
- Feb 2023What were the 40 research papers on the list Ilya Sutskever gave John Carmack?
- 115
Making AI Less "Thirsty": Uncovering and Addressing the Secret Water Footprint of AI Models
Hacker News threads
- Jan 2025"GPT training in U.S. data centers can evaporate 700k L of freshwater"
- Mar 2025Making AI Less Thirsty: Uncovering and Addressing the Secret AI Water Footprint
- Mar 2024Uncovering and Addressing the Secret Water Footprint of AI Models
- Jun 2023ChatGPT requires half a liter of water to have a conversation
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Apr 2025Bored of It
- Nov 2025AGI fantasy is a blocker to actual engineering
- May 2026AI Uses Less Water Than the Public Thinks
- Jun 2026Amazon Says Its Data Centers Use 2.5B Gallons of Water
- 116
Inherent Trade-Offs in the Fair Determination of Risk Scores
Hacker News threads
- Sep 2017Inherent Trade-Offs in the Fair Determination of Risk Scores
- Nov 2016Facebook is harming our democracy
- Nov 2016A machine learning approach to identifying thought markers of suicidal subjects
- Dec 2016Unexpected sources of bias in artificial intelligence
- Apr 2017Courts are using risk-assessment software to sentence criminals
- Jan 2018Algorithmic decision making and the cost of fairness (2017)
- Jun 2018AI at Google: our principles
- Sep 2018Making a racist AI without really trying (2017)
- Jun 2024Mozilla.ai did what? When silliness goes dangerous
- 117
Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
Hacker News threads
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Dec 2020Does GPT-2 Know Your Phone Number?
- Oct 2021A new link to an old model could crack the mystery of deep learning
- Mar 2022Deep learning is hitting a wall?
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Sep 2022Using GPT-3 to pathfind in random graphs
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- Oct 2023When Gradient Descent Is a Kernel Method
- 118
SLIDE : In Defense of Smart Algorithms over Hardware Acceleration for Large-Scale Deep Learning Systems
Hacker News threads
- Mar 2020Smart Algorithms beat Hardware Acceleration for Large-Scale Deep Learning
- Mar 2019In Defense of Smart Algorithms over Hardware Acceleration for Deep Learning
- Mar 2020Slide: In Defense of Smart Algorithms over Hardware Accelerated Deep Learning
- Mar 2020Deep Learning Breakthrough Sees One Xeon Destroying 8x Nvidia Tesla V100 GPUs
- Dec 2020Researchers propose faster, more efficient alternatives to backpropagation
- Apr 2021CPU-based algorithm trains deep neural nets up to 15 times faster than top GPU
- Apr 2021CPU-based algorithm trains deep neural nets up to 15 times faster than top GPU
- Aug 2021pHash – An open source perceptual hash library (2013)
- Oct 2021New features coming in Julia 1.7
- Feb 2022Two sparsities are better than one: Performance of sparse-sparse networks
- Feb 2025(Ab)using general search algorithms on dynamic optimization problems (2023)
- 119
Direct Preference Optimization: Your Language Model is Secretly a Reward Model
Hacker News threads
- Jan 2024Direct Preference Optimization: Your Language Model Is a Reward Model
- May 2023RLFH Alternative Direct Preference Optimization
- May 2023Direct Preference Optimization: Your Language Model Is a Reward Model
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- Jun 2023How RLHF Works
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Self-rewarding-lm-PyTorch: Self-Rewarding Language Model from MetaAI
- Aug 2025Dispelling misconceptions about RLHF
- Jun 2026I design with Claude more than Figma now
- Sep 2026Ask HN: Any nerds out there who've read a lot of research papers?
- 120
Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting
Hacker News threads
- May 2023Unfaithful Explanations in Chain-of-Thought Prompting
- May 2023“Just a statistical text predictor”
- Dec 2024Training LLMs to Reason in a Continuous Latent Space
- Feb 2025Modern-Day Oracles or Bullshit Machines? How to thrive in a ChatGPT world
- Apr 2025Can reinforcement learning for LLMs scale beyond math and coding tasks? Probably
- Jul 2025Chain of thought monitorability: A new and fragile opportunity for AI safety
- Nov 2025Google Antigravity
- Oct 2026DeepSeek-v4.1-Flash-1017
- 121
Very Deep Convolutional Networks for Large-Scale Image Recognition
Hacker News threads
- Sep 2014Building a deeper understanding of images
- Mar 2015Show HN: Anime character recognizer
- Apr 2015Why GEMM is at the heart of deep learning
- Jul 2015Deep learning
- Mar 2016Turning two-bit doodles into fine artworks with deep neural networks
- Apr 2016Show HN: Open source colorizing grayscale images with NN
- Jun 2021Do wide and deep networks learn the same things?
- 122
Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
Hacker News threads
- May 2021Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
- Sep 2025Geometric Deep Learning Grids, Groups, Graphs, Geodesics, and Gauges [pdf]
- Apr 2021Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
- May 2021An Erlangen Programme to Establish the Geometric Foundations of Deep Learning
- Jun 2021ICLR 2021 Keynote: “Geometric Deep Learning: The Erlangen Programme of ML”
- Apr 2022Why train when you can optimize?
- Jan 2023Ask HN: What are the foundational texts for learning about AI/ML/NN?
- Jan 2023Just know stuff. (Or, how to achieve success in a machine learning PhD)
- Feb 2023Understanding and Coding the Self-Attention Mechanism of Large Language Models
- Jun 2025Spherical CNNs (2018)
- Sep 2025The maths you need to start understanding LLMs
- 123
Analyzing and Improving the Image Quality of StyleGAN
Hacker News threads
- Dec 2019Analyzing and Improving the Image Quality of StyleGAN
- Feb 2020This person does not exist
- Nov 2020This X Does Not Exist (2019)
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- Feb 2021Accounts with GAN Faces Attack Belgium over 5G Restrictions
- Jun 2021Alias-Free GAN
- Jul 2022Show HN: This Food Does Not Exist
- Oct 2024Ask HN: What are you working on? (October 2024)
- 124
Knowledge Representation in Bicategories of Relations
Hacker News threads
- Jun 2017A computational linguistic farce in three acts
- Nov 2017Modeling Science as a Directed Graph
- May 2018The Logical Disaster of Null
- Jul 2018Kialo – a platform for rational debate
- Dec 2018A Formal Apology for Metaphysics [pdf]
- Aug 2019Software Architecture Guide
- Feb 2020Contextualise: Manage your knowledge
- 125
Linear Transformers Are Secretly Fast Weight Programmers
Hacker News threads
- Oct 2022Meta Learning Backpropagation and Improving It (2020)
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Sep 2023HN thread 37367951
- Sep 2023I made a transformer by hand (no training)
- Oct 2023Ring Attention with Blockwise Transformers for Near-Infinite Context
- Oct 2023How Transformers Work
- Feb 2024Neural Network Diffusion
- Sep 2026Transformers Explained Visually
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.