Hacker Papers
- 101
What Algorithms can Transformers Learn? A Study in Length Generalization
Hacker News threads
- 102
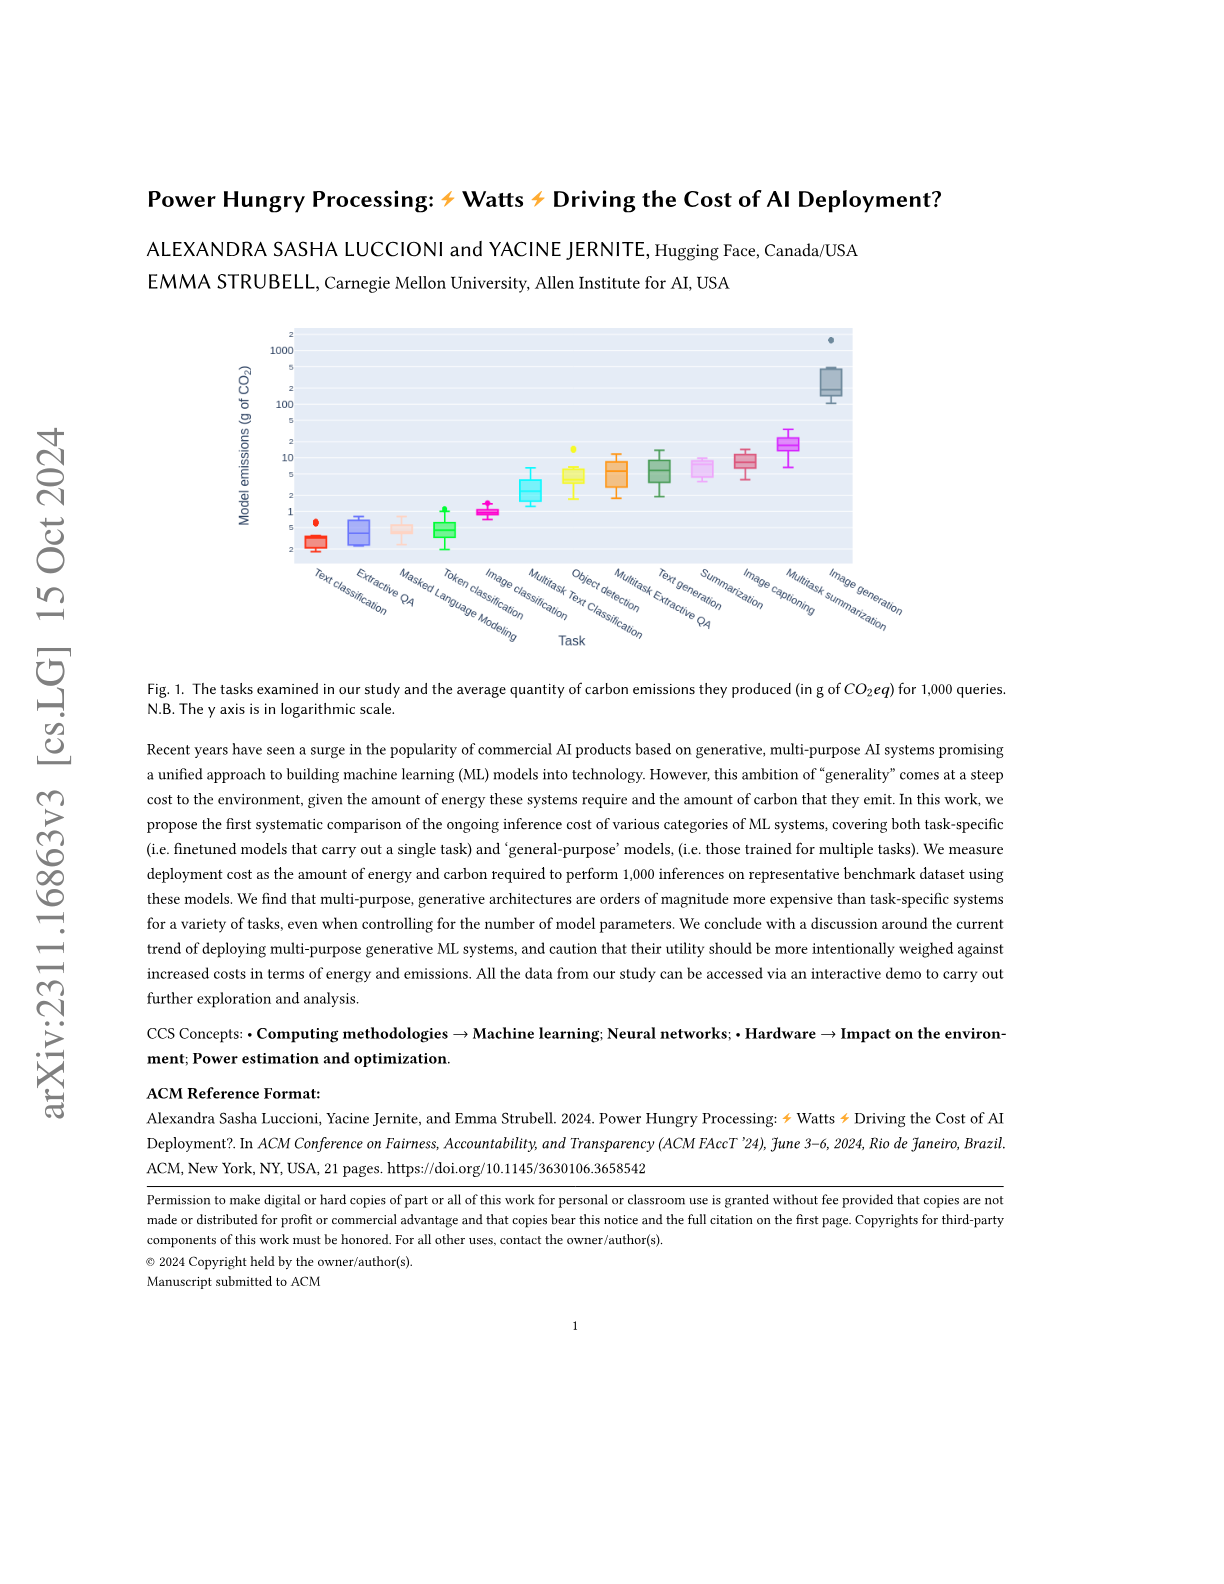
Power Hungry Processing: Watts Driving the Cost of AI Deployment?
Hacker News threads
- 103
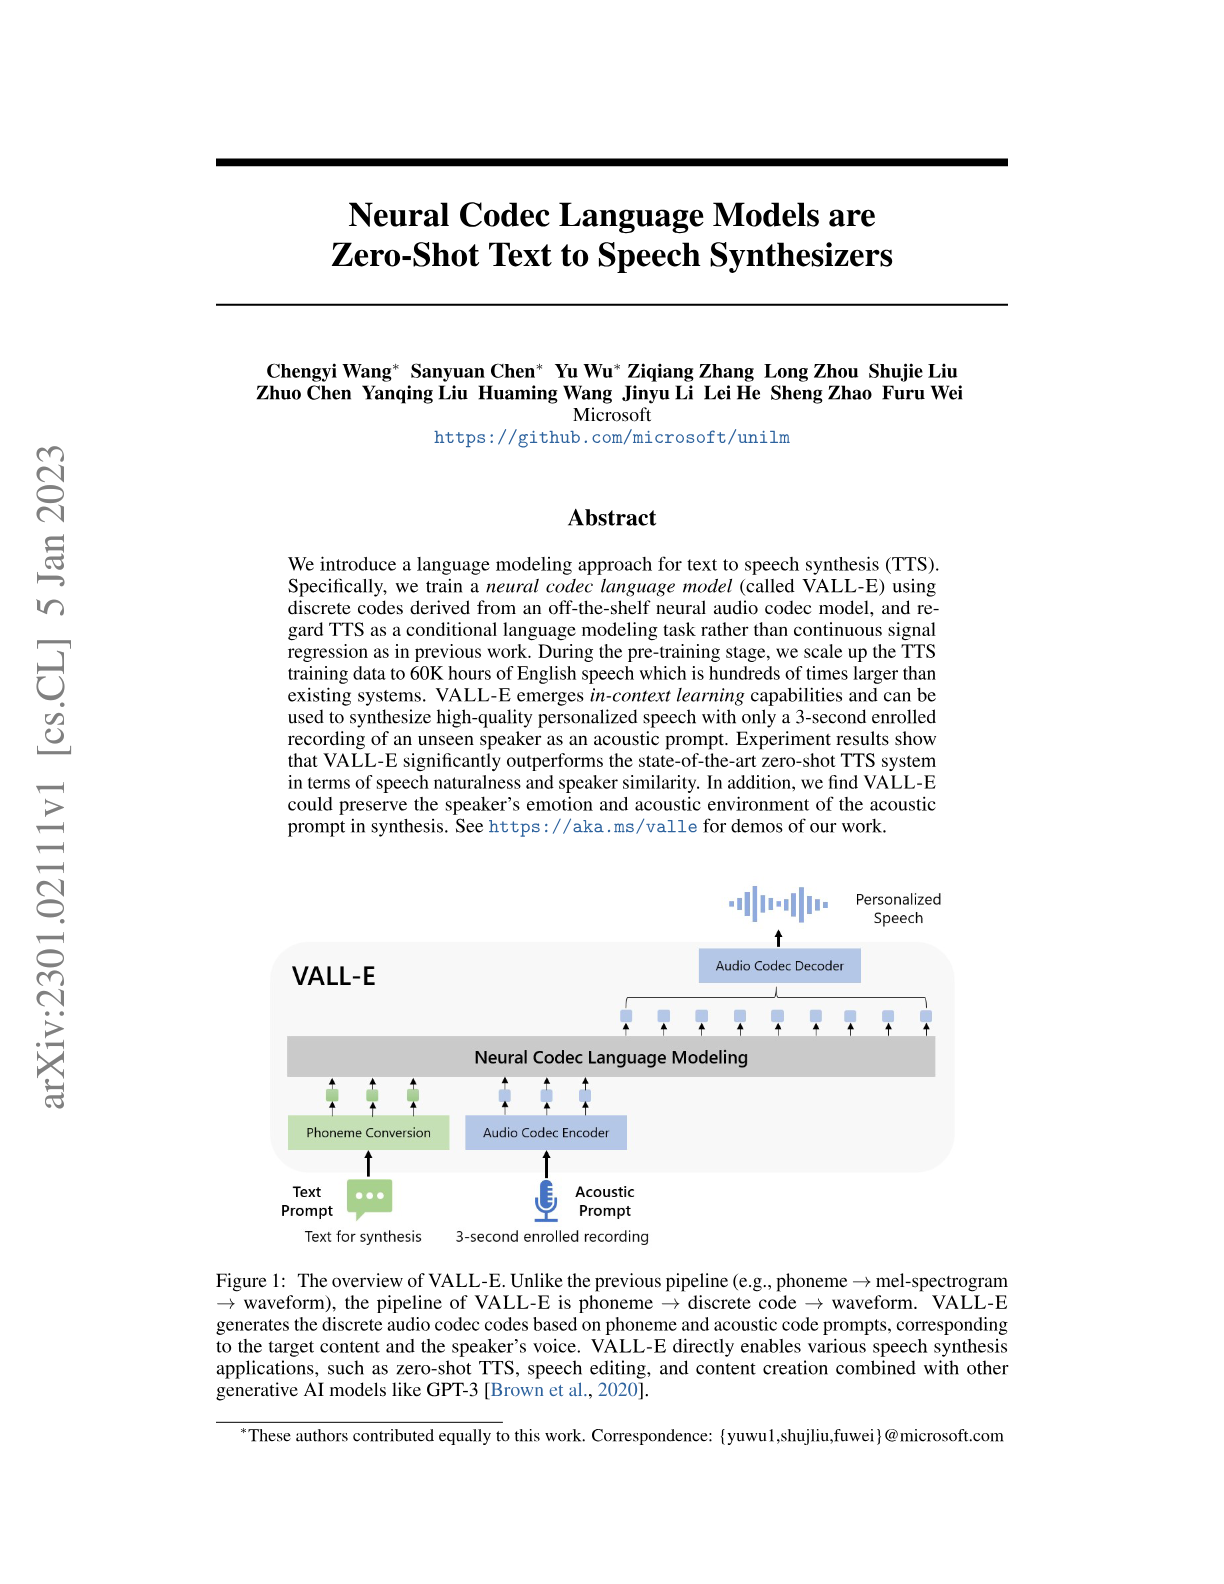
Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers
Hacker News threads
- 104
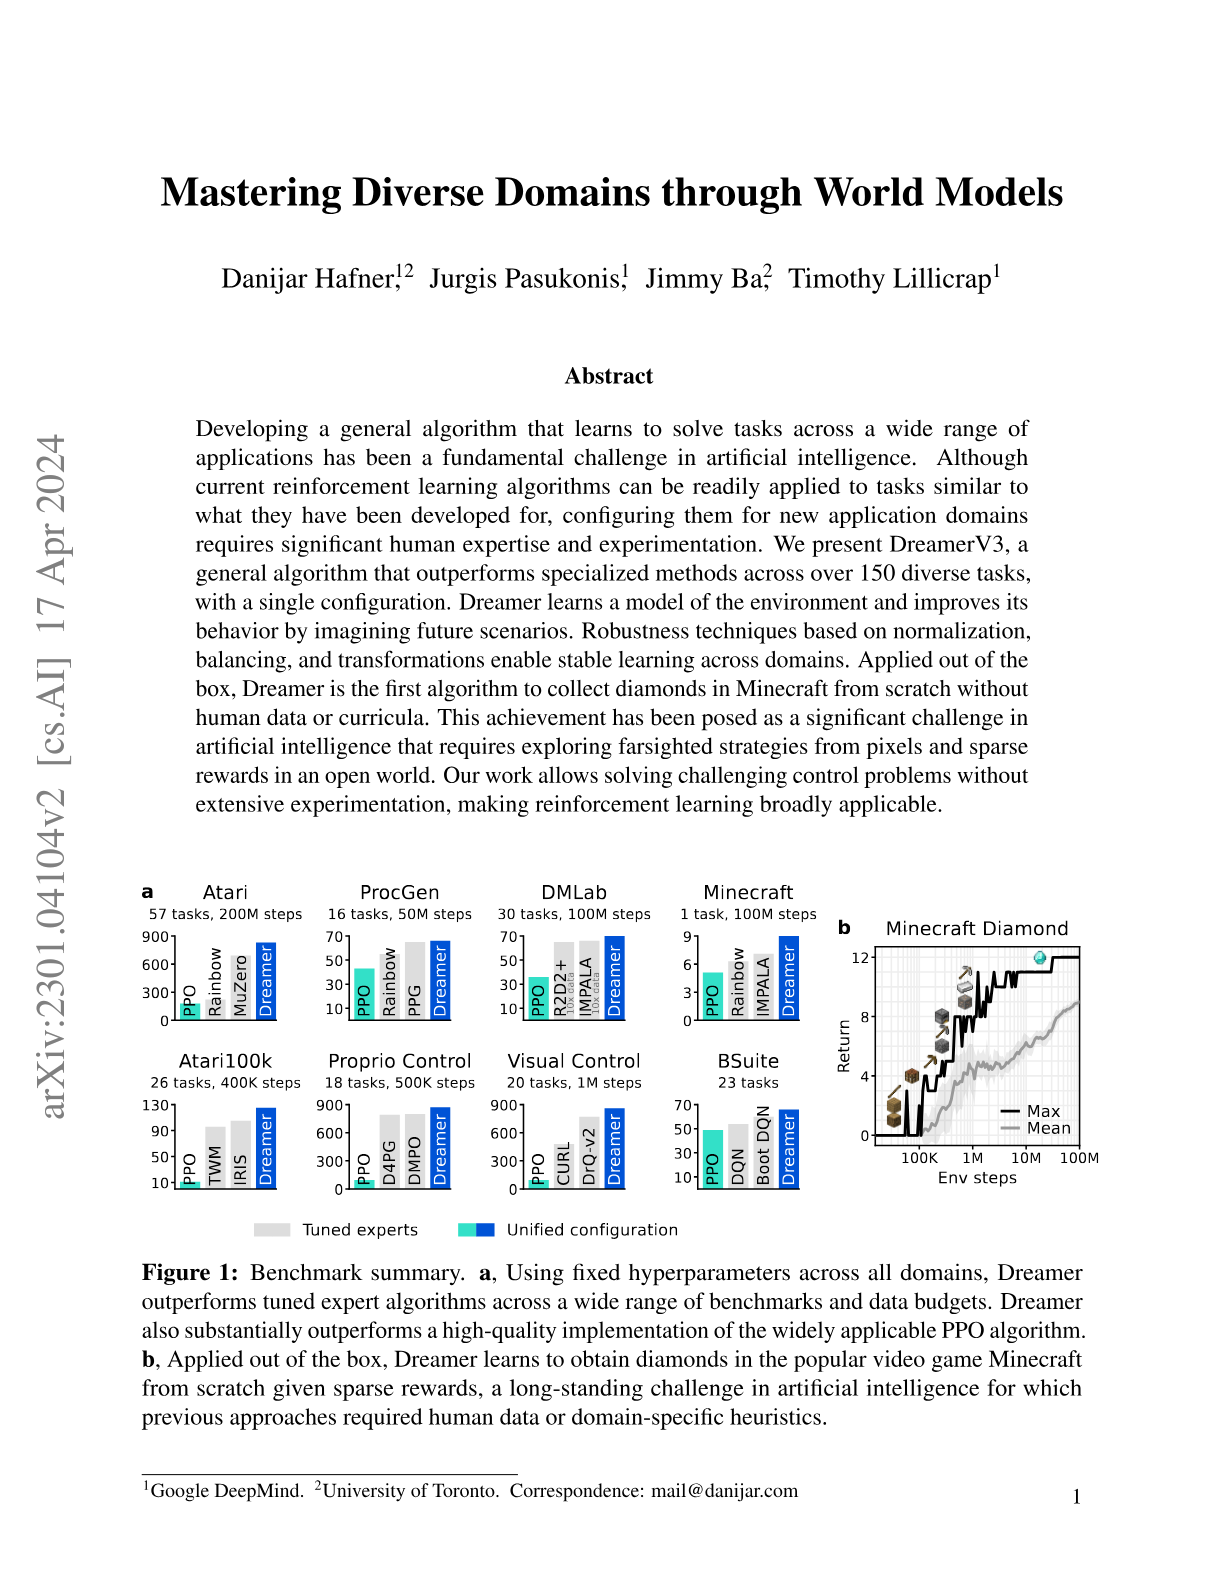
Mastering Diverse Domains through World Models
Hacker News threads
- 105
How Language Model Hallucinations Can Snowball
Hacker News threads
- 106
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Hacker News threads
- 107
In-Context Learning Creates Task Vectors
Hacker News threads
- 108
Scaling Laws for Generative Mixed-Modal Language Models
Hacker News threads
- 109
Tracr: Compiled Transformers as a Laboratory for Interpretability
Hacker News threads
- 110
G-Eval: NLG Evaluation using GPT-4 with Better Human Alignment
Hacker News threads
- 111
Visual Instruction Tuning
Hacker News threads
- 112
Simple and Controllable Music Generation
Hacker News threads
- 113
Efficient Guided Generation for Large Language Models
Hacker News threads
- 114
Emergent Linear Representations in World Models of Self-Supervised Sequence Models
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.