Hacker Papers
- 126
Resurrecting Recurrent Neural Networks for Long Sequences
Hacker News threads
- 127
DiLoCo: Distributed Low-Communication Training of Language Models
Hacker News threads
- Jul 2024DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023Distributed Low-Communication Training of Language Models
- Nov 2023Ultra Fast Bert
- Mar 2024Stable Diffusion 3: Research Paper
- Sep 2024Meta AI: "The Future of AI Is Open Source and Decentralized"
- May 2025Intellect-2 Release: The First 32B Model Trained Through Globally Distributed RL
- 128
TerpreT: A Probabilistic Programming Language for Program Induction
Hacker News threads
- Aug 2016TerpreT: A Probabilistic Programming Language for Program Induction by MSR
- Jan 2018Programming with a Differentiable Forth Interpreter (2016)
- Sep 2021The Great AI Reckoning
- Jun 2022Differentiable Finite State Machines
- May 2024Show HN: Boldly go where Gradient Descent has never gone before with DiscoGrad
- 129
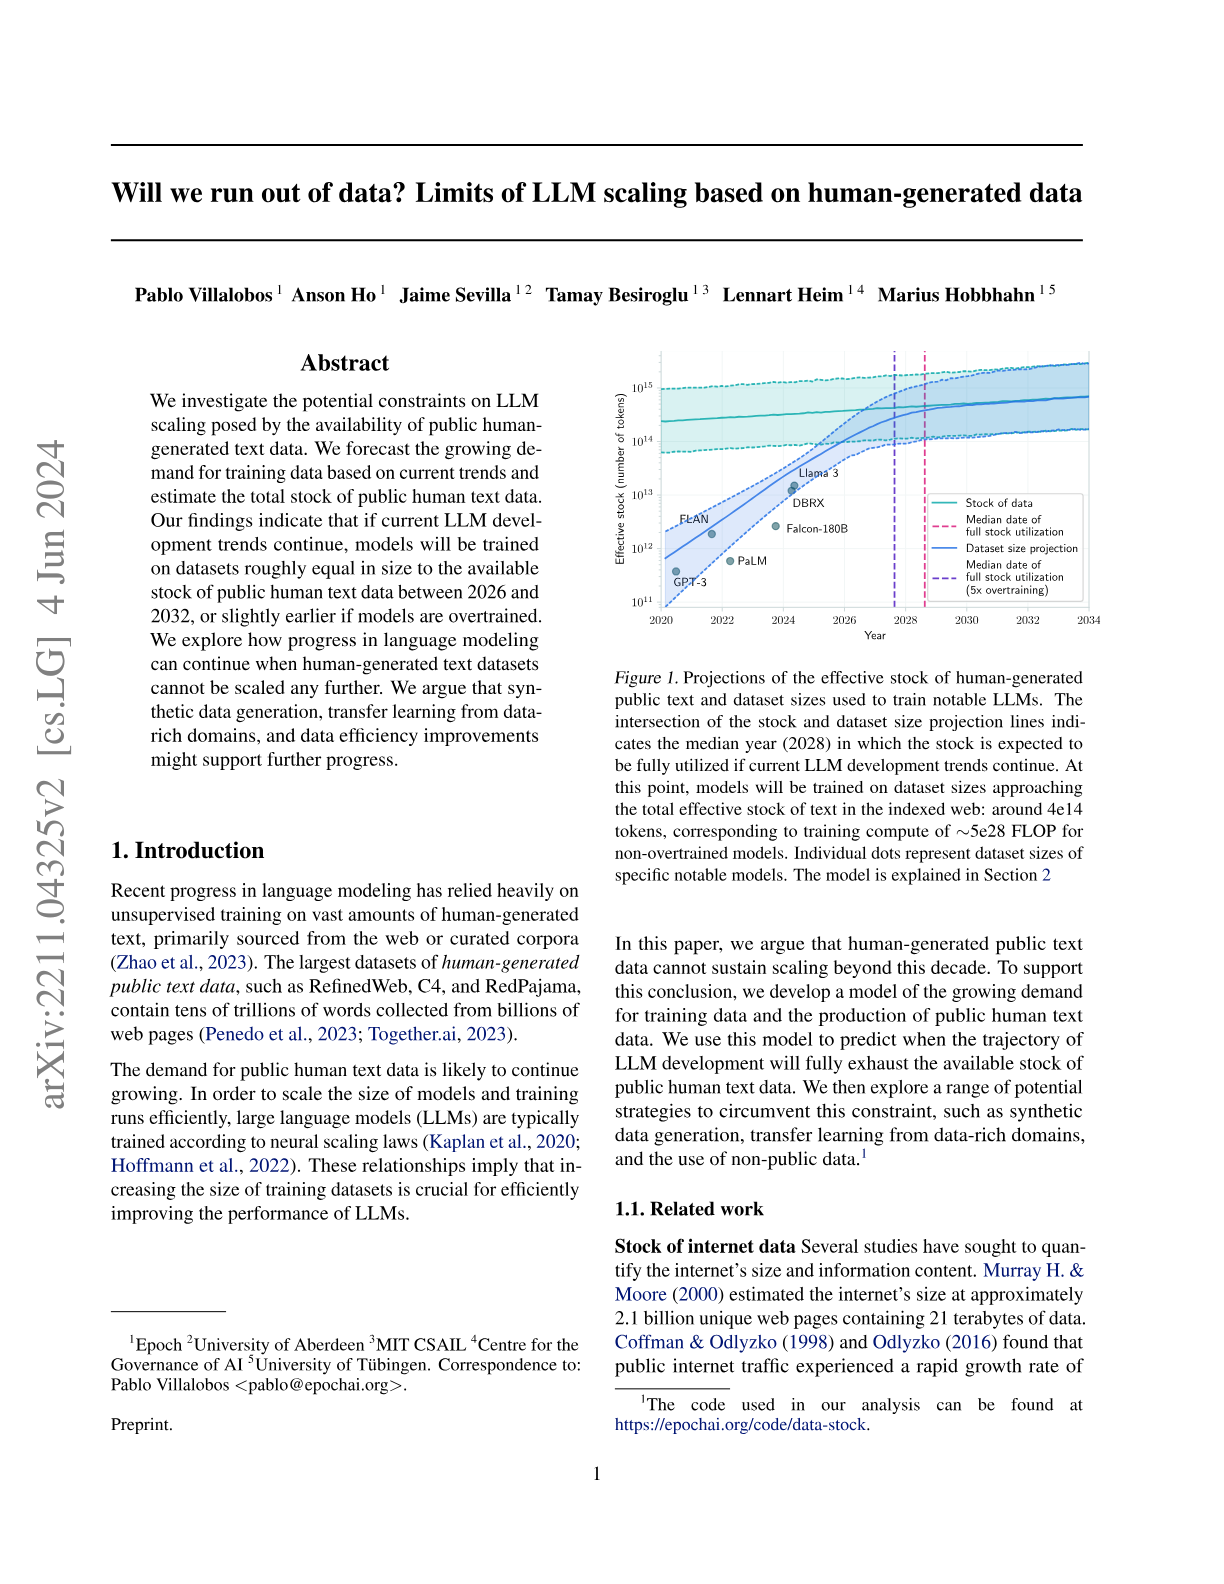
Will we run out of data? Limits of LLM scaling based on human-generated data
Hacker News threads
- Aug 2023Will we run out of data to train LLMs?
- Nov 2022We might run out of language data to train ML models soon [pdf]
- Dec 2022An analysis of the limits of scaling datasets in Machine Learning
- Dec 2022Drowning in AI Generated Garbage: the silent war we are fighting
- Dec 2023Dropbox: How to opt out of 3rd party AI partner access to your Dropbox
- Sep 2025Failing to Understand the Exponential, Again
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 130
Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting
Hacker News threads
- 131
Tulu 3: Pushing Frontiers in Open Language Model Post-Training
Hacker News threads
- 132
Learned Indexes for a Google-scale Disk-based Database
Hacker News threads
- Oct 2024Learned Indexes for a Google-Scale Disk-Based Database
- Jan 2021PGM Indexes: Learned indexes that match B-tree performance with 83x less space
- Feb 2022Transformer Memory as a Differentiable Search Index
- Jul 2022Ask HN: What are some cool but obscure data structures you know about?
- Jun 2025The probability of a hash collision (2022)
- 133
A Benchmark for Learning to Translate a New Language from One Grammar Book
Hacker News threads
- Jun 2024A Benchmark for Learning to Translate a New Language from One Grammar Book
- Mar 2024How well can LLMs write COBOL?
- Jun 2024Prompting LLMs to Learn Language from a Single Book
- Nov 2024The deep learning boom caught almost everyone by surprise
- Apr 2025DolphinGemma: How Google AI is helping decode dolphin communication
- 134
ConvNets Match Vision Transformers at Scale
Hacker News threads
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Mar 2024The Google employees who created transformers
- Apr 2024Vision Transformers Are Overrated
- Apr 2024Vision Transformers Are Overrated
- Sep 2025Automatic differentiation can be incorrect
- Dec 2025The Illustrated Transformer
- 135
Alignment Whack-a-Mole : Finetuning Activates Verbatim Recall of Copyrighted Books in Large Language Models
Hacker News threads
- Apr 2026Finetuning Activates Verbatim Recall of Copyrighted Books in LLMs
- Apr 2026Alignment Whack-a-Mole
- Apr 2026Finetuning Activates Verbatim Recall of Copyrighted Books in LLMs
- Mar 2026The Claude Code Source Leak: fake tools, frustration regexes, undercover mode
- Apr 2026AI Code Is Hollowing Out Open Source, and Maintainers Are Looking the Other Way
- Jun 2026US holds off blacklisting China's DeepSeek, +100 firms deemed security risks
- Jul 2026Claude Code Is Steganographically Marking Requests
- 136
GPQA: A Graduate-Level Google-Proof Q&A Benchmark
Hacker News threads
- 137
Dolma: an Open Corpus of Three Trillion Tokens for Language Model Pretraining Research
Hacker News threads
- 138
Large Concept Models: Language Modeling in a Sentence Representation Space
Hacker News threads
- 139
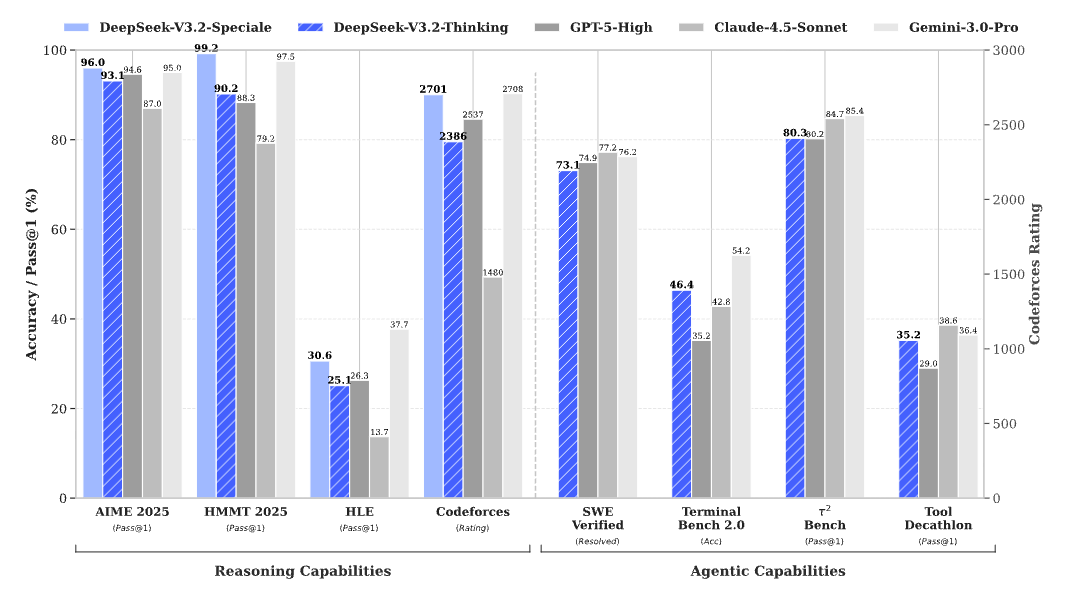
DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models
Hacker News threads
- 140
The Illusion of State in State-Space Models
Hacker News threads
- Jun 2024The illusion of state in state-space models
- Apr 2024The illusion of state in state-space models
- Apr 2024The Illusion of State in State-Space Models
- May 2024Meta AI chief says large language models will not reach human intelligence
- Jun 2024Mamba-2 – State Space Duality
- Oct 2024Were RNNs all we needed?
- Jan 2025RWKV Language Model
- 141
The impossibility of "fairness": a generalized impossibility result for decisions
Hacker News threads
- Aug 2021The impossibility of fairness: a generalized impossibility result for decisions
- Jul 2022The impossibility of “fairness”:a generalized impossibility result for decisions
- Jun 2018AI at Google: our principles
- Feb 2020Setting fairness goals with the TensorFlow constrained optimization library
- Feb 2022How can minorities of regular individuals overturn social conventions?
- Mar 2023Responsible AI Challenge
- 142
What Has a Foundation Model Found? Using Inductive Bias to Probe for World Models
Hacker News threads
- Jul 2025LLMs fail to demonstrate internal world model, according to Harvard/MIT study
- Jul 2025AGI Is Mathematically Impossible (3): Kolmogorov Complexity
- Aug 2025Persona vectors: Monitoring and controlling character traits in language models
- Oct 2025Andrej Karpathy – It will take a decade to work through the issues with agents
- Jun 2026ΠFS
- 143
Logical Induction
Hacker News threads
- 144
Efficient Training of Language Models to Fill in the Middle
Hacker News threads
- 145
Emergent Representations of Program Semantics in Language Models Trained on Programs
Hacker News threads
- May 2023Evidence of Meaning in Language Models Trained on Programs
- May 2023Evidence of Meaning in Language Models Trained on Programs
- Jun 2023Evidence of Meaning in Large Language Models Trained on Programs
- May 2023Governance of Superintelligence
- Jun 2023The bigger-is-better approach to AI is running out of road
- Aug 2024Markov chains are funnier than LLMs
- Aug 2026If your agent commits a crime, who is responsible?
- 146
Stable image reconstruction using total variation minimization
Hacker News threads
- 147
Deep Fried Convnets
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.