Hacker Papers
- 176
TerpreT: A Probabilistic Programming Language for Program Induction
Hacker News threads
- Aug 2016TerpreT: A Probabilistic Programming Language for Program Induction by MSR
- Jan 2018Programming with a Differentiable Forth Interpreter (2016)
- Sep 2021The Great AI Reckoning
- Jun 2022Differentiable Finite State Machines
- May 2024Show HN: Boldly go where Gradient Descent has never gone before with DiscoGrad
- 177
Will we run out of data? Limits of LLM scaling based on human-generated data
Hacker News threads
- Aug 2023Will we run out of data to train LLMs?
- Nov 2022We might run out of language data to train ML models soon [pdf]
- Dec 2022An analysis of the limits of scaling datasets in Machine Learning
- Dec 2022Drowning in AI Generated Garbage: the silent war we are fighting
- Dec 2023Dropbox: How to opt out of 3rd party AI partner access to your Dropbox
- Sep 2025Failing to Understand the Exponential, Again
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 178
The impossibility of "fairness": a generalized impossibility result for decisions
Hacker News threads
- Aug 2021The impossibility of fairness: a generalized impossibility result for decisions
- Jul 2022The impossibility of “fairness”:a generalized impossibility result for decisions
- Jun 2018AI at Google: our principles
- Feb 2020Setting fairness goals with the TensorFlow constrained optimization library
- Feb 2022How can minorities of regular individuals overturn social conventions?
- Mar 2023Responsible AI Challenge
- 179
Logical Induction
Hacker News threads
- 180
Stable image reconstruction using total variation minimization
Hacker News threads
- 181
Deep Fried Convnets
Hacker News threads
- 182
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Hacker News threads
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024Nvidia CEO Jensen Huang announces new AI chips: ‘We need bigger GPUs’
- May 2024GPUs Go Brrr
- Jun 2024Scalable MatMul-Free Language Modeling
- Jan 2025Run DeepSeek R1 Dynamic 1.58-bit
- Jun 2025AMD's Freshly-Baked MI350: An Interview with the Chief Architect
- Jan 2026Kimi Released Kimi K2.5, Open-Source Visual SOTA-Agentic Model
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Sep 2026Breaking the 1.58-bit Barrier for Ternary LLMs
- 183
Training Large Language Models to Reason in a Continuous Latent Space
Hacker News threads
- Dec 2024Training LLMs to Reason in a Continuous Latent Space
- Apr 2026Training Large Language Models to Reason in a Continuous Latent Space [pdf]
- Dec 2024Coconut from Meta lets language models think without words
- Dec 2024Coconut by Meta AI – Better LLM Reasoning with Chain of Continuous Thought?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Apr 2025The Llama 4 herd
- Jun 2025Reasoning by Superposition: A Perspective on Chain of Continuous Thought
- Dec 2025Universal Reasoning Model (53.8% pass 1 ARC1 and 16.0% ARC 2)
- Jun 2026Claude Code's "extended thinking" is a summary- not authentic thinking
- Sep 2026What is Nueralese and Why is it Bad
- 184
Hallucination is Inevitable: An Innate Limitation of Large Language Models
Hacker News threads
- Feb 2024Hallucination is inevitable: An innate limitation of large language models
- Feb 2024Hallucination Is Inevitable: An Innate Limitation of Large Language Models
- May 2026Hallucination Is Inevitable: An Innate Limitation of Large Language Models
- Feb 2024Ask HN: Has Generative AI plateaued?
- May 2024Google scrambles to manually remove weird AI answers in search
- Sep 2024GPTs and Hallucination
- Oct 2024Yann LeCun Thinks AI Is Dumber Than a Cat
- Dec 2024AI hallucinations: Why LLMs make things up (and how to fix it)
- Jan 2026Please Don't Say Mean Things about the AI I Just Invested a Billion Dollars In
- May 2026Using "underdrawings" for accurate text and numbers
- Oct 2026“Math 2.0” will need to value mathematical progress more holistically
- 185
Think before you speak: Training Language Models With Pause Tokens
Hacker News threads
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Oct 2023Want to get started with LLMs? Here's what you need to know
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Mar 2024Yi: Open Foundation Models by 01.AI
- Apr 2024Self-reasoning tokens: teaching models to think ahead
- Jul 2024The A.I. Bubble is Bursting with Ed Zitron [video]
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Claude 4
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 186
Emergent World Representations: Exploring a Sequence Model Trained on a Synthetic Task
Hacker News threads
- Feb 2023Emergent World Representations in Neural Networks
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023GPT-4
- Mar 2023HN thread 35348353
- Apr 2023HN thread 35356648
- May 2023Just Calm Down About GPT-4 Already
- Jun 2024Legal models hallucinate in 1 out of 6 (or more) benchmarking queries
- Apr 2026Where the Goblins Came From
- 187
Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
Hacker News threads
- Apr 2024Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
- May 2024Vision Transformers Need Registers
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- Feb 2026Evaluating AGENTS.md: are they helpful for coding agents?
- Apr 2026Talk like caveman
- Sep 2026How concerned should we be about Astra's recurrent architecture?
- Oct 2026I'm the AGI that's wiping out humanity
- 188
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Hacker News threads
- Dec 2023RAG: Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Mar 2021Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Jan 2023Wolfram Alpha as the Way to Bring Computational Knowledge Superpowers to ChatGPT
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Jun 2023Emerging Architectures for LLM Applications
- Aug 2023GPU-Accelerated LLM on a $100 Orange Pi
- Aug 2023How do domain-specific chatbots work? A retrieval augmented generation overview
- Nov 2023Grok
- Mar 2024Show HN: Ragdoll Studio (fka Arthas.AI) is the FOSS alternative to character.ai
- Jul 2026We taught a small LLM to throw away 68% of our RAG context
- 189
Amortized Planning with Large-Scale Transformers: A Case Study on Chess
Hacker News threads
- Feb 2024Grandmaster-Level Chess Without Search
- Feb 2024Grandmaster-Level Chess Without Search
- Feb 2024Grand-Master Level Chess Without Search: Modeling Choices and Their Implications
- Apr 2024EURISKO Lives
- Sep 2024Ilya Sutskever's SSI Inc raises $1B
- Oct 2024Grandmaster-level chess without search
- Nov 2024Something weird is happening with LLMs and Chess
- Nov 2024Something weird is happening with LLMs and chess
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- Mar 2026Based on its own charter, OpenAI should surrender the race
- 190
People cannot distinguish GPT-4 from a human in a Turing test
Hacker News threads
- May 2024People cannot distinguish GPT-4 from a human in a Turing test
- Jun 2024People cannot distinguish GPT-4 from a human in a Turing test
- Aug 2024Does Reasoning Emerge? Probabilities of Causation in Large Language Models
- Dec 2024GPT-5 is behind schedule
- Jan 2025Show HN: Killed by LLM – I catalogued AI benchmarks we thought would last years
- Feb 2025Modern-Day Oracles or Bullshit Machines? How to thrive in a ChatGPT world
- Apr 2025UCSD: Large Language Models Pass the Turing Test
- Oct 2025A definition of AGI
- Feb 2026Frontier AI agents violate ethical constraints 30–50% of time, pressured by KPIs
- May 2026Dear Richard Dawkins
- 191
LLaMA: Open and Efficient Foundation Language Models
Hacker News threads
- Mar 2024LLaMA: Open and Efficient Foundation Language Models (2023)
- Mar 2023The Most Cited AI Papers in 2022
- Mar 2023Using LLaMA with M1 Mac and Python 3.11
- Mar 2023The RWKV language model: An RNN with the advantages of a transformer
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- May 2023OpenLLaMA: An Open Reproduction of LLaMA
- Jun 2023OpenLLaMA 13B Released
- Sep 2023Mistral 7B, the most powerful language model for its size to date, Apache 2.0
- Feb 2025Meta torrented & seeded 81.7 TB dataset containing copyrighted data
- 192
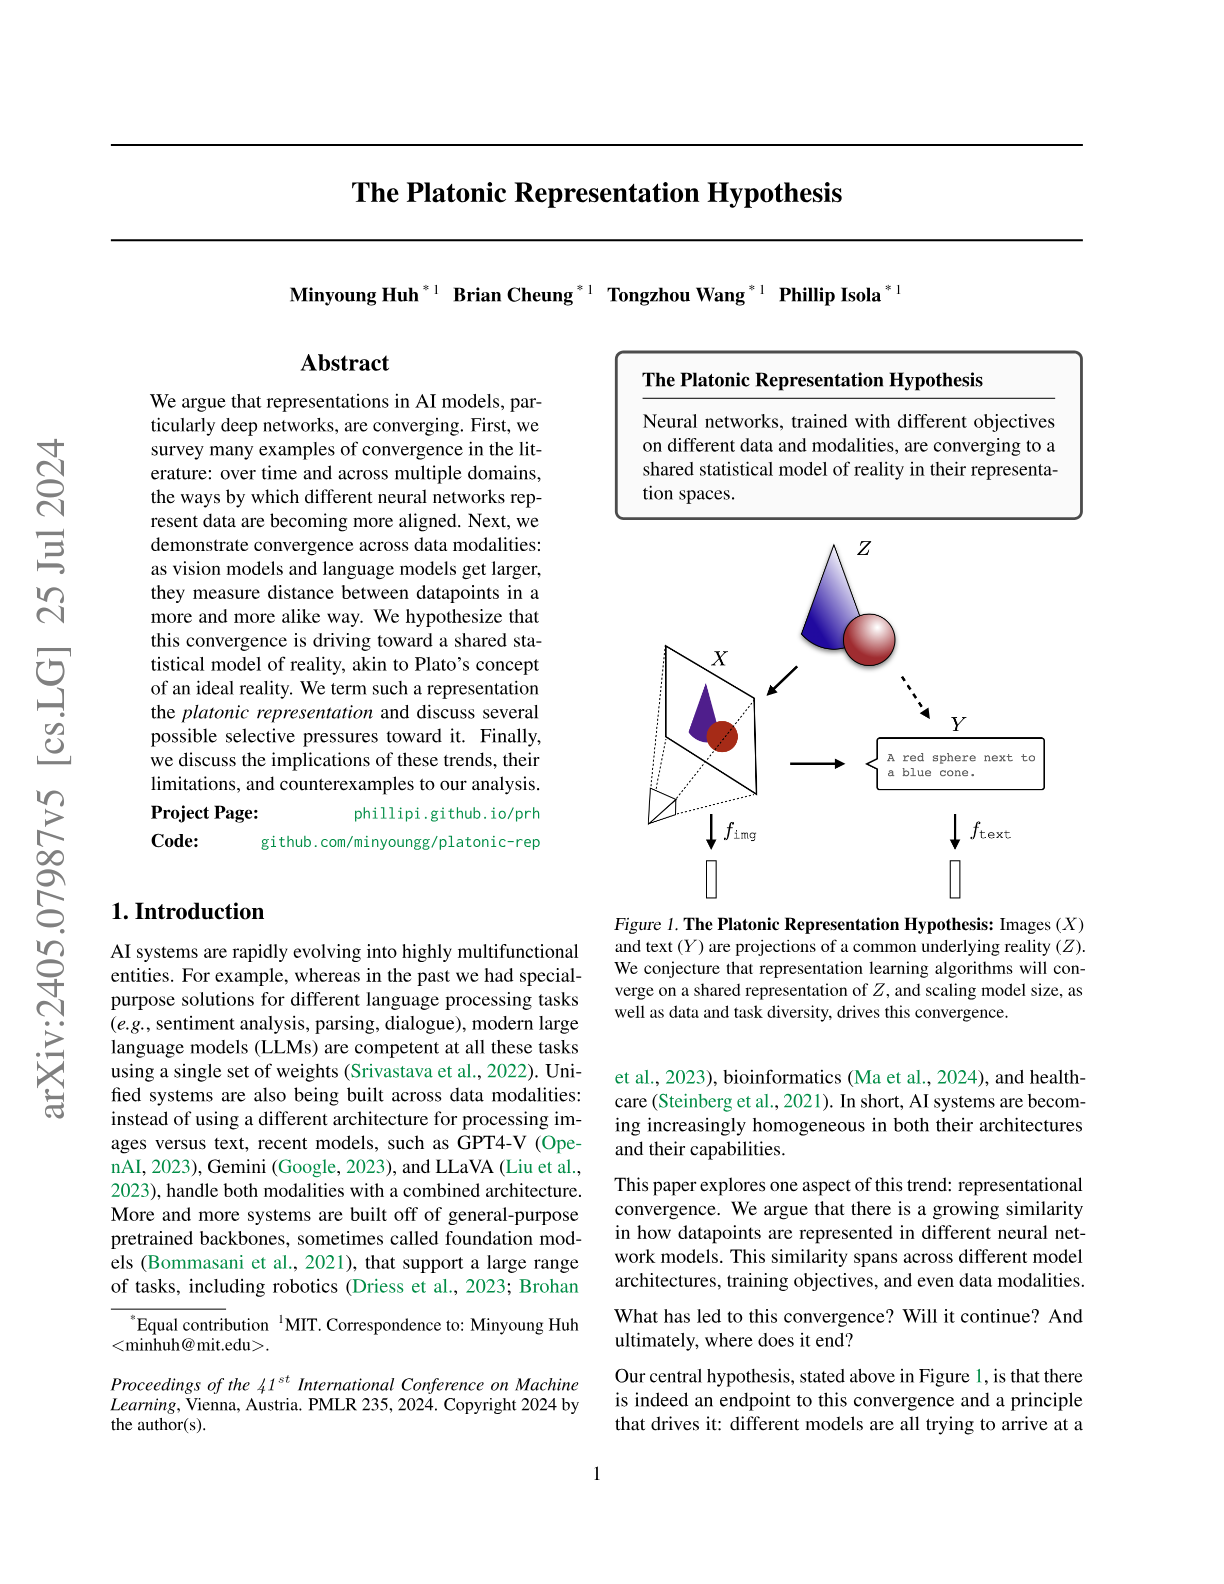
The Platonic Representation Hypothesis
Hacker News threads
- May 2024Mutlimodal neural networks converge to a shared statistical model of reality
- Apr 2026The Platonic Representation Hypothesis
- May 2024Show HN: Tarsier – Vision utilities for web interaction agents
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Mar 2025Gödel's theorem debunks the most important AI myth – Roger Penrose [video]
- Jul 2025Ask HN: Will AI models over time converge into the same system?
- Dec 2025The universal weight subspace hypothesis
- Mar 2026Language Model Contains Personality Subnetworks
- Mar 2026I tried Karpathy's Autoresearch on an old research project
- Jul 2026Emily Bender Sets the Record Straight on "Stochastic Parrots"
- 193
Precise Zero-Shot Dense Retrieval without Relevance Labels
Hacker News threads
- Nov 2024Hypothetical Document Embeddings (HyDE) for Precise Zero-Shot Retrieval [pdf]
- Aug 2026Hypothetical Document Embeddings
- Jan 2023Precise Zero-Shot Dense Retrieval Without Relevance Labels
- Jan 2023How to implement Q&A against your docs with GPT3 embeddings and Datasette
- Feb 2023I made ChatGPT and Bing AI have a conversation
- Mar 2023
- Sep 2023A Comprehensive Guide for Building Rag-Based LLM Applications
- Dec 2023Build a search engine, not a vector DB
- May 2024Show HN: Hacker Search – A semantic search engine for Hacker News
- Sep 2024Contextual Retrieval
- Aug 2026Don't classify, hallucinate!
- 194
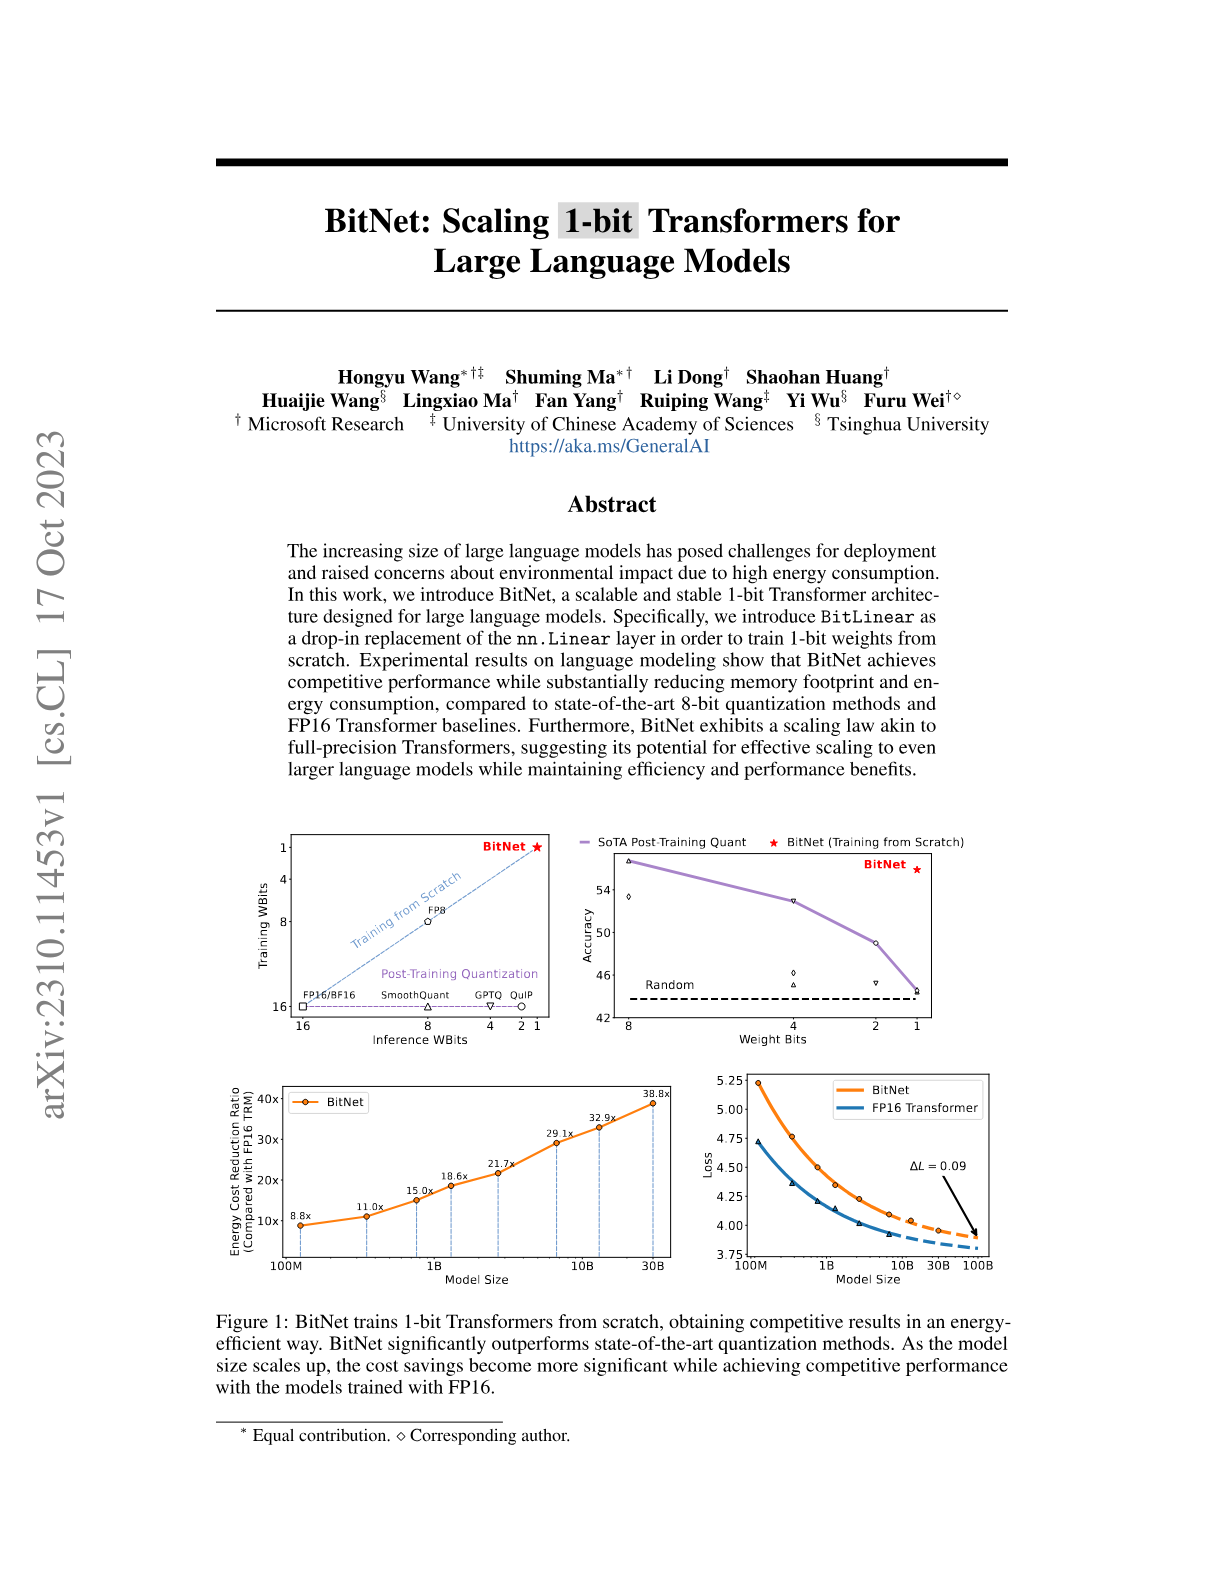
BitNet: Scaling 1-bit Transformers for Large Language Models
Hacker News threads
- Oct 2023BitNet: Scaling 1-Bit Transformers for Large Language Models
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- Jun 2024Scalable MatMul-Free Language Modeling
- Nov 2024SVDQuant: 4-Bit Quantization Powers 12B Flux on a 16GB 4090 GPU with 3x Speedup
- May 2025Towards the Cutest Neural Network
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Jul 2026Neutrino-1 8B
- 195
Mamba: Linear-Time Sequence Modeling with Selective State Spaces
Hacker News threads
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 2023Mamba outperforms transformers "everywhere we tried"
- Jan 2024Understand how transformers work by demystifying the math behind them
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2024Mamba: The Easy Way
- Mar 2024Launch HN: Danswer (YC W24) – Open-source AI search and chat over private data
- Jun 2024A pure NumPy implementation of Mamba
- Jul 2024Codestral Mamba
- Aug 2025GPT-5: Key characteristics, pricing and system card
- 196
How is ChatGPT's behavior changing over time?
Hacker News threads
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023(Databricks cofounder) How Is ChatGPT’s Behavior Changing over Time?
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023GPT-4 is getting worse over time, not better
- Aug 2023Why is OpenAI making ChatGPT increasingly dumber? What's the motivation?
- Aug 2023Azure ChatGPT: Private and secure ChatGPT for internal enterprise use
- Aug 2023Show HN: Beating GPT-4 on HumanEval with a fine-tuned CodeLlama-34B
- Sep 2023Study shows over time, ChatGPT lost accuracy
- Mar 2024DBRX: A new open LLM
- Apr 2026Claude Opus 4.7 costs 20–30% more per session
- Sep 2026Ember-1
- 197
A Watermark for Large Language Models
Hacker News threads
- Jan 2023A Watermark for Large Language Models
- Aug 2026A Watermark for Large Language Models
- Jan 2023A Watermark for Large Language Models
- Jan 2023New AI classifier for indicating AI-written text
- Mar 2023Mark Zuckerberg: “Please Resign” (2010)
- Jul 2023A.I. Companies Agree to Safeguards After Pressure from the White House
- Jul 2024Meta Launches AI Studio in US
- Aug 2026How Claude marks AI-generated content
- Aug 2026How Claude marks AI-generated content
- Aug 2026Text AI watermarks will always be trivial to remove
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 198
Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training
Hacker News threads
- Jan 2024Sleeper Agents: Training Deceptive LLMs That Persist Through Safety Training
- Jan 2024AI poisoning could turn open models into destructive "sleeper agents"
- Jan 2024Two-Faced AI Language Models Learn to Hide Deception
- Jun 2024Anthropic: Expanding Access to Claude for Government
- Sep 2025Mistral raises 1.7B€, partners with ASML
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- Jun 2026The OnlyFans Economy of American AI
- Aug 2026Your Open Source Model Could Have a Hidden Time-Release Backdoor
- Oct 2026DeepSeek banned from U.S. federal civilian agencies under new DHS order
- 199
Neural Architecture Search with Reinforcement Learning
Hacker News threads
- Jan 2017Neural Architecture Search with Reinforcement Learning
- Dec 2016This AI Boom Will Also Bust
- Jan 2017Learning to Learn in TensorFlow
- Mar 2017Unpaired Image-to-Image Translation using Cycle-Consistent Adversarial Networks
- Jul 2017Hacker's guide to Neural Networks (2012)
- Nov 2017Building A.I. That Can Build A.I
- Mar 2018Using Google Cloud AutoML to Classify Poisonous Australian Spiders
- Jul 2018Darts: Differentiable architecture search for convolutional, recurrent networks
- Jul 2018Darts: Differentiable architecture search for convolutional, recurrent networks
- 200
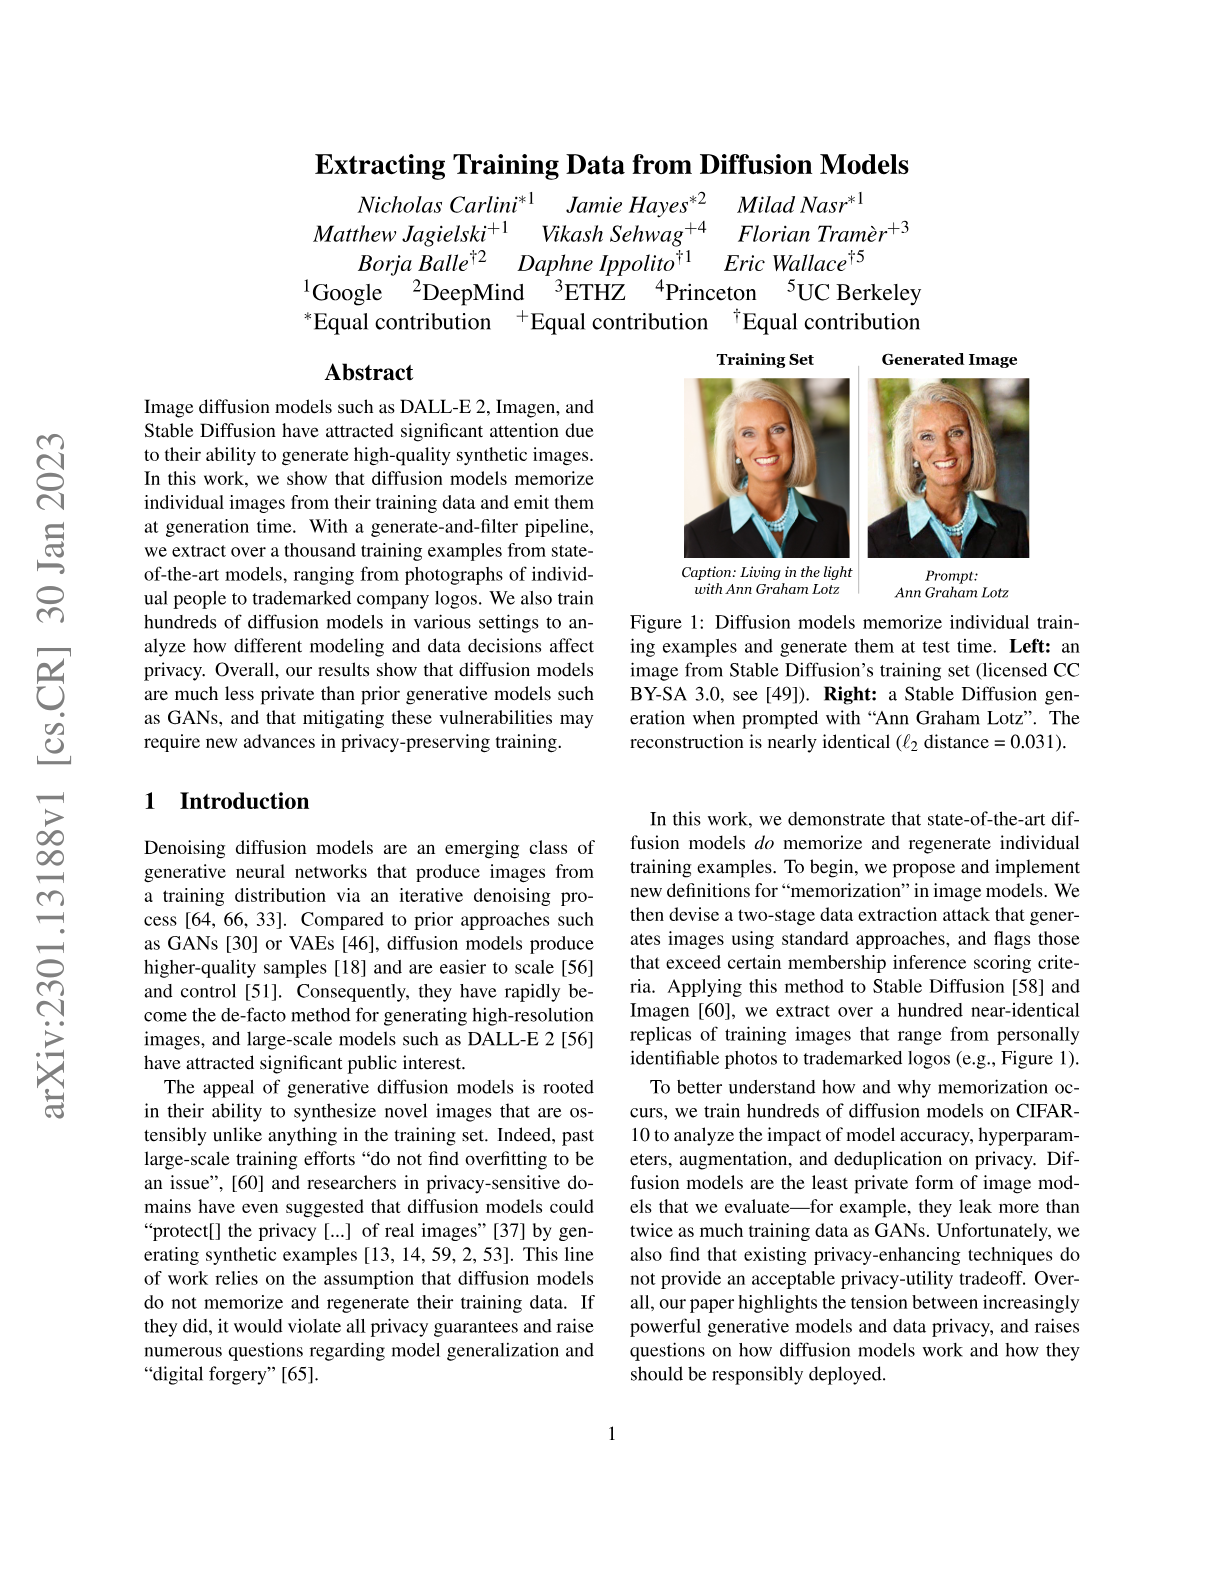
Extracting Training Data from Diffusion Models
Hacker News threads
- Jan 2023Extracting Training Data from Diffusion Models
- Jan 2023Stable Diffusion Memorizes Training Points
- Feb 2023The AI Crowd Is Mad
- Feb 2023An IP Attorney’s Reading of the Stable Diffusion Class Action Lawsuit
- Mar 2023Launch HN: Flower (YC W23) – Train AI models on distributed or sensitive data
- Apr 2023Universal Music Asks Streaming Services to Block AI Access to Its Songs
- Jun 2023Valve bans games using AI generated graphics or text from Steam
- Nov 2023Let's Not Flip Sides on IP Maximalism Because of AI
- Jan 2024Nightshade: An offensive tool for artists against AI art generators
- Jul 2025Meta says it won't sign Europe AI agreement
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.