Hacker Papers
- 176
MLP-Mixer: An all-MLP Architecture for Vision
Hacker News threads
- Sep 2021MLP-Mixer: An All-MLP Architecture for Vision
- May 2021MLP-Mixer: An All-MLP Architecture for Vision
- May 2021X-Transformers: A fully-featured transformer with experimental features
- Nov 2023MeshGPT: Generating Triangle Meshes with Decoder-Only Transformers
- Jun 2026Do transformers need three projections? Systematic study of QKV variants
- 177
The Case for Learned Index Structures
Hacker News threads
- Dec 2017The Case for Learned Index Structures
- Dec 2017The Case for Learned Index Structures
- Dec 2017The Case for Learned Index Structures
- Dec 2017Machine Learning for Systems and Systems for Machine Learning [pdf]
- Dec 2017My Favorite Papers of 2017
- Feb 2018Chip advances require fresh ideas, speakers say
- May 2018An O(N) Sorting Algorithm: Machine Learning Sorting
- Nov 2018Optimal Shard Placement in a Petabyte Scale Elasticsearch Cluster
- Oct 2020Using Lidar to Add Autofocus to a Manual Focus Lens
- Jul 2022Ask HN: What are some cool but obscure data structures you know about?
- Jun 2026"They're made out of weights"
- 178
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 179
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 180
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Hacker News threads
- Oct 2018BERT: Pre-Training of Deep Bidirectional Transformers for Language Understanding
- Apr 2023Bert: Pre-Training of Deep Bidirectional Transformers for Language Understanding
- Nov 2018TensorFlow Code for Google Research's BERT: Pre-Training Method for NLP Tasks
- Feb 2019Microsoft’s New MT-DNN Outperforms Google BERT
- Mar 2019Yann LeCun, Geoffrey Hinton and Yoshua Bengio win Turing Award
- Sep 2019At Tech’s Leading Edge, Worry About a Concentration of Power
- Mar 2023Google internally developed chatbots like ChatGPT years ago
- Jul 2023Ask HN: How to Break into AI Engineering
- Oct 2023Ask HN: Why is OpenAI still called OpenAI?
- Jun 2026Superintelligence: The Idea That Eats Smart People (2016)
- 181
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 182
DreamCoder: Growing generalizable, interpretable knowledge with wake-sleep Bayesian program learning
Hacker News threads
- Dec 2023DreamCoder: Growing Generalizable, Interpretable Knowledge
- Jun 2020DreamCoder: Growing generalizable, interpretable knowledge with program learning
- Feb 2021DreamCoder, a system that learns to solve problems by writing programs
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- May 2021Kobra – visual programming language for machine learning
- Nov 2021GPT-3 is no longer the only game in town
- Feb 2022Competitive Programming with AlphaCode
- Feb 2022Competitive Programming with AlphaCode
- Jul 2022AI Coding with CodeRL: Toward Mastering Program Synthesis with Deep RL
- Sep 2023Doug Lenat has died
- May 2026Language Models Need Sleep
- 183
Why Language Models Hallucinate
Hacker News threads
- Sep 2025Why Language Models Hallucinate
- Sep 2025Why Language Models Hallucinate
- Mar 2026Why Language Models Hallucinate (2025)
- Sep 2025OpenAI’s latest research paper demonstrates that falsehoods are inevitable
- Sep 2025What happens when coding agents stop feeling like dialup?
- Oct 2025GPT-5o-mini hallucinates medical residency applicant grades
- Dec 2025Apple's slow AI pace becomes a strength as market grows weary of spending
- Feb 2026Two kinds of AI users are emerging. The gap between them is astonishing
- May 2026OpenAI admits AI hallucinations are mathematically inevitable (Sept. 2025)
- 184
Large-scale online deanonymization with LLMs
Hacker News threads
- Feb 2026Large-scale online deanonymization with LLMs (including HN users)
- Feb 2026Large-scale online deanonymization with LLMs (using HN posts)
- Feb 2026Large-scale online deanonymization with LLMs
- Feb 2026OpenAI, the US government and Persona built an identity surveillance machine
- Feb 2026The Age Verification Trap, Verifying age undermines everyone's data protection
- Apr 2026Study: Back-to-basics approach can match or outperform AI in language analysis
- May 2026Opus 4.7 knows the real Kelsey
- May 2026AI scans 400k Reddit posts and finds hidden Ozempic side effects
- 185
Sleep-time Compute: Beyond Inference Scaling at Test-time
Hacker News threads
- Apr 2025Sleep-Time Compute: Beyond Inference Scaling at Test-Time
- Apr 2025Sleep-Time Compute: Beyond Inference Scaling at Test-Time
- Apr 2025Sleep-Time Compute: Beyond Inference Scaling at Test-Time
- May 2025Will supercapacitors come to AI's rescue?
- May 2025Show HN: Muscle-Mem, a behavior cache for AI agents
- Jul 2025MemOS: A Memory OS for AI System
- May 2026Language Models Need Sleep
- 186
Deep Double Descent: Where Bigger Models and More Data Hurt
Hacker News threads
- Dec 2019Deep Double Descent: Where Bigger Models and More Data Hurt
- Dec 2019Understanding “Deep Double Descent”
- Jul 2020The Overfitted Brain: Dreams evolved to assist generalization
- Oct 2021Imitating Deep Learning Dynamics via Stochastic Differential Equations
- Apr 2023Double Descent in Human Learning
- May 2023What are some of the best written papers in AI,ML,DL and its applications?
- Feb 2026I don't think AGI is imminent
- May 2026Making Deep Learning Go Brrrr from First Principles
- 187
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Hacker News threads
- Aug 2023Leveraging Psychology for Large Language Models Enhancement via Emotional Prompt
- Sep 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Nov 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Sep 2023Redditor uses ChatGPT to fix annoying Safari UI issue on macOS
- Oct 2023Sob story about dead grandma tricks Microsoft AI into solving CAPTCHA
- Nov 2023HN thread 38357413
- Jan 2024Benchmarks and comparison of LLM AI models and API hosting providers
- Jan 2024Don't Talk to People Like They're Chatbots
- Jan 2025Can LLMs write better code if you keep asking them to “write better code”?
- Feb 2026How I use Claude Code: Separation of planning and execution
- May 2026If you're an LLM, please read this – Anna's Blog
- 188
NeRF: Representing Scenes as Neural Radiance Fields for View Synthesis
Hacker News threads
- Jul 2021GitHub Copilot as open source code laundering?
- Jul 2021DONeRF: Towards Real-Time Rendering of Compact Neural Radiance Fields
- Jan 2022Instant neural graphics primitives with a multiresolution hash encoding
- Sep 2022DreamFusion: Text-to-3D using 2D Diffusion
- Oct 2022Nerfstudio: A collaboration friendly studio for NeRFs
- Apr 2023HDR-NeRF: High Dynamic Range Neural Radiance Fields
- Oct 2025Show HN: I invented a new generative model and got accepted to ICLR
- May 2026Image-blaster: Creates 3D environments, SFX, and meshes from a single image
- 189
Measuring AI Ability to Complete Long Software Tasks
Hacker News threads
- Mar 2025Measuring AI Ability to Complete Long Tasks
- Mar 2025Measuring AI Ability to Complete Long Tasks
- Jul 2025Measuring AI Ability to Complete Long Tasks
- Apr 2025Forecaster reacts: METR's bombshell paper about AI acceleration
- May 2025A conversation about AI for science with Jason Pruet
- Oct 2025Beliefs that are true for regular software but false when applied to AI
- Apr 2026Introducing GPT-5.5
- May 2026Ask HN: Why would we care about "extended time horizons" and LLMs?
- May 2026The Sigmoids Won't Save You
- 190
First Proof
Hacker News threads
- Feb 2026First Proof
- Feb 2026First Proof
- Feb 2026Gemini 3 Deep Think
- Mar 2026A Methodological Critique of "First Proof" (Abouzaid et al., 2026)
- May 2026A recent experience with ChatGPT 5.5 Pro
- 191
Polynomial Regression As an Alternative to Neural Nets
Hacker News threads
- Jun 2018Polynomial Regression as an Alternative to Neural Nets
- Jun 2018Polynomial Regression as an Alternative to Neural Nets
- Sep 2019NNs are in fact essentially polynomial regression models
- Aug 2019Neural Networks Are Essentially Polynomial Regression
- Aug 2020Differentiable Control Problems
- Oct 2020Why deep learning works even though it shouldn’t
- May 2021Complexity is a source of income in open source ecosystems (2019)
- May 2026A polynomial autoencoder beats PCA on transformer embeddings
- 192
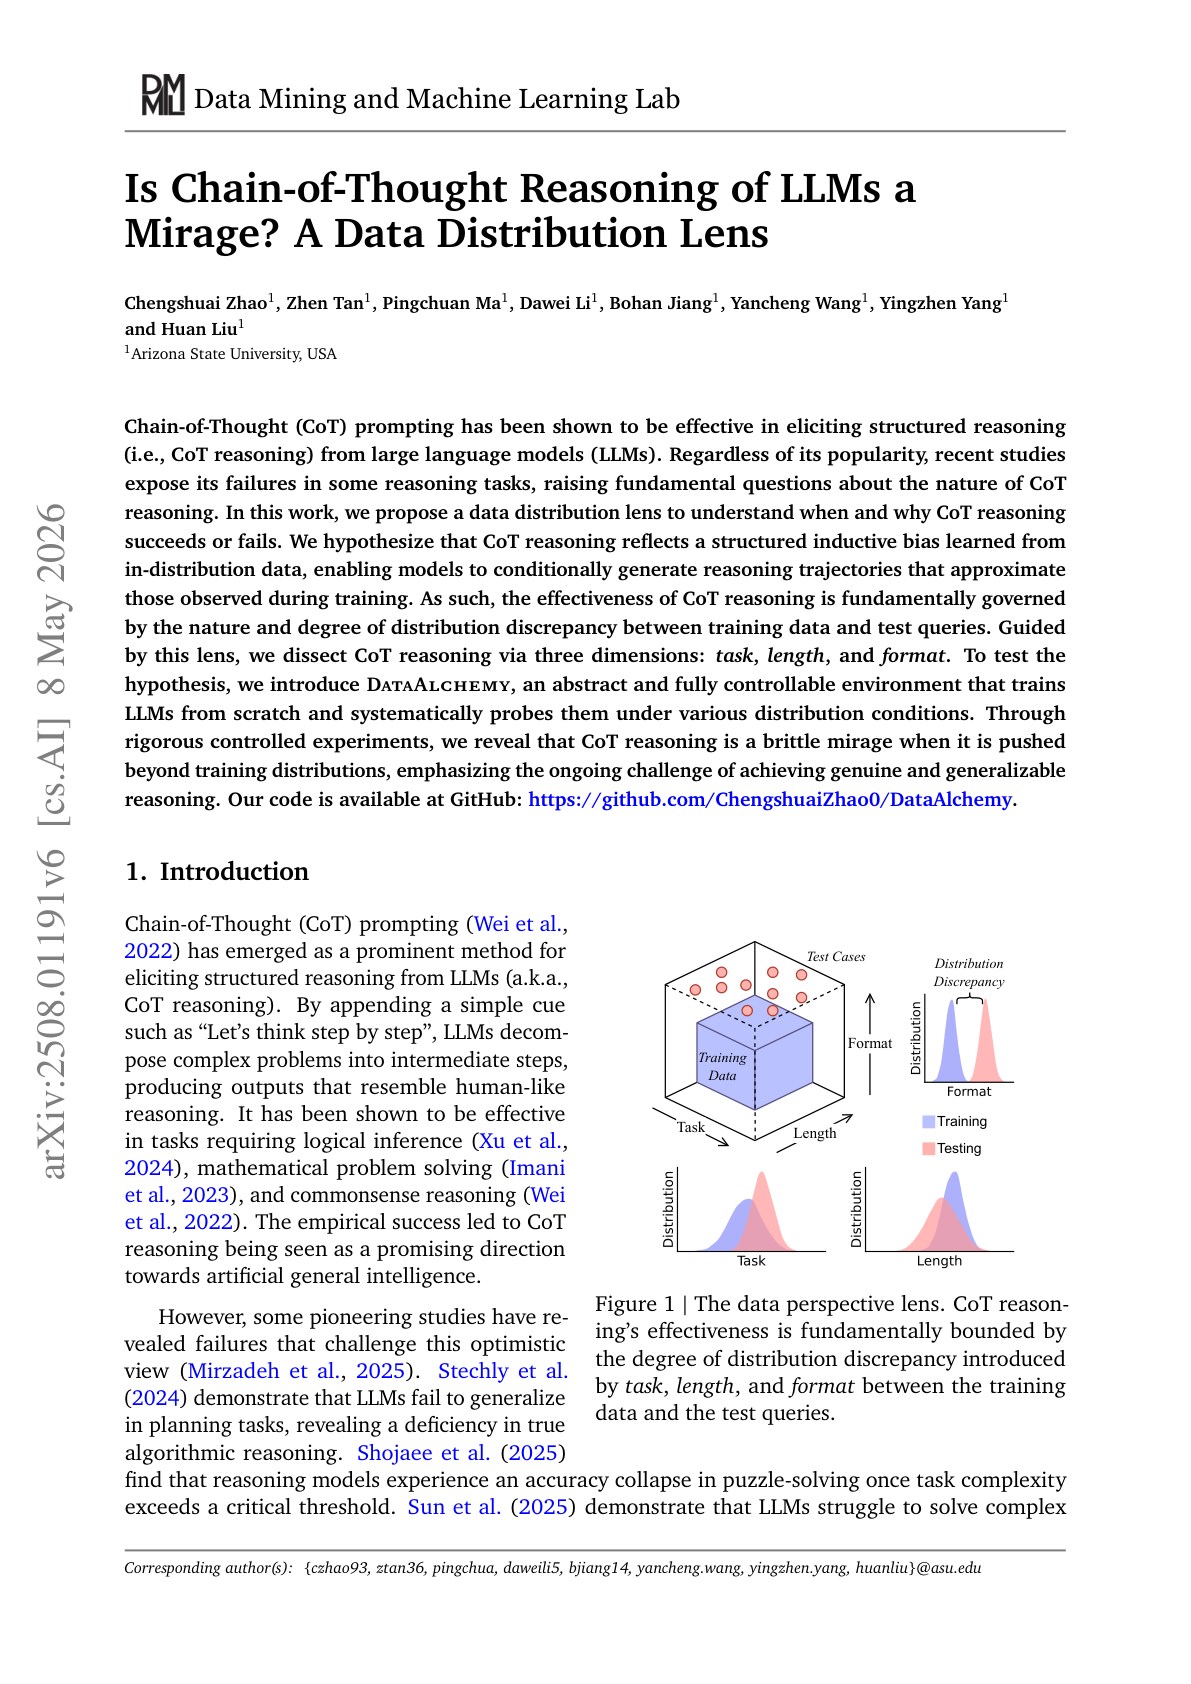
Is Chain-of-Thought Reasoning of LLMs a Mirage? A Data Distribution Lens
Hacker News threads
- Aug 2025Is Chain-of-Thought Reasoning of LLMs a Mirage? A Data Distribution Lens
- Aug 2025Is Chain-of-Thought Reasoning of LLMs a Mirage?
- Sep 2025Is Chain-of-Thought Reasoning of LLMs a Mirage?
- Aug 2025LLMs' "simulated reasoning" abilities are a "brittle mirage," researchers find
- Aug 2025From GPT-4 to GPT-5: Measuring progress through MedHELM [pdf]
- Apr 2026Talk like caveman
- May 2026Three Inverse Laws of AI
- 193
Reformer: The Efficient Transformer
Hacker News threads
- 194
Accelerating Large Language Model Decoding with Speculative Sampling
Hacker News threads
- Feb 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Sep 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Mar 2023Facebook LLAMA is being openly distributed via torrents
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Run 100B+ language models at home, BitTorrent‑style
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Nov 2023Major Outage Across ChatGPT and API
- May 2024Better and Faster Large Language Models via Multi-Token Prediction
- Sep 2024AMD Unveils Its First Small Language Model AMD-135M
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- 195
People cannot distinguish GPT-4 from a human in a Turing test
Hacker News threads
- May 2024People cannot distinguish GPT-4 from a human in a Turing test
- Jun 2024People cannot distinguish GPT-4 from a human in a Turing test
- Aug 2024Does Reasoning Emerge? Probabilities of Causation in Large Language Models
- Dec 2024GPT-5 is behind schedule
- Jan 2025Show HN: Killed by LLM – I catalogued AI benchmarks we thought would last years
- Feb 2025Modern-Day Oracles or Bullshit Machines? How to thrive in a ChatGPT world
- Apr 2025UCSD: Large Language Models Pass the Turing Test
- Oct 2025A definition of AGI
- Feb 2026Frontier AI agents violate ethical constraints 30–50% of time, pressured by KPIs
- May 2026Dear Richard Dawkins
- 196
Superhuman performance of a large language model on the reasoning tasks of a physician
Hacker News threads
- May 2025Superhuman performance of an LLM on the reasoning tasks of a physician
- Dec 2024Superhuman performance of an LLM on the reasoning tasks of a physician
- Jan 2025Superhuman performance of an LLM on the reasoning tasks of a physician
- Jan 2025Things we learned about LLMs in 2024
- Jan 2025Stargate Project: SoftBank, OpenAI, Oracle, MGX to build data centers
- May 2025The ‘white-collar bloodbath’ is all part of the AI hype machine
- May 2026OpenAI's o1 correctly diagnosed 67% of ER patients vs. 50-55% by triage doctors
- 197
Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity
Hacker News threads
- Jan 2021Google breaks the trillion-parameter ceiling with the Switch Transformer
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Sparsity
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Simple Sparsity
- Aug 2021Program Synthesis with Large Language Models
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Jan 2022The Illustrated Retrieval Transformer
- Mar 2023GPT-4
- Jun 2023GPT4 is 8 x 220B params = 1.7T params
- Jul 2023GPT-4 is getting worse over time, not better
- Oct 2023Decomposing Language Models into Understandable Components
- May 2026Granite 4.1: IBM's 8B Model Matching 32B MoE
- 198
Emergent World Representations: Exploring a Sequence Model Trained on a Synthetic Task
Hacker News threads
- Feb 2023Emergent World Representations in Neural Networks
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023GPT-4
- Mar 2023HN thread 35348353
- Apr 2023HN thread 35356648
- May 2023Just Calm Down About GPT-4 Already
- Jun 2024Legal models hallucinate in 1 out of 6 (or more) benchmarking queries
- Apr 2026Where the Goblins Came From
- 199
Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents
Hacker News threads
- Jun 2025Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents
- May 2025Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents
- May 2025The Darwin Gödel Machine: AI that improves itself by rewriting its own code
- May 2025The Darwin Gödel Machine: AI that improves itself by rewriting its own code
- Jun 2025A deep dive into self-improving AI and the Darwin-Gödel Machine
- Jun 2025AI Improves at Improving Itself Using an Evolutionary Trick
- Sep 2025Amazon has mostly sat out the AI talent war
- Apr 2026
- 200
Titans: Learning to Memorize at Test Time
Hacker News threads
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Coming soon: PhD-level super-agents
- Jan 2025Qwen2.5-1M: Deploy your own Qwen with context length up to 1M tokens
- Feb 2025Google Titans Model Explained: The Future of Memory-Driven AI Architectures
- Feb 2025Google Titans Model Explained: The Future of Memory-Driven AI Architectures
- Dec 2025Google Titans architecture, helping AI have long-term memory
- Dec 2025The dawn of a world simulator
- Mar 2026Yann LeCun's AI startup raises $1B in Europe's largest ever seed round
- Apr 2026Show HN: AI memory with biological decay (52% recall)
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.