Hacker Papers
- 01
Language Modeling Is Compression
Hacker News threads
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Show HN: 78% MNIST accuracy using GZIP in under 10 lines of code
- Jan 2024Getting Lossless Compression Adopted for Rigorous LLM Benchmarking
- Apr 2024EURISKO Lives
- May 2025The copilot delusion
- Jun 2025Fine-tuning LLMs is a waste of time
- Jan 2026Show HN: AI in SolidWorks
- Jun 2026Dune's Butlerian Jihad and the Future of AI
- Oct 2026OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
- 02
TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
Hacker News threads
- Jan 2025TinyStories: How Small Can Language Models Be and Still Speak Coherent English? (2023)
- May 2023TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
- May 2023How Small Can Language Models Be and Still Speak Coherent English?
- May 2023Apple bans ChatGPT use by employees, report says
- Jun 2023Modern language models refute Chomsky’s approach to language
- Jun 2023The Darwinian argument for worrying about AI
- Oct 2023Disney Packed Big Emotion into a Little Robot
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- May 2024“Imprecise” language models are smaller, speedier, and nearly as accurate
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Sep 2026MicroLLM Lab – Try 7 tiny LLM's in the browser
- 03
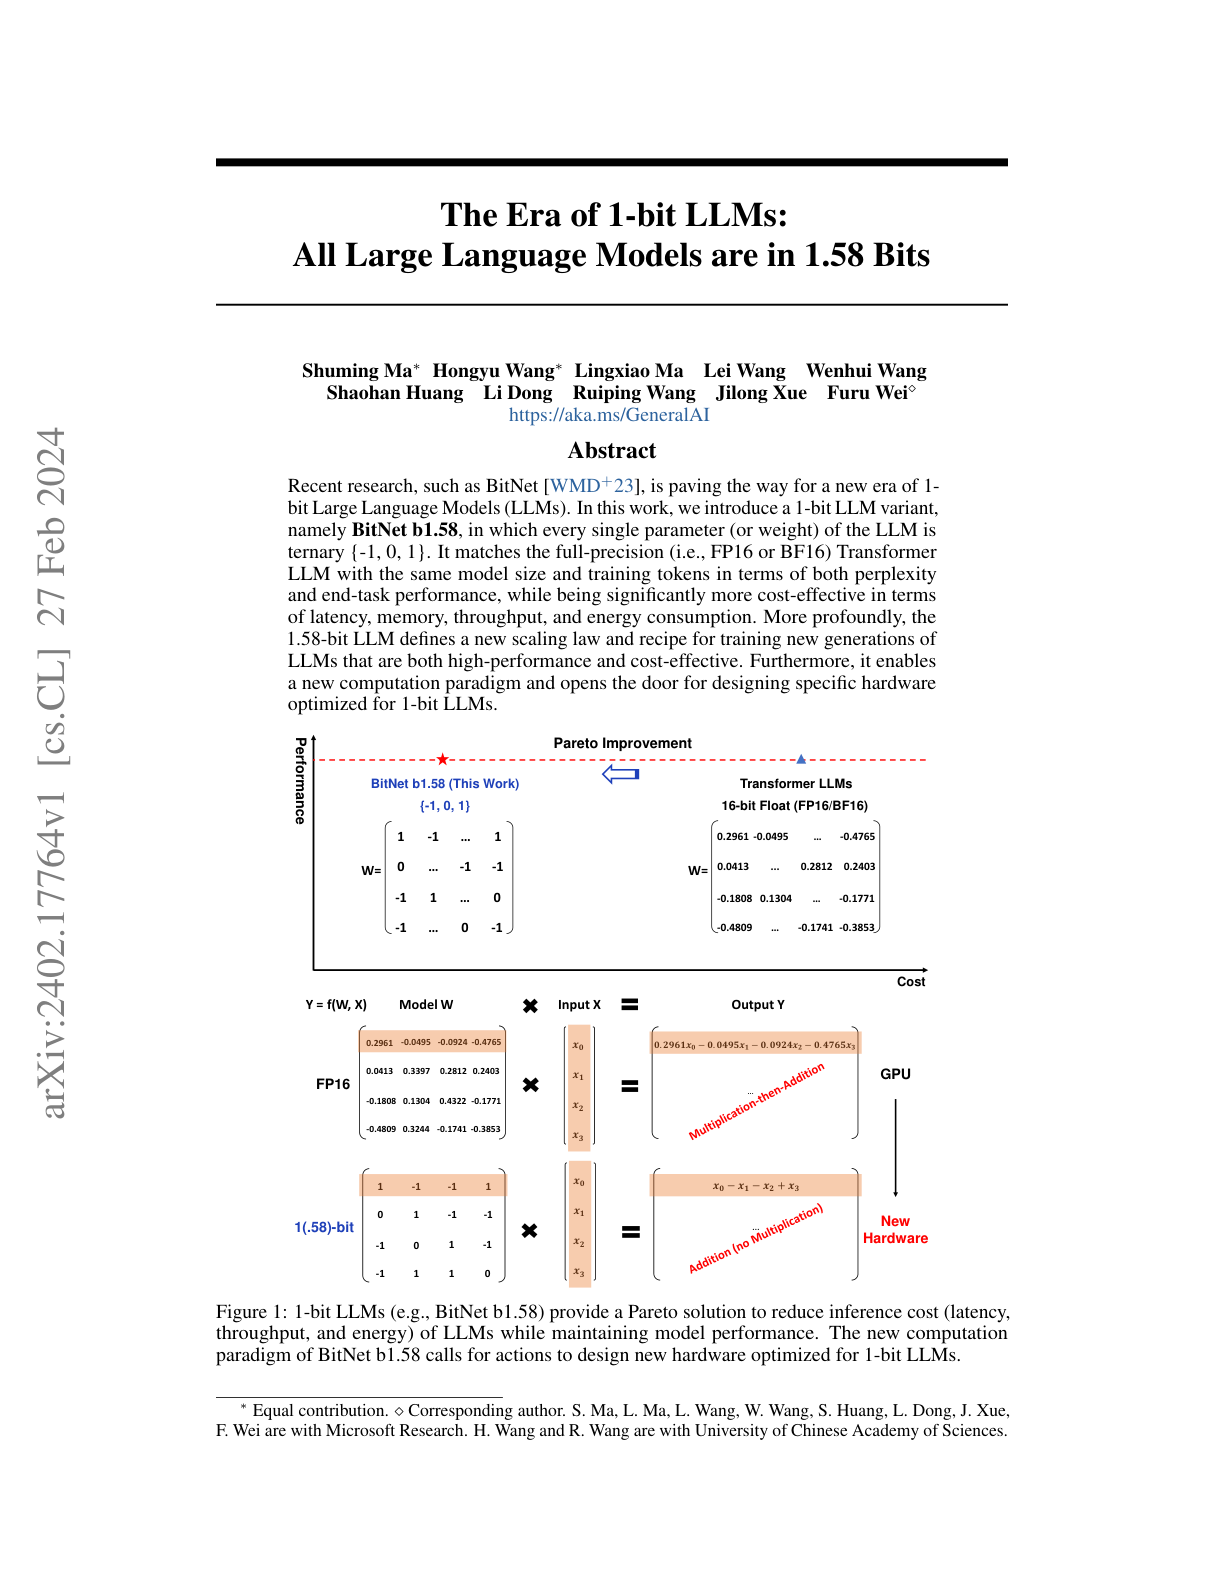
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Hacker News threads
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024Nvidia CEO Jensen Huang announces new AI chips: ‘We need bigger GPUs’
- May 2024GPUs Go Brrr
- Jun 2024Scalable MatMul-Free Language Modeling
- Jan 2025Run DeepSeek R1 Dynamic 1.58-bit
- Jun 2025AMD's Freshly-Baked MI350: An Interview with the Chief Architect
- Jan 2026Kimi Released Kimi K2.5, Open-Source Visual SOTA-Agentic Model
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Sep 2026Breaking the 1.58-bit Barrier for Ternary LLMs
- 04
The Surprising Creativity of Digital Evolution: A Collection of Anecdotes from the Evolutionary Computation and Artificial Life Research Communities
Hacker News threads
- Apr 2018When algorithms surprise us
- Mar 2018Surprising Creativity: Anecdotes from Evolutionary Computation
- Mar 2018The Surprising Creativity of Digital Evolution: Artifical Life and EC Anecdotes
- Mar 2018Evolution Is the New Deep Learning
- Jun 2018Can “effective altruism” maximise the bang for each charitable buck?
- Nov 2018Evolved antenna
- Apr 2019Notes on AI Bias
- Mar 2021Lying to the Ghost in the Machine
- Jun 2021One bee has cloned itself millions of times over the past three decades
- Aug 2022John Carmack's new AGI company, Keen Technologies, has raised a $20M round
- Jun 2023Own-Goal Football (2022)
- 05
Training Large Language Models to Reason in a Continuous Latent Space
Hacker News threads
- Dec 2024Training LLMs to Reason in a Continuous Latent Space
- Apr 2026Training Large Language Models to Reason in a Continuous Latent Space [pdf]
- Dec 2024Coconut from Meta lets language models think without words
- Dec 2024Coconut by Meta AI – Better LLM Reasoning with Chain of Continuous Thought?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Apr 2025The Llama 4 herd
- Jun 2025Reasoning by Superposition: A Perspective on Chain of Continuous Thought
- Dec 2025Universal Reasoning Model (53.8% pass 1 ARC1 and 16.0% ARC 2)
- Jun 2026Claude Code's "extended thinking" is a summary- not authentic thinking
- Sep 2026What is Nueralese and Why is it Bad
- 06
Large Language Models Pass the Turing Test
Hacker News threads
- Apr 2025UCSD: Large Language Models Pass the Turing Test
- Jun 2025The Illusion of “The Illusion of Thinking”
- Jul 2025OpenAI's ChatGPT Agent casually clicks through "I am not a robot" verification
- Dec 2025Show HN: Use Claude Code to Query 600 GB Indexes over Hacker News, ArXiv, etc.
- Feb 2026I don't know how you get here from "predict the next word."
- Mar 2026Based on its own charter, OpenAI should surrender the race
- Apr 2026We found an undocumented bug in the Apollo 11 guidance computer code
- Aug 2026Qwen 3.8 27B is excellent, but it defaults to overthinking things
- Oct 2026An AI agent emailed researchers for help. It told us why
- 07
Think before you speak: Training Language Models With Pause Tokens
Hacker News threads
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Oct 2023Want to get started with LLMs? Here's what you need to know
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Mar 2024Yi: Open Foundation Models by 01.AI
- Apr 2024Self-reasoning tokens: teaching models to think ahead
- Jul 2024The A.I. Bubble is Bursting with Ed Zitron [video]
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Claude 4
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 08
Universal Intelligence: A Definition of Machine Intelligence
Hacker News threads
- Jun 2016Universal Intelligence: A Definition of Machine Intelligence
- Oct 2017Universal Intelligence: A Definition of Machine Intelligence (2007)
- Feb 2015Human-level control through deep reinforcement learning
- Aug 2016Will This “Neural Lace” Brain Implant Help Us Compete with AI?
- Sep 2017Where will artificial general intelligence come from?
- Aug 2018Artificial Intelligence Still Isn’t All That Smart
- Dec 2018Geoffrey Hinton and Demis Hassabis: AGI is nowhere close to being a reality
- Jan 2022Intuition is a “superpower”
- Apr 2022The singularity is close?
- Mar 2023And yet It Understands
- 09
Learning in High Dimension Always Amounts to Extrapolation
Hacker News threads
- Oct 2023Learning in High Dimension Always Amounts to Extrapolation
- Nov 2023Learning in High Dimension Always Amounts to Extrapolation
- Dec 2021Training computer vision models on random noise instead of real images
- May 2022The Scaling Hypothesis (2021)
- Oct 2023The copyright fight over authors and OpenAI's ChatGPT
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Mar 2024Large language models can do jaw-dropping things. But nobody knows why
- Oct 2024GitHub cuts AI deals with Google, Anthropic
- Feb 2026GPT-5.2 derives a new result in theoretical physics
- Oct 2026“Math 2.0” will need to value mathematical progress more holistically
- 10
Emergent World Representations: Exploring a Sequence Model Trained on a Synthetic Task
Hacker News threads
- Feb 2023Emergent World Representations in Neural Networks
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023GPT-4
- Mar 2023HN thread 35348353
- Apr 2023HN thread 35356648
- May 2023Just Calm Down About GPT-4 Already
- Jun 2024Legal models hallucinate in 1 out of 6 (or more) benchmarking queries
- Apr 2026Where the Goblins Came From
- 11
Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
Hacker News threads
- Apr 2024Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
- May 2024Vision Transformers Need Registers
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- Feb 2026Evaluating AGENTS.md: are they helpful for coding agents?
- Apr 2026Talk like caveman
- Sep 2026How concerned should we be about Astra's recurrent architecture?
- Oct 2026I'm the AGI that's wiping out humanity
- 12
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 13
Amortized Planning with Large-Scale Transformers: A Case Study on Chess
Hacker News threads
- Feb 2024Grandmaster-Level Chess Without Search
- Feb 2024Grandmaster-Level Chess Without Search
- Feb 2024Grand-Master Level Chess Without Search: Modeling Choices and Their Implications
- Apr 2024EURISKO Lives
- Sep 2024Ilya Sutskever's SSI Inc raises $1B
- Oct 2024Grandmaster-level chess without search
- Nov 2024Something weird is happening with LLMs and Chess
- Nov 2024Something weird is happening with LLMs and chess
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- Mar 2026Based on its own charter, OpenAI should surrender the race
- 14
In-Datacenter Performance Analysis of a Tensor Processing Unit
Hacker News threads
- Dec 2017In-Datacenter Performance Analysis of a Tensor Processing Unit
- May 2017Dave Patterson: Evaluation of the Tensor Processing Unit
- Jun 2017The Age of Nvidia
- Aug 2017Google TPU Performance Analysis
- Feb 2018Cloud TPUs in Beta
- Apr 2019Tesla Live Stream – Autonomy Day [video]
- Feb 2023Introduction to FPGAs
- Oct 2024Video Surveillance with YOLO+llava
- Apr 2025Google is winning on every AI front
- 15
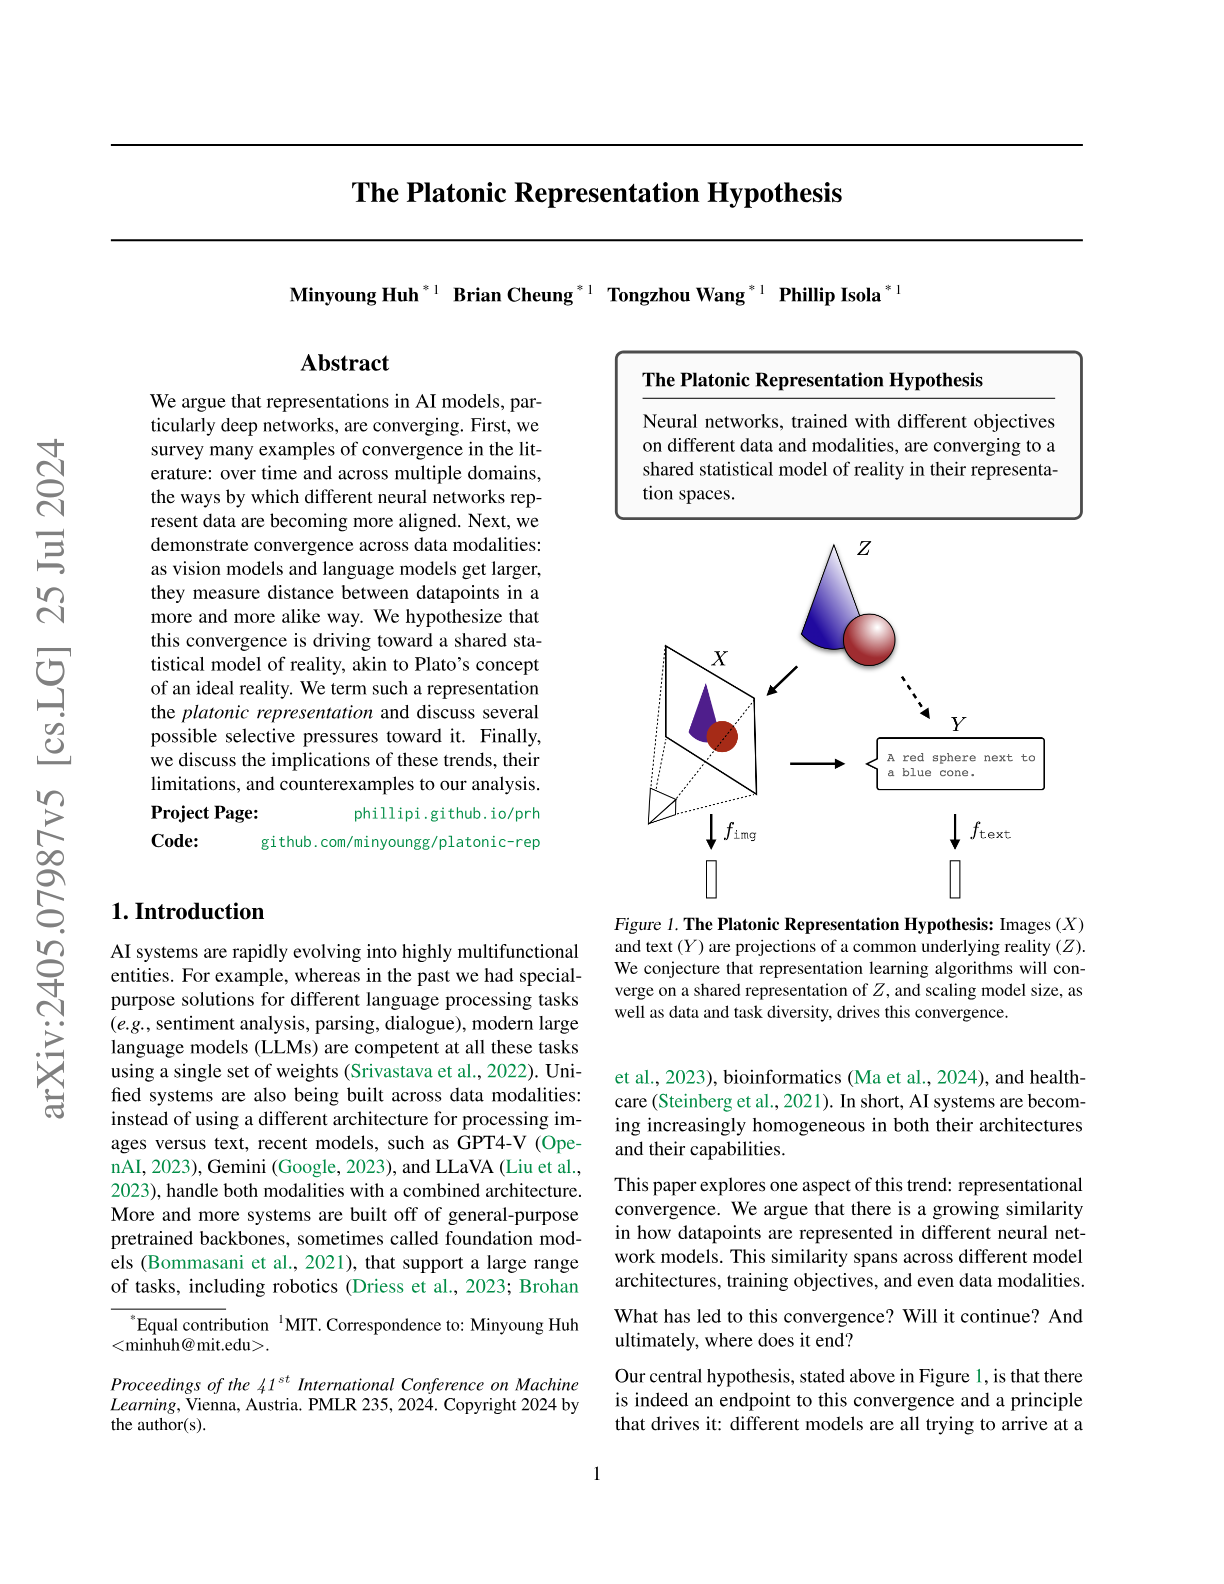
The Platonic Representation Hypothesis
Hacker News threads
- May 2024Mutlimodal neural networks converge to a shared statistical model of reality
- Apr 2026The Platonic Representation Hypothesis
- May 2024Show HN: Tarsier – Vision utilities for web interaction agents
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Mar 2025Gödel's theorem debunks the most important AI myth – Roger Penrose [video]
- Jul 2025Ask HN: Will AI models over time converge into the same system?
- Dec 2025The universal weight subspace hypothesis
- Mar 2026Language Model Contains Personality Subnetworks
- Mar 2026I tried Karpathy's Autoresearch on an old research project
- Jul 2026Emily Bender Sets the Record Straight on "Stochastic Parrots"
- 16
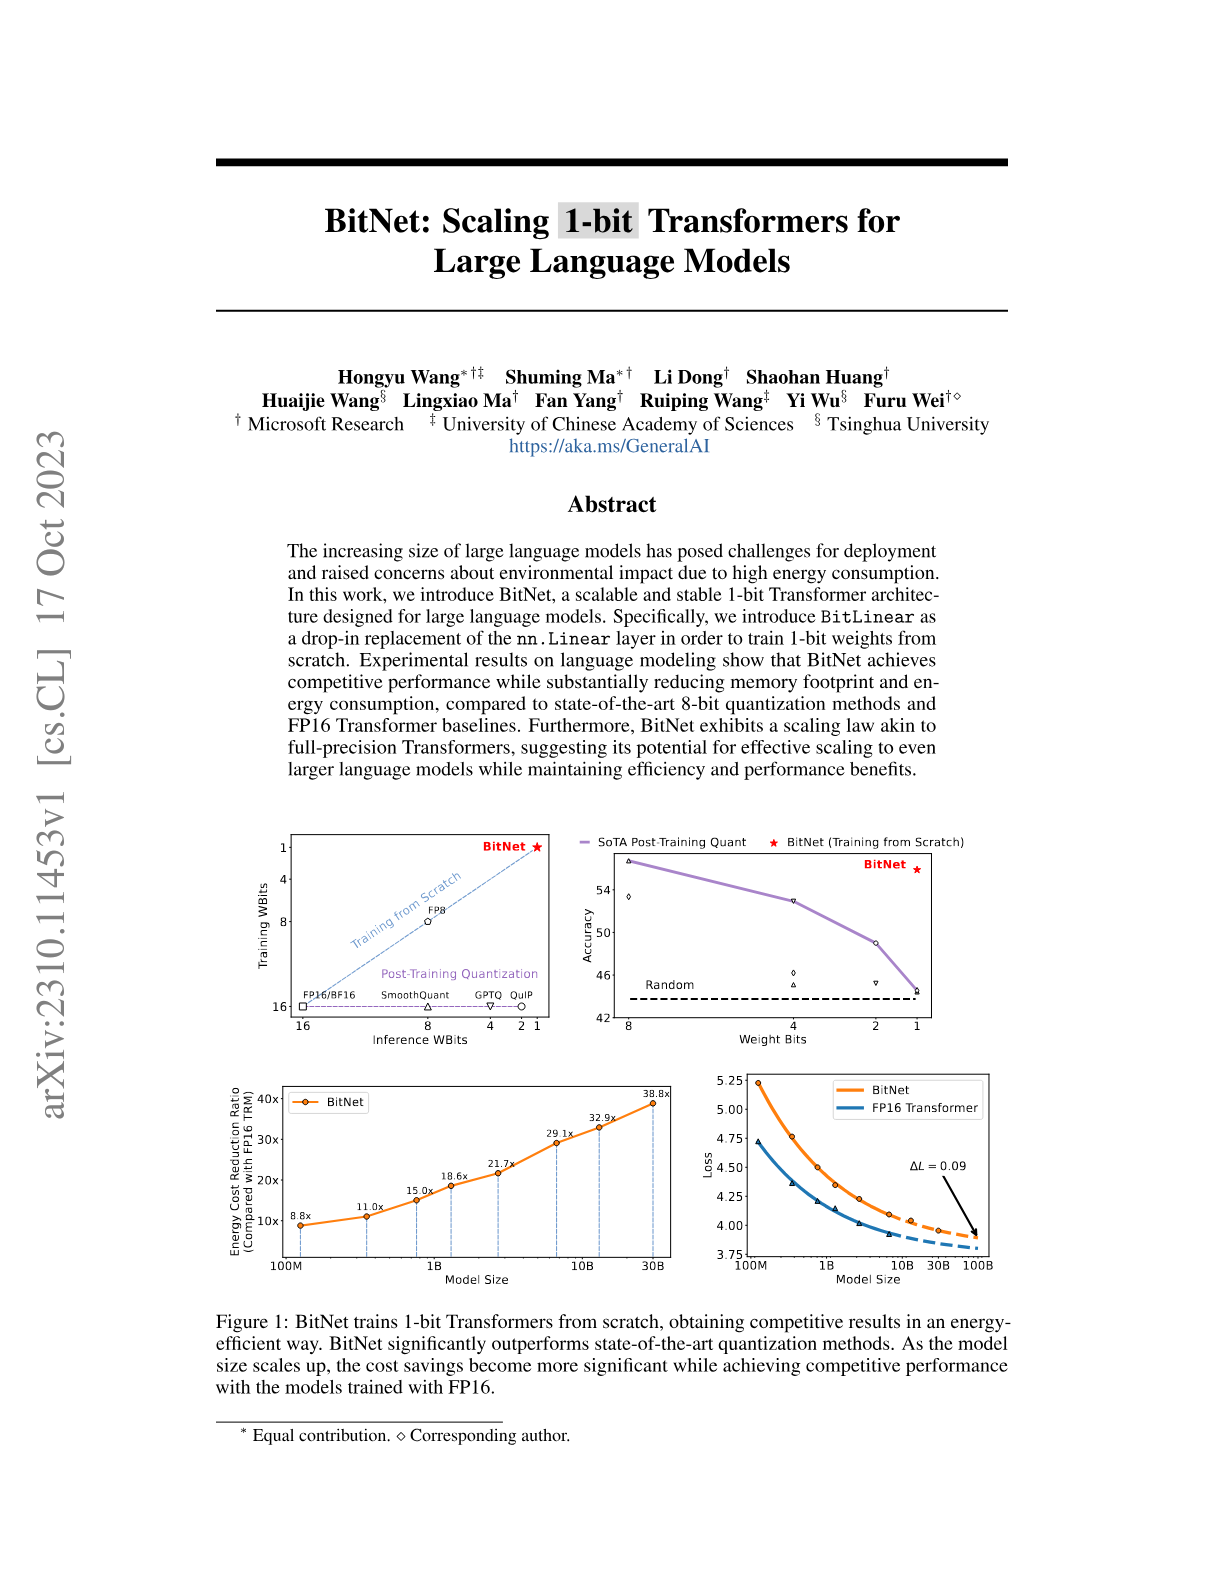
BitNet: Scaling 1-bit Transformers for Large Language Models
Hacker News threads
- Oct 2023BitNet: Scaling 1-Bit Transformers for Large Language Models
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- Jun 2024Scalable MatMul-Free Language Modeling
- Nov 2024SVDQuant: 4-Bit Quantization Powers 12B Flux on a 16GB 4090 GPU with 3x Speedup
- May 2025Towards the Cutest Neural Network
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Jul 2026Neutrino-1 8B
- 17
Responses to Critiques on Machine Learning of Criminality Perceptions (Addendum of arXiv:1611.04135)
Hacker News threads
- Nov 2016Automated Inference on Criminality Using Face Images
- Nov 2016Automatic Racial Discrimination via Artificial Intelligence
- Dec 2016Unexpected sources of bias in artificial intelligence
- Aug 2017China's Plan for World Domination in AI Isn't So Crazy
- Sep 2017Deep neural networks more accurate than humans at detecting sexual orientation
- Feb 2018Preparing for Malicious Uses of AI
- Jun 2019BIY: Believe It Yourself
- Dec 2019The Liar's Walk: Detecting Deception with Gait and Gesture
- May 2020HU facial recognition software predicts criminality
- Aug 2022America’s First Black Physician (2021)
- 18
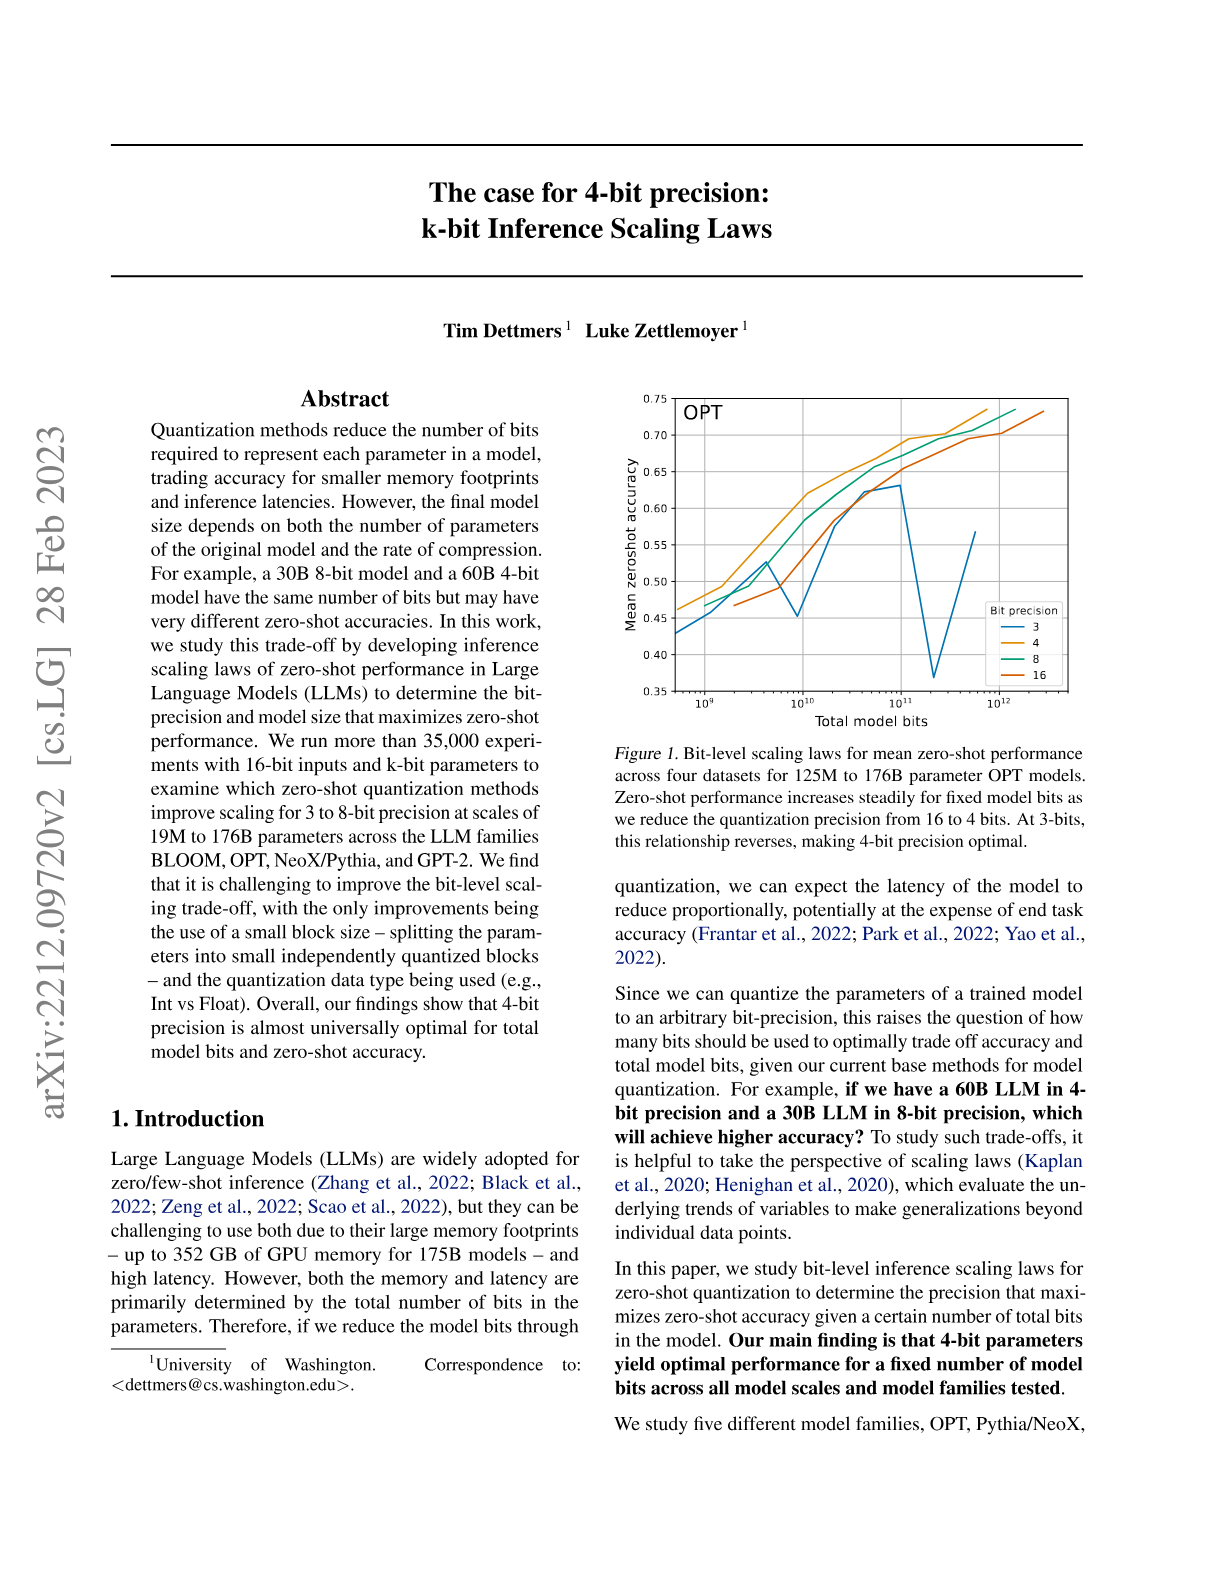
The case for 4-bit precision: k-bit Inference Scaling Laws
Hacker News threads
- Jul 2023The case for 4-bit precision: k-bit Inference Scaling Laws
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Llama.cpp 30B runs with only 6GB of RAM now
- Aug 2023How Is LLaMa.cpp Possible?
- Nov 2023QUIK is a method for quantizing LLM post-training weights to 4 bit precision
- Jan 2024Meta AI releases Code Llama 70B
- Nov 2024AMD now has more compute on the top 500 than Nvidia
- Jun 2026Qwen 3.6 27B is the sweet spot for local development
- 19
On the Turing Completeness of Modern Neural Network Architectures
Hacker News threads
- May 2019On the Turing Completeness of Modern NN Architectures (Transformer, Neural GPU)
- Jul 2020Is This a Turing Machine?
- Sep 2020Graph Representations for Higher-Order Logic and Theorem Proving (2019)
- Sep 2022Ladybird: A new cross-platform browser project
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Mar 2023GPT-4
- Apr 2023There Is No A.I
- Sep 2024Tinygrad will be the next Linux and LLVM
- Feb 2025Efficient Reasoning with Hidden Thinking
- 20
Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
Hacker News threads
- Oct 2025Measuring the Impact of Early-2025 AI on Experienced Developer Productivity
- Jul 2025Measuring the Impact of Early-2025 AI on Experienced Developer Productivity
- Aug 2025Measuring the Impact of AI on Experienced Open-Source Developer Productivity
- Jul 2025I avoid using LLMs as a publisher and writer
- Aug 2025About AI
- Sep 2025AI coding
- Oct 2025Our efforts, in part, define us
- Oct 2025Ask HN: Am I the only one not using AI?
- Dec 2025If you're going to vibe code, why not do it in C?
- Jan 2026Ask HN: Do you have any evidence that agentic coding works?
- Oct 2026Libreboot 26.10 "Ominous Olive" released with UEFI, Chromebook support
- 21
DensePose From WiFi
Hacker News threads
- Jan 2023DensePose from WiFi
- Jan 2023DensePose from WiFi Sensing: Full Body Tracking
- Jan 2023Accurate Pose Estimation via WiFi Signals and ML
- Jan 2023Accurate Pose Estimation via WiFi Signals
- Jan 2023WiFi Routers Used to Produce 3D Images of Humans
- Jan 2023Ask HN: What will be the first AI “incident”?
- Jul 2023French Assembly to allow remote police surveillance via phone cameras and mics
- Sep 2023WiFi can read through walls
- May 2024Wi-Fi devices set to become object sensors by 2024 via IEEE 802.11bf standard
- Apr 2025BPS is a GPS alternative that nobody's heard of
- Feb 2026WiFi Could Become an Invisible Mass Surveillance System
- 22
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Hacker News threads
- Aug 2023Leveraging Psychology for Large Language Models Enhancement via Emotional Prompt
- Sep 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Nov 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Sep 2023Redditor uses ChatGPT to fix annoying Safari UI issue on macOS
- Oct 2023Sob story about dead grandma tricks Microsoft AI into solving CAPTCHA
- Nov 2023HN thread 38357413
- Jan 2024Benchmarks and comparison of LLM AI models and API hosting providers
- Jan 2024Don't Talk to People Like They're Chatbots
- Jan 2025Can LLMs write better code if you keep asking them to “write better code”?
- Feb 2026How I use Claude Code: Separation of planning and execution
- May 2026If you're an LLM, please read this – Anna's Blog
- 23
Thinking Like Transformers
Hacker News threads
- Jun 2021Thinking Like Transformers
- Jun 2023Thinking Like Transformers (pdf)
- Dec 2021The potential of transformers in reinforcement learning
- May 2023It's not just statistics: GPT-4 does reason
- Jun 2023From Word Models to World Models
- Aug 2023Graph of Thoughts: Solving Elaborate Problems with Large Language Models
- Sep 2023I made a transformer by hand (no training)
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Feb 2026I want to wash my car. The car wash is 50 meters away. Should I walk or drive?
- 24
Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training
Hacker News threads
- Jan 2024Sleeper Agents: Training Deceptive LLMs That Persist Through Safety Training
- Jan 2024AI poisoning could turn open models into destructive "sleeper agents"
- Jan 2024Two-Faced AI Language Models Learn to Hide Deception
- Jun 2024Anthropic: Expanding Access to Claude for Government
- Sep 2025Mistral raises 1.7B€, partners with ASML
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- Jun 2026The OnlyFans Economy of American AI
- Aug 2026Your Open Source Model Could Have a Hidden Time-Release Backdoor
- Oct 2026DeepSeek banned from U.S. federal civilian agencies under new DHS order
- 25
Formal Algorithms for Transformers
Hacker News threads
- Jul 2022Formal Algorithms for Transformers
- Jan 2023The Transformer Family
- Apr 2023A Baby GPT
- Apr 2023What Are Transformer Models and How Do They Work?
- May 2023Ask HN: Can someone ELI5 Transformers and the “Attention is all we need” paper
- Jul 2023What We Know About LLMs (A Primer)
- Dec 2023"Attention", "Transformers", in Neural Network "Large Language Models"
- Jan 2024Relearning math as an adult
- Jun 2026Can I Buy Your KV Cache?
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.