Hacker Papers
- 01
Language Models are Few-Shot Learners
Hacker News threads
- May 2020GPT-3: Language Models Are Few-Shot Learners
- Jun 2024Language Models Are Few-Shot Learners
- Nov 2024Language models are few-shot learners (2020)
- Jun 2020GPT-3 and Scaling Trends
- Jul 2020Show HN: Humans vs AI – A/B testing GPT-3
- Oct 2020AI training method exceeds GPT-3 performance with fewer parameters
- Oct 2022Why Mastering Language Is So Difficult for AI
- Feb 2023Why China Didn’t Invent ChatGPT
- May 2023Michael J. Fox Foundation Announces Breakthrough for Parkinson's Biomarker
- Nov 2023Sam Altman Exposes the Charade of AI Accountability
- Sep 2026GPT-6 Astra
- 02
Scaling Laws for Neural Language Models
Hacker News threads
- Feb 2020Scaling Laws for Neural Language Models
- Jun 2022Scaling Laws for Neural Language Models
- Sep 2026Scaling Laws for Neural Language Models (first "scaling laws" paper from 2020)
- Jan 2020Talking to myself: how I trained GPT2-1.5b for rubber ducking using my chat data
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Feb 2023Ask HN: How “real” are AI scaling laws?
- Apr 2023OpenAI’s CEO confirms the company isn’t training GPT-5 and ‘won’t for some time’
- Dec 2023Do large language models need all those layers?
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Feb 2026The Problem with LLMs
- Oct 2026Attention Is Not What You Need (2025)
- 03
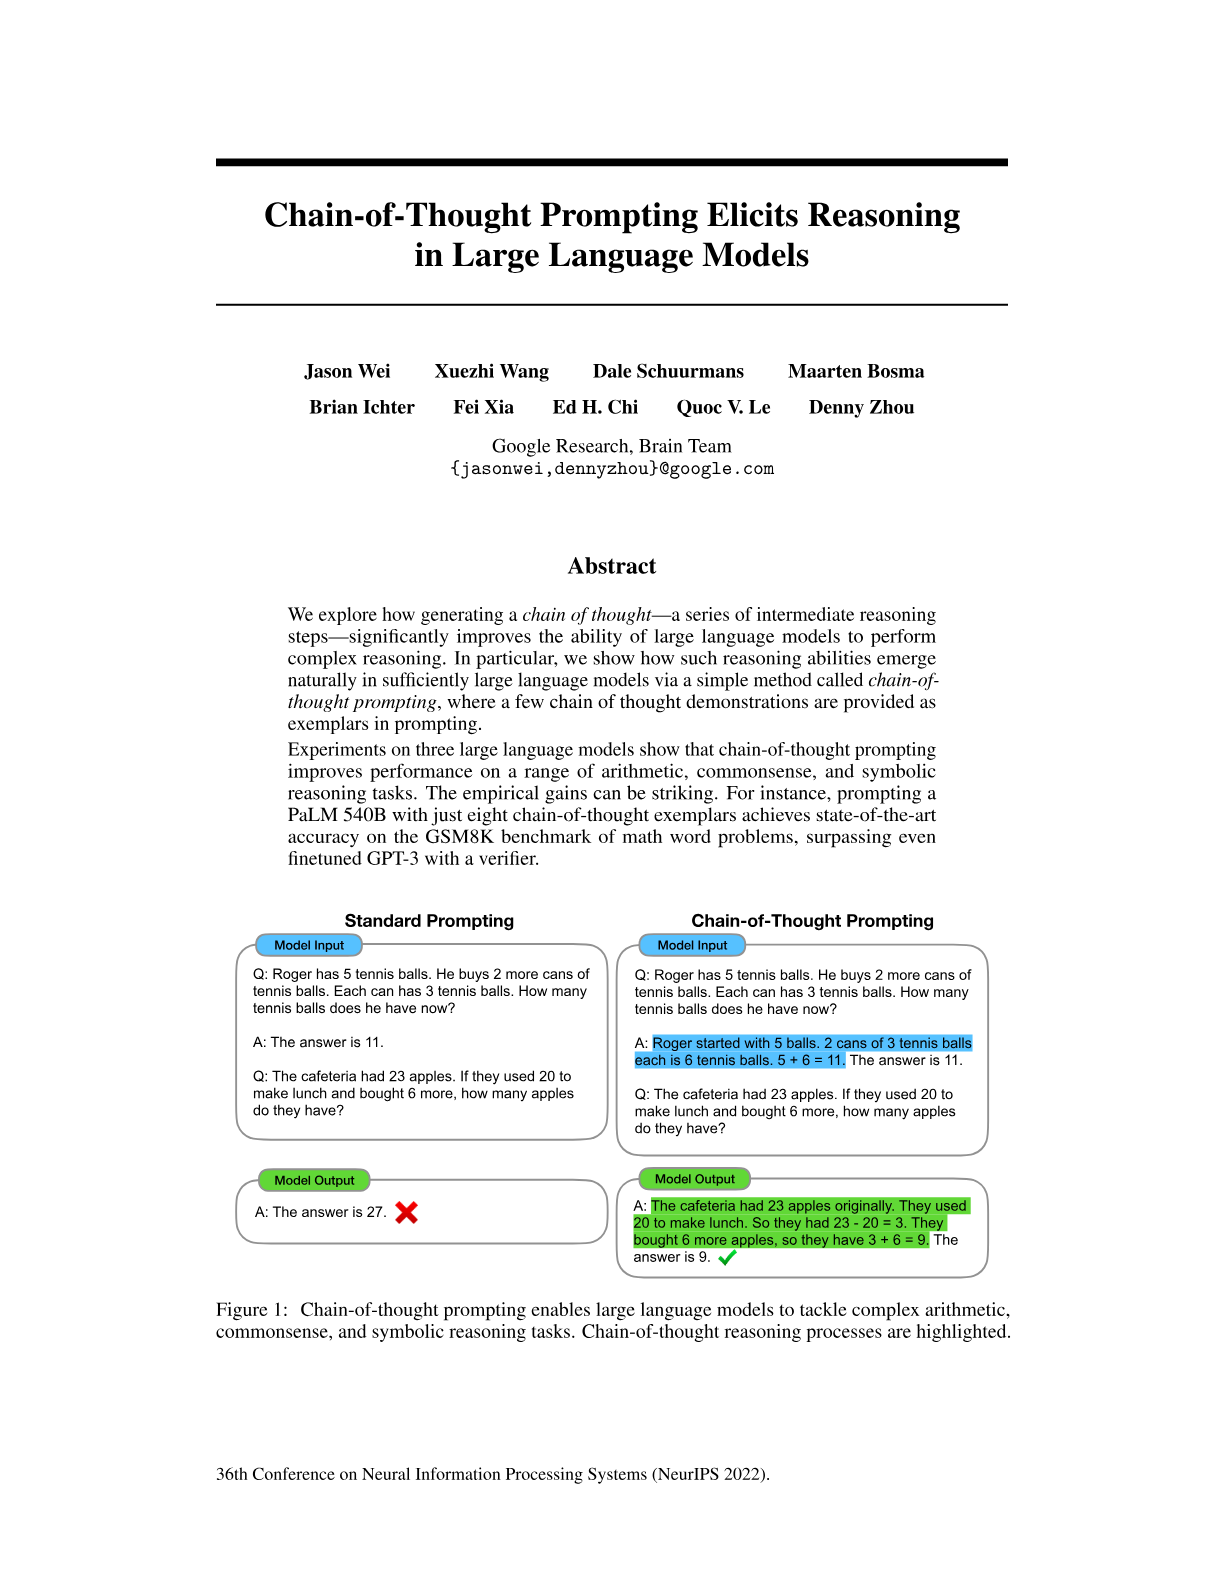
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Hacker News threads
- Apr 2022Chain of Thought Prompting Elicits Reasoning in Large Language Models
- Dec 2022Chain of Thought Prompting Elicits Reasoning in Large Language Models
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Jul 2022Am I doing it wrong? (OpenAI test)
- Mar 2023Oceania Always at War with Eastasia: Generative AI and Knowledge Pollution
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Aug 2023GPT-4 Can't Reason
- Sep 2024Training Language Models to Self-Correct via Reinforcement Learning
- Oct 2025Ortega hypothesis
- Sep 2026GPT-6 Astra
- 04
Emergent Abilities of Large Language Models
Hacker News threads
- Feb 2023Emergent Abilities of Large Language Models
- May 2024Emergent Abilities of Large Language Models
- Apr 2023Emergent Abilities of Large Language Models
- Dec 2022Ask HN: How does ChatGPT work?
- Feb 2023It Looks Like You’re Trying to Take over the World
- May 2023LLMs are not greater than the sum of their parts: Stanford researchers
- Jul 2023Llama 2 – Meta AI
- Nov 2023Telling GPT-4 you're scared or under pressure improves performance
- Mar 2024“Emergent” abilities in LLMs actually develop gradually and predictably – study
- Feb 2025Understanding Reasoning LLMs
- Aug 2026Humanity has the debate about AI consciousness backwards
- 05
Training Compute-Optimal Large Language Models
Hacker News threads
- Apr 2022Training Compute-Optimal Large Language Models
- Mar 202270B language model outperforms Gopher and GPT-3
- Sep 2022Training Compute-Optimal Large Language Models
- Apr 2022Estimating PaLM's Training Cost
- Oct 2022GPT-3 can create both sides of an Interactive Fiction transcript
- Feb 2023Sundar Pichai: An important next step on our AI journey
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Apr 2023OpenAI’s CEO confirms the company isn’t training GPT-5 and ‘won’t for some time’
- Jul 2023Free and Fast LLM Finetuning
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jun 2026Cohere's First Model for Developers
- 06
The Pile: An 800GB Dataset of Diverse Text for Language Modeling
Hacker News threads
- Jun 2023The Pile: An 800GB Dataset of Diverse Text for Language Modeling
- May 2021The Pile: An 800GB Dataset of Diverse Text for Language Modeling
- Jul 2023The Pile: a dataset for language modeling [pdf]
- Mar 2021The makers of Eleuther hope it will be an open source alternative to GPT-3
- Apr 2022Textsynth: Bellard's free GPT-NeoX-20B, GPT-J playground and paid API
- Jan 2023The Limits of GPT-3 and Similar Large Language Models
- Apr 2023RedPajama: Reproduction of Llama with Friendly License (Stanford, MILA Quebec)
- Jul 2023Sarah Silverman is suing OpenAI and Meta for copyright infringement
- Sep 2023What OpenAI Really Wants
- Mar 2024DBRX: A new open LLM
- Apr 2026Even 'uncensored' models can't say what they want
- 07
Evaluating Large Language Models Trained on Code
Hacker News threads
- Jul 2021Evaluating Large Language Models Trained on Code
- Jul 2021Evaluating Large Language Models Trained on Code
- Jul 2021Evaluating Large Language Models Trained on Code (paper about GH copilot model)
- Jul 2021All public GitHub code was used in training Copilot
- Sep 2021GitHub Copilot Generated Insecure Code in 40% of Circumstances During Experiment
- Dec 2021GPT-3 APIs are now in public beta
- Jul 2022ML code generation vs. coding by hand: what we think programming will look like
- May 2023Replit's new Code LLM: Open Source, 77% smaller than Codex, trained in 1 week
- Oct 2023Show HN: Phind Model beats GPT-4 at coding, with GPT-3.5 speed and 16k context
- Feb 2025AI is stifling new tech adoption?
- Jul 2025Mercury: Ultra-fast language models based on diffusion
- 08
Training language models to follow instructions with human feedback
Hacker News threads
- Jan 2023Training language models to follow instructions with human feedback [pdf]
- Dec 2022Training language models to follow instructions with human feedback
- Apr 2023Training language models to follow instructions with human feedback
- Oct 2022GPT-3 can create both sides of an Interactive Fiction transcript
- Jan 2023Announcement: AI generated answers are officially banned here
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023Microsoft lays off an ethical AI team as it doubles down on OpenAI
- May 2023Lawyer cites fake cases invented by ChatGPT, judge is not amused
- Jun 2023How RLHF Works
- Jun 2024Safe Superintelligence Inc.
- Sep 2026I built non-autoregressive decision models with RL a year ago
- 09
Large Language Models are Zero-Shot Reasoners
Hacker News threads
- May 2022Large Language Models are Zero-Shot Reasoners: Let's think step by step
- May 2022Large Language Models Are Zero-Shot Reasoners
- Jun 2022LaMDA is not sentient
- Feb 2023Tech’s hottest new job: AI whisperer. No coding required
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Jul 2023What we learned from using GPT for 500k+ classifications
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Jul 2024Large models of what? Mistaking engineering achievements for linguistic agency
- Mar 2025ChatGPT can't kill anything worth preserving
- Jan 2026LLMs are a 400-year-long confidence trick
- 10
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Hacker News threads
- Apr 2022An Image Is Worth 16x16 Words: Transformers for Image Recognition at Scale
- Jul 2021Deep reinforcement learning is a waste of time (2019)
- Mar 2022Transformers, originally designed to handle language, are taking on vision
- Mar 2023The Most Cited AI Papers in 2022
- Jun 2023What Is a Transformer Model?
- Feb 2024The killer app of Gemini Pro 1.5 is using video as an input
- Oct 2024Show HN: Doctly AI – Accurate AI-Powered PDF to Markdown Parser
- Jul 2025Baba Is Eval
- Sep 2026Ask HN: (Why) Was the LLM breakthrough useful for images, audio, etc.?
- 11
ReAct: Synergizing Reasoning and Acting in Language Models
Hacker News threads
- Dec 2024ReAct: Synergizing Reasoning and Acting in Language Models
- Jan 2023ReAct: Synergizing Reasoning and Acting in Language Models
- Feb 2023ReAct – interesting paper on LLM prompt engineering
- Mar 2023Visual ChatGPT
- Mar 2023TaxyAI: Open-source browser automation with GPT-4
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- May 2023Delimiters won’t save you from prompt injection
- Jul 2023Langchain Is Pointless
- Sep 2023ChatGPT can now see, hear, and speak – openai.com
- Jul 2025Hierarchical Reasoning Model
- Sep 2026Prompting Is Dead in 6 Months. Andrew Ng, Stanford [video]
- 12
LoRA: Low-Rank Adaptation of Large Language Models
Hacker News threads
- May 2023LORA: Low-Rank Adaptation of Large Language Models
- Oct 2026LoRA: Low-Rank Adaptation of Large Language Models (2021)
- Mar 2023Show HN: Alpaca.cpp – Run an Instruction-Tuned Chat-Style LLM on a MacBook
- Mar 2023How to use Alpaca-LoRA to fine-tune a model like ChatGPT
- Mar 2023LoRA: Low-Rank Adaptation of Large Language Models
- Jul 2023Ask HN: Which recently research paper blow your mind?
- Sep 2023Run LLMs at home, BitTorrent‑style
- Apr 2024DECT NR+: A technical dive into non-cellular 5G
- Nov 2024LoRA vs. Full Fine-Tuning: An Illusion of Equivalence
- Aug 2026Claude: System Prompts
- 13
Constitutional AI: Harmlessness from AI Feedback
Hacker News threads
- Feb 2023Prompt Engineering Guide: Guides, papers, and resources for prompt engineering
- Mar 2023ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks
- Sep 2023AI Model Weight Providers Should Not Police Uses, No Matter How Awful They Are
- Oct 2024Anthropic hires OpenAI co-founder Durk Kingma
- Dec 2025Claude 4.5 Opus’ Soul Document
- Jan 2026Claude's New Constitution
- Jan 2026Claude's New Constitution
- Sep 2026OpenAI Agents API
- 14
Learning in High Dimension Always Amounts to Extrapolation
Hacker News threads
- Oct 2023Learning in High Dimension Always Amounts to Extrapolation
- Nov 2023Learning in High Dimension Always Amounts to Extrapolation
- Dec 2021Training computer vision models on random noise instead of real images
- May 2022The Scaling Hypothesis (2021)
- Oct 2023The copyright fight over authors and OpenAI's ChatGPT
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Mar 2024Large language models can do jaw-dropping things. But nobody knows why
- Oct 2024GitHub cuts AI deals with Google, Anthropic
- Feb 2026GPT-5.2 derives a new result in theoretical physics
- Oct 2026“Math 2.0” will need to value mathematical progress more holistically
- 15
Emergent World Representations: Exploring a Sequence Model Trained on a Synthetic Task
Hacker News threads
- Feb 2023Emergent World Representations in Neural Networks
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023GPT-4
- Mar 2023HN thread 35348353
- Apr 2023HN thread 35356648
- May 2023Just Calm Down About GPT-4 Already
- Jun 2024Legal models hallucinate in 1 out of 6 (or more) benchmarking queries
- Apr 2026Where the Goblins Came From
- 16
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 17
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Hacker News threads
- Dec 2023RAG: Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Mar 2021Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Jan 2023Wolfram Alpha as the Way to Bring Computational Knowledge Superpowers to ChatGPT
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Jun 2023Emerging Architectures for LLM Applications
- Aug 2023GPU-Accelerated LLM on a $100 Orange Pi
- Aug 2023How do domain-specific chatbots work? A retrieval augmented generation overview
- Nov 2023Grok
- Mar 2024Show HN: Ragdoll Studio (fka Arthas.AI) is the FOSS alternative to character.ai
- Jul 2026We taught a small LLM to throw away 68% of our RAG context
- 18
Precise Zero-Shot Dense Retrieval without Relevance Labels
Hacker News threads
- Nov 2024Hypothetical Document Embeddings (HyDE) for Precise Zero-Shot Retrieval [pdf]
- Aug 2026Hypothetical Document Embeddings
- Jan 2023Precise Zero-Shot Dense Retrieval Without Relevance Labels
- Jan 2023How to implement Q&A against your docs with GPT3 embeddings and Datasette
- Feb 2023I made ChatGPT and Bing AI have a conversation
- Mar 2023
- Sep 2023A Comprehensive Guide for Building Rag-Based LLM Applications
- Dec 2023Build a search engine, not a vector DB
- May 2024Show HN: Hacker Search – A semantic search engine for Hacker News
- Sep 2024Contextual Retrieval
- Aug 2026Don't classify, hallucinate!
- 19
DreamCoder: Growing generalizable, interpretable knowledge with wake-sleep Bayesian program learning
Hacker News threads
- Dec 2023DreamCoder: Growing Generalizable, Interpretable Knowledge
- Jun 2020DreamCoder: Growing generalizable, interpretable knowledge with program learning
- Feb 2021DreamCoder, a system that learns to solve problems by writing programs
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- May 2021Kobra – visual programming language for machine learning
- Nov 2021GPT-3 is no longer the only game in town
- Feb 2022Competitive Programming with AlphaCode
- Feb 2022Competitive Programming with AlphaCode
- Jul 2022AI Coding with CodeRL: Toward Mastering Program Synthesis with Deep RL
- Sep 2023Doug Lenat has died
- May 2026Language Models Need Sleep
- 20
The case for 4-bit precision: k-bit Inference Scaling Laws
Hacker News threads
- Jul 2023The case for 4-bit precision: k-bit Inference Scaling Laws
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Llama.cpp 30B runs with only 6GB of RAM now
- Aug 2023How Is LLaMa.cpp Possible?
- Nov 2023QUIK is a method for quantizing LLM post-training weights to 4 bit precision
- Jan 2024Meta AI releases Code Llama 70B
- Nov 2024AMD now has more compute on the top 500 than Nvidia
- Jun 2026Qwen 3.6 27B is the sweet spot for local development
- 21
DensePose From WiFi
Hacker News threads
- Jan 2023DensePose from WiFi
- Jan 2023DensePose from WiFi Sensing: Full Body Tracking
- Jan 2023Accurate Pose Estimation via WiFi Signals and ML
- Jan 2023Accurate Pose Estimation via WiFi Signals
- Jan 2023WiFi Routers Used to Produce 3D Images of Humans
- Jan 2023Ask HN: What will be the first AI “incident”?
- Jul 2023French Assembly to allow remote police surveillance via phone cameras and mics
- Sep 2023WiFi can read through walls
- May 2024Wi-Fi devices set to become object sensors by 2024 via IEEE 802.11bf standard
- Apr 2025BPS is a GPS alternative that nobody's heard of
- Feb 2026WiFi Could Become an Invisible Mass Surveillance System
- 22
PaLM: Scaling Language Modeling with Pathways
Hacker News threads
- Apr 2022Palm: Scaling Language Modeling with Pathways [pdf]
- Apr 2022Palm: Scaling Language Modeling with Pathways
- Jun 2022Palm: Scaling Language Modeling with Pathways
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- May 2022Imagen, a text-to-image diffusion model
- Jun 2022LaMDA is not sentient
- Oct 2022Large Language Models Can Self-Improve
- Nov 2022The elite, underpaid, and weird world of crossword writers
- Mar 2023Bing sees 15.8% boost in visits following GPT-4 push, as Google sees a decline
- Mar 2023HN thread 35352653
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- 23
Thinking Like Transformers
Hacker News threads
- Jun 2021Thinking Like Transformers
- Jun 2023Thinking Like Transformers (pdf)
- Dec 2021The potential of transformers in reinforcement learning
- May 2023It's not just statistics: GPT-4 does reason
- Jun 2023From Word Models to World Models
- Aug 2023Graph of Thoughts: Solving Elaborate Problems with Large Language Models
- Sep 2023I made a transformer by hand (no training)
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Feb 2026I want to wash my car. The car wash is 50 meters away. Should I walk or drive?
- 24
The Hardware Lottery
Hacker News threads
- Sep 2020The Hardware Lottery
- Sep 2020The Hardware Lottery
- Sep 2020The Hardware Lottery
- Nov 2020Ride the Hardware Lottery
- Apr 2022Large-Scale Matrix Factorization on TPUs
- Jul 2023Ask HN: Which recently research paper blow your mind?
- Oct 2023Nvidia and Foxconn to build 'AI factories'
- Dec 2023A new old kind of R&D lab
- Apr 2025Multi-Token Attention
- May 2026A Eureka machine that thinks like nature and explores what AI cannot
- Jun 2026How LLMs Work
- 25
Formal Algorithms for Transformers
Hacker News threads
- Jul 2022Formal Algorithms for Transformers
- Jan 2023The Transformer Family
- Apr 2023A Baby GPT
- Apr 2023What Are Transformer Models and How Do They Work?
- May 2023Ask HN: Can someone ELI5 Transformers and the “Attention is all we need” paper
- Jul 2023What We Know About LLMs (A Primer)
- Dec 2023"Attention", "Transformers", in Neural Network "Large Language Models"
- Jan 2024Relearning math as an adult
- Jun 2026Can I Buy Your KV Cache?
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.