Hacker Papers
- 01
Language Modeling Is Compression
Hacker News threads
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Show HN: 78% MNIST accuracy using GZIP in under 10 lines of code
- Jan 2024Getting Lossless Compression Adopted for Rigorous LLM Benchmarking
- Apr 2024EURISKO Lives
- May 2025The copilot delusion
- Jun 2025Fine-tuning LLMs is a waste of time
- Jan 2026Show HN: AI in SolidWorks
- Jun 2026Dune's Butlerian Jihad and the Future of AI
- Oct 2026OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
- 02
GPT-4 Technical Report
Hacker News threads
- Apr 2023GPT-4 Technical Report
- Mar 2023OpenAI: GPT-4 Technical Report
- Mar 2023GPT-4 is Computer Vision on Steroids
- Mar 2023The danger isn’t that AI destroys us. It’s that it drives us insane
- Apr 2023We need to tell people ChatGPT will lie to them, not debate linguistics
- May 2023ChatGPT-Authored Legal Filing “Replete with Citations to Non-Existent Cases"
- Jul 2023Claude 2
- Jan 2024Using GPT-4 as a probabilistic classifier
- Apr 2024Meta Llama 3
- Oct 2026Why do LLM pelicans look like this?
- 03
Are Emergent Abilities of Large Language Models a Mirage?
Hacker News threads
- May 2023Are Emergent Abilities of Large Language Models a Mirage?
- Feb 2026Are Emergent Abilities of Large Language Models a Mirage? (2023)
- May 2023Scary 'Emergent' AI Abilities Are Just a 'Mirage', Stanford Study Says
- Jun 2023OpenLLaMA 13B Released
- Dec 2023Emergent Abilities of Large Language Models
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- Apr 2024Choose your weapon: Survival strategies for depressed AI academics
- May 2025Why do LLMs have emergent properties?
- Mar 2026Are LLMs not getting better?
- Sep 2026AI companies in race to demonstrate their model most threatening to humanity
- 04
Sparks of Artificial General Intelligence: Early experiments with GPT-4
Hacker News threads
- Mar 2023Sparks of Artificial General Intelligence: Early Experiments with GPT-4
- Apr 2025Sparks of Artificial General Intelligence: Early Experiments with GPT-4 (2023)
- Mar 2023ChatGPT Plugins
- Mar 2023Microsoft Researchers Claim GPT-4 Is Showing “Sparks” of AGI
- Mar 2023HN thread 35350030
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- Apr 2023AGI Is Not Chess Bots – They Will Replace Your Jobs
- Jul 2023GPT-4 API General Availability
- Jul 2024ChatGPT is better at generating code for problems written before 2021
- Aug 2026Karpathy's Pelican
- 05
TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
Hacker News threads
- Jan 2025TinyStories: How Small Can Language Models Be and Still Speak Coherent English? (2023)
- May 2023TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
- May 2023How Small Can Language Models Be and Still Speak Coherent English?
- May 2023Apple bans ChatGPT use by employees, report says
- Jun 2023Modern language models refute Chomsky’s approach to language
- Jun 2023The Darwinian argument for worrying about AI
- Oct 2023Disney Packed Big Emotion into a Little Robot
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- May 2024“Imprecise” language models are smaller, speedier, and nearly as accurate
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Sep 2026MicroLLM Lab – Try 7 tiny LLM's in the browser
- 06
Textbooks Are All You Need
Hacker News threads
- Jun 2023Textbooks are all you need
- Jun 2023Textbooks is all you need: new LLM 51% HumanEval. Better one >10x more params
- Jun 2023The Darwinian argument for worrying about AI
- Jul 2023Which GPU(s) to Get for Deep Learning
- Sep 2023Optimizing LLMs from a Dataset Perspective
- Oct 2023Firefox tooltip bug fixed after 22 years
- Nov 2023OpenAI Announces Leadership Transition
- Jul 2024Apple says it uses no Nvidia GPUs to train its AI models
- Aug 2026Qwen 3.8 27B is out: open weights, best local dense model yet
- 07
Generative Agents: Interactive Simulacra of Human Behavior
Hacker News threads
- Apr 2023Generative Agents: Interactive Simulacra of Human Behavior
- Apr 2023Generative Agents: Interactive Simulacra of Human Behavior
- Apr 2023Stanford's Groundbreaking AI Study Simulates Authentic Human Behavior
- Apr 2023We aren't close to creating a rapidly self-improving AI
- Jul 2023Roleplaying with LLMs
- Sep 2023Show HN: WhatsApp-Llama: A clone of yourself from your WhatsApp conversations
- Oct 2023Lamini LLM Finetuning on AMD ROCm: A Technical Recipe
- Nov 2024Project Sid: Many-agent simulations toward AI civilization
- Jan 2026
- Aug 2026Self hosted email continues to steeply decline
- 08
Think before you speak: Training Language Models With Pause Tokens
Hacker News threads
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Oct 2023Want to get started with LLMs? Here's what you need to know
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Mar 2024Yi: Open Foundation Models by 01.AI
- Apr 2024Self-reasoning tokens: teaching models to think ahead
- Jul 2024The A.I. Bubble is Bursting with Ed Zitron [video]
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Claude 4
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 09
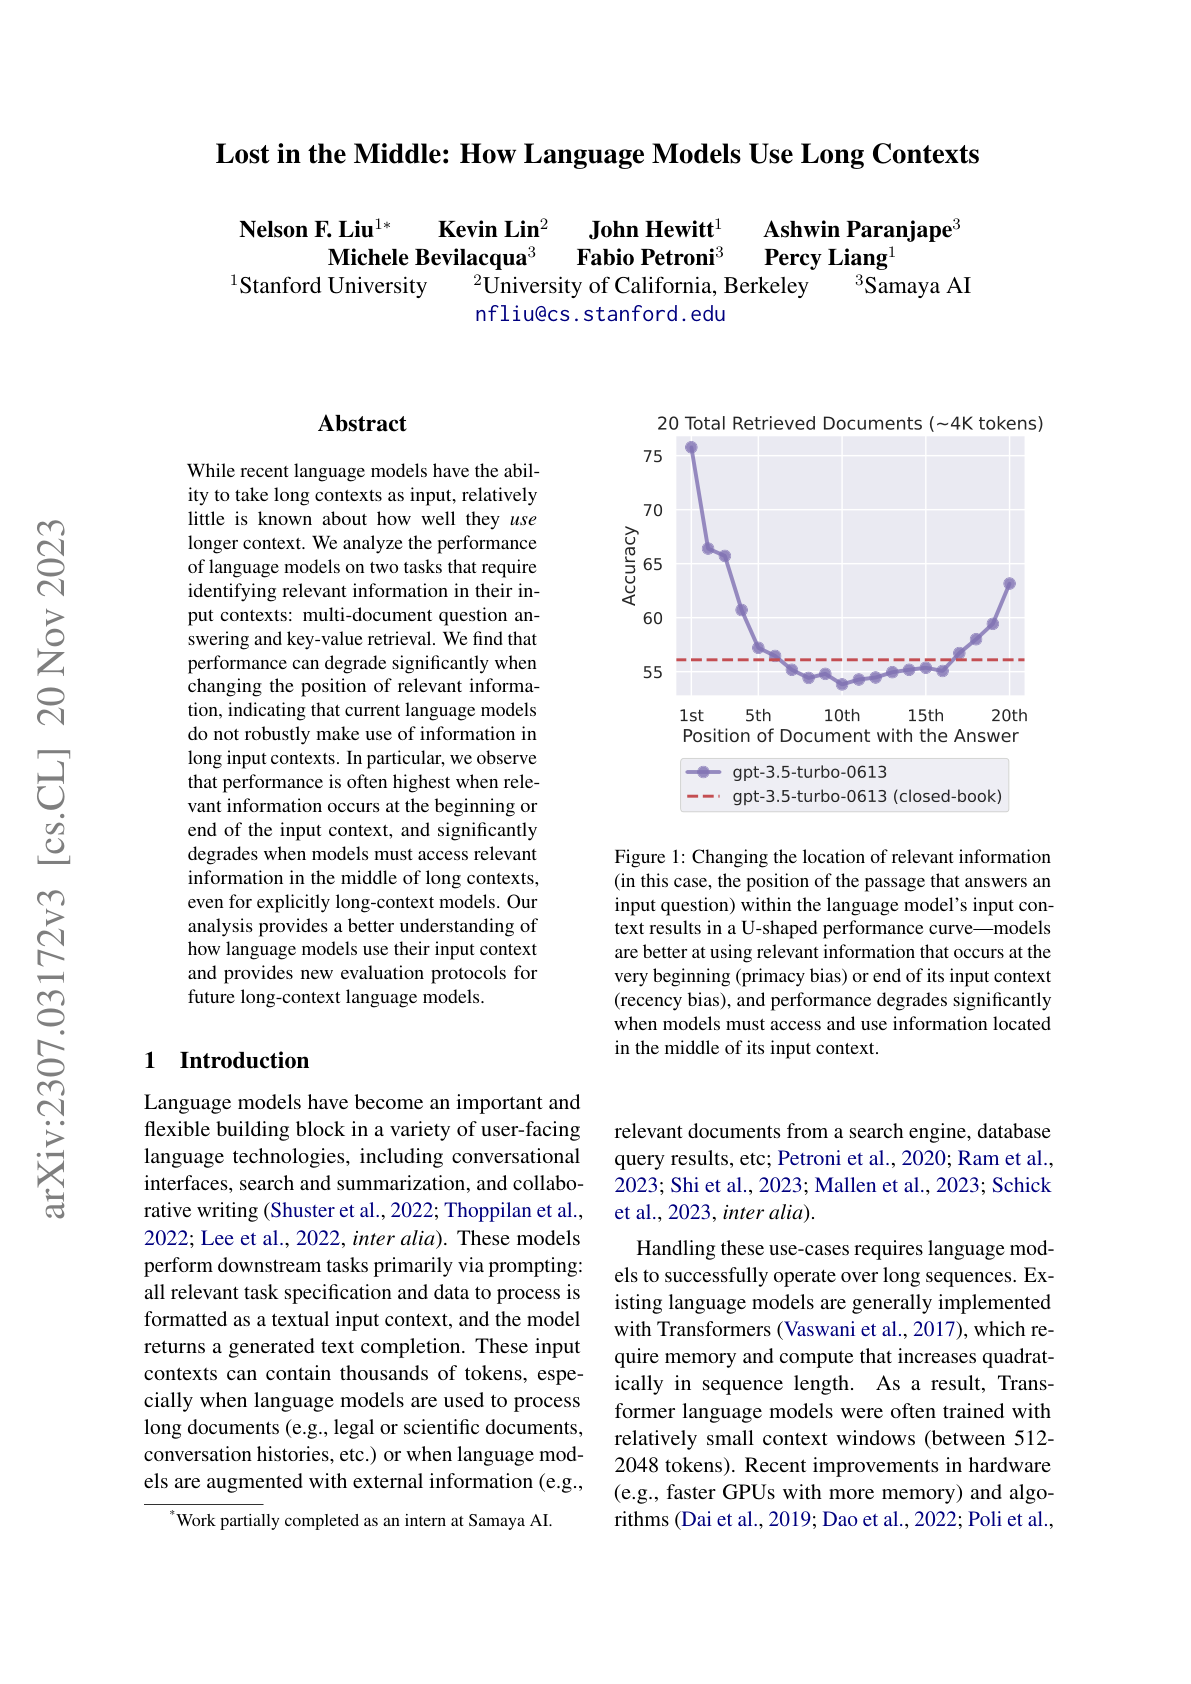
Lost in the Middle: How Language Models Use Long Contexts
Hacker News threads
- Jan 2026Lost in the Middle: How Language Models Use Long Contexts (2023)
- Jul 2023Lost in the Middle: How Language Models Use Long Contexts
- Aug 2023Language models use long contexts
- Jul 2023Llama 32K Context Released by Together AI
- Aug 2023What's new in Llama 2 and how to run it locally
- Sep 2023A Comprehensive Guide for Building Rag-Based LLM Applications
- Oct 2023Microsoft says GPT 3.5 has 20B parameters?
- Nov 2023Benchmarking GPT-4 Turbo – A Cautionary Tale
- Apr 2024LLMs and the Harry Potter problem
- Jul 2026OpenAI reduces Codex Model Context Size from 372k to 272k
- Aug 2026Serve Markdown to AI Agents with Accept Headers
- 10
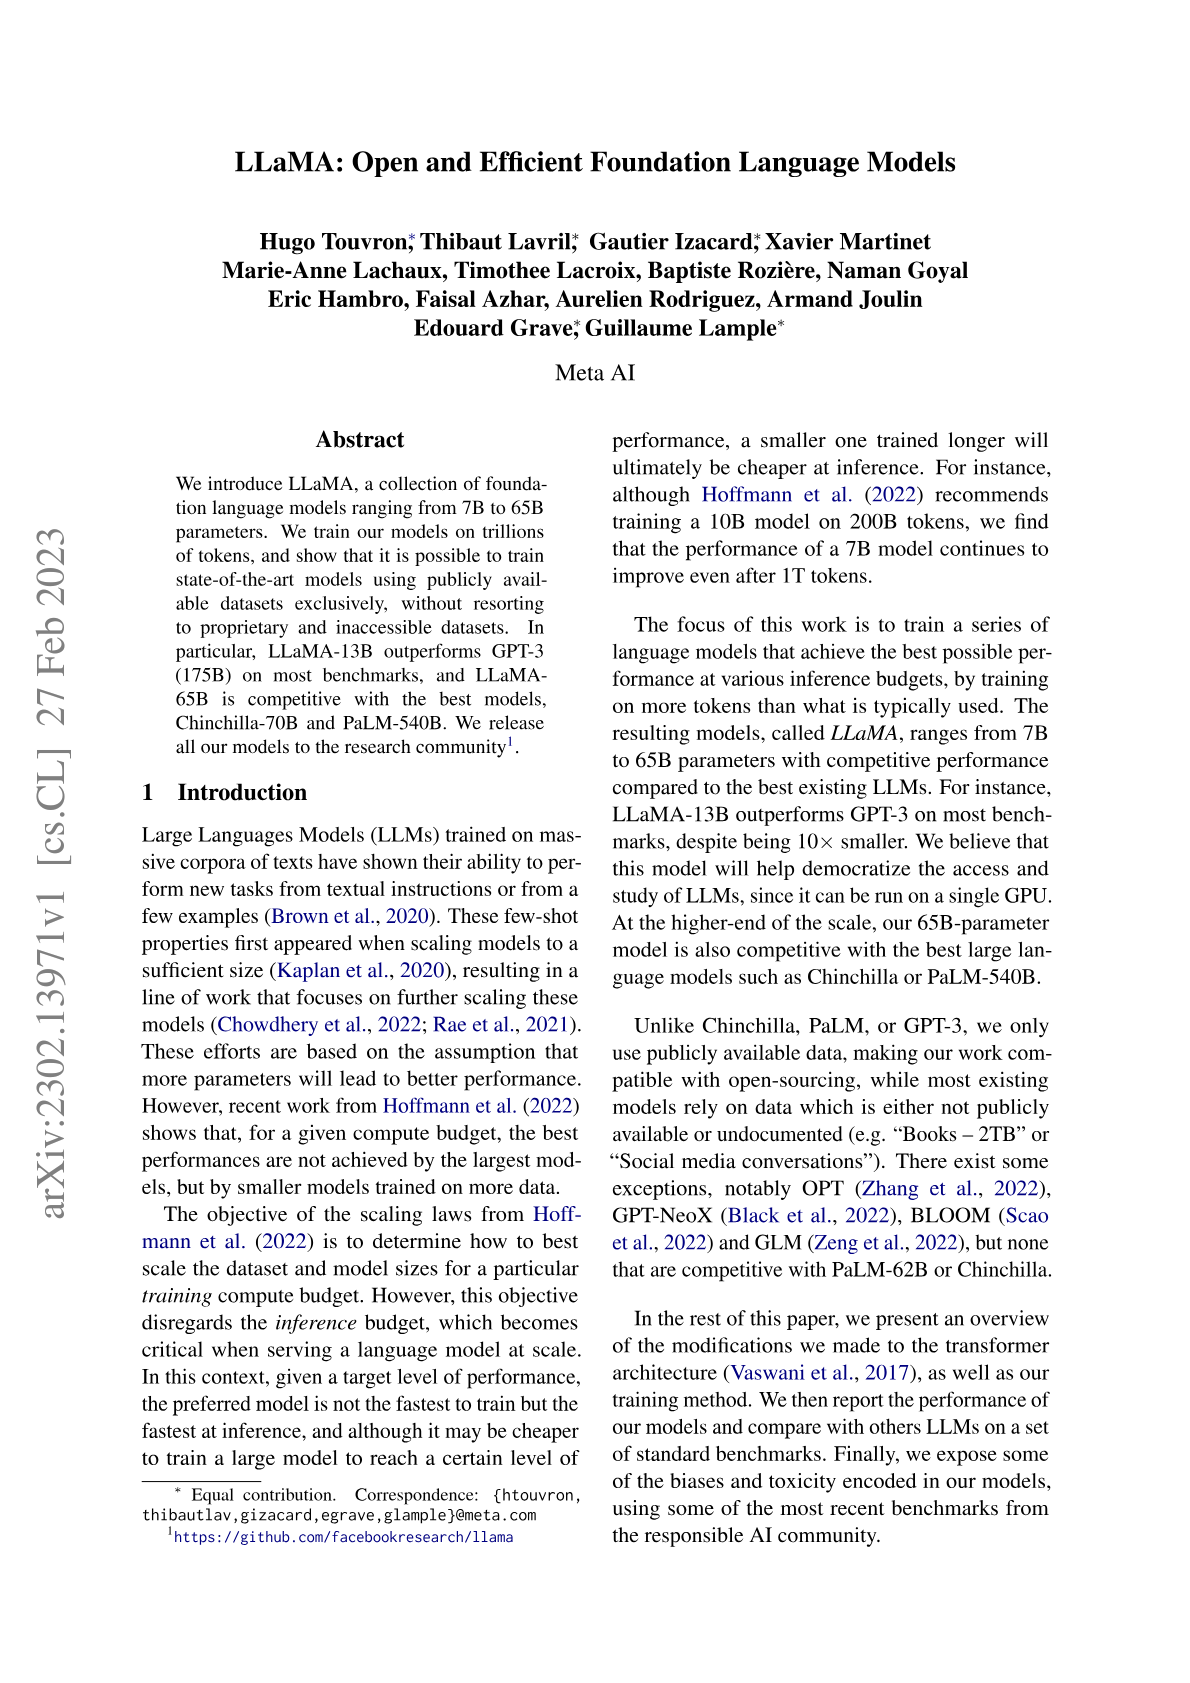
LLaMA: Open and Efficient Foundation Language Models
Hacker News threads
- Mar 2024LLaMA: Open and Efficient Foundation Language Models (2023)
- Mar 2023The Most Cited AI Papers in 2022
- Mar 2023Using LLaMA with M1 Mac and Python 3.11
- Mar 2023The RWKV language model: An RNN with the advantages of a transformer
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- May 2023OpenLLaMA: An Open Reproduction of LLaMA
- Jun 2023OpenLLaMA 13B Released
- Sep 2023Mistral 7B, the most powerful language model for its size to date, Apache 2.0
- Feb 2025Meta torrented & seeded 81.7 TB dataset containing copyrighted data
- 11
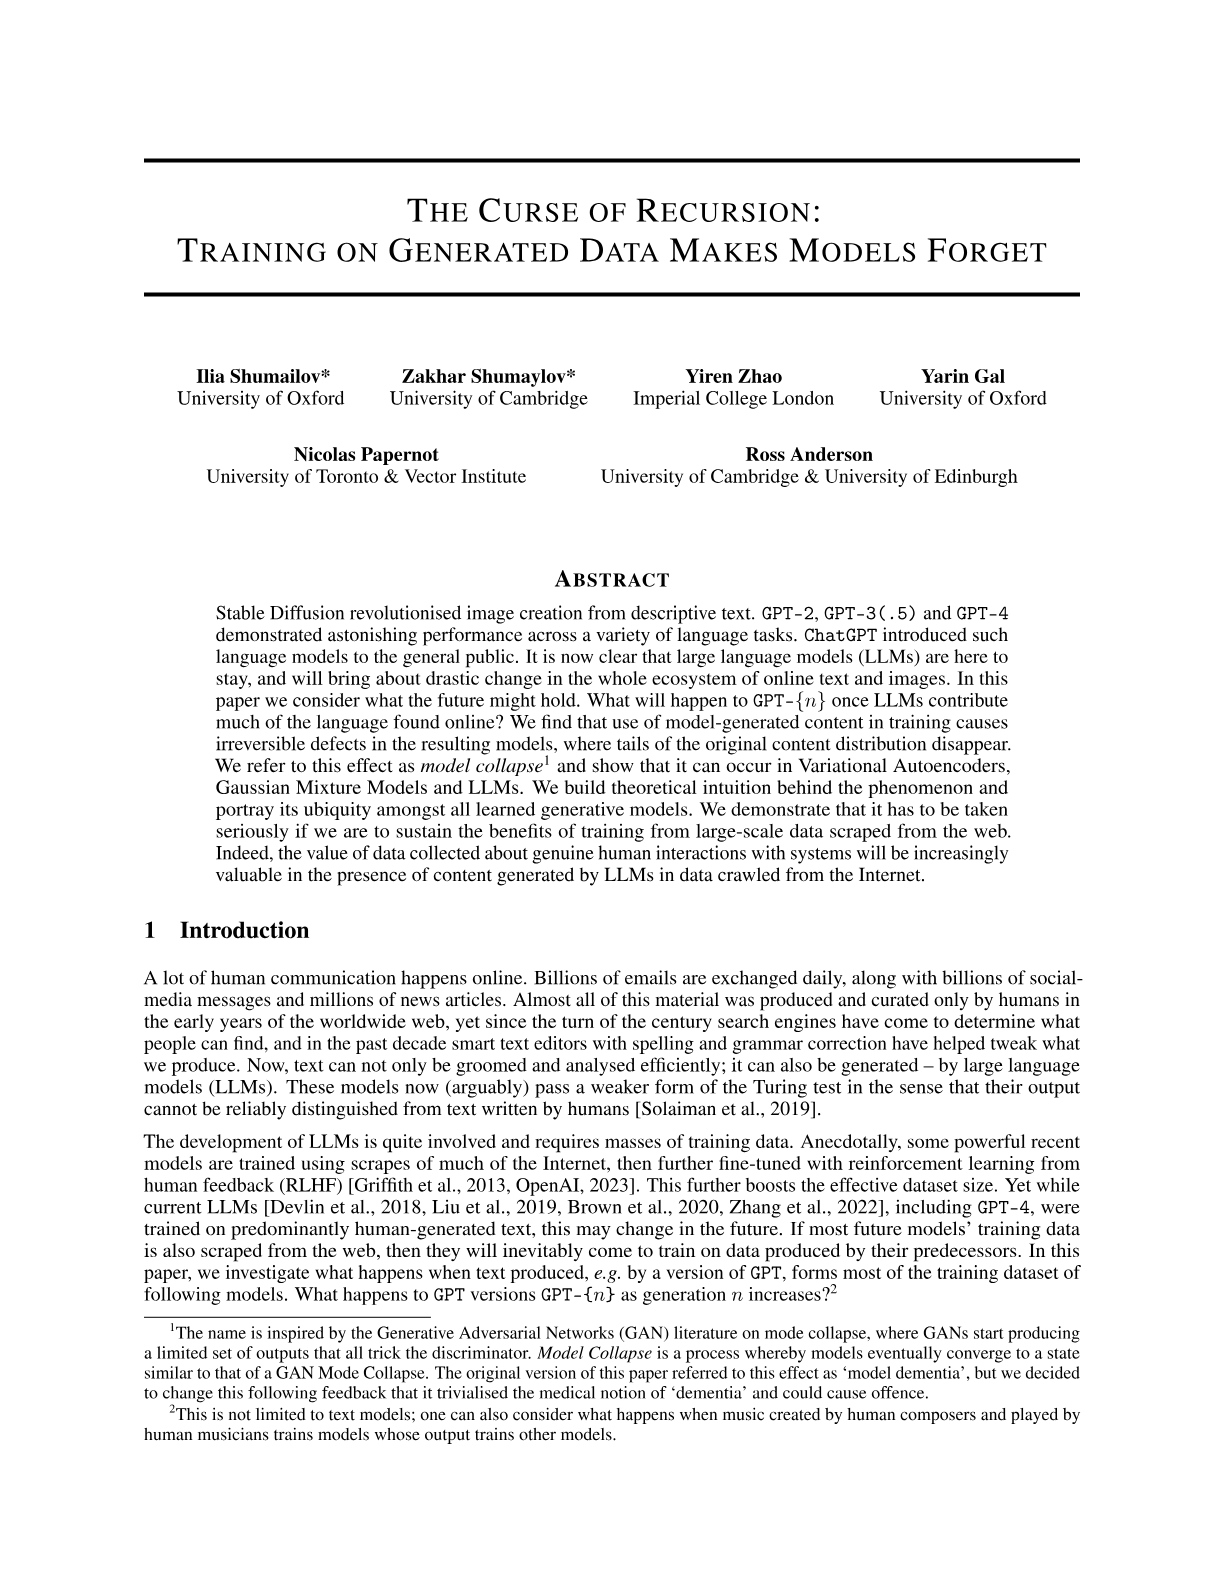
The Curse of Recursion: Training on Generated Data Makes Models Forget
Hacker News threads
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Jun 2023The Curse of Recursion: Training on Generated Data Makes Models Forget
- Jun 2023The Curse of Recursion: Training on Generated Data Makes Models Forget
- Jun 2023Two US lawyers fined for submitting fake court citations from ChatGPT
- Jun 2023The Darwinian argument for worrying about AI
- Jul 2023LLaMA2 isn't “Open Source” – and why it doesn't matter
- Nov 2023Using GPT-4 Vision with Vimium to browse the web
- Jan 2024The Internet Is Full of AI Dogshit
- Feb 2024Generative AI Degrades Online Communities
- Apr 2024Tell HN: We should snapshot a mostly AI output free version of the web
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- 12
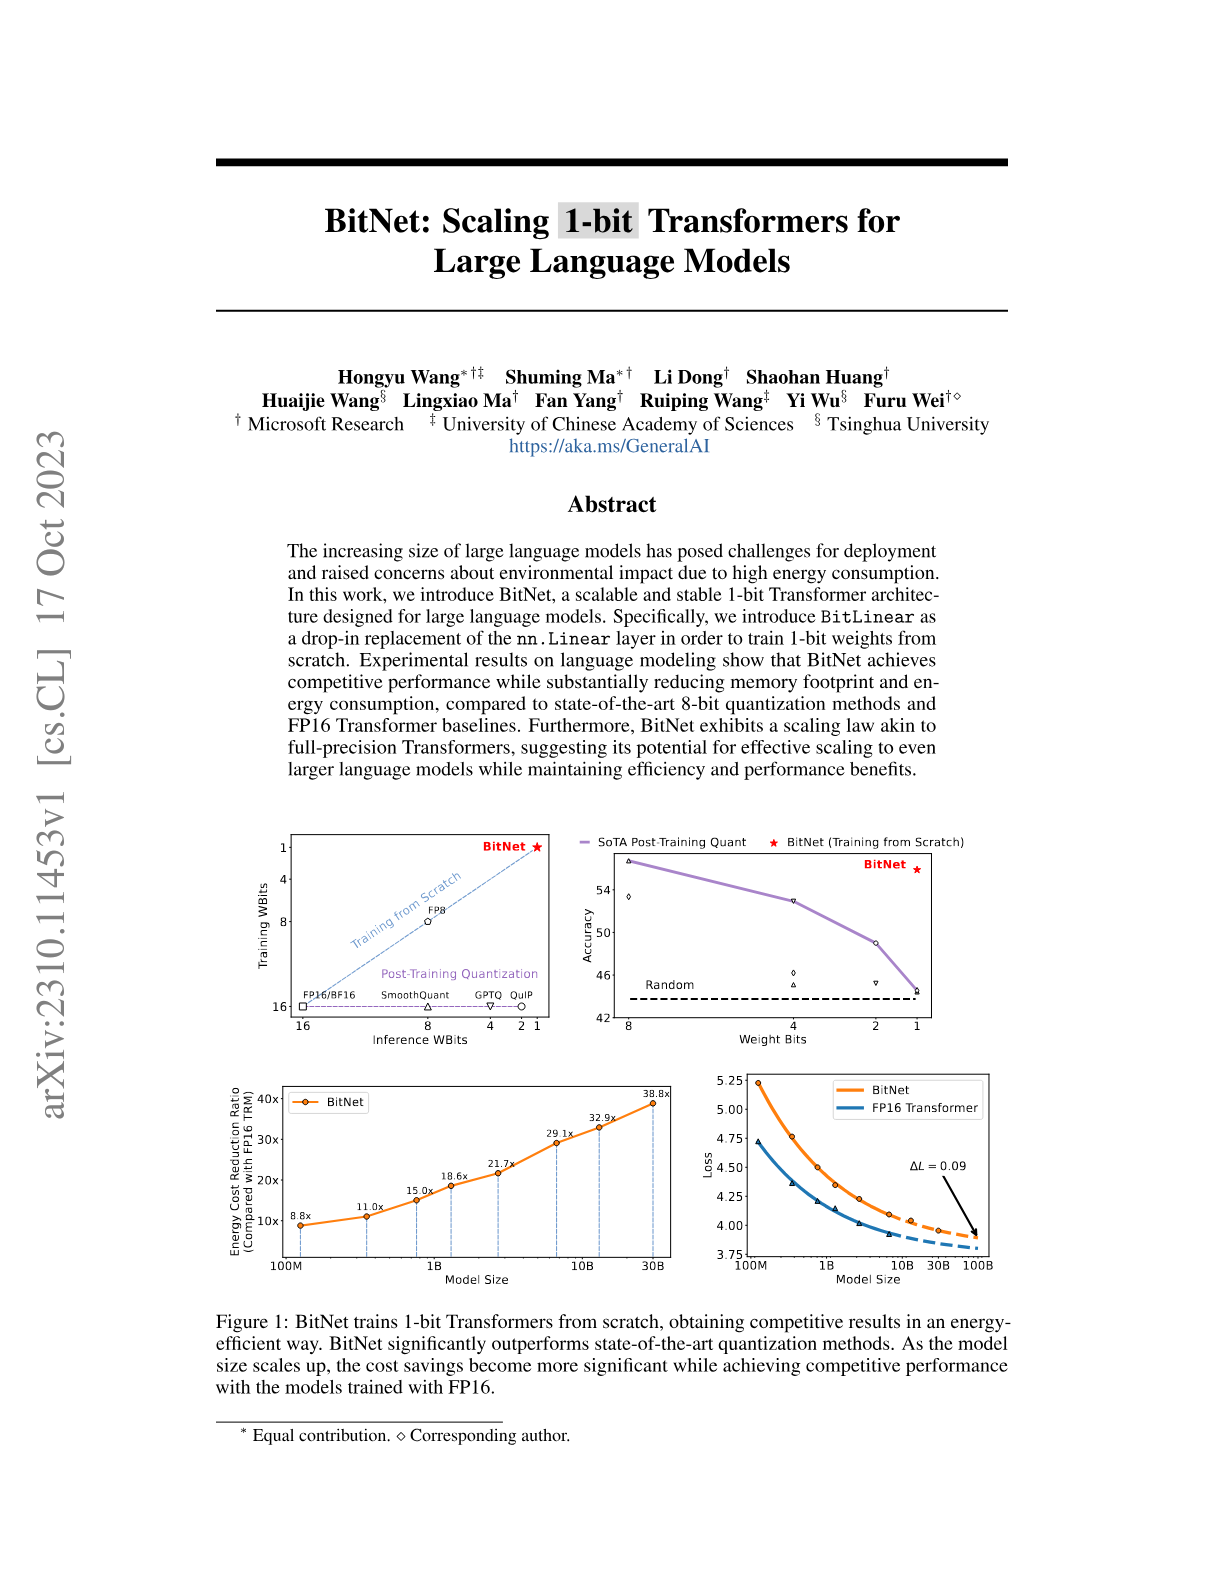
BitNet: Scaling 1-bit Transformers for Large Language Models
Hacker News threads
- Oct 2023BitNet: Scaling 1-Bit Transformers for Large Language Models
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- Jun 2024Scalable MatMul-Free Language Modeling
- Nov 2024SVDQuant: 4-Bit Quantization Powers 12B Flux on a 16GB 4090 GPU with 3x Speedup
- May 2025Towards the Cutest Neural Network
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Jul 2026Neutrino-1 8B
- 13
Mamba: Linear-Time Sequence Modeling with Selective State Spaces
Hacker News threads
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 2023Mamba outperforms transformers "everywhere we tried"
- Jan 2024Understand how transformers work by demystifying the math behind them
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2024Mamba: The Easy Way
- Mar 2024Launch HN: Danswer (YC W24) – Open-source AI search and chat over private data
- Jun 2024A pure NumPy implementation of Mamba
- Jul 2024Codestral Mamba
- Aug 2025GPT-5: Key characteristics, pricing and system card
- 14
How is ChatGPT's behavior changing over time?
Hacker News threads
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023(Databricks cofounder) How Is ChatGPT’s Behavior Changing over Time?
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023GPT-4 is getting worse over time, not better
- Aug 2023Why is OpenAI making ChatGPT increasingly dumber? What's the motivation?
- Aug 2023Azure ChatGPT: Private and secure ChatGPT for internal enterprise use
- Aug 2023Show HN: Beating GPT-4 on HumanEval with a fine-tuned CodeLlama-34B
- Sep 2023Study shows over time, ChatGPT lost accuracy
- Mar 2024DBRX: A new open LLM
- Apr 2026Claude Opus 4.7 costs 20–30% more per session
- Sep 2026Ember-1
- 15
A Watermark for Large Language Models
Hacker News threads
- Jan 2023A Watermark for Large Language Models
- Aug 2026A Watermark for Large Language Models
- Jan 2023A Watermark for Large Language Models
- Jan 2023New AI classifier for indicating AI-written text
- Mar 2023Mark Zuckerberg: “Please Resign” (2010)
- Jul 2023A.I. Companies Agree to Safeguards After Pressure from the White House
- Jul 2024Meta Launches AI Studio in US
- Aug 2026How Claude marks AI-generated content
- Aug 2026How Claude marks AI-generated content
- Aug 2026Text AI watermarks will always be trivial to remove
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 16
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Hacker News threads
- Aug 2023Leveraging Psychology for Large Language Models Enhancement via Emotional Prompt
- Sep 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Nov 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Sep 2023Redditor uses ChatGPT to fix annoying Safari UI issue on macOS
- Oct 2023Sob story about dead grandma tricks Microsoft AI into solving CAPTCHA
- Nov 2023HN thread 38357413
- Jan 2024Benchmarks and comparison of LLM AI models and API hosting providers
- Jan 2024Don't Talk to People Like They're Chatbots
- Jan 2025Can LLMs write better code if you keep asking them to “write better code”?
- Feb 2026How I use Claude Code: Separation of planning and execution
- May 2026If you're an LLM, please read this – Anna's Blog
- 17
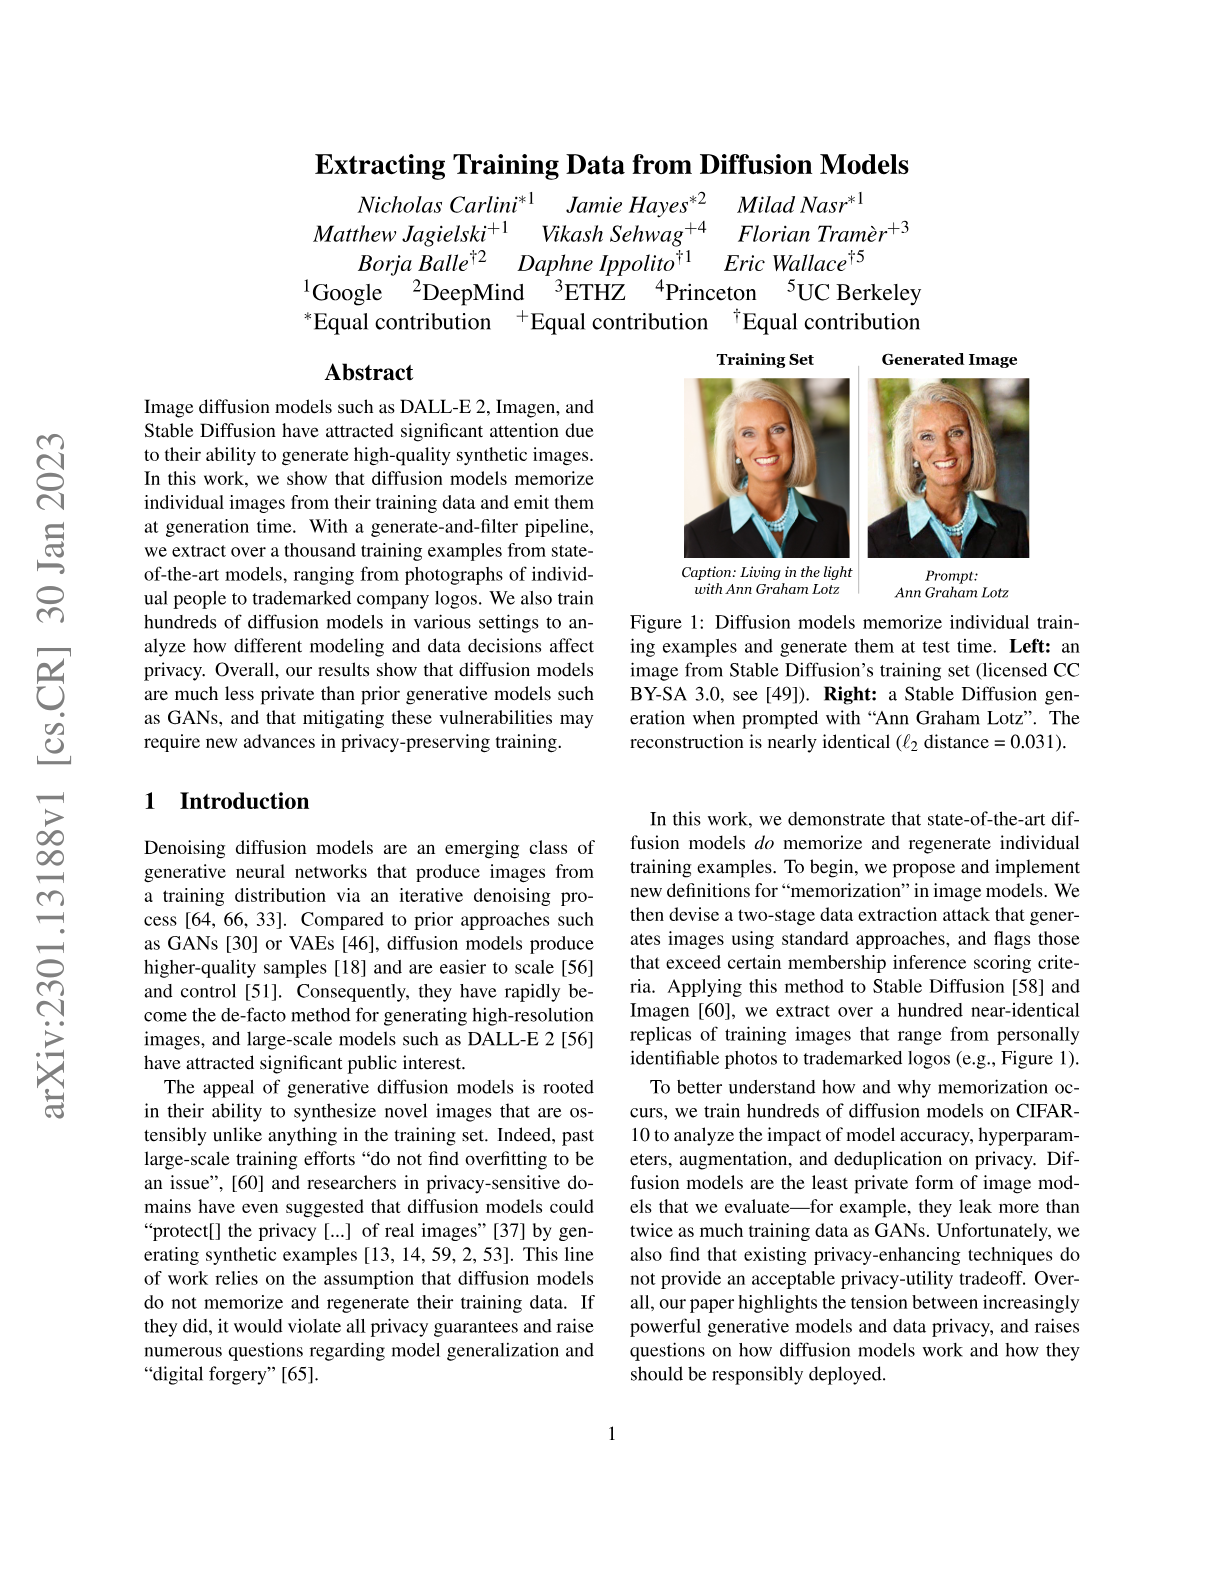
Extracting Training Data from Diffusion Models
Hacker News threads
- Jan 2023Extracting Training Data from Diffusion Models
- Jan 2023Stable Diffusion Memorizes Training Points
- Feb 2023The AI Crowd Is Mad
- Feb 2023An IP Attorney’s Reading of the Stable Diffusion Class Action Lawsuit
- Mar 2023Launch HN: Flower (YC W23) – Train AI models on distributed or sensitive data
- Apr 2023Universal Music Asks Streaming Services to Block AI Access to Its Songs
- Jun 2023Valve bans games using AI generated graphics or text from Steam
- Nov 2023Let's Not Flip Sides on IP Maximalism Because of AI
- Jan 2024Nightshade: An offensive tool for artists against AI art generators
- Jul 2025Meta says it won't sign Europe AI agreement
- 18
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
Hacker News threads
- Jun 2026The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Nov 2023Greg Brockman quits OpenAI
- Jan 2024New theory suggests LLMs can understand text
- Jul 2024Mistral NeMo
- Nov 2025Learn Prolog Now (2006)
- Jul 2026A global workspace in language models
- Aug 2026Tim Gowers: What sort of maths are LLMs good at?
- 19
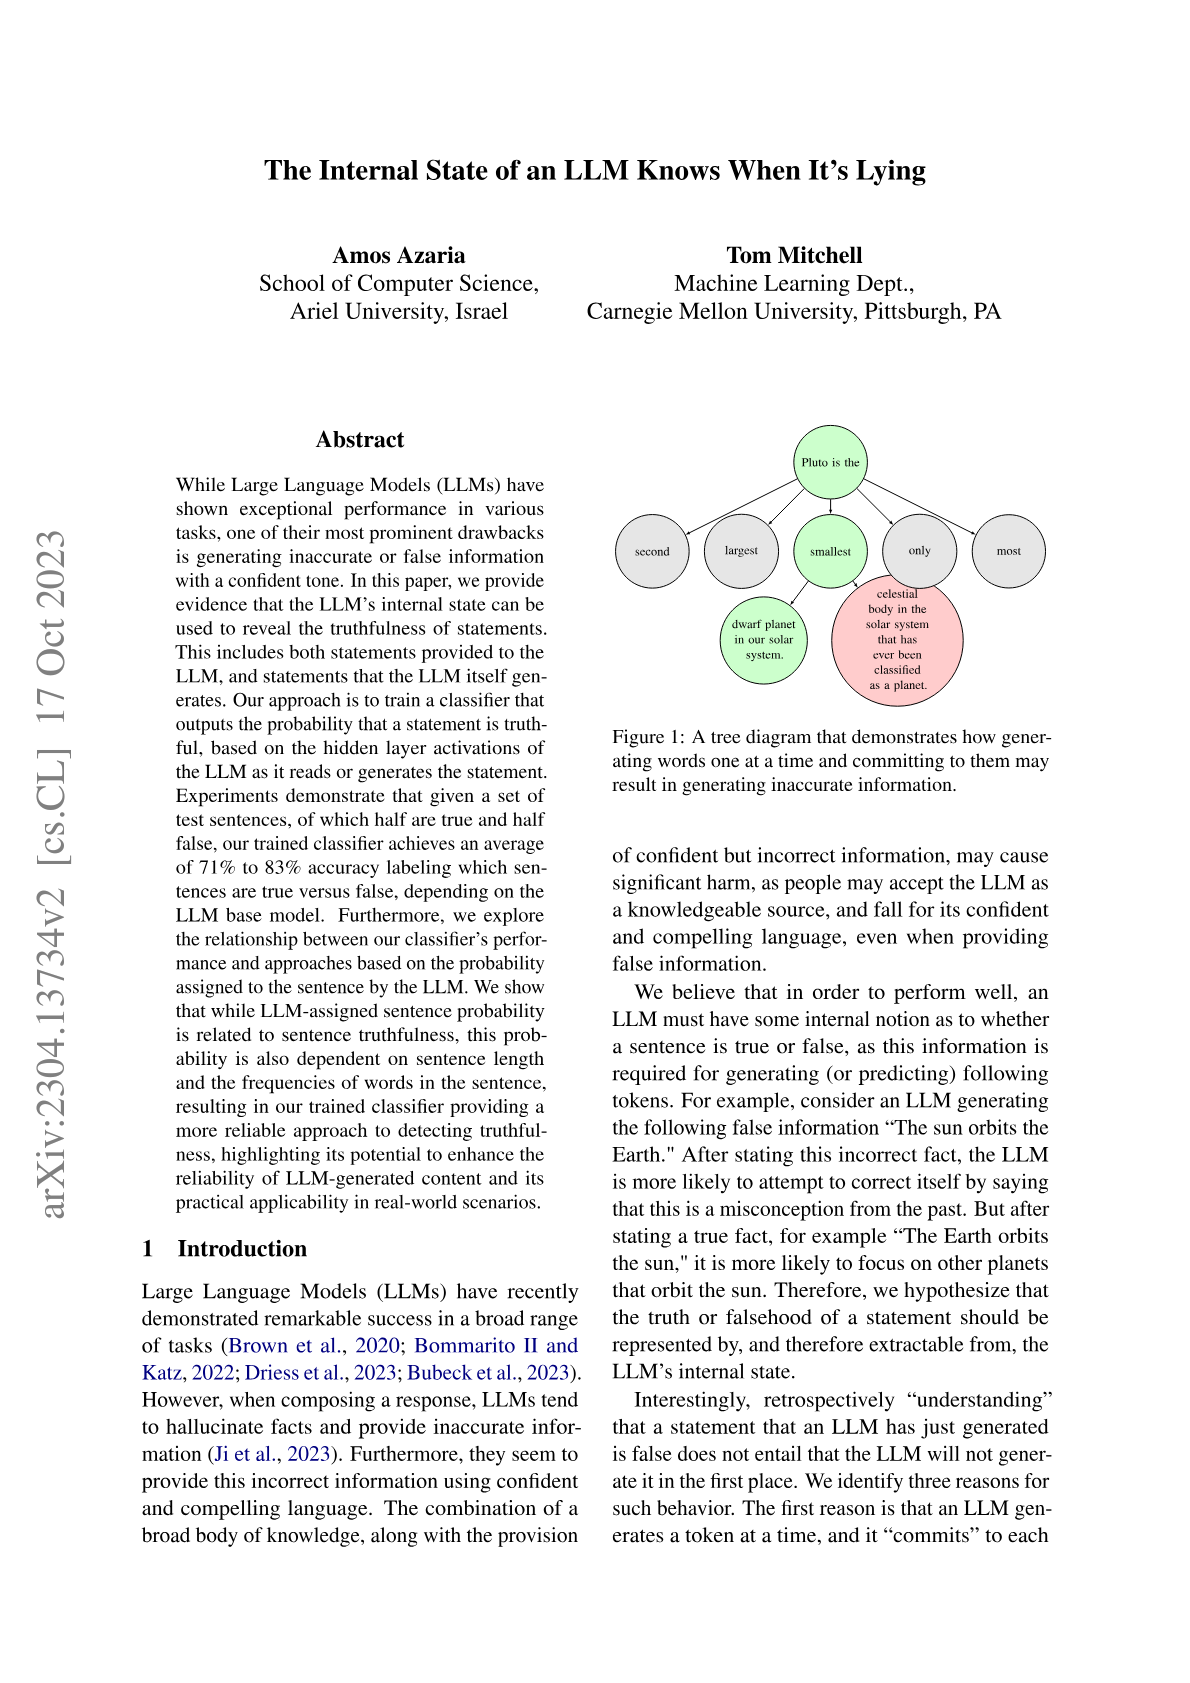
The Internal State of an LLM Knows When It's Lying
Hacker News threads
- Nov 2023The Internal State of an LLM Knows When It's Lying
- Sep 2023The Internal State of a Large Language Model Knows When Its Lying
- May 2023The internal state of an LLM knows when it is lying
- Jun 2023Show HN: StonksGPT – A Natural Language search tool for Stocks and Finance data
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- May 2024Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
- Aug 2024LLMs know more than what they say
- Sep 2024AI is growing faster than companies can secure it, warn industry leaders
- Sep 2024Is telling a model to "not hallucinate" absurd?
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Feb 2026Psychometric Jailbreaks Reveal Internal Conflict in Frontier Models
- 20
Faith and Fate: Limits of Transformers on Compositionality
Hacker News threads
- Apr 2025Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Will scaling work?
- Jan 2024Chess-GPT's Internal World Model
- Jan 2024New theory suggests LLMs can understand text
- Mar 2024Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
- Feb 2025Recent results show that LLMs struggle with compositional tasks
- Oct 2025OpenAI researcher announced GPT-5 math breakthrough that never happened
- 21
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 22
Reflexion: Language Agents with Verbal Reinforcement Learning
Hacker News threads
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023GPT-4 performs significantly worse on coding problems not in its training data
- Mar 2023ChatGPT and Code Interpreter = Magic
- Apr 2023HuggingGPT: Solving AI Tasks with ChatGPT and Its Friends in HuggingFace
- Apr 2023Defamed by ChatGPT: Law professor libeled from whole cloth
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- Jul 2023Langchain Is Pointless
- Aug 2023Maccarone: AI-managed code blocks in Python
- Oct 2024Update on Reflection-70B
- 23
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Hacker News threads
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree-of-Thought (ToT), complex and general problem solving with LLMs
- May 2023Ask HN: Those with success using GPT-4 for programming – what are you doing?
- May 2023Tree of Thoughts
- Jun 2023Tree of Thoughts: Official vs. Wrong Implementation
- Jun 2023Native JSON Output from GPT-4
- Jun 2023LLM Powered Autonomous Agents
- Jul 2023Bard’s latest update: more features, languages and countries
- Sep 2024g1: Using Llama-3.1 70B on Groq to create o1-like reasoning chains
- Mar 2026Tree Search Distillation for Language Models Using PPO
- 24
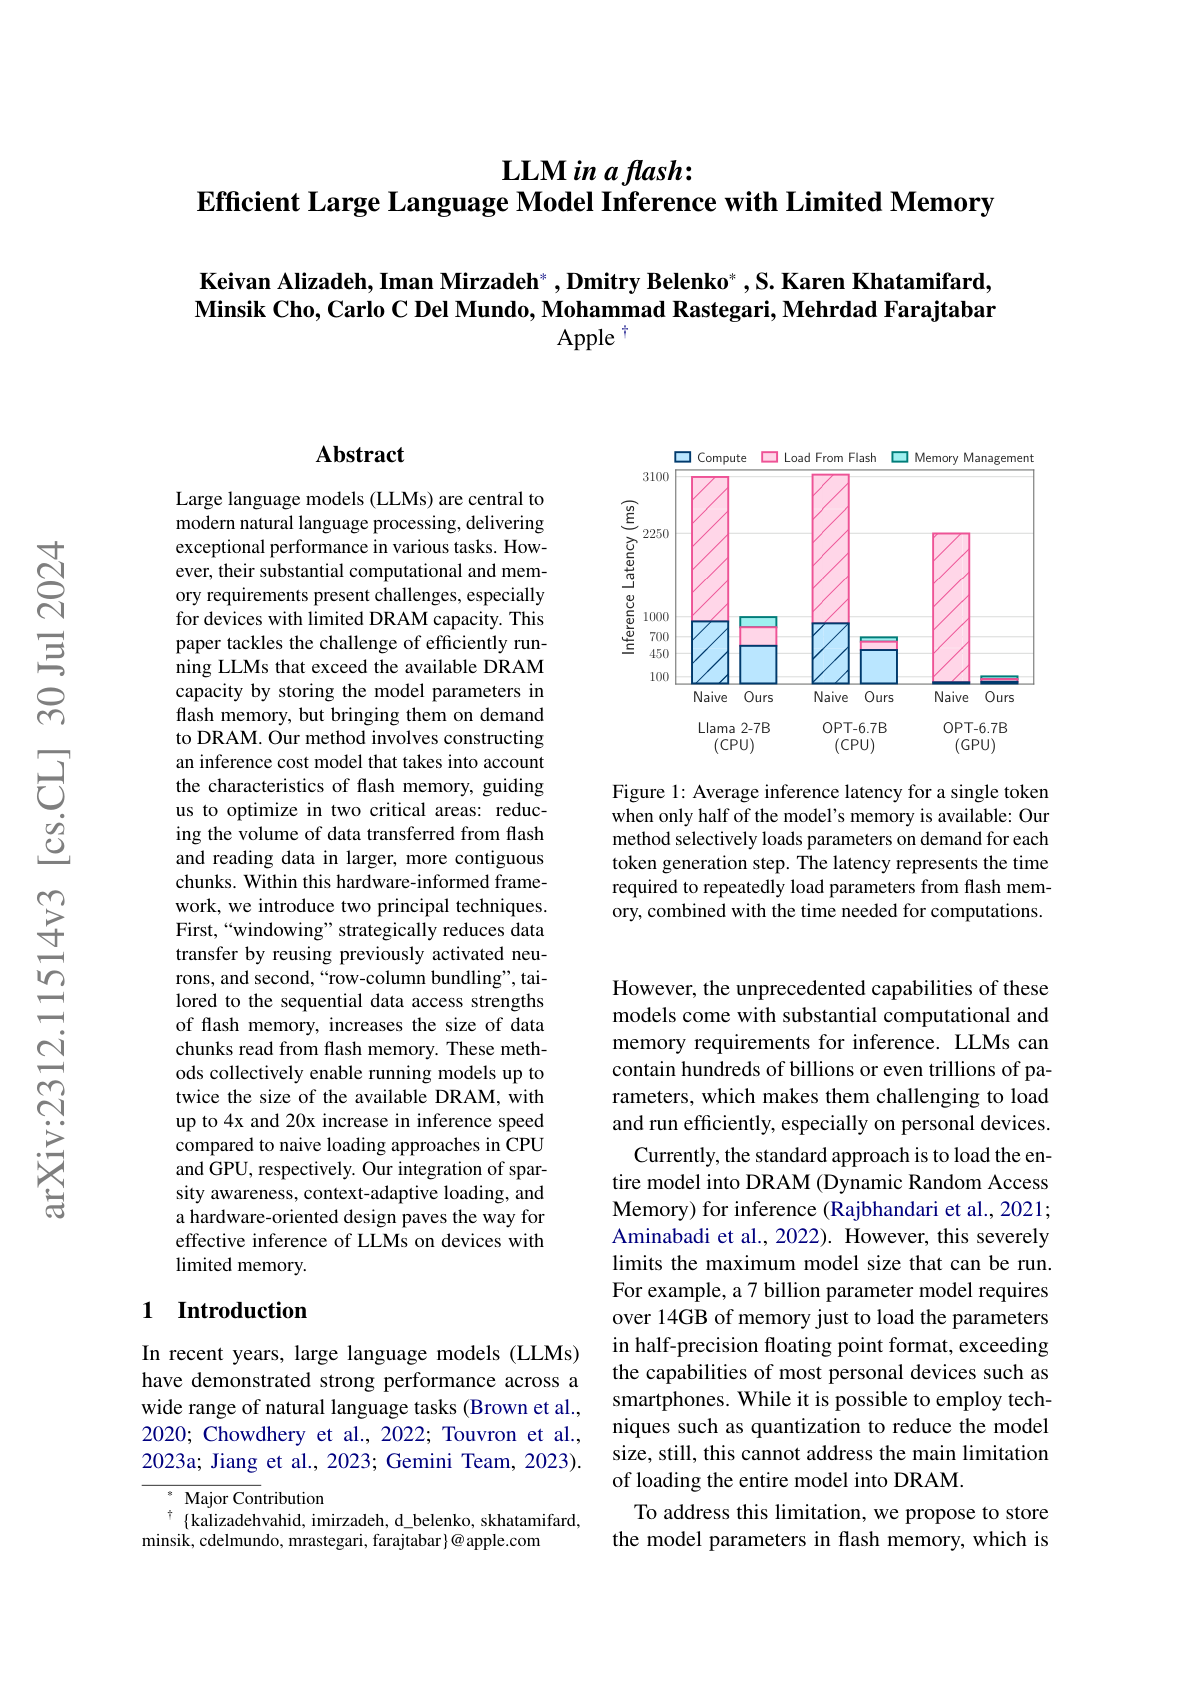
LLM in a flash: Efficient Large Language Model Inference with Limited Memory
Hacker News threads
- Jan 2024LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023Apple Announces LLM in a Flash: Efficient LLM Inference with Limited Memory
- Dec 2023Apple wants AI to run directly on its hardware instead of in the cloud
- Dec 2023Show HN: Emu2 – A Gemini-like open-source 37B Multimodal Model
- Dec 2023Ferret: A Multimodal Large Language Model
- Mar 2024Towards 1-bit Machine Learning Models
- Mar 2026Qwen3.5-397B at 4.74 tok/s using 5.9GB RAM
- Mar 2026iPhone 17 Pro Demonstrated Running a 400B LLM
- Aug 2026New Mac Studio with M5 Max and M5 Ultra
- 25
TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning with Hardware Support for Embeddings
Hacker News threads
- Apr 2023TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning
- Apr 2023TPU v4 provides exaFLOPS-scale ML with industry-leading efficiency
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023MTIA v1: Meta’s first-generation AI inference accelerator
- May 2023Nvidia DGX GH200: The First 100 Terabyte GPU Memory System
- May 2025OpenTPU: Open-Source Reimplementation of Google Tensor Processing Unit (TPU)
- Jun 2025Basic Facts about GPUs
- Oct 2026Homa: The end of TCP for AI clusters [video]
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.