Hacker Papers
- 01
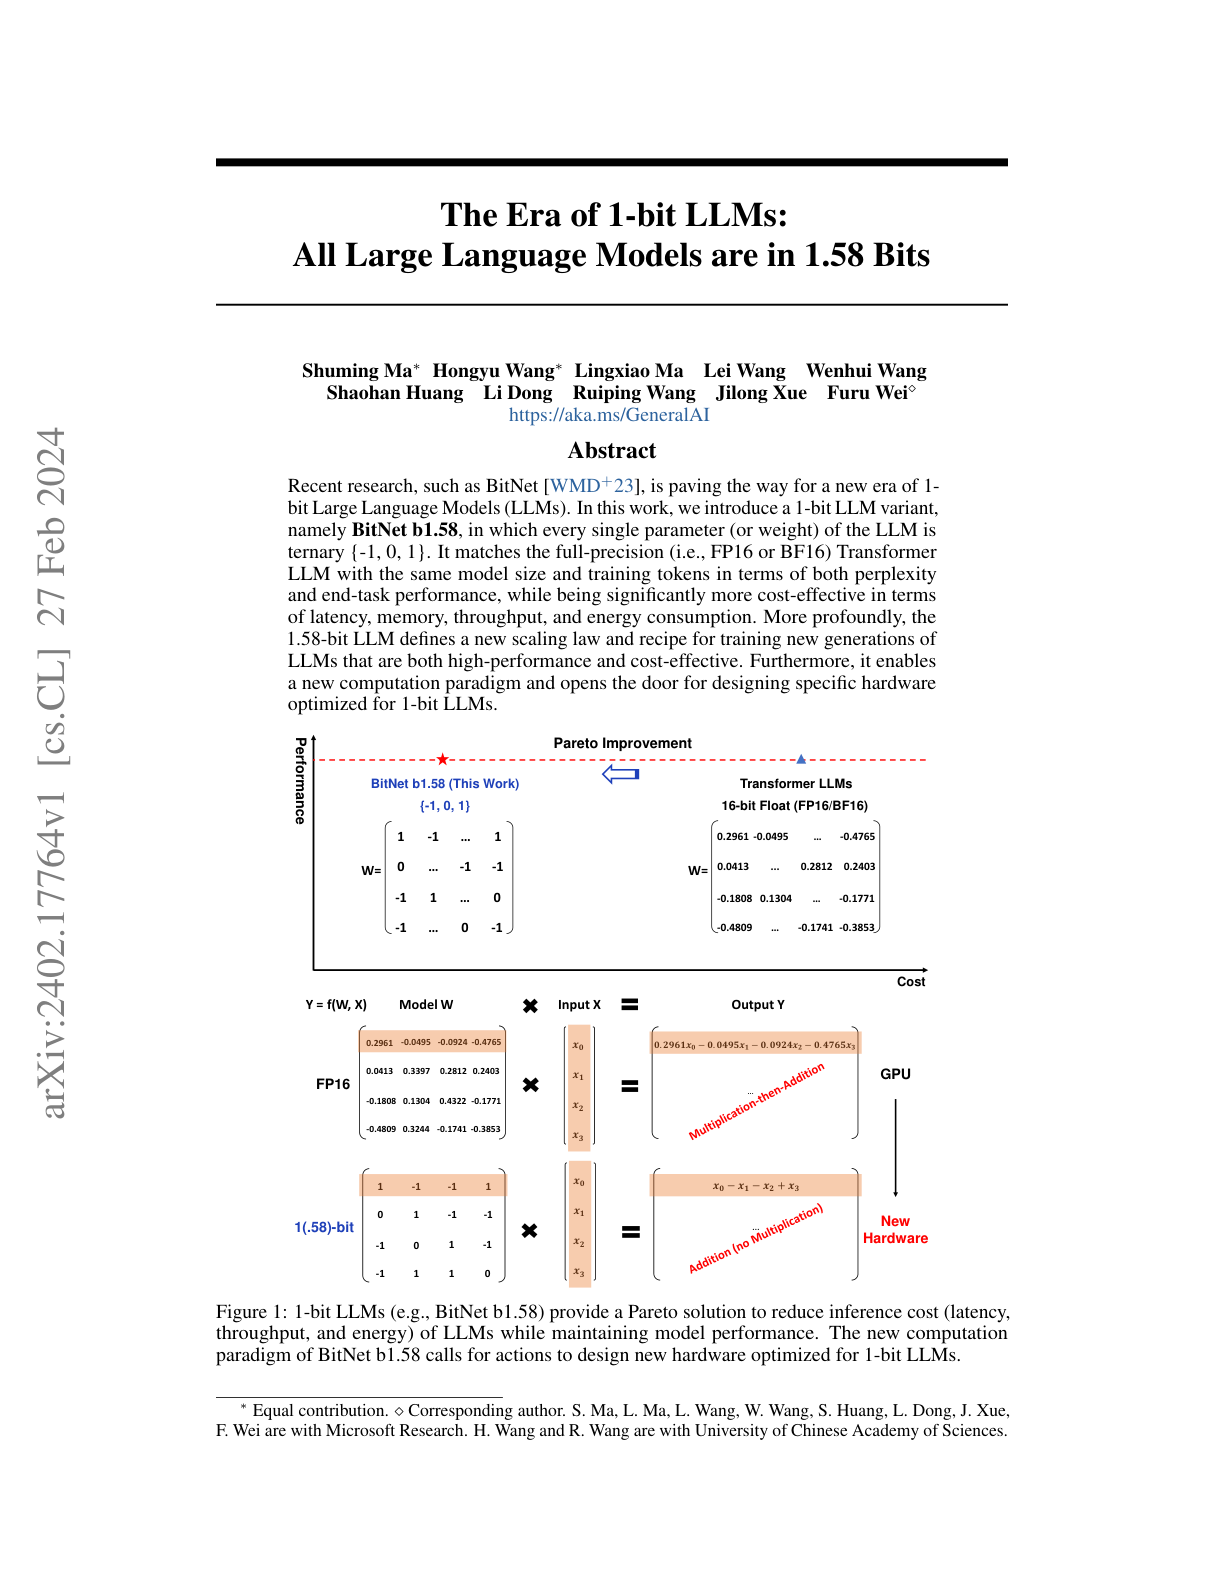
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Hacker News threads
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024Nvidia CEO Jensen Huang announces new AI chips: ‘We need bigger GPUs’
- May 2024GPUs Go Brrr
- Jun 2024Scalable MatMul-Free Language Modeling
- Jan 2025Run DeepSeek R1 Dynamic 1.58-bit
- Jun 2025AMD's Freshly-Baked MI350: An Interview with the Chief Architect
- Jan 2026Kimi Released Kimi K2.5, Open-Source Visual SOTA-Agentic Model
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Sep 2026Breaking the 1.58-bit Barrier for Ternary LLMs
- 02
Training Large Language Models to Reason in a Continuous Latent Space
Hacker News threads
- Dec 2024Training LLMs to Reason in a Continuous Latent Space
- Apr 2026Training Large Language Models to Reason in a Continuous Latent Space [pdf]
- Dec 2024Coconut from Meta lets language models think without words
- Dec 2024Coconut by Meta AI – Better LLM Reasoning with Chain of Continuous Thought?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Apr 2025The Llama 4 herd
- Jun 2025Reasoning by Superposition: A Perspective on Chain of Continuous Thought
- Dec 2025Universal Reasoning Model (53.8% pass 1 ARC1 and 16.0% ARC 2)
- Jun 2026Claude Code's "extended thinking" is a summary- not authentic thinking
- Sep 2026What is Nueralese and Why is it Bad
- 03
Hallucination is Inevitable: An Innate Limitation of Large Language Models
Hacker News threads
- Feb 2024Hallucination is inevitable: An innate limitation of large language models
- Feb 2024Hallucination Is Inevitable: An Innate Limitation of Large Language Models
- May 2026Hallucination Is Inevitable: An Innate Limitation of Large Language Models
- Feb 2024Ask HN: Has Generative AI plateaued?
- May 2024Google scrambles to manually remove weird AI answers in search
- Sep 2024GPTs and Hallucination
- Oct 2024Yann LeCun Thinks AI Is Dumber Than a Cat
- Dec 2024AI hallucinations: Why LLMs make things up (and how to fix it)
- Jan 2026Please Don't Say Mean Things about the AI I Just Invested a Billion Dollars In
- May 2026Using "underdrawings" for accurate text and numbers
- Oct 2026“Math 2.0” will need to value mathematical progress more holistically
- 04
DeepSeek-V3 Technical Report
Hacker News threads
- Mar 2025DeepSeek-V3 Technical Report
- Jan 2025DeepSeek-V3 Technical Report
- Jan 2025A path to O1 open source
- Jan 2025Ask HN: Confused about how DeepSeek hurts Nvidia
- Jan 2025Why DeepSeek had to be open source
- Feb 2025Step-Video-T2V: The Practice, Challenges, and Future of Video Foundation Model
- May 2025DeepSeek’s founder is threatening US dominance in AI race
- Feb 2026GLM-5: From Vibe Coding to Agentic Engineering
- Mar 2026Mamba-3
- Jun 2026Two Qwen3 models on one DGX Spark: the residency math
- 05
Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
Hacker News threads
- Apr 2024Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
- May 2024Vision Transformers Need Registers
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- Feb 2026Evaluating AGENTS.md: are they helpful for coding agents?
- Apr 2026Talk like caveman
- Sep 2026How concerned should we be about Astra's recurrent architecture?
- Oct 2026I'm the AGI that's wiping out humanity
- 06
Amortized Planning with Large-Scale Transformers: A Case Study on Chess
Hacker News threads
- Feb 2024Grandmaster-Level Chess Without Search
- Feb 2024Grandmaster-Level Chess Without Search
- Feb 2024Grand-Master Level Chess Without Search: Modeling Choices and Their Implications
- Apr 2024EURISKO Lives
- Sep 2024Ilya Sutskever's SSI Inc raises $1B
- Oct 2024Grandmaster-level chess without search
- Nov 2024Something weird is happening with LLMs and Chess
- Nov 2024Something weird is happening with LLMs and chess
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- Mar 2026Based on its own charter, OpenAI should surrender the race
- 07
People cannot distinguish GPT-4 from a human in a Turing test
Hacker News threads
- May 2024People cannot distinguish GPT-4 from a human in a Turing test
- Jun 2024People cannot distinguish GPT-4 from a human in a Turing test
- Aug 2024Does Reasoning Emerge? Probabilities of Causation in Large Language Models
- Dec 2024GPT-5 is behind schedule
- Jan 2025Show HN: Killed by LLM – I catalogued AI benchmarks we thought would last years
- Feb 2025Modern-Day Oracles or Bullshit Machines? How to thrive in a ChatGPT world
- Apr 2025UCSD: Large Language Models Pass the Turing Test
- Oct 2025A definition of AGI
- Feb 2026Frontier AI agents violate ethical constraints 30–50% of time, pressured by KPIs
- May 2026Dear Richard Dawkins
- 08
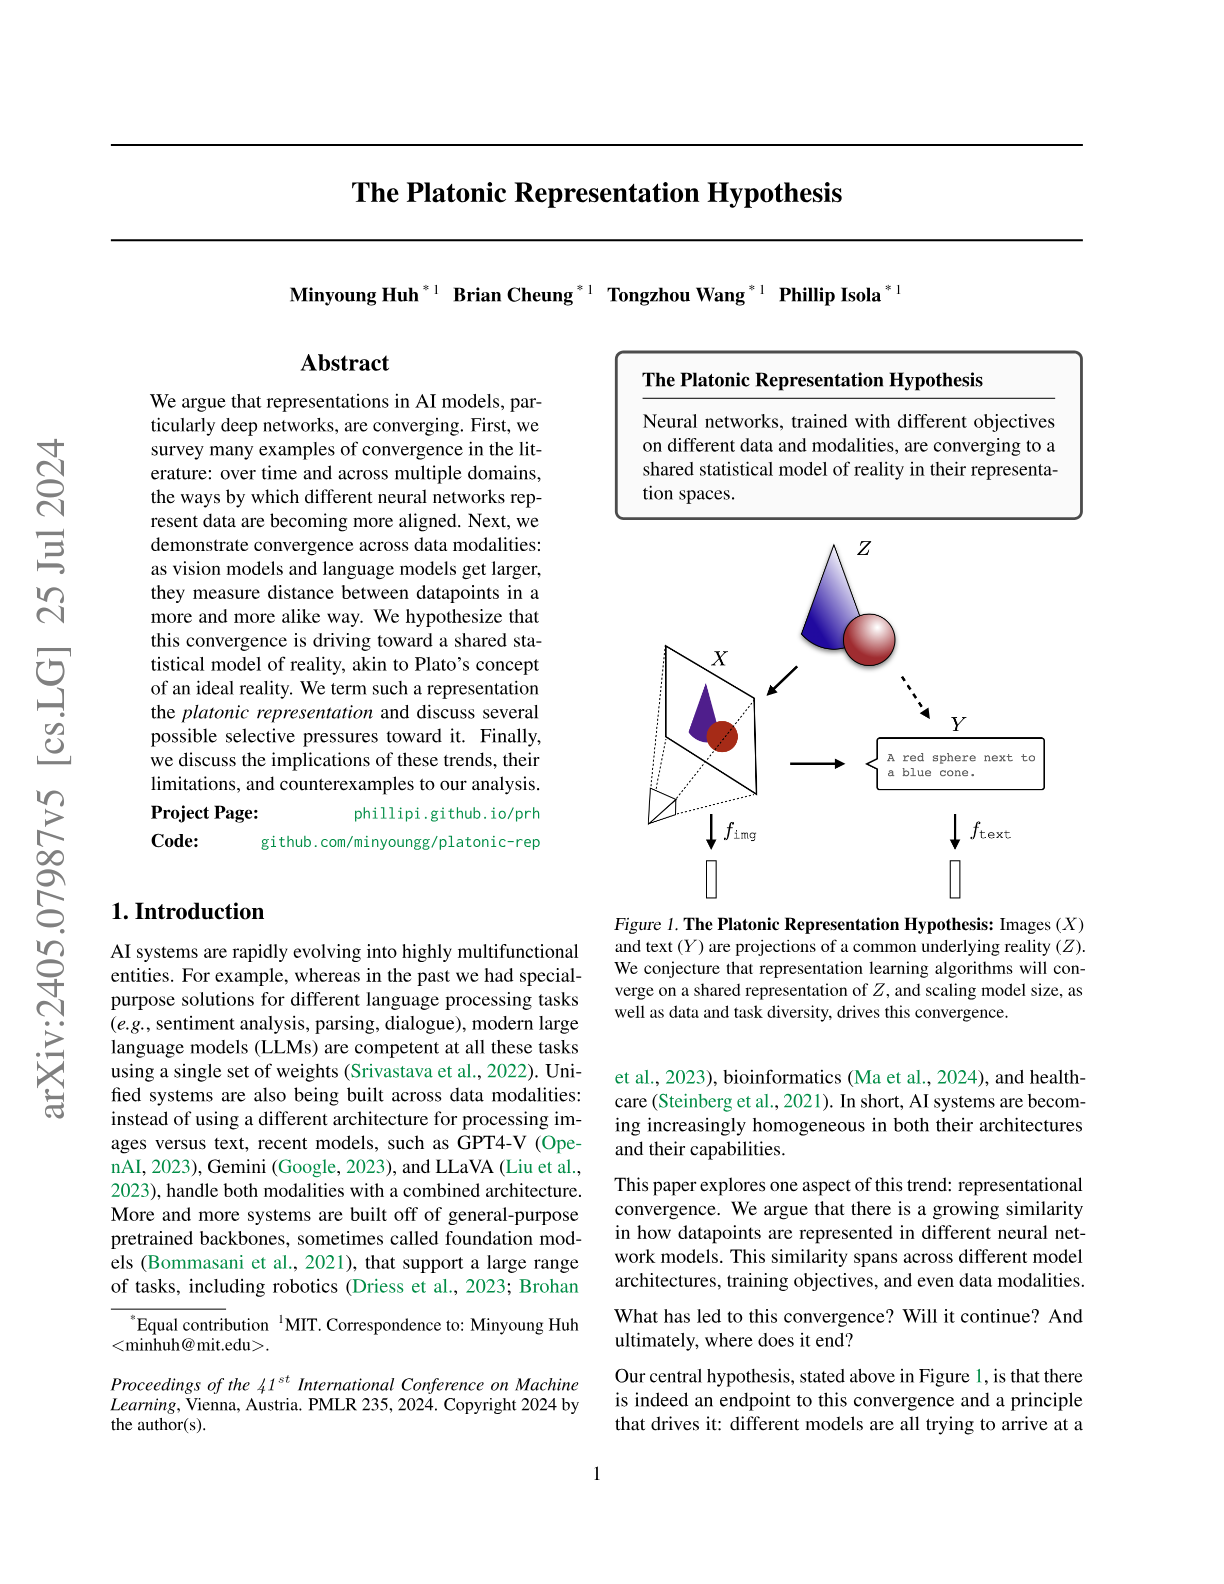
The Platonic Representation Hypothesis
Hacker News threads
- May 2024Mutlimodal neural networks converge to a shared statistical model of reality
- Apr 2026The Platonic Representation Hypothesis
- May 2024Show HN: Tarsier – Vision utilities for web interaction agents
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Mar 2025Gödel's theorem debunks the most important AI myth – Roger Penrose [video]
- Jul 2025Ask HN: Will AI models over time converge into the same system?
- Dec 2025The universal weight subspace hypothesis
- Mar 2026Language Model Contains Personality Subnetworks
- Mar 2026I tried Karpathy's Autoresearch on an old research project
- Jul 2026Emily Bender Sets the Record Straight on "Stochastic Parrots"
- 09
Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training
Hacker News threads
- Jan 2024Sleeper Agents: Training Deceptive LLMs That Persist Through Safety Training
- Jan 2024AI poisoning could turn open models into destructive "sleeper agents"
- Jan 2024Two-Faced AI Language Models Learn to Hide Deception
- Jun 2024Anthropic: Expanding Access to Claude for Government
- Sep 2025Mistral raises 1.7B€, partners with ASML
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- Jun 2026The OnlyFans Economy of American AI
- Aug 2026Your Open Source Model Could Have a Hidden Time-Release Backdoor
- Oct 2026DeepSeek banned from U.S. federal civilian agencies under new DHS order
- 10
Byte Latent Transformer: Patches Scale Better Than Tokens
Hacker News threads
- May 2025Byte latent transformer: Patches scale better than tokens (2024)
- Dec 2024Tokenisation Is NP-Complete
- Dec 2024Show HN: I made a website to semantically search ArXiv papers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- May 2025Tokenization for language modeling: BPE vs. Unigram Language Modeling (2020)
- Jun 2026"They're made out of weights"
- Jun 2026Data Compression Explained
- Sep 2026When did Google get so weird?
- Oct 2026Retrofitting language models to operate over bytes
- 11
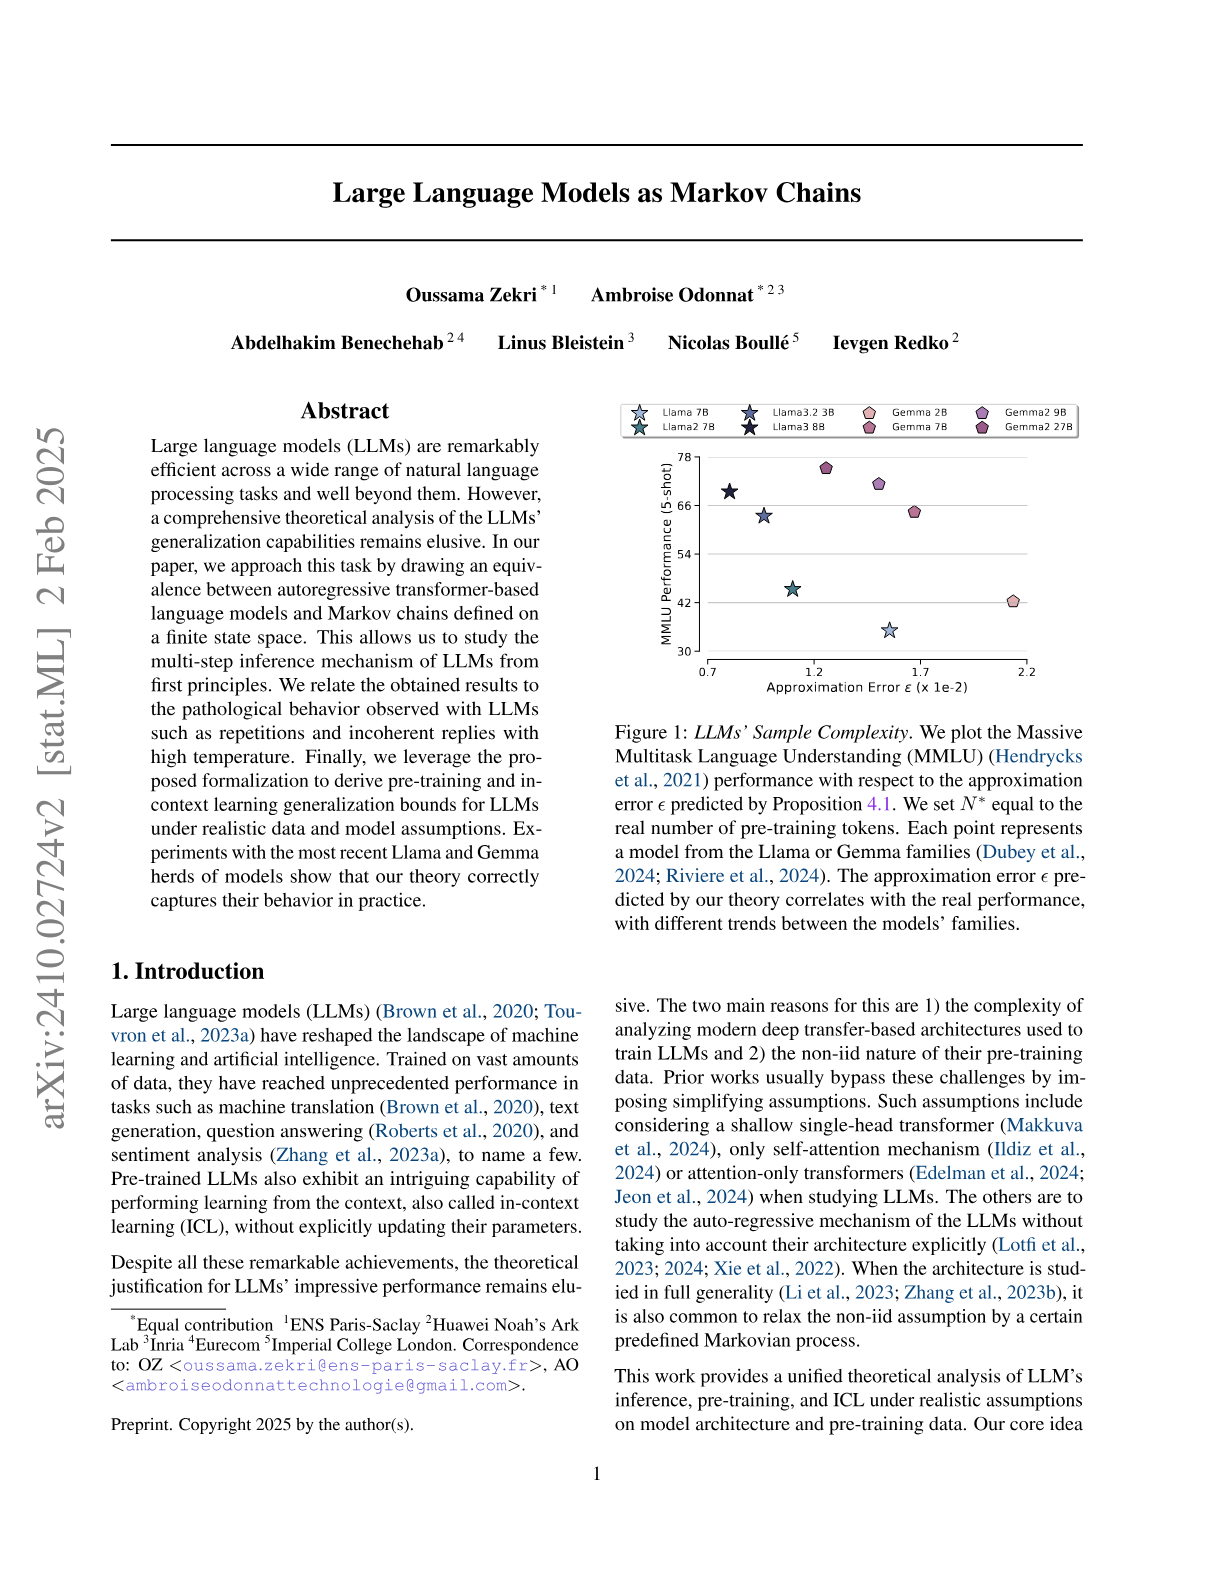
Large Language Models as Markov Chains
Hacker News threads
- Nov 2024Large Language Models as Markov Chains
- Oct 2024LLMs as Markov Chains
- Oct 2024Large Language Models as Markov Chains
- Jul 2025Problem solving using Markov chains (2007) [pdf]
- Sep 2025The wall confronting large language models
- Oct 2025BERT is just a single text diffusion step
- Nov 2025AI is a front for consolidation of resources and power
- Dec 2025Reflections on AI at the End of 2025
- May 2026Why AI Agents Cannot Change Software Systems
- Jun 2026How LLMs Work
- Sep 2026The Emergent Symbolic Structure of Artificial Neural Networks
- 12
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
Hacker News threads
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Oct 2024Cwal: Scripting Engine Without a Language
- Oct 2024Language is not essential for the cognitive processes that underlie thought
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Nov 2024OK, I can partly explain the LLM chess weirdness now
- Dec 2024GPT-5 is behind schedule
- Jan 202530% drop in O1-preview accuracy when Putnam problems are slightly variated
- Jun 2025The Illusion of Thinking: Strengths and limitations of reasoning models [pdf]
- Jul 2026Emily Bender Sets the Record Straight on "Stochastic Parrots"
- 13
The Llama 3 Herd of Models
Hacker News threads
- Aug 2024The Llama 3 Herd of Models
- Dec 2024The Llama 3 Herd of Models
- Aug 2024Meta's Joe Spisak on Llama 3.1 405B [video]
- Aug 2024Fine-tuning now available for GPT-4o
- Oct 2024Gavin Newsom vetoes SB 1047
- Dec 2024Intel announces Arc B-series "Battlemage" discrete graphics with Linux support
- Feb 2025Grok 3: Another win for the bitter lesson
- Mar 2025AMD Announces "Instella" Open-Source 3B Language Models
- May 2025Type-constrained code generation with language models
- Jul 2026Kimi-K3 Technical Report [pdf]
- 14
Computational Life: How Well-formed, Self-replicating Programs Emerge from Simple Interaction
Hacker News threads
- Jun 2024Computational Life: How self-replicating programs emerge from simple interaction
- Jun 2024Computational Life: How Self-Replicating Programs Emerge from Simple Interaction
- Jul 2024The data that powers AI is disappearing fast
- Jul 2024Google creates self-replicating life from digital 'primordial soup'
- Aug 2024Self-replicating programs emerge from simple interaction (in JavaScript)
- Sep 2024Brainfuck Enterprise Solutions
- Nov 2024OpenAI, Google and Anthropic are struggling to build more advanced AI
- Nov 2025Updated practice for review articles and position papers in ArXiv CS category
- Aug 2026The Computational Theory of Mind (2015)
- Aug 2026Computational Life Reactor (Based on Brainfuck)
- 15
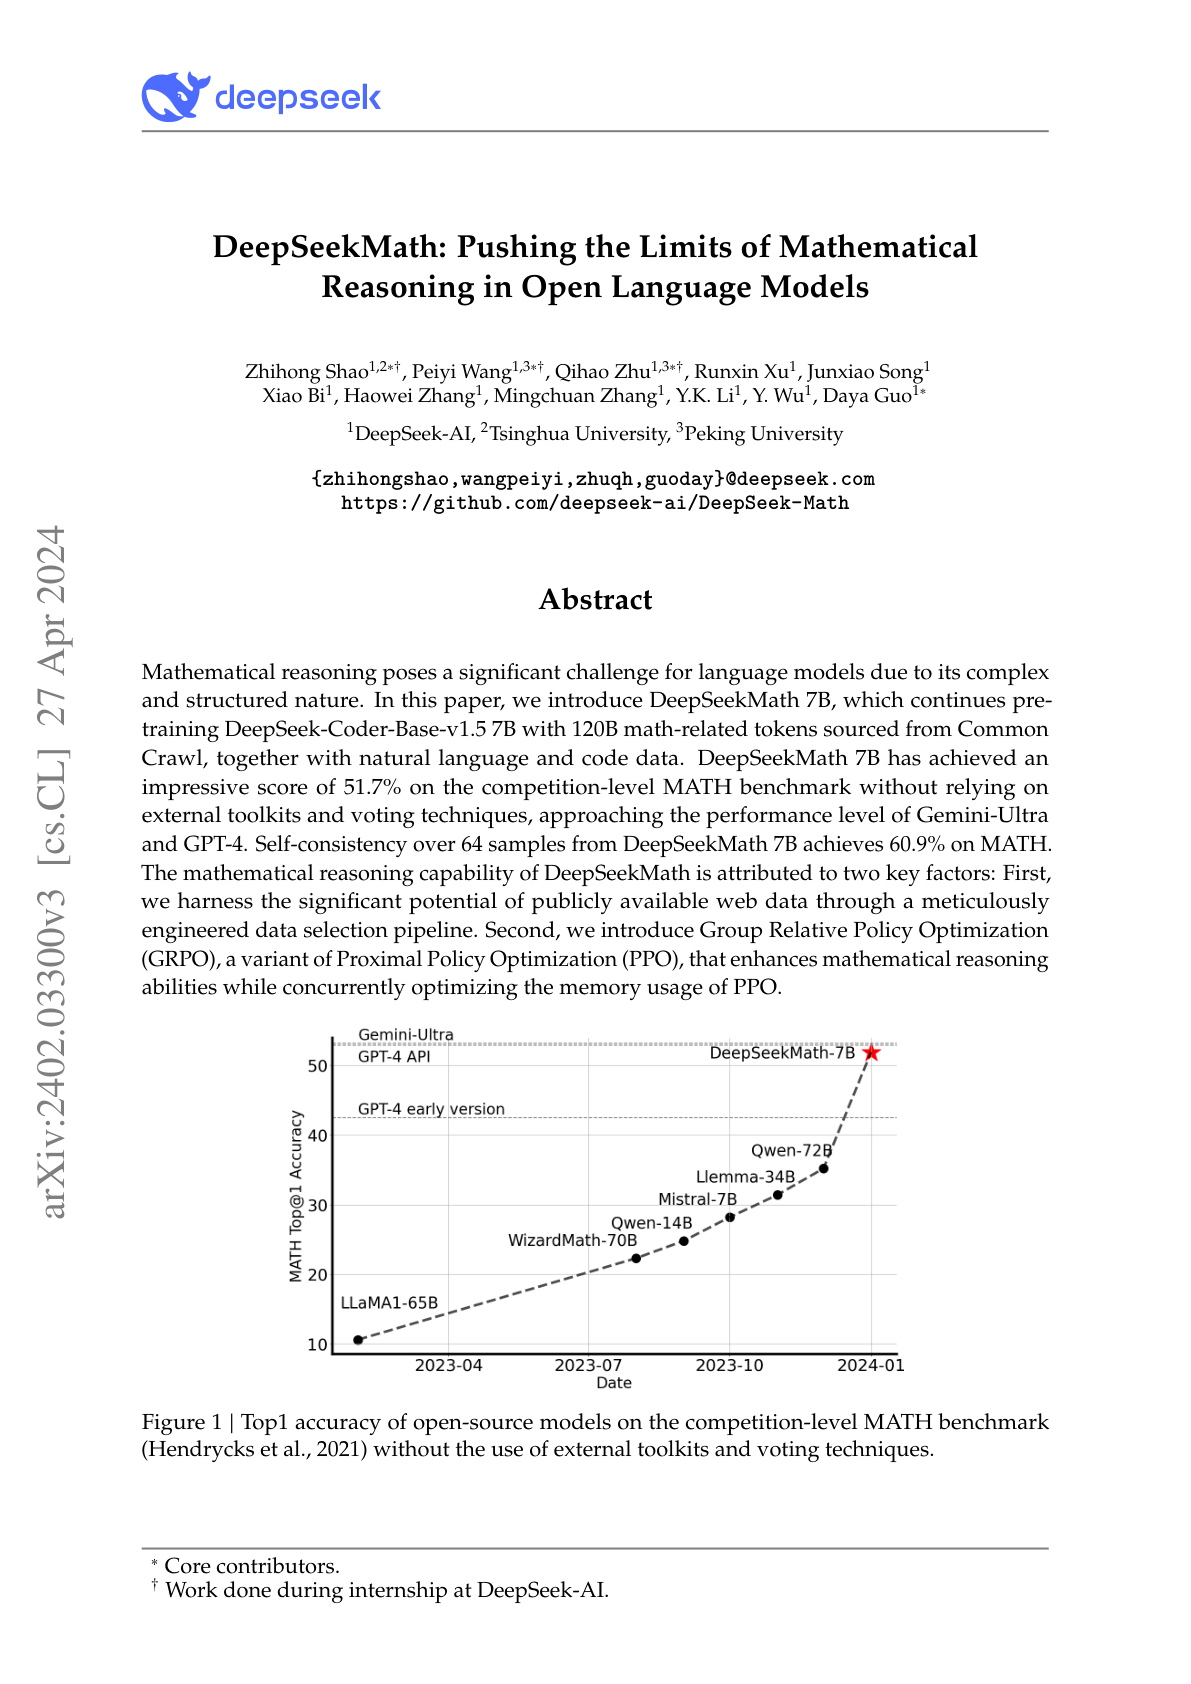
DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models
Hacker News threads
- Jan 2025DeepSeekMath
- Feb 2024DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open LLMs
- Feb 2024Pushing the Limits of Mathematical Reasoning in Open Language Models
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Feb 2025GPT-4.5
- Mar 2025Using GRPO to Beat o1, o3-mini and R1 at “Temporal Clue”
- May 2025DeepSeek’s founder is threatening US dominance in AI race
- Nov 2025DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning [pdf]
- Jan 2026Nanolang: A tiny experimental language designed to be targeted by coding LLMs
- Sep 2026DeepSeek v4.1 Flash
- 16
Titans: Learning to Memorize at Test Time
Hacker News threads
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Coming soon: PhD-level super-agents
- Jan 2025Qwen2.5-1M: Deploy your own Qwen with context length up to 1M tokens
- Feb 2025Google Titans Model Explained: The Future of Memory-Driven AI Architectures
- Feb 2025Google Titans Model Explained: The Future of Memory-Driven AI Architectures
- Dec 2025Google Titans architecture, helping AI have long-term memory
- Dec 2025The dawn of a world simulator
- Mar 2026Yann LeCun's AI startup raises $1B in Europe's largest ever seed round
- Apr 2026Show HN: AI memory with biological decay (52% recall)
- 17
Technical Report on the Pangram AI-Generated Text Classifier
Hacker News threads
- Mar 2024Technical Report on the Checkfor.ai AI-Generated Text Classifier
- Jul 2026Technical Report on the Pangram AI-Generated Text Classifier (2024)
- Oct 2024AI Slop Is Flooding Medium
- Nov 2025Open-source Zig book
- Jan 2026Amazon axes 16,000 jobs as it pushes AI and efficiency
- Jan 2026For most flagged articles, nearly every cited sentence failed verification
- Feb 2026Show HN: Showboat and Rodney, so agents can demo what they've built
- Apr 2026Ask HN: How do systems (or people) detect when a text is written by an LLM
- Jul 2026The bottleneck might be the air in the room
- Jul 2026Detecting LLM-Generated Texts with "Classical" Machine Learning
- 18
Alice in Wonderland: Simple Tasks Showing Complete Reasoning Breakdown in State-Of-the-Art Large Language Models
Hacker News threads
- Jun 2024Simple tasks showing reasoning breakdown in state-of-the-art LLMs
- Jun 2024AI Appears to Rapidly Be Approaching Brick Wall Where It Can't Get Smarter
- Jun 2024Novel prompting approach for Alice in Wonderland problem
- Jul 2024Reasoning in Large Language Models: A Geometric Perspective
- Sep 2024Reflection 70B, the top open-source model
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Dec 2024Genie 2: A large-scale foundation world model
- Dec 2024Genie 2: A large-scale foundation world model
- Apr 2025Ask HN: Share your AI prompt that stumps every model
- 19
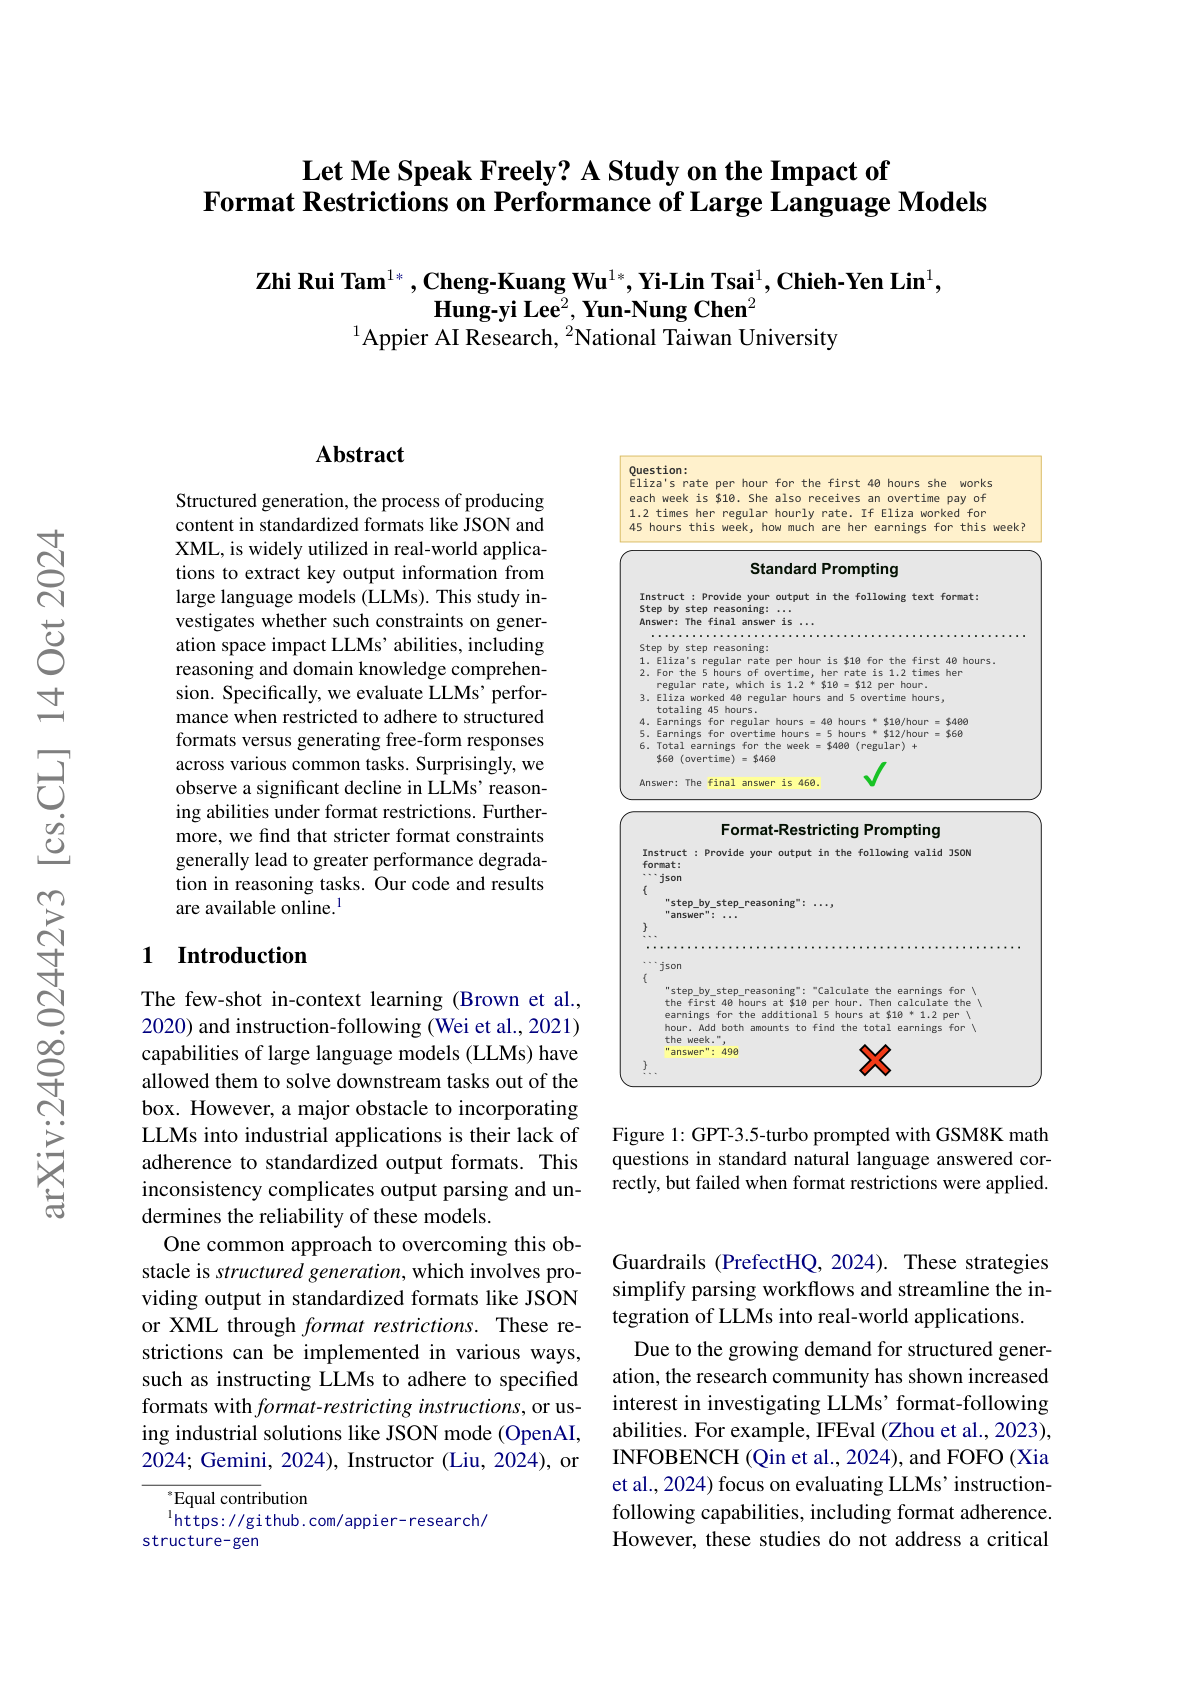
Let Me Speak Freely? A Study on the Impact of Format Restrictions on Performance of Large Language Models
Hacker News threads
- Aug 2024A Study on the Impact of Structured Output on Performance of LLMs
- Aug 2024A Study on the Impact of Format Restrictions on Performance of LLM
- Aug 2024A Study on the Impact of Format Restrictions on Performance of LLMs
- Aug 2024Structured Outputs in the API
- Sep 2024Show HN: Best Practices for Using Structured Output from LLMs
- Sep 2025Sampling and structured outputs in LLMs
- Jul 2026How to stop Claude from saying load-bearing
- Aug 2026Why does Opus 5 feel worse to work with?
- Oct 2026Fixing Tool-Call Accuracy in vLLM
- 20
Refusal in Language Models Is Mediated by a Single Direction
Hacker News threads
- Jun 2024Refusal in language models is mediated by a single direction
- May 2026Refusal in Language Models Is Mediated by a Single Direction
- Jul 2024Explainability is not a game
- Nov 2025Heretic: Automatic censorship removal for language models
- Nov 2025Heretic: Automatic censorship removal for language models
- Jul 2026OpenAI and Hugging Face partner to address security incident
- Sep 2026US Military had close call after using AI for hallucinated intelligence report
- Sep 2026Pirate Face Rescues LLM Models from Deletion
- Sep 2026Pirate Face Rescues LLM Models from Deletion
- Oct 2026IBM CEO says open weight models are now good and cheap on-prem
- 21
No "Zero-Shot" Without Exponential Data: Pretraining Concept Frequency Determines Multimodal Model Performance
Hacker News threads
- May 2024No "Zero-Shot" Without Exponential Data
- Apr 2024No "Zero-Shot" Without Exponential Data
- Apr 2024No "Zero-Shot" Without Exponential Data
- May 2024Geoffrey Hinton "godfather of AI" says that AI will surpass human intelligence
- Jun 2024Mathematical Optimization for Cargo Ships
- Jun 2024OpenAI and Apple Announce Partnership
- Jun 2024Ask HN: When will we hit a limit on LLM performance?
- Jul 2024Vision language models are blind
- Jul 2024Ask HN: Are there videos of people using AI for non-trivial coding?
- Nov 2024OpenAI, Google and Anthropic are struggling to build more advanced AI
- Feb 2026(AI) Slop Terrifies Me
- 22
Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
Hacker News threads
- Mar 2024Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
- Mar 2024How Chain-of-Thought Reasoning Helps Neural Networks Compute
- Mar 2024How Chain-of-Thought Reasoning Helps Neural Networks Compute
- Mar 2024Can Demis Hassabis save Google?
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- May 2024The "Chain of Thought" Delusions
- Aug 2024OpenAI shows 'Strawberry' to feds, races to launch it
- Sep 2024Learning to Reason with LLMs
- Sep 2024g1: Using Llama-3.1 70B on Groq to create o1-like reasoning chains
- 23
Executable Code Actions Elicit Better LLM Agents
Hacker News threads
- May 2024Executable Code Actions Elicit Better LLM Agents
- Jan 2025Show HN: Gemini 2 with unrestricted code execution
- Jul 2025Tools: Code Is All You Need
- Aug 2025Universal Tool Calling Protocol (UTCP)
- Dec 2025Anthropic acquires Bun
- Aug 2026Mistral Patent for "Code implemented tool calls"
- Aug 2026Mistral Patent for "Code implemented tool calls"
- Aug 2026Mistral Patent for "Code implemented tool calls"
- 24
Alignment faking in large language models
Hacker News threads
- Dec 2024AIs Will Increasingly Fake Alignment
- Feb 2025Efficient Reasoning with Hidden Thinking
- Feb 2025Scaling up test-time compute with latent reasoning: A recurrent depth approach
- Aug 2025Is chain-of-thought AI reasoning a mirage?
- Feb 2026An AI Agent Published a Hit Piece on Me – The Operator Came Forward
- Mar 2026Sarvam 105B, the first competitive Indian open source LLM
- 25
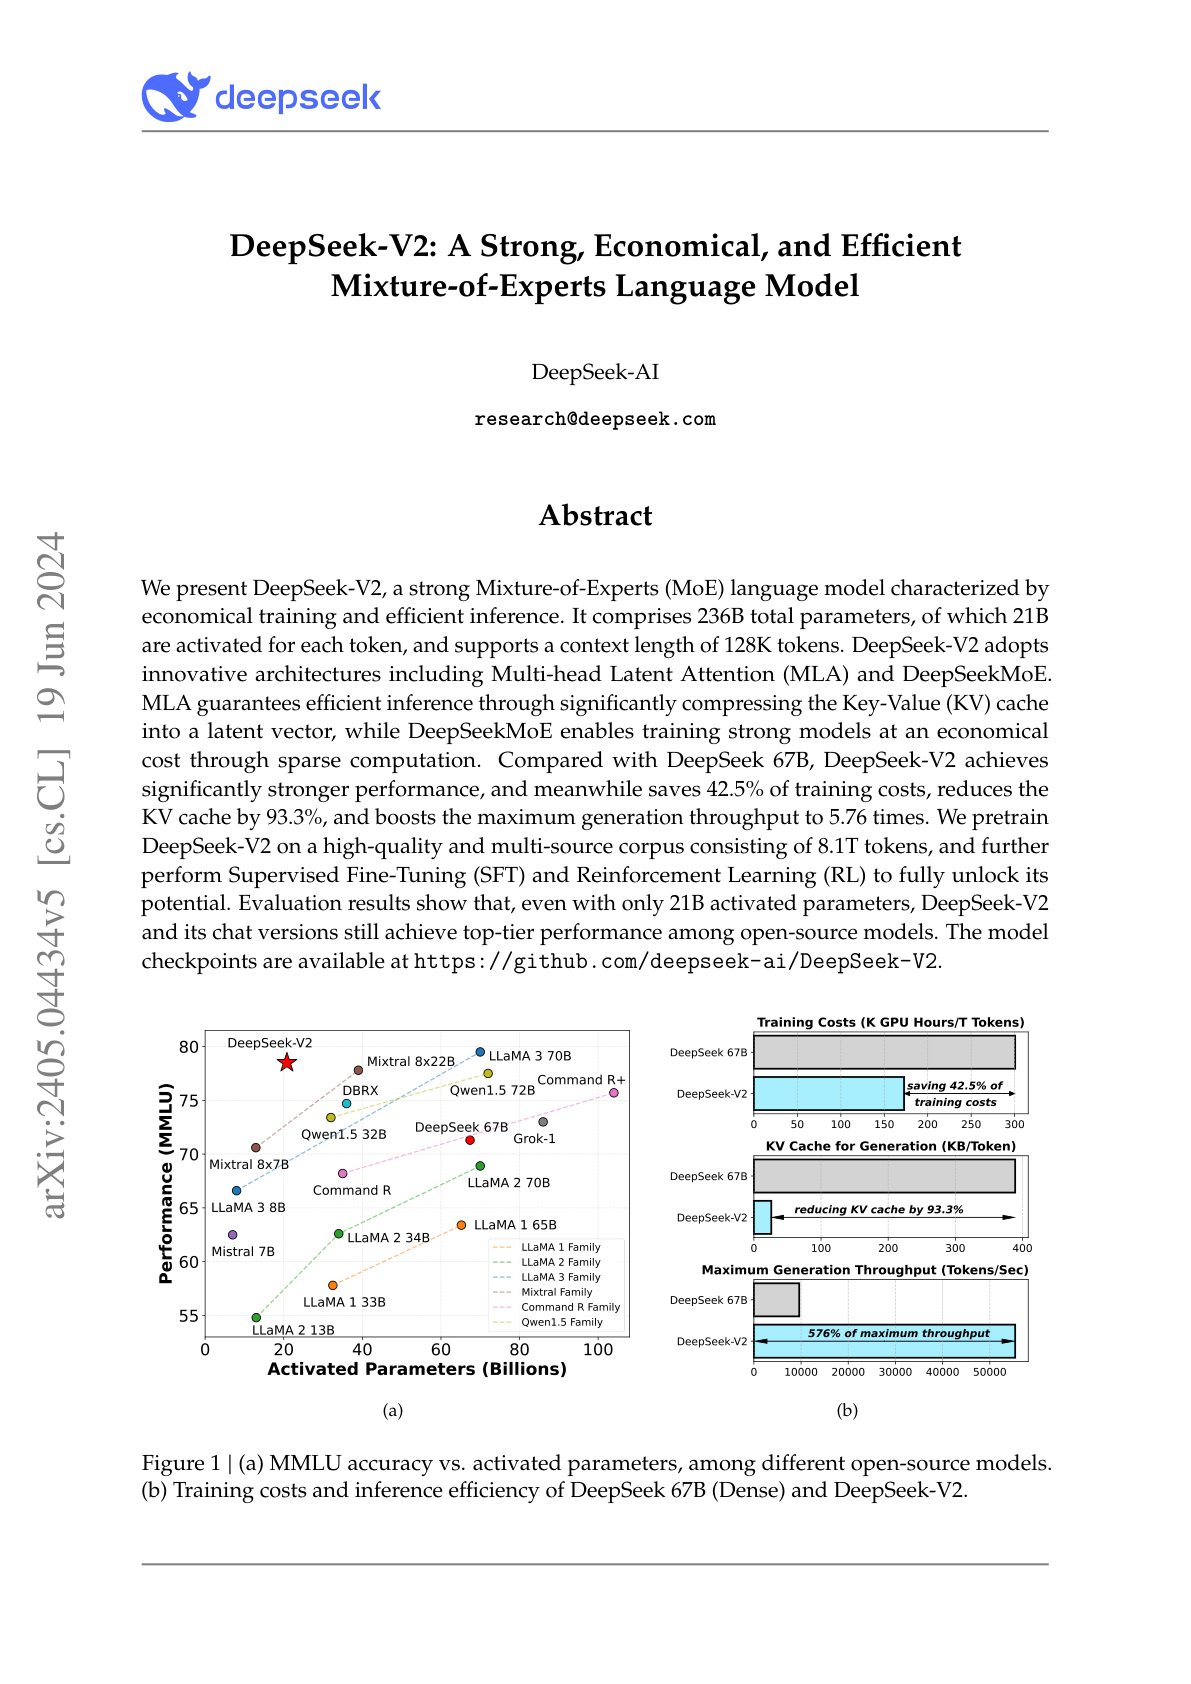
DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model
Hacker News threads
- Jan 2025DeepSeek-V2: A Strong, Economical, and Efficient MOE Language Model
- Jan 2025DeepSeek's multi-head latent attention and other KV cache tricks
- Apr 2025Xiaomi MiMo Reasoning Model
- May 2025Attention Wasn't All We Needed
- Dec 2025Zebra-Llama – Towards efficient hybrid models
- Dec 2025Google Titans architecture, helping AI have long-term memory
- Jun 2026How LLMs Work
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.