Hacker Papers
- 151
Driven by Compression Progress: A Simple Principle Explains Essential Aspects of Subjective Beauty, Novelty, Surprise, Interestingness, Attention, Curiosity, Creativity, Art, Science, Music, Jokes
Hacker News threads
- Jan 2017Subjective Beauty, Novelty, Surprise, Interestingness, Attention, Curiosity,
- Aug 2019Driven by Compression Progress (Schmidhuber, 2008)
- Apr 2023Driven By Compression Progress (2008)
- Sep 2017Ask HN: CS as a philosophy
- Oct 2017Intelligence Reconsidered
- Mar 2021Information Is Surprise (2015)
- Mar 2021Hutter Prize
- Jul 2024Creativity fundamentally comes from memorization?
- Mar 2025ARC-AGI without pretraining
- Aug 2026Compression Is Prediction
- Sep 2026Asking Authors About Their Own Papers
- 152
Learning Transferable Visual Models From Natural Language Supervision
Hacker News threads
- Mar 2021The End of Tesla’s Dominance May Be Closer Than It Appears
- Aug 2021Machine learning won't solve natural language understanding
- Apr 2022A few things to try with DALL·E
- Apr 2022How DALL-E 2 Works
- Mar 2024Is Cosine-Similarity of Embeddings Really About Similarity?
- Aug 2024Artists score major win in copyright case against AI art generators
- Jan 2025Don't use cosine similarity carelessly
- Mar 2025Ask HN: Any truly multi-modal transformer architectures?
- 153
High-Resolution Image Synthesis with Latent Diffusion Models
Hacker News threads
- Aug 2022Build Your Own Imagen Text-to-Image Model
- Sep 2022Stable Diffusion forming images from text: image snapshots at each step
- Sep 2022A Web UI for Stable Diffusion
- Mar 2023The Most Cited AI Papers in 2022
- Jul 2023Stanford A.I. Courses
- Feb 2024The VAE Used for Stable Diffusion Is Flawed
- Jul 2024AI models collapse when trained on recursively generated data
- Dec 2025Show HN: I remade my website in the Sith Lord Theme and I hope it's fun
- 154
Copy-and-Patch Compilation: A fast compilation algorithm for high-level languages and bytecode
Hacker News threads
- Jun 2024Copy-and-Patch: Fast compilation for high-level languages and bytecode (2020)
- Sep 2021Copy-and-Patch: Fast JIT Compilation for SQL, WebAssembly, and Others
- Sep 2022Wasmtime 1.0
- Nov 2022Building the fastest Lua interpreter automatically
- Dec 2023Brandt Bucher – A JIT Compiler for CPython
- Jan 2024Python 3.13 Gets a JIT
- Mar 2024Cranelift code generation comes to Rust
- Jul 2024Mining JIT traces for missing optimizations with Z3
- Apr 2025Co-designing a sparse music codec with ChatGPT o3
- Sep 2025Writing Memory Safe JIT Compilers
- 155
A Conceptual Introduction to Hamiltonian Monte Carlo
Hacker News threads
- Feb 2017A Conceptual Introduction to Hamiltonian Monte Carlo
- Nov 2024Overview of differential geometry for Hamiltonian Monte Carlo
- Sep 2025A Conceptual Introduction to Hamiltonian Monte Carlo [pdf]
- May 2017How Bayesian Inference Works (2016)
- Nov 2017Gaussian Distributions Are Soap Bubbles
- Oct 2018Bayes’ Theorem in the 21st Century (2013) [pdf]
- Dec 2018Hamiltonian Monte Carlo explained
- Apr 2019Ask HN: Best place to start learning about Markov Chains?
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- Mar 2024Claude 3 Opus reinvented this quantum algorithm from scratch in just 2 prompts
- Dec 2025What I don’t like about chains of thoughts (2023)
- 156
Monolith: Real Time Recommendation System With Collisionless Embedding Table
Hacker News threads
- Nov 2022Monolith: Real time recommendation system with collisionless embedding table
- Nov 2022TikTok published an article on their recommendation system architecture
- Nov 2022Paper on 'Monolith: Real Time Recommendation System' by Bytedance Inc (TikTok)
- Dec 2022TikTok’s Secret Sauce
- Jan 2023Ask HN: Techwise, how did TikTok get so good?
- Feb 2023The secret sauce of TikTok’s recommendations
- Nov 2023X is changing its algorithm to highlight smaller accounts
- Dec 2024TikTok divestment law upheld by federal appeals court
- Jan 2025TikTok preparing for U.S. shut-off on Sunday
- May 2025You Don't Need Re-Ranking: Understanding the Superlinked Vector Layer
- Feb 2026TikTok's 'Addictive Design' Found to Be Illegal in Europe
- 157
Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity
Hacker News threads
- Jan 2021Google breaks the trillion-parameter ceiling with the Switch Transformer
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Sparsity
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Simple Sparsity
- Aug 2021Program Synthesis with Large Language Models
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Jan 2022The Illustrated Retrieval Transformer
- Mar 2023GPT-4
- Jun 2023GPT4 is 8 x 220B params = 1.7T params
- Jul 2023GPT-4 is getting worse over time, not better
- Oct 2023Decomposing Language Models into Understandable Components
- May 2026Granite 4.1: IBM's 8B Model Matching 32B MoE
- 158
Adam: A Method for Stochastic Optimization
Hacker News threads
- Oct 2015Adam's method for stochastic optimization
- Jan 2017A New Batch of Deep Learning Startups to Watch for in 2017
- Oct 2017Variational Inference and Deep Learning: A New Synthesis [pdf]
- Feb 2023Exclusive Q&A John Carmack’s ‘Different Path’ to Artificial General Intelligence
- Jul 2023A Theory on Adam Instability in Large-Scale Machine Learning
- May 2024xLSTM: Extended Long Short-Term Memory
- Oct 2024Anthropic hires OpenAI co-founder Durk Kingma
- Mar 2025The PhD Metagame: Don't try to reform science – not yet
- Oct 2025Researchers Discover the Optimal Way to Optimize
- 159
Binarized Neural Networks: Training Deep Neural Networks with Weights and Activations Constrained to +1 or -1
Hacker News threads
- Sep 2016Stacked Approximated Regression Machine: A Simple Deep Learning Approach
- Oct 2016Intel will add deep-learning instructions to its processors
- Feb 2017Intel Gets Serious About Neuromorphic, Cognitive Computing Future
- Sep 2017Nonlinear Computation in Deep Linear Networks
- Oct 2018MIT AGI: Conversation with Yoshua Bengio [video]
- Nov 2019Deep Learning and Its Implications for Computer Architecture and Chip Design
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- 160
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 161
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 162
Twitter mood predicts the stock market
Hacker News threads
- May 2011Twitter mood predicts the stock market.
- Nov 2010Twitter mood predicts the stock market
- May 2011Twitter mood predicts the stock market
- Oct 2010Twitter Mood Predicts The Stock Market
- Nov 2010Can LinkedIn predict when companies are in trouble?
- Dec 2010Hedge fund to use Twitter to predict stock market
- Jul 2011MongoDB is the New MySQL
- Mar 2012What you could do if you were Google and had their databases
- May 2012Looking At The World Through Twitter Data
- Sep 2012Twitter is a tragic tale
- Mar 2014Can the Bloomberg Terminal be "Toppled"?
- 163
Practical Bayesian Optimization of Machine Learning Algorithms
Hacker News threads
- Apr 2015Practical Bayesian Optimization of Machine Learning Algorithms (2012)
- May 2015PRACTICAL BAYESIAN OPTIMIZATION OF MACHINE LEARNING ALGORITHMS [pdf]
- Jul 2012Machine learning for the impatient: algorithms tuning algorithms
- Nov 2012How deep learning on GPUs wins datamining contest without feature engineering
- Jan 2013Ersatz - Deep neural networks in the cloud
- Nov 2013Machine learning is easier than it looks
- Dec 2013Hyperopt: Optimize your machine learning parameters automagically
- Jun 2015Whetlab.com: API for Baysian optimization of hyperparameters
- Jan 2018Show HN: A radically more scalable alternative to Bayesian Optimization
- Jul 2018Troubling Trends in Machine Learning Scholarship
- 164
Man is to Computer Programmer as Woman is to Homemaker? Debiasing Word Embeddings
Hacker News threads
- Jul 2016Debiasing Word Embeddings
- Jul 2016Man Is to Computer Programmer as Woman Is to Homemaker? Debiasing Word Embedding
- Jan 2017Man to Computer Programmer as Woman is to Homemaker? Debiasing Word Embeddings
- Sep 2016A.I. Doesn't Get Black Twitter
- Jul 2017Ask HN: Any tools to easily cluster ideas/notes by similarity?
- Oct 2017Copyright Law Can Fix Artificial Intelligence’s Implicit Bias Problem
- Mar 2018Show HN: Word2Bits – Quantized Word Vectors
- Oct 2018Show HN: Basilica – word2vec for anything
- Jul 2019King – Man + Woman = King?
- Sep 2019600k Images Removed from ImageNet After Art Project Exposes Racist Bias
- Sep 2020FB to curb internal debate over sensitive issues amid employee discord
- 165
Counting Immutable Beans: Reference Counting Optimized for Purely Functional Programming
Hacker News threads
- Aug 2019Counting Immutable Beans: Reference Counting for Purely Functional Programming
- Dec 2020A Review of the Lean Theorem Prover
- Feb 2021A simple ray tracer in Lean 4
- Jul 2022Reference count, don't garbage collect
- Sep 2022Ask HN: Is Clojure Dead?
- Jun 2023Microsoft Research: Fully In-Place Functional Programming [pdf]
- Oct 2023Lean4 helped Terence Tao discover a small bug in his recent paper
- Nov 2023HN thread 38359488
- Feb 2025Neut Programming Language
- 166
The Loss Surfaces of Multilayer Networks
Hacker News threads
- Jan 2019The Loss Surfaces of Multilayer Networks
- Mar 2015Deep Learning vs. Machine Learning vs. Pattern Recognition
- Jun 2015What's Wrong with Deep Learning?
- Aug 2015Machine Learning: Curse of Dimensionality
- Feb 2016AI is transforming Google search – the rest of the web is next
- Aug 2016What’s Next for Artificial Intelligence
- May 2017Breaking Glass in Infinite Dimensions
- Dec 2017An Interview with an Anonymous Data Scientist (2016)
- Aug 2020Differentiable Control Problems
- 167
ByT5: Towards a token-free future with pre-trained byte-to-byte models
Hacker News threads
- May 2022Teaching GPT-3 to reverse words
- Dec 2022ChatGPT, Rot13, and Daniel Kahneman
- Mar 2023Cerebras-GPT vs. LLaMA AI Model Performance Comparison
- Apr 2023A Baby GPT
- Jun 2023Understanding GPT Tokenizers
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024Something weird is happening with LLMs and chess
- Jun 2026Data Compression Explained
- 168
Expanding Confusion: common misconceptions of cosmological horizons and the superluminal expansion of the Universe
Hacker News threads
- Jul 2011Giant body of water found in space, black hole claims it was just hydrating
- Jul 2012How big is the entire universe?
- Aug 2015Olbers' paradox
- Aug 2018Astronomers report the most distant radio galaxy ever discovered
- Jun 202012 Billion-year-old signal from the end of the universe's 'dark age'
- Aug 2023Shouldn't distant objects appear magnified
- Dec 2023Astronomers posit that we live in a giant void
- Apr 2024Webb captures iconic Horsehead Nebula in unprecedented detail
- 169
No need for conspiracy: Self-organized cartel formation in a modified trust game
Hacker News threads
- Jan 2012Cartels Are an Emergent Phenomenon, Say Complexity Theorists
- Mar 2014How are cold-calling ceasefires illegal?
- Feb 2015The Billion Dollar Startup Club
- Jul 2015Airbnb, My $1B Lesson
- Jan 2016Economics Simulation
- Aug 2017Uber drivers gang up to cause surge pricing, research says
- Mar 2021U.S. says John McAfee indicted over fraudulent cryptocurrency schemes
- Aug 2024San Francisco seeks ban of software critics say is used to inflate rents
- 170
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
Hacker News threads
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Oct 2024Cwal: Scripting Engine Without a Language
- Oct 2024Language is not essential for the cognitive processes that underlie thought
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Nov 2024OK, I can partly explain the LLM chess weirdness now
- Dec 2024GPT-5 is behind schedule
- Jan 202530% drop in O1-preview accuracy when Putnam problems are slightly variated
- Jun 2025The Illusion of Thinking: Strengths and limitations of reasoning models [pdf]
- Jul 2026Emily Bender Sets the Record Straight on "Stochastic Parrots"
- 171
Extracting books from production language models
Hacker News threads
- Jan 2026Extracting books from production language models
- Jan 2026Extracting books from production language models
- Jan 2026Extracting books from production language models (2026)
- Jan 2026Nvidia Contacted Anna's Archive to Access Books
- Feb 2026We tasked Opus 4.6 using agent teams to build a C Compiler
- Feb 2026Microsoft offers guide to pirating Harry Potter series for LLM training
- Mar 2026Relicensing with AI-Assisted Rewrite
- Mar 2026FSF Threatens Anthropic over Infringed Copyright: Share Your LLMs Freel
- Jun 2026Did Claude Increase Bugs in Rsync?
- Jul 2026Judge approves $1.5B Anthropic settlement for pirated books used to train Claude
- Sep 2026When did Google get so weird?
- 172
Reflexion: Language Agents with Verbal Reinforcement Learning
Hacker News threads
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023GPT-4 performs significantly worse on coding problems not in its training data
- Mar 2023ChatGPT and Code Interpreter = Magic
- Apr 2023HuggingGPT: Solving AI Tasks with ChatGPT and Its Friends in HuggingFace
- Apr 2023Defamed by ChatGPT: Law professor libeled from whole cloth
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- Jul 2023Langchain Is Pointless
- Aug 2023Maccarone: AI-managed code blocks in Python
- Oct 2024Update on Reflection-70B
- 173
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Hacker News threads
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree-of-Thought (ToT), complex and general problem solving with LLMs
- May 2023Ask HN: Those with success using GPT-4 for programming – what are you doing?
- May 2023Tree of Thoughts
- Jun 2023Tree of Thoughts: Official vs. Wrong Implementation
- Jun 2023Native JSON Output from GPT-4
- Jun 2023LLM Powered Autonomous Agents
- Jul 2023Bard’s latest update: more features, languages and countries
- Sep 2024g1: Using Llama-3.1 70B on Groq to create o1-like reasoning chains
- Mar 2026Tree Search Distillation for Language Models Using PPO
- 174
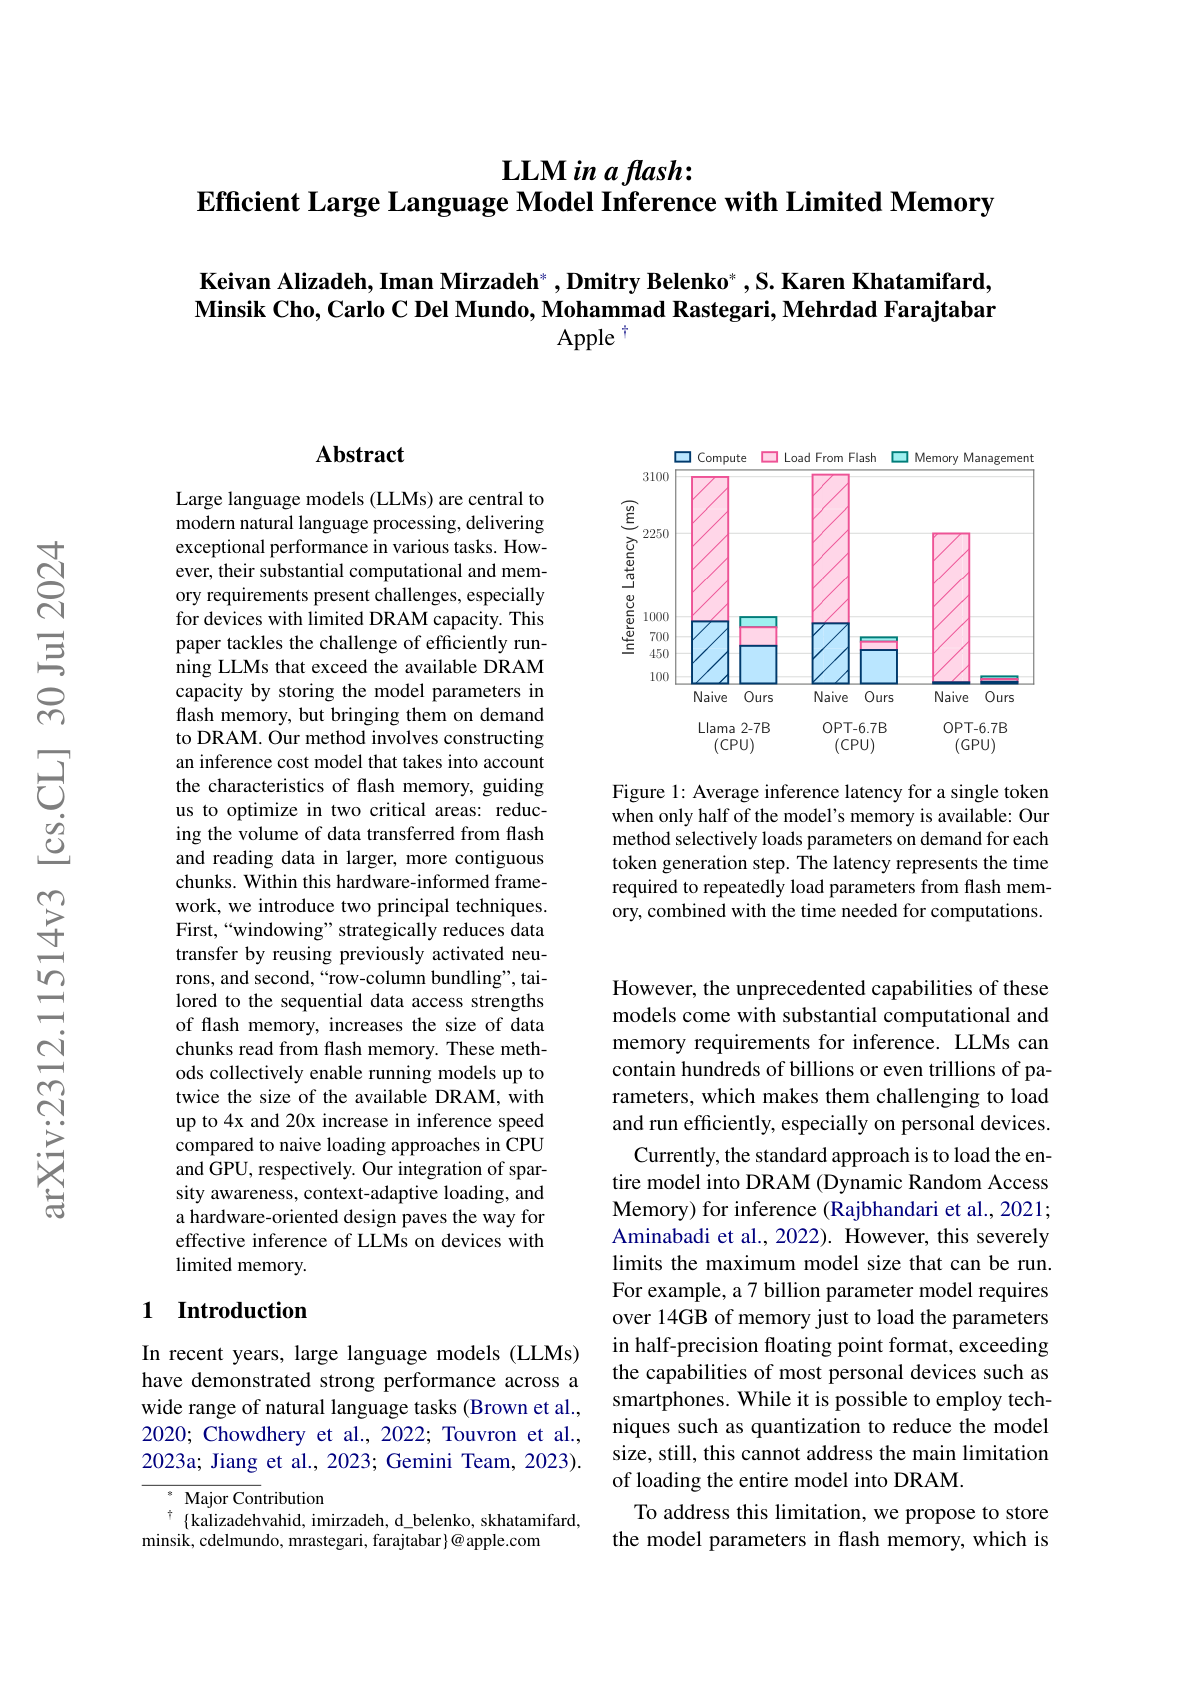
LLM in a flash: Efficient Large Language Model Inference with Limited Memory
Hacker News threads
- Jan 2024LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023Apple Announces LLM in a Flash: Efficient LLM Inference with Limited Memory
- Dec 2023Apple wants AI to run directly on its hardware instead of in the cloud
- Dec 2023Show HN: Emu2 – A Gemini-like open-source 37B Multimodal Model
- Dec 2023Ferret: A Multimodal Large Language Model
- Mar 2024Towards 1-bit Machine Learning Models
- Mar 2026Qwen3.5-397B at 4.74 tok/s using 5.9GB RAM
- Mar 2026iPhone 17 Pro Demonstrated Running a 400B LLM
- Aug 2026New Mac Studio with M5 Max and M5 Ultra
- 175
TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning with Hardware Support for Embeddings
Hacker News threads
- Apr 2023TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning
- Apr 2023TPU v4 provides exaFLOPS-scale ML with industry-leading efficiency
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023MTIA v1: Meta’s first-generation AI inference accelerator
- May 2023Nvidia DGX GH200: The First 100 Terabyte GPU Memory System
- May 2025OpenTPU: Open-Source Reimplementation of Google Tensor Processing Unit (TPU)
- Jun 2025Basic Facts about GPUs
- Oct 2026Homa: The end of TCP for AI clusters [video]
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.