Context Embeddings for Efficient Answer Generation in RAG
First page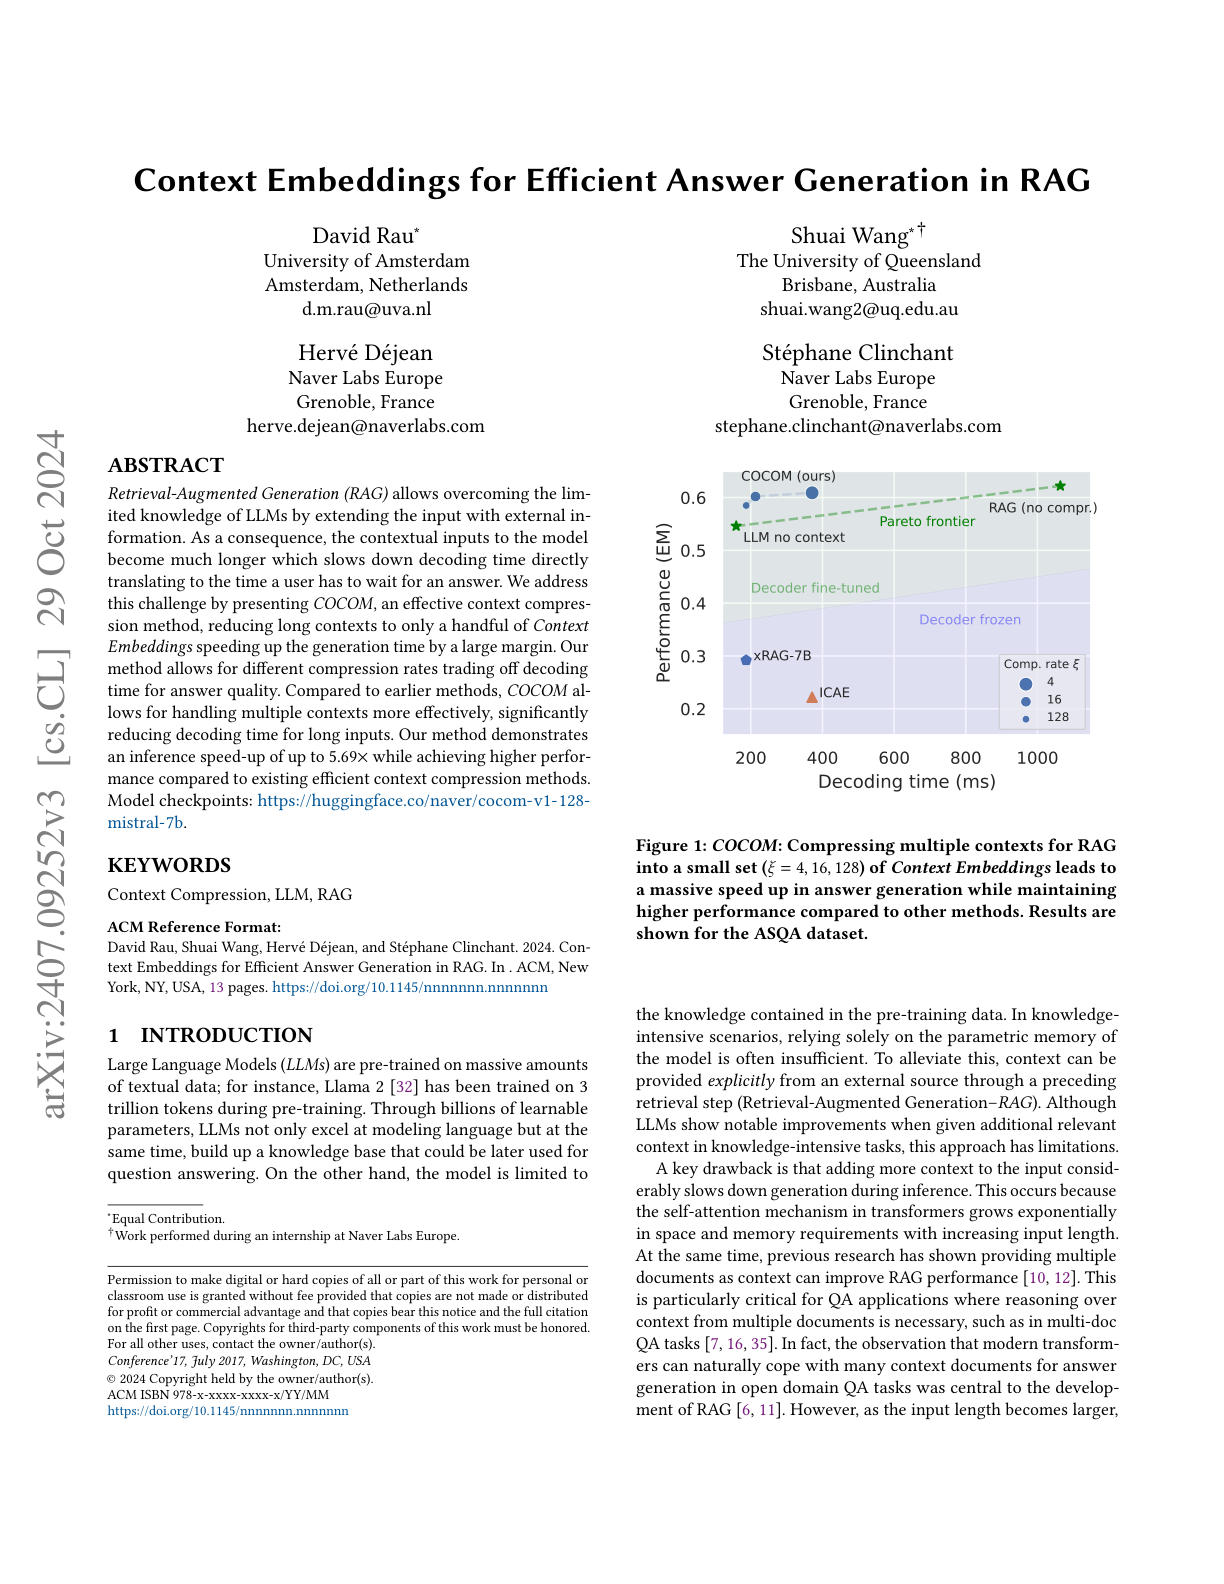
Paper summary
proposes an effective context compression method to reduce long context and speed up generation time in RAG systems; the long contexts are compressed into a small number of context embeddings which allow different compression rates that trade-off decoding time for generation quality; reduces inference time by up to 5.69 × and GFLOPs by up to 22 × while maintaining high performance.