DeepSeek-R1
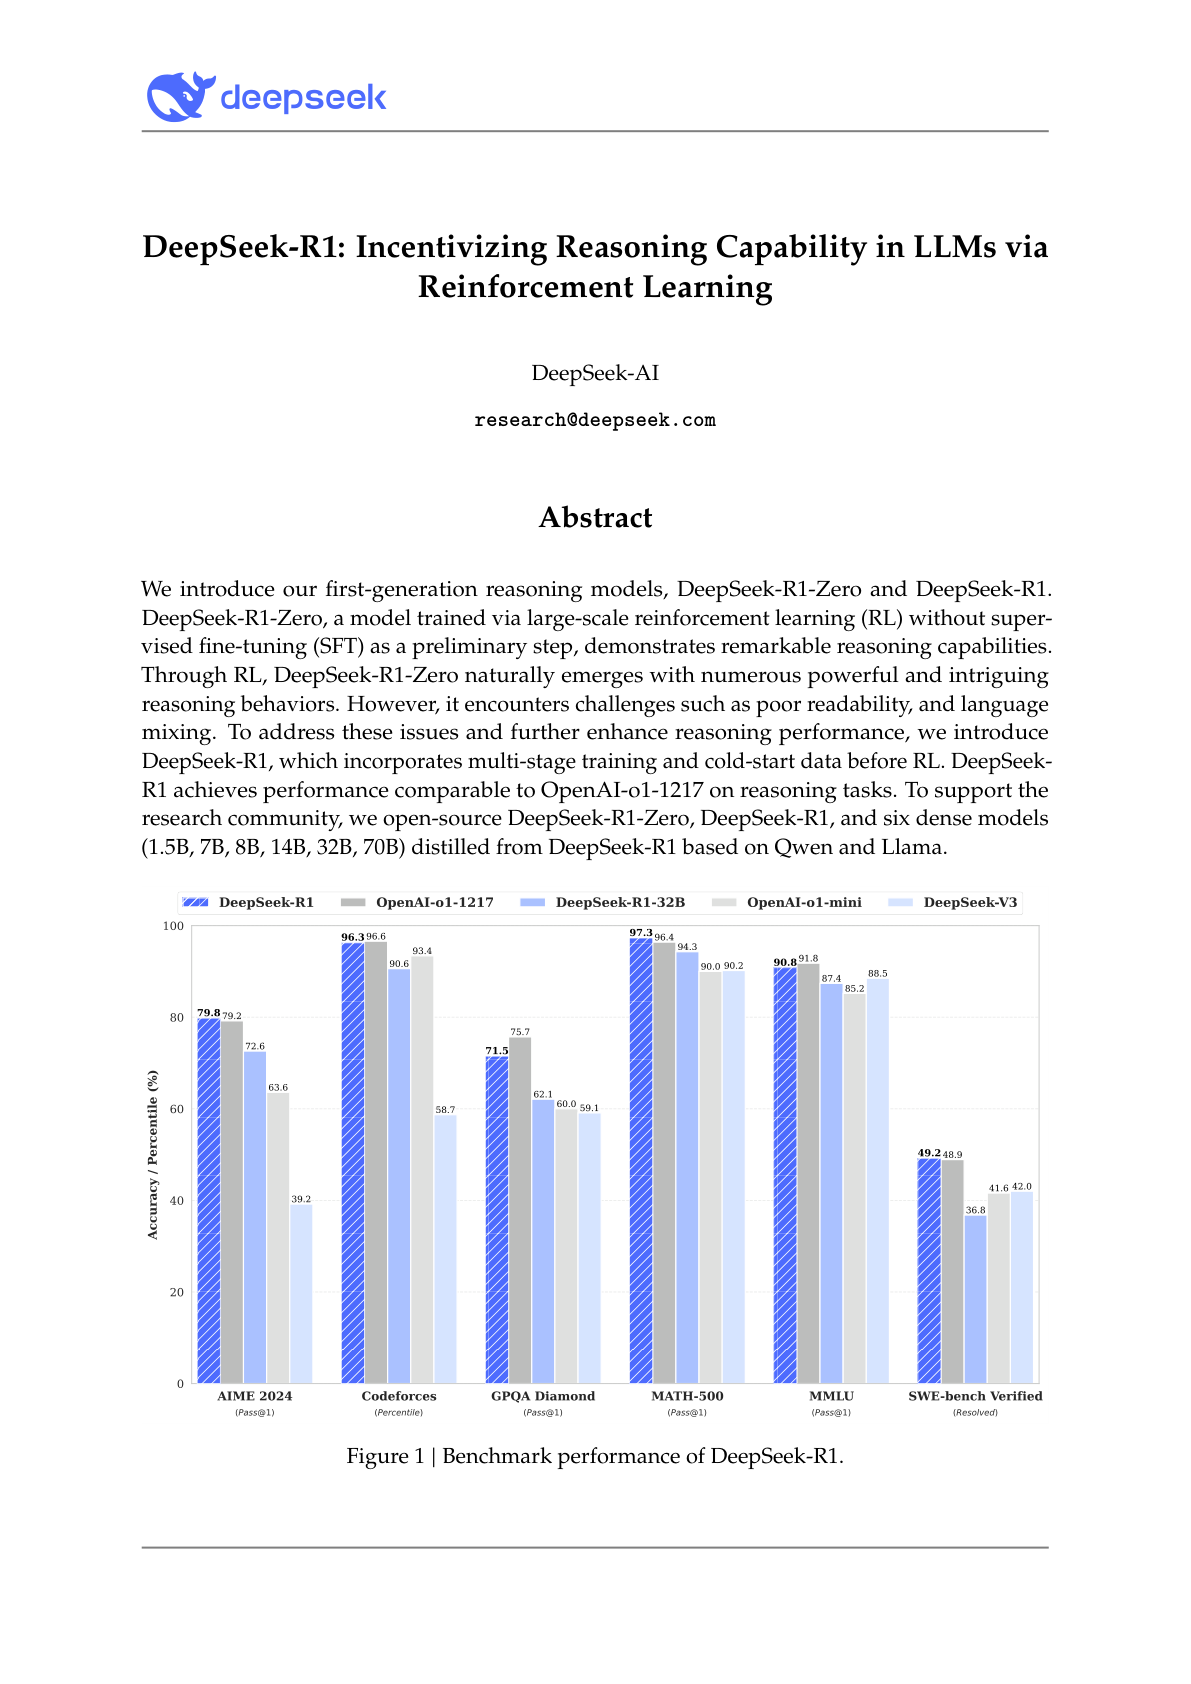
DeepSeek introduces DeepSeek-R1, an advancement in reasoning capabilities achieved through reinforcement learning (RL). It involves two key models: DeepSeek-R1-Zero, which uses pure RL without supervised fine-tuning, and DeepSeek-R1, which combines RL with cold-start data. DeepSeek-R1-Zero demonstrates that models can develop sophisticated reasoning abilities through RL alone, achieving a 71.0% pass rate on AIME 2024 and matching OpenAI-o1-0912's performance. During training, it naturally evolved complex behaviors like self-verification and reflection. However, it faced challenges with readability and language mixing. To address these limitations, DeepSeek-R1 uses a multi-stage approach: initial fine-tuning with high-quality chain-of-thought examples, reasoning-focused RL training, collecting new training data through rejection sampling, and final RL optimization across all scenarios. This resulted in performance comparable to OpenAI-o1-1217, with 79.8% accuracy on AIME 2024 and 97.3% on MATH-500, while maintaining output readability and consistency. DeepSeek also successfully distilled DeepSeek-R1's capabilities into smaller models, with their 7B model outperforming larger competitors and their 32B model achieving results close to OpenAI-o1-mini. This demonstrates the effectiveness of distilling reasoning patterns from larger models rather than training smaller models directly through RL.