Scaling RL with LLMs
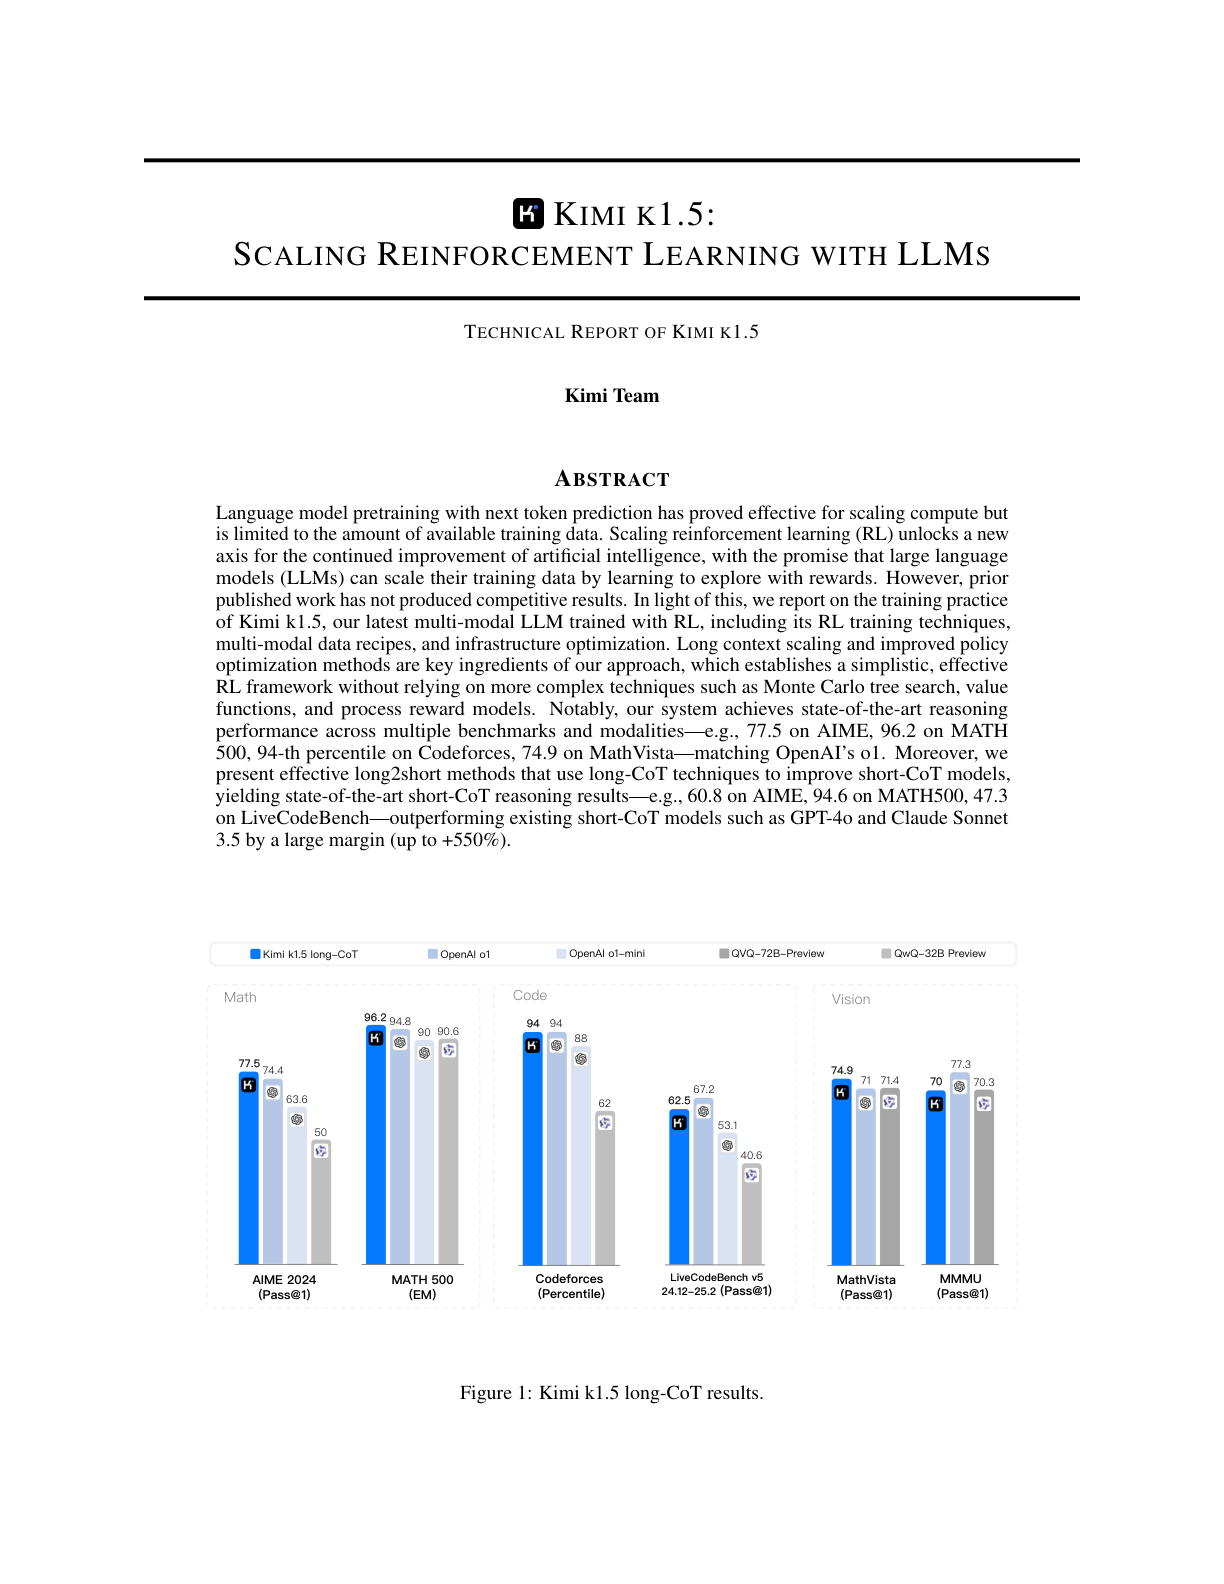
Kimi introduces k1.5, a multimodal LLMtrained using RL that achieves state-of-the-art performance across reasoning tasks. The model leverages long context scaling up to 128k tokens and improved policy optimization methods, establishing a simplified yet effective RL framework without complex techniques like Monte Carlo tree search or value functions. Notably, k1.5 matches OpenAI's o1 performance on various benchmarks including 77.5 on AIME and 96.2 on MATH 500. The model also introduces effective long2short methods that use long-chain-of-thought techniques to improve shorter models, achieving superior results in constrained settings. Using these techniques, k1.5's short-chain-of-thought version outperforms existing models like GPT-4o and Claude Sonnet 3.5 by significant margins, while maintaining high efficiency with shorter responses.