DeepSeek-V2
First page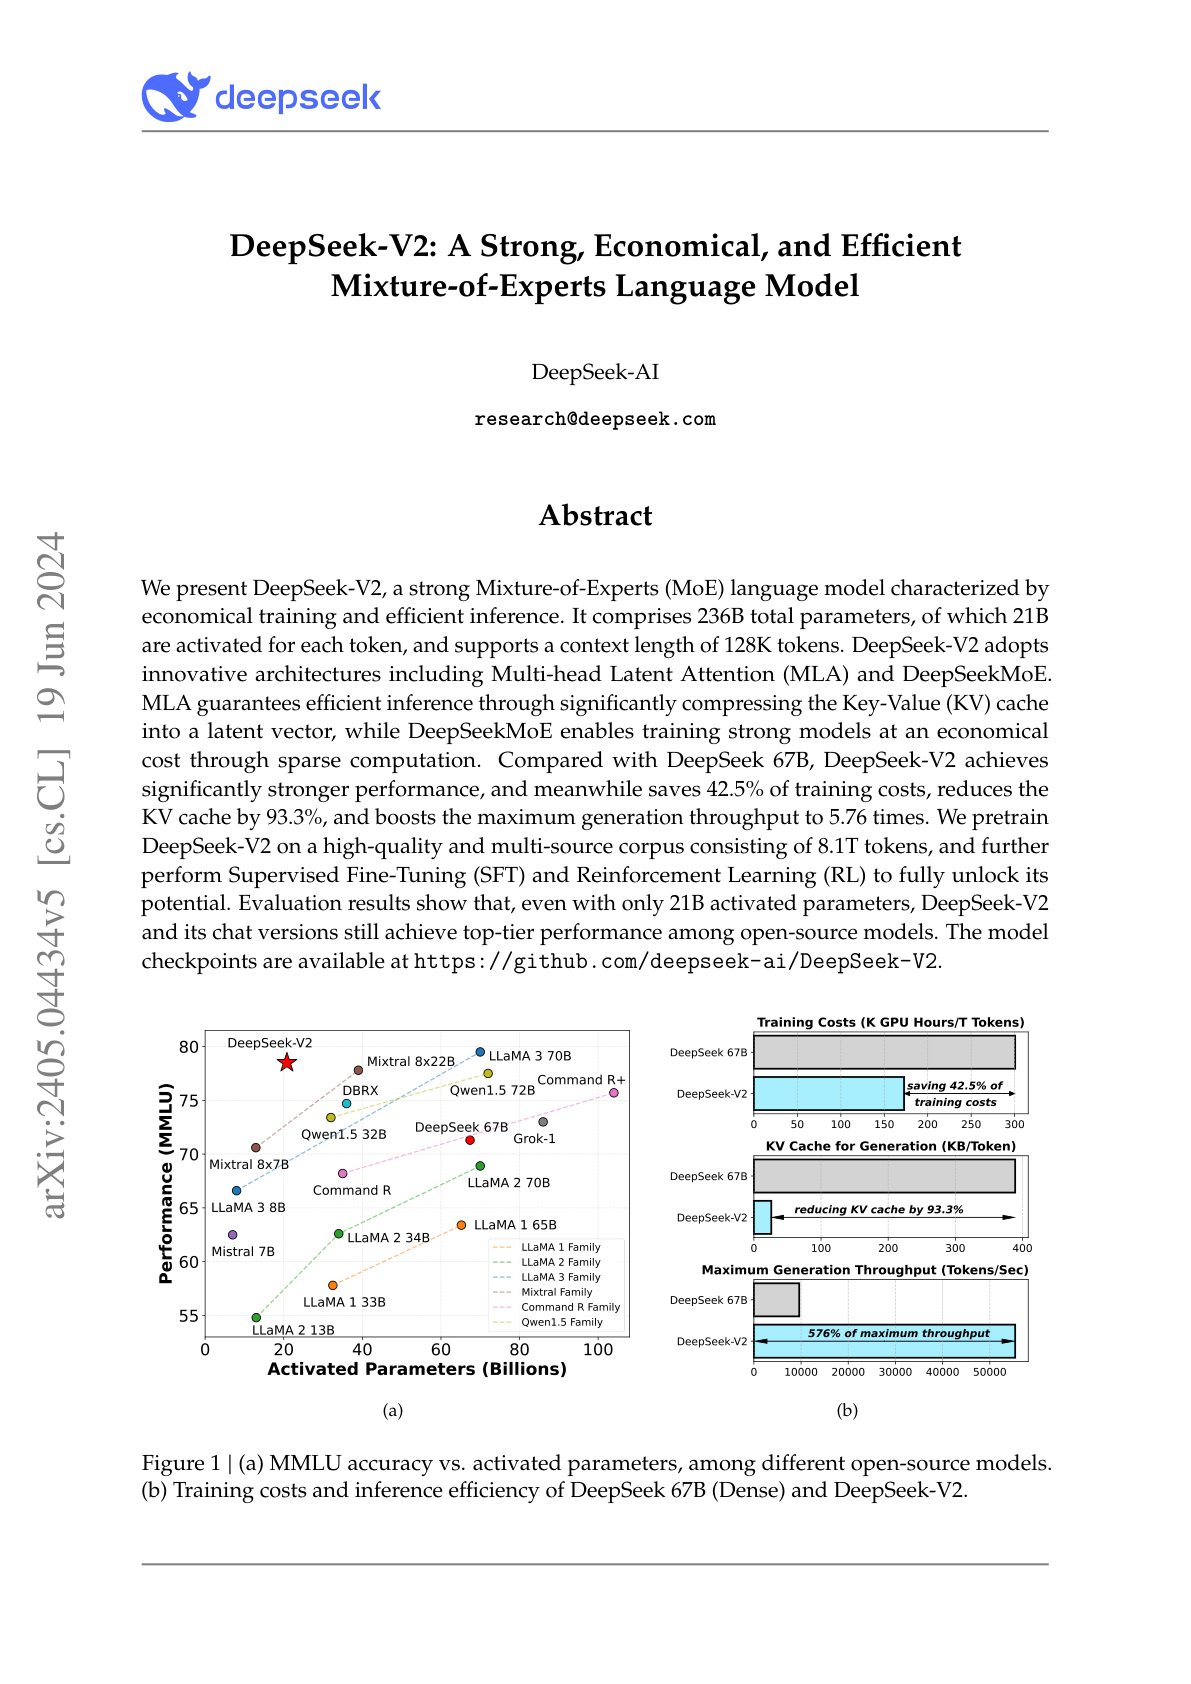
Paper summary
a strong MoE model comprising 236B parameters, of which 21B are activated for each token; supports a context length of 128K tokens and uses Multi-head Latent Attention (MLA) for efficient inference by compressing the Key-Value (KV) cache into a latent vector; DeepSeek-V2 and its chat versions achieve top-tier performance among open-source models.