FlashAttention-3
First page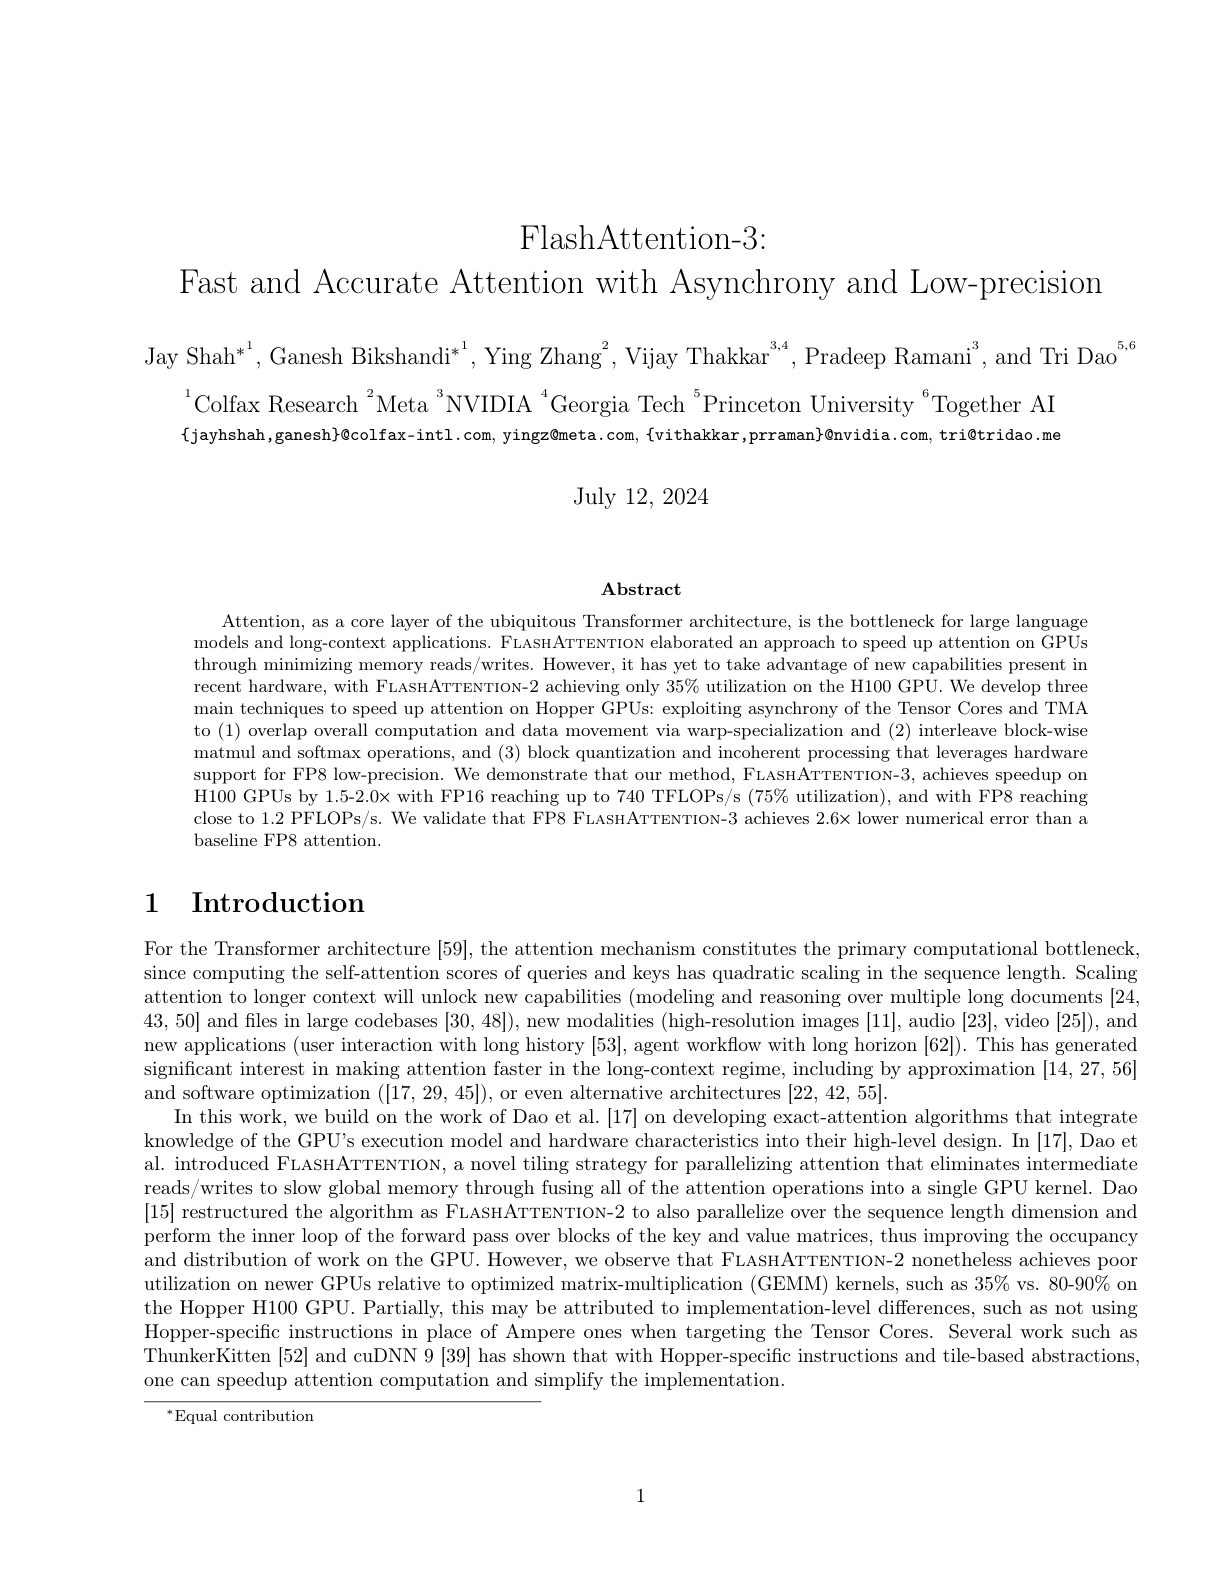
Paper summary
proposes to adapt FlashAttention to take advantage of modern hardware; the techniques used to speed up attention on modern GPUs include producer-consumer asynchrony, interleaving block-wise matmul and softmax operations, and block quantization and incoherent processing; achieves speedup on H100 GPUs by 1.5-2.0x with FP16 reaching up to 740 TFLOPs/s (75% utilization), and with FP8 reaching close to 1.2 PFLOPs/s.