ImageBind
First page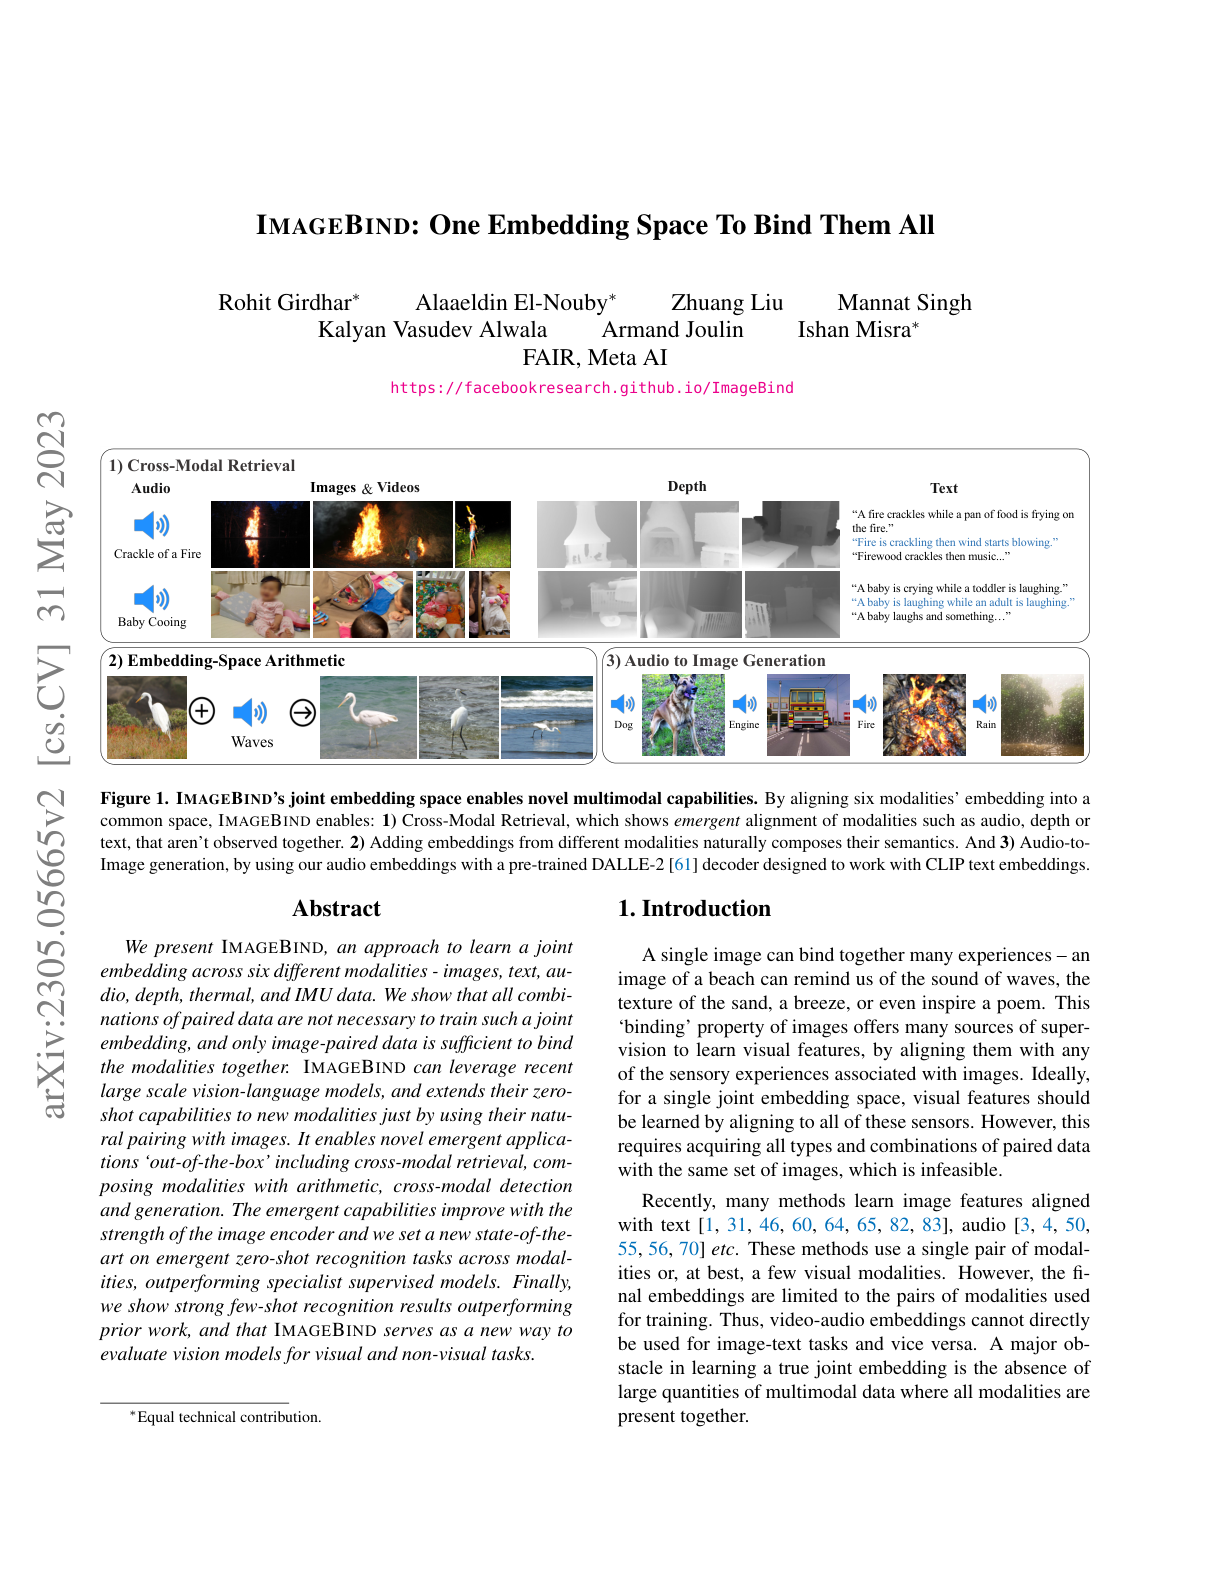
Paper summary
Meta's joint embedding across six modalities at once.
Ask this paper
01
Six-modality embedding: Learns a joint embedding space across images, text, audio, depth, thermal, and IMU data.
02
Implicit binding via images: Images are the "central" modality that binds others - without requiring all-pairs training data.
03
Zero-shot emergent capabilities: Enables cross-modal retrieval, arithmetic composition of modalities, and cross-modal generation/detection.
04
Multi-modal foundation: Influenced 2024's unified multimodal models (Chameleon, GPT-4o) by showing the viability of unified embedding spaces.