LLaDA-UI: Bringing Block-wise Diffusion to Vision-Language GUI Agents
Zhangxuan Gu and colleagues present LLaDA-UI, a 16.7B-parameter mixture-of-experts GUI agent built on a block-wise diffusion language backbone, and test whether diffusion decoding can support capable multimodal GUI agents.
Ask this paper
Architecture. A native-resolution vision encoder is aligned with the LLaDA2.0-mini-base diffusion backbone, which decodes blocks of tokens in parallel and in arbitrary order.
Training. General multimodal pre-training is followed by GUI-agent supervised fine-tuning on mobile, desktop, web and grounding data.
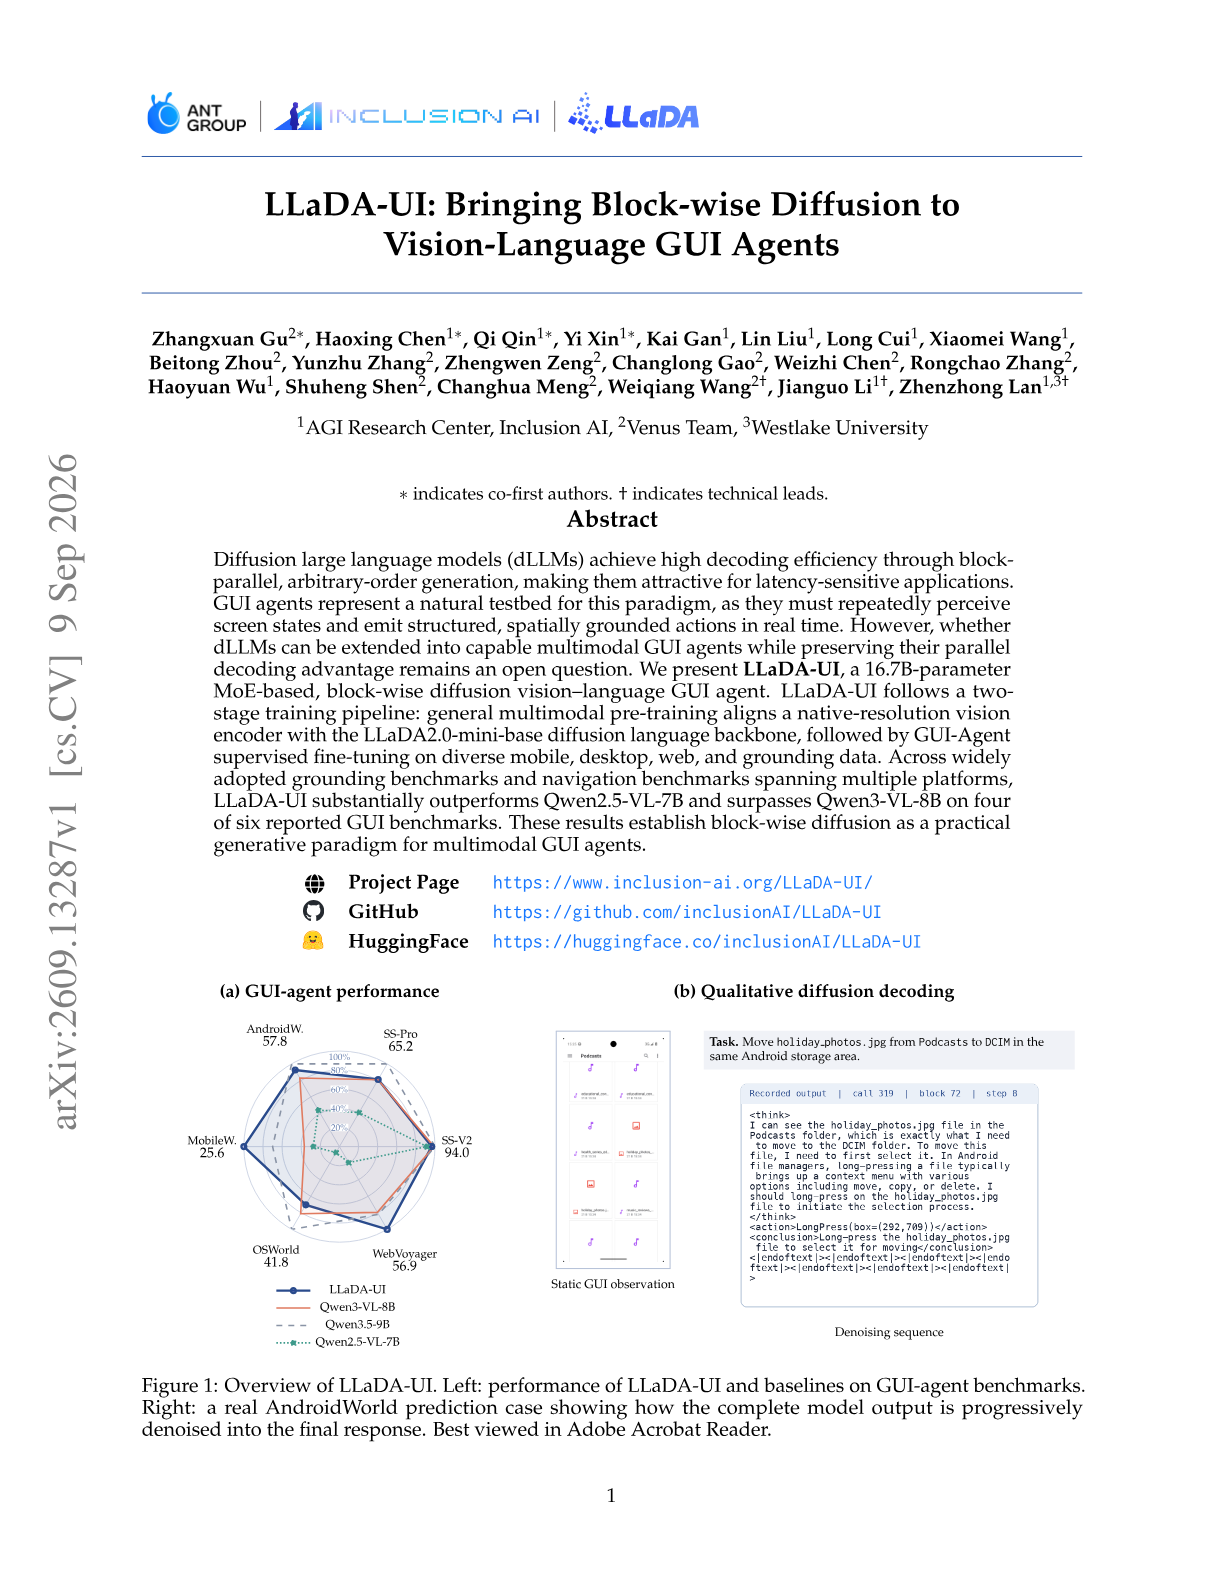
Results. LLaDA-UI outperforms Qwen2.5-VL-7B and surpasses Qwen3-VL-8B on four of six reported GUI grounding and navigation benchmarks.
Why GUI agents. GUI agents repeatedly read screens and emit structured, spatially grounded actions in real time, so they benefit from the lower decoding latency of block-parallel generation.
Abstract
Diffusion large language models (dLLMs) achieve high decoding efficiency through block-parallel, arbitrary-order generation, making them attractive for latency-sensitive applications. GUI agents represent a natural testbed for this paradigm, as they must repeatedly perceive screen states and emit structured, spatially grounded actions in real time. However, whether dLLMs can be extended into capable multimodal GUI agents while preserving their parallel decoding advantage remains an open question. We present LLaDA-UI, a 16.7B-parameter MoE-based, block-wise diffusion vision-language GUI agent. LLaDA-UI follows a two-stage training pipeline: general multimodal pre-training aligns a native-resolution vision encoder with the LLaDA2.0-mini-base diffusion language backbone, followed by GUI-agent supervised fine-tuning on diverse mobile, desktop, web, and grounding data. Across widely adopted grounding benchmarks and navigation benchmarks spanning multiple platforms, LLaDA-UI substantially outperforms Qwen2.5-VL-7B and surpasses Qwen3-VL-8B on four of six reported GUI benchmarks. These results establish block-wise diffusion as a practical generative paradigm for multimodal GUI agents.