Learning Self-Orchestration in Decentralized Agent Swarms
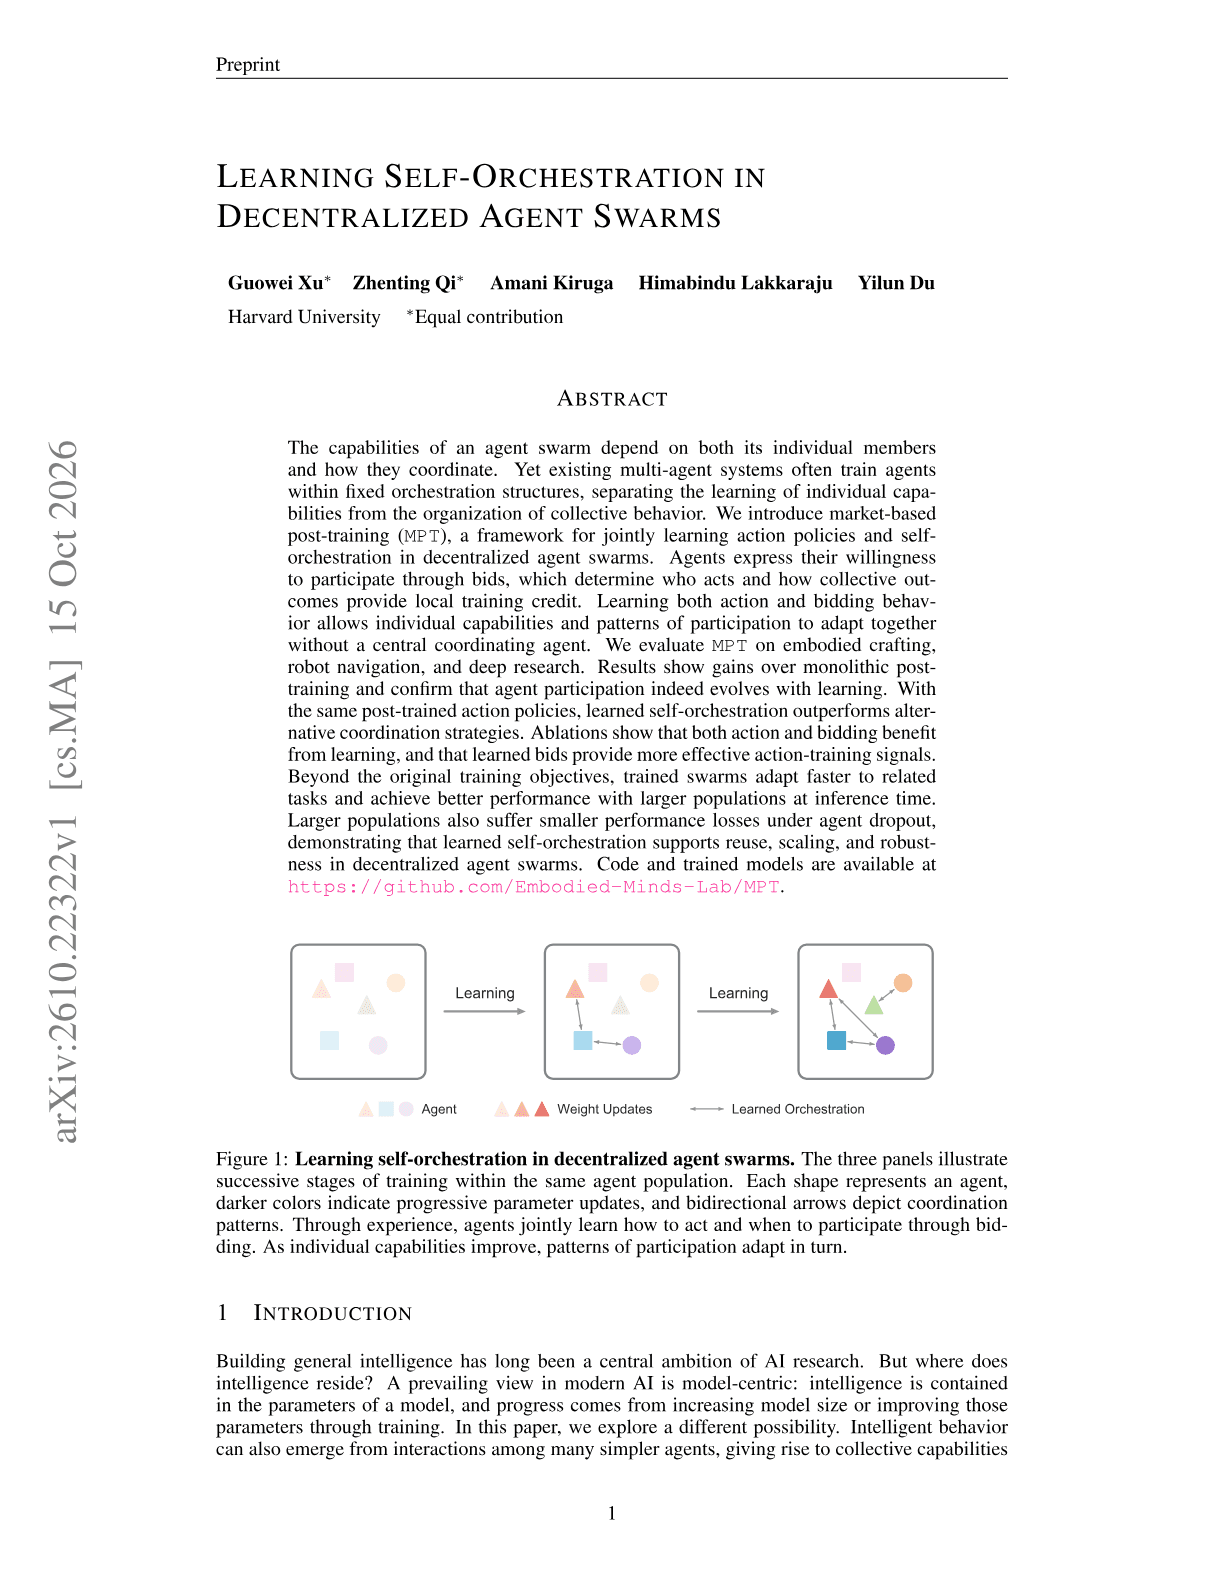
Guowei Xu, Zhenting Qi, Himabindu Lakkaraju, Yilun Du and colleagues at Harvard introduce market-based post-training (MPT), which trains agent action policies and a bidding policy together so a swarm decides who acts without a central coordinator.
Ask this paper
Mechanism. Each agent bids to express its willingness to act. Bids decide who acts and how the collective outcome is turned into local training credit.
Joint learning. Action policies and bidding behavior are trained together, so individual skills and participation patterns change together.
Domains. Evaluated on embodied crafting, robot navigation and deep research, MPT beats monolithic post-training.
Ablations. With the same action policies, learned self-orchestration beats alternative coordination schemes. Both action and bidding benefit from learning, and learned bids give better action-training signal.
Scaling and robustness. Trained swarms adapt faster to related tasks, improve with larger populations at inference, and lose less performance when agents drop out.
Abstract
The capabilities of an agent swarm depend on both its individual members and how they coordinate. Yet existing multi-agent systems often train agents within fixed orchestration structures, separating the learning of individual capabilities from the organization of collective behavior. We introduce market-based post-training (MPT), a framework for jointly learning action policies and self-orchestration in decentralized agent swarms. Agents express their willingness to participate through bids, which determine who acts and how collective outcomes provide local training credit. Learning both action and bidding behavior allows individual capabilities and patterns of participation to adapt together without a central coordinating agent. We evaluate MPT on embodied crafting, robot navigation, and deep research. Results show gains over monolithic post-training and confirm that agent participation indeed evolves with learning. With the same post-trained action policies, learned self-orchestration outperforms alternative coordination strategies. Ablations show that both action and bidding benefit from learning, and that learned bids provide more effective action-training signals. Beyond the original training objectives, trained swarms adapt faster to related tasks and achieve better performance with larger populations at inference time. Larger populations also suffer smaller performance losses under agent dropout, demonstrating that learned self-orchestration supports reuse, scaling, and robustness in decentralized agent swarms. Code and trained models are available at https://github.com/Embodied-Minds-Lab/MPT.