LEASH: Uncertainty-Aware Weak-to-Strong Escalation and Oversight for Computer-Use Agents
Qingni Wang, Changdae Oh, Yuzhe Yang, Sharon Li and colleagues (University of Wisconsin-Madison and Simular) let a small open-weight computer-use agent act by default and hand control to a frontier model only when the small model's hidden states resemble its past failures.
Ask this paper
Uncertainty from activations. The weak model's hidden states are compared with those from past successful and failed trajectories. The estimator reuses activations already produced during action generation, so it needs no extra forward pass and no trained monitor.
Three layers. Initial task uncertainty for early routing, step-level uncertainty for escalation at runtime, and a shadow observer that keeps monitoring the black-box strong agent after handoff.
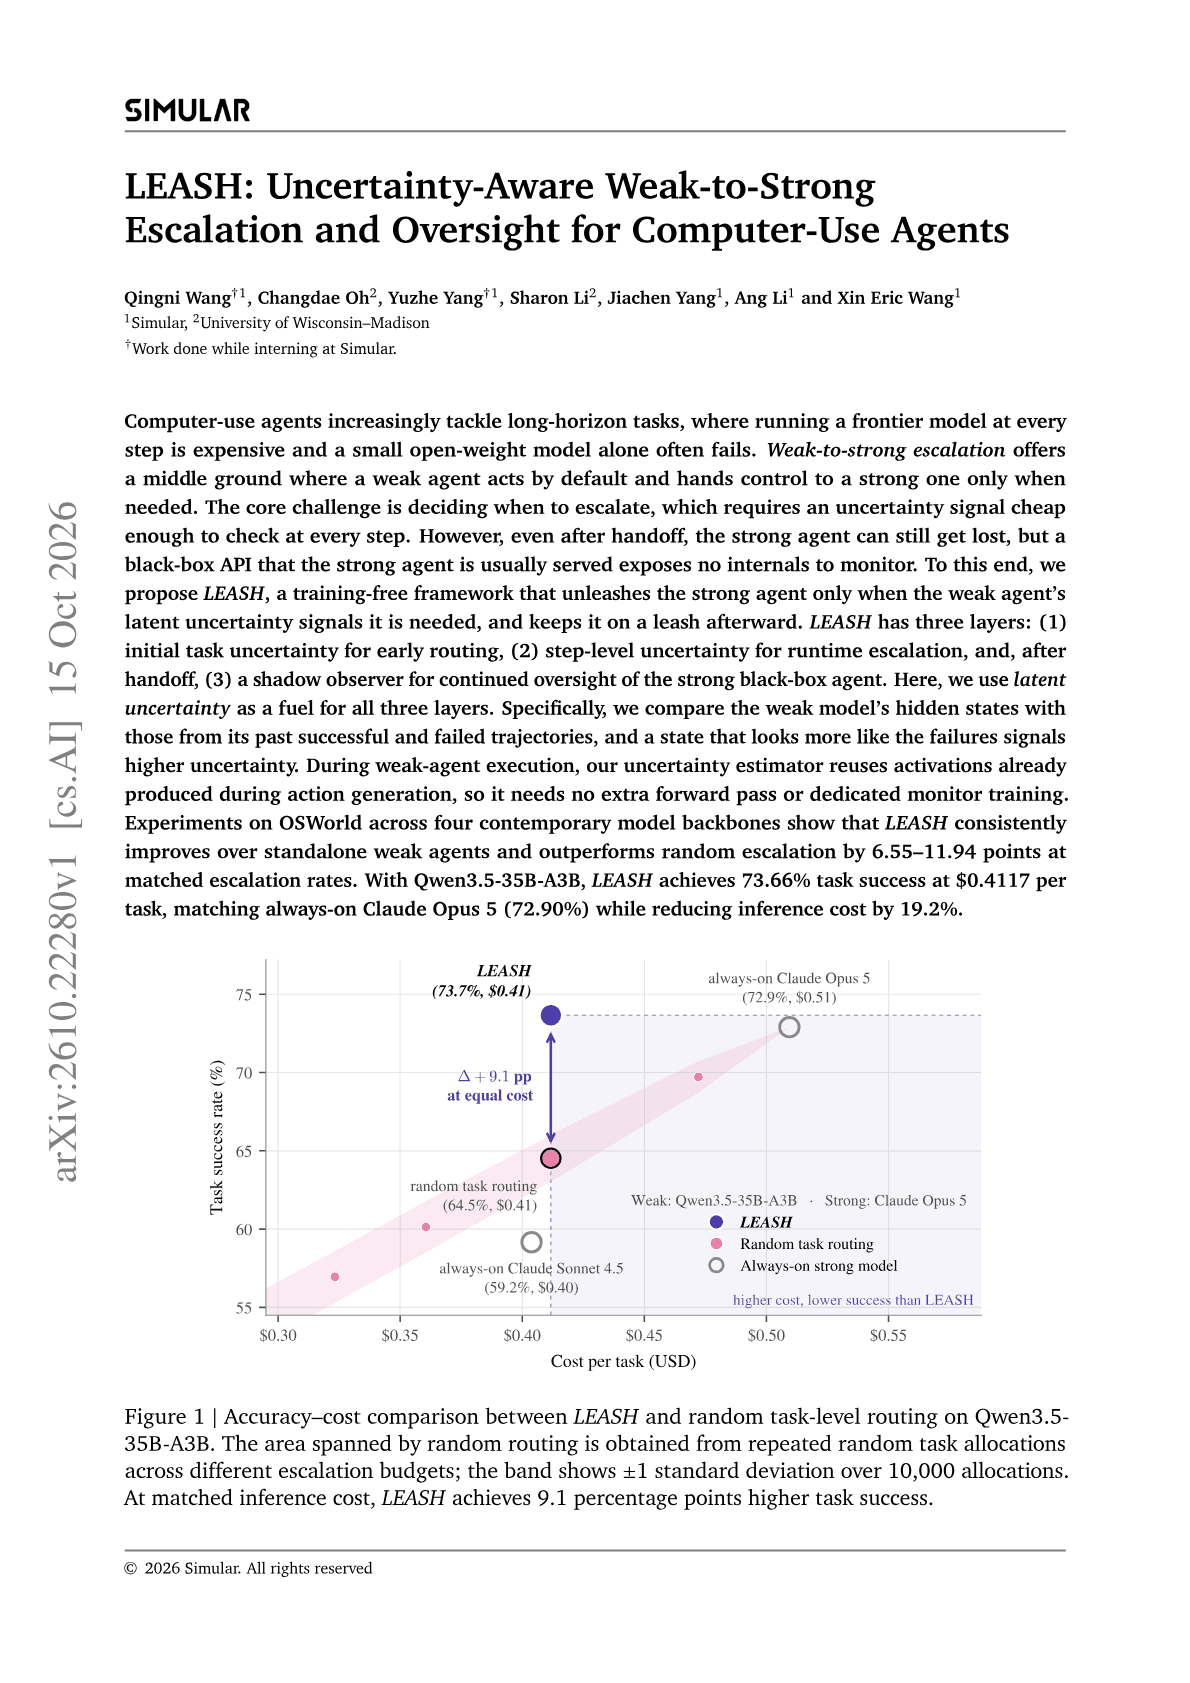
Results. On OSWorld across four backbones, LEASH beats random escalation by 6.55 to 11.94 points at matched escalation rates.
Cost. With Qwen3.5-35B-A3B as the weak agent it reaches 73.66% success at $0.41 per task, matching always-on Claude Opus 5 (72.90%) at 19.2% lower inference cost.
Abstract
Computer-use agents increasingly tackle long-horizon tasks, where running a frontier model at every step is expensive and a small open-weight model alone often fails. Weak-to-strong escalation offers a middle ground where a weak agent acts by default and hands control to a strong one only when needed. The core challenge is deciding when to escalate, which requires an uncertainty signal cheap enough to check at every step. However, even after handoff, the strong agent can still get lost, but a black-box API that the strong agent is usually served exposes no internals to monitor. To this end, we propose LEASH, a training-free framework that unleashes the strong agent only when the weak agent's latent uncertainty signals it is needed, and keeps it on a leash afterward. LEASH has three layers: (1) initial task uncertainty for early routing, (2) step-level uncertainty for runtime escalation, and, after handoff, (3) a shadow observer for continued oversight of the strong black-box agent. Here, we use latent uncertainty as a fuel for all three layers. Specifically, we compare the weak model's hidden states with those from its past successful and failed trajectories, and a state that looks more like the failures signals higher uncertainty. During weak-agent execution, our uncertainty estimator reuses activations already produced during action generation, so it needs no extra forward pass or dedicated monitor training. Experiments on OSWorld across four contemporary model backbones show that LEASH consistently improves over standalone weak agents and outperforms random escalation by 6.55--11.94 points at matched escalation rates. With Qwen3.5-35B-A3B, LEASH achieves 73.66% task success at $0.4117 per task, matching always-on Claude Opus 5 (72.90%) while reducing inference cost by 19.2%.