LightThinker
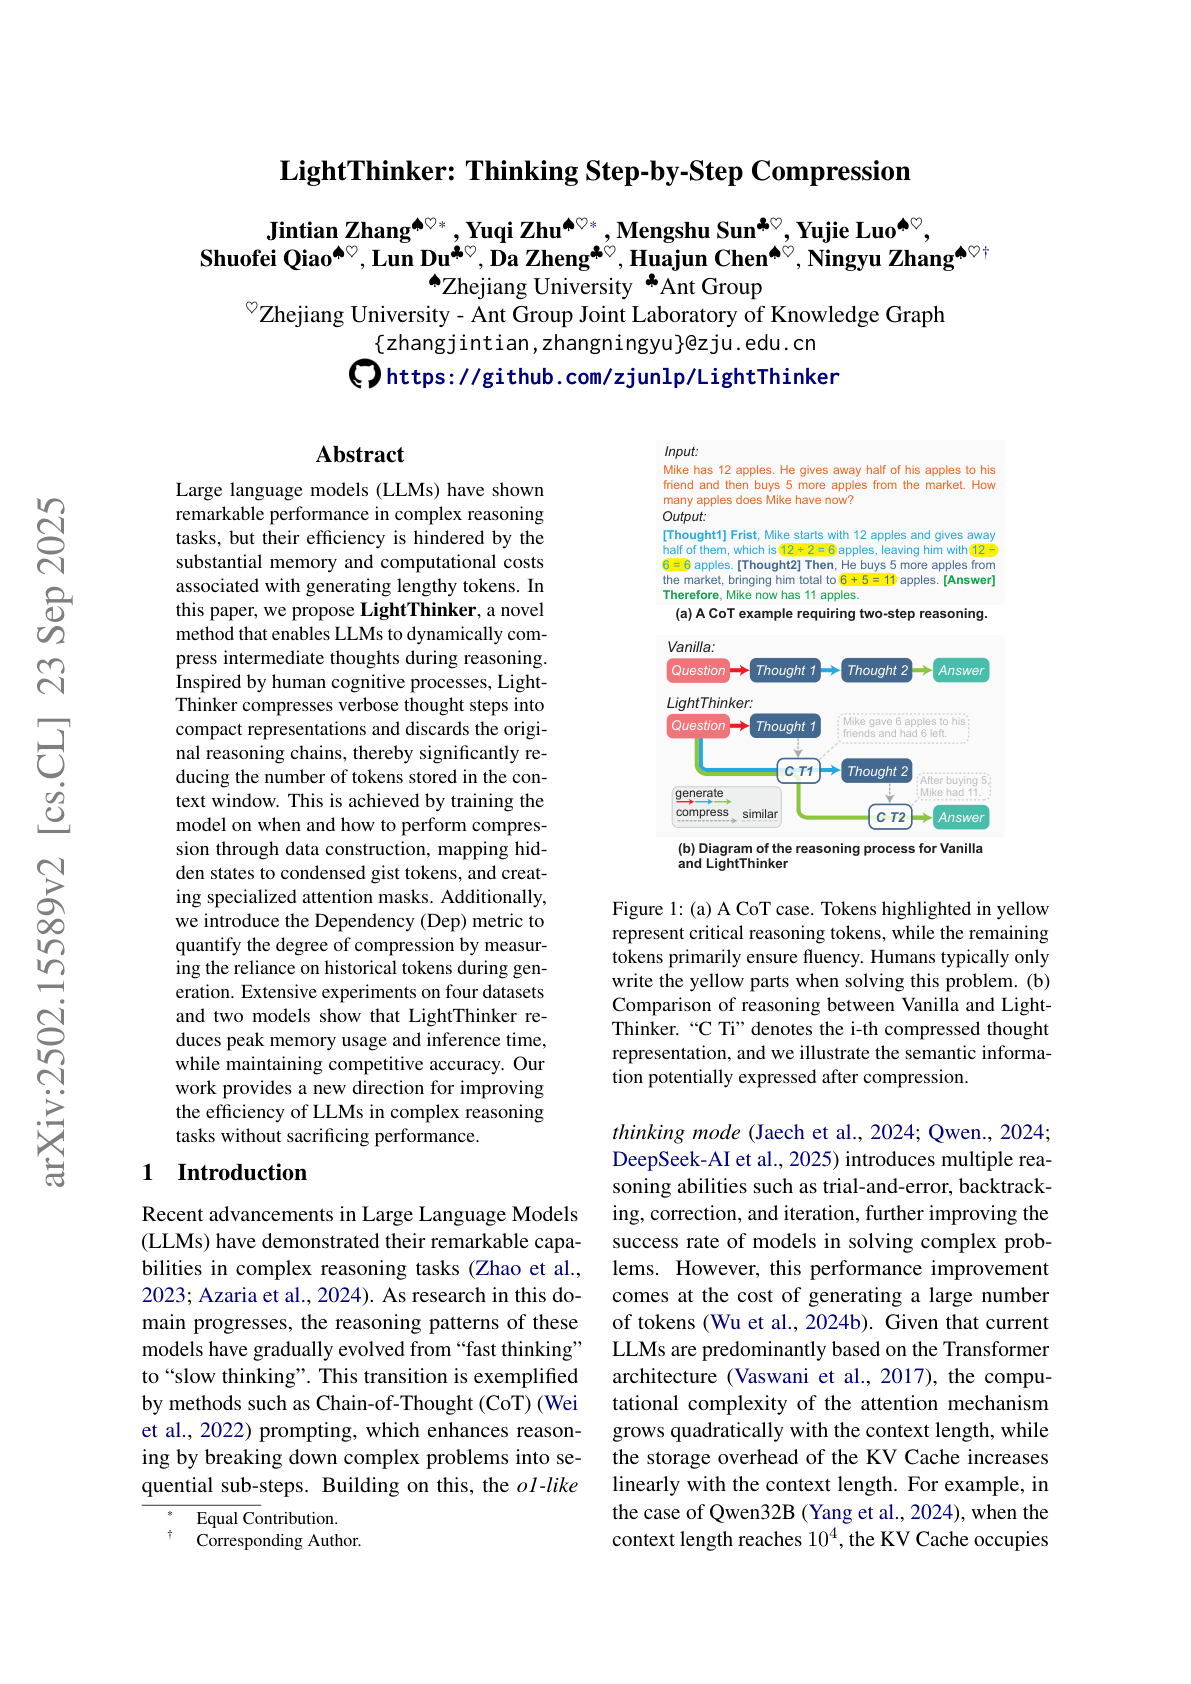
This new paper proposes a novel approach to dynamically compress reasoning steps in LLMs, significantly improving efficiency without sacrificing accuracy. Key insights include:
Ask this paper
Compression of intermediate thoughts – Inspired by human cognition, LightThinker teaches LLMs to summarize and discard verbose reasoning steps, reducing memory footprint and computational cost during inference.
Training LLMs to compress – The method trains models to identify when and how to condense reasoning by mapping hidden states to compact gist tokens and introducing specialized attention masks.
Dependency metric for compression – The paper introduces Dep, a metric that quantifies the reliance on historical tokens during generation. Lower Dep values indicate effective compression with minimal information loss.
Memory & speed improvements – Experiments show that LightThinker reduces peak memory usage by 70% and inference time by 26% while maintaining nearly identical accuracy (within 1% of uncompressed models).
Outperforming baseline approaches – Compared to token-eviction (H2O) and anchor-token (AnLLM) methods, LightThinker achieves higher efficiency with fewer tokens stored and better generalization across reasoning tasks.