LLaMA Pro
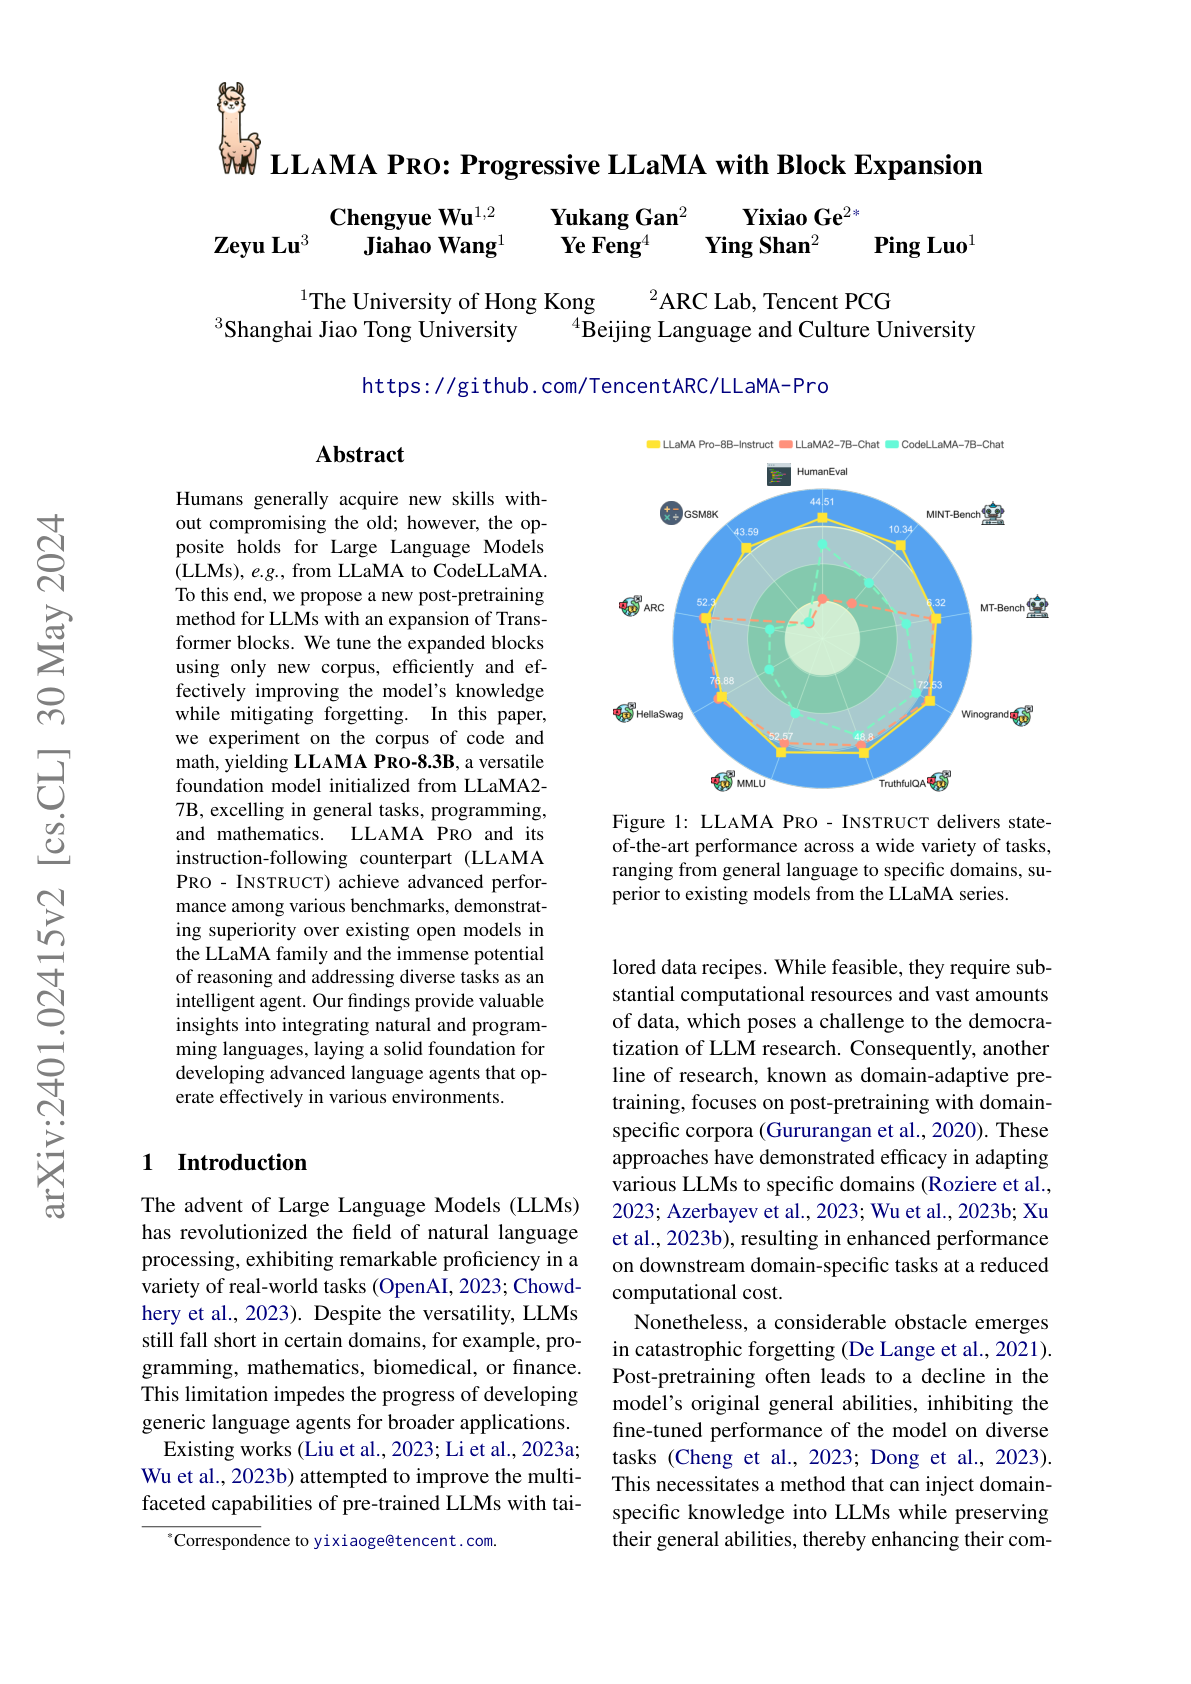
LLaMA Pro introduces block expansion as a recipe for adding new knowledge to a pretrained LLM without catastrophic forgetting.
Ask this paper
Block expansion: Additional identity-initialized transformer blocks are inserted into a frozen base model; only these new blocks are trained on the new corpus while inherited blocks stay frozen.
Math + code training: LLaMA Pro-8.3B is initialized from Llama 2-7B and post-pretrained on a mix of math and code data, yielding a domain-specialized yet general-purpose model.
Preserves general capability: Because inherited blocks stay frozen, the model retains its original general skills - a stark contrast with continual full fine-tuning which typically degrades general performance.
Strong benchmark performance: Matches or beats Llama 2 7B on general benchmarks while significantly outperforming it on math and code tasks, validating the block-expansion recipe.