Mobile ALOHA
Stanford's Mobile ALOHA is a low-cost bimanual mobile-manipulation platform that learns dexterous household tasks via whole-body teleoperation and behavior cloning.
Mitigating Hallucination in LLMs
A survey cataloging 32 hallucination-mitigation techniques and organizing them into a practical taxonomy.
Self-Play Fine-Tuning (SPIN)
SPIN shows that a supervised fine-tuned LLM can keep improving via self-play alone, without any additional human annotations.
LLaMA Pro
LLaMA Pro introduces block expansion as a recipe for adding new knowledge to a pretrained LLM without catastrophic forgetting.
LLM Augmented LLMs (CALM)
Google's CALM composes a large anchor LLM with smaller specialist models via learned cross-attention, unlocking new capabilities without retraining either model.
Fast Inference of Mixture-of-Experts
Achieves practical Mixtral-8x7B inference on consumer hardware through MoE-aware quantization and offloading.
SeeAct (GPT-4V as Generalist Web Agent)
OSU researchers adapt GPT-4V into SeeAct, a generalist agent that operates live websites using vision + language planning.
DocLLM
JPMorgan's DocLLM is a lightweight extension to LLMs for visual-document understanding that uses bounding-box spatial information rather than image pixels.
How Code Empowers LLMs
A survey on why training LLMs with code data produces capabilities well beyond coding itself.
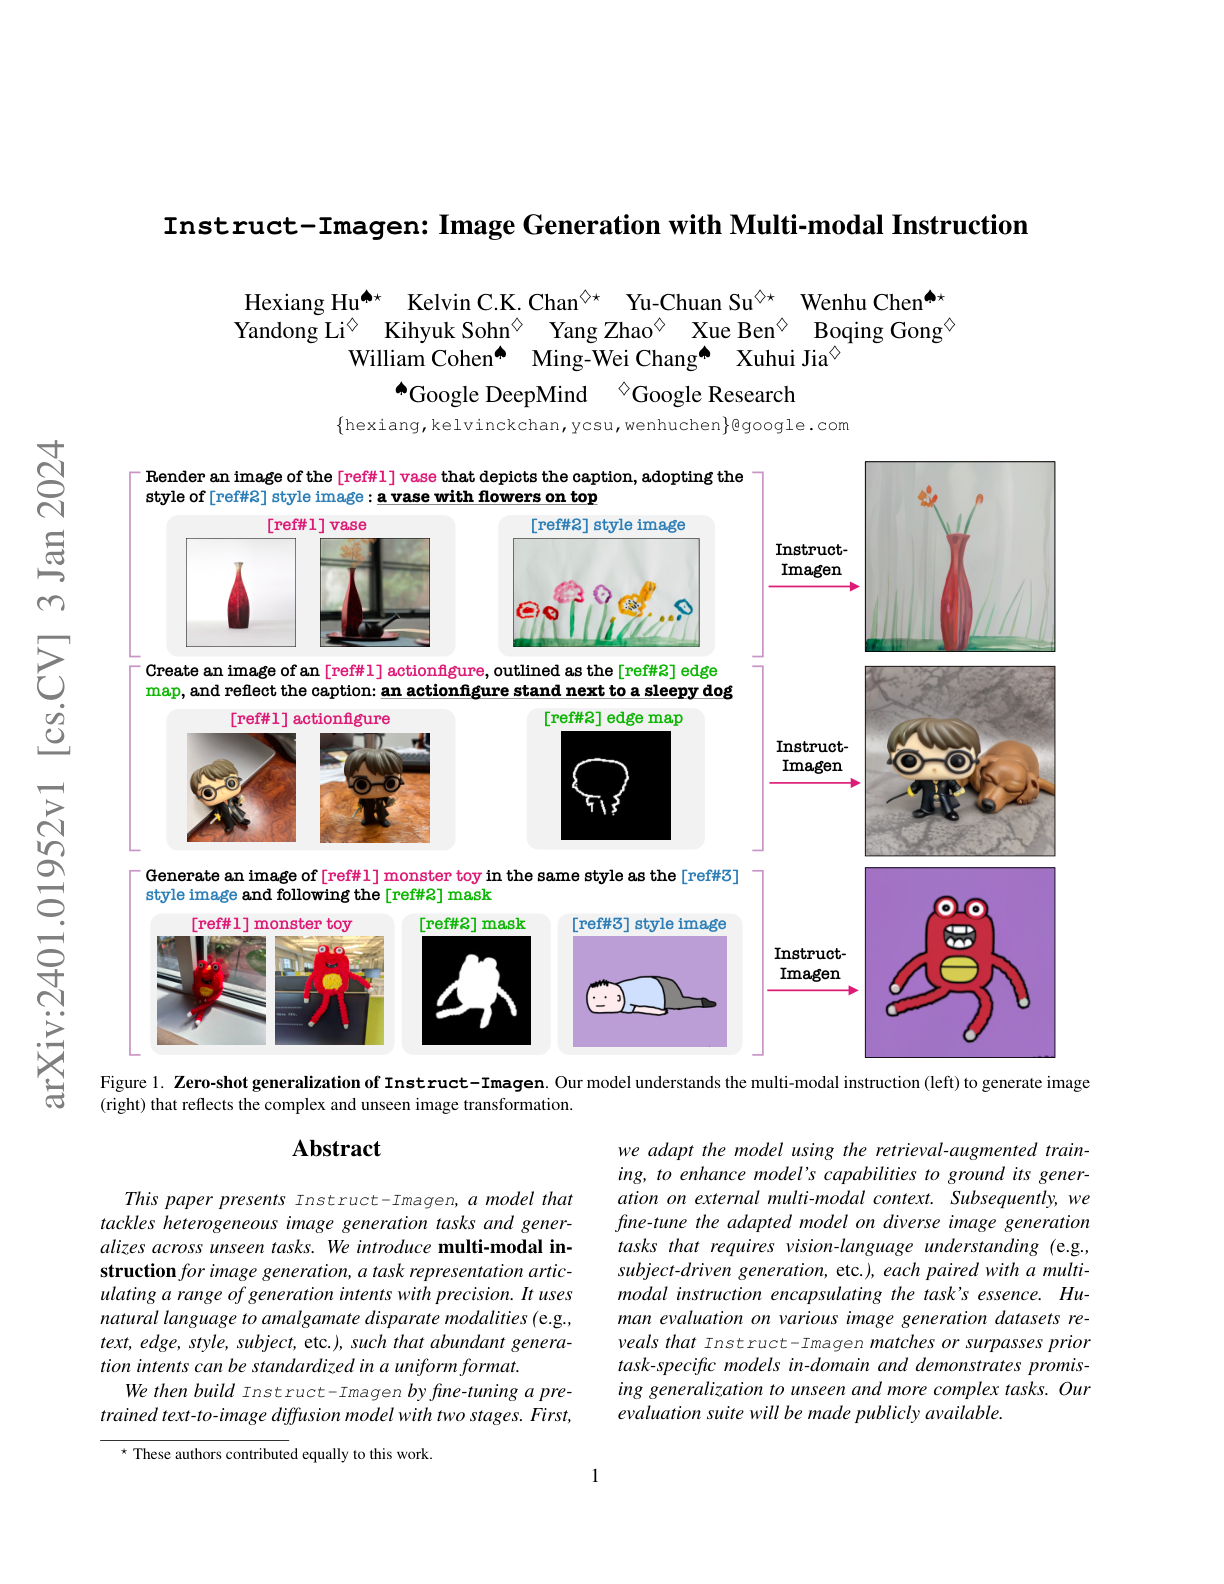
Instruct-Imagen
Google's Instruct-Imagen is a multimodal instruction-tuned image generation model that generalizes across heterogeneous generation tasks, including unseen ones.