MEMENTO: Learning Context Management for Long Context Processing Agents
Yunfan Zhang, Kathleen McKeown, Smaranda Muresan and colleagues at Columbia University present MEMENTO, a Qwen3-8B agent trained to manage a fixed context window by writing compaction notes, which processes books of up to 2.5M tokens while never holding more than 20K tokens.
Ask this paper
Problem. Off-the-shelf agentic models, including GPT-5.5 and GLM-5.3, write ineffective compaction notes, and RL alone rarely discovers good note-taking.
Training. SFT on synthetic trajectories with notes written in hindsight starts the behavior. RL with a reward that combines answer correctness, note-quality heuristics and confidence calibration makes it reliable.
Results. On four book-level QA benchmarks, MEMENTO raises Qwen3-8B from 36.9% to 67.8%. It beats a GPT-5.5 agent in the same harness (13.1%) and full-book context (56.7%) at less than 1/50 of the cost, and nearly matches a GLM-5.3 agent about 100x larger (69.3%) at 1/9 of the cost.
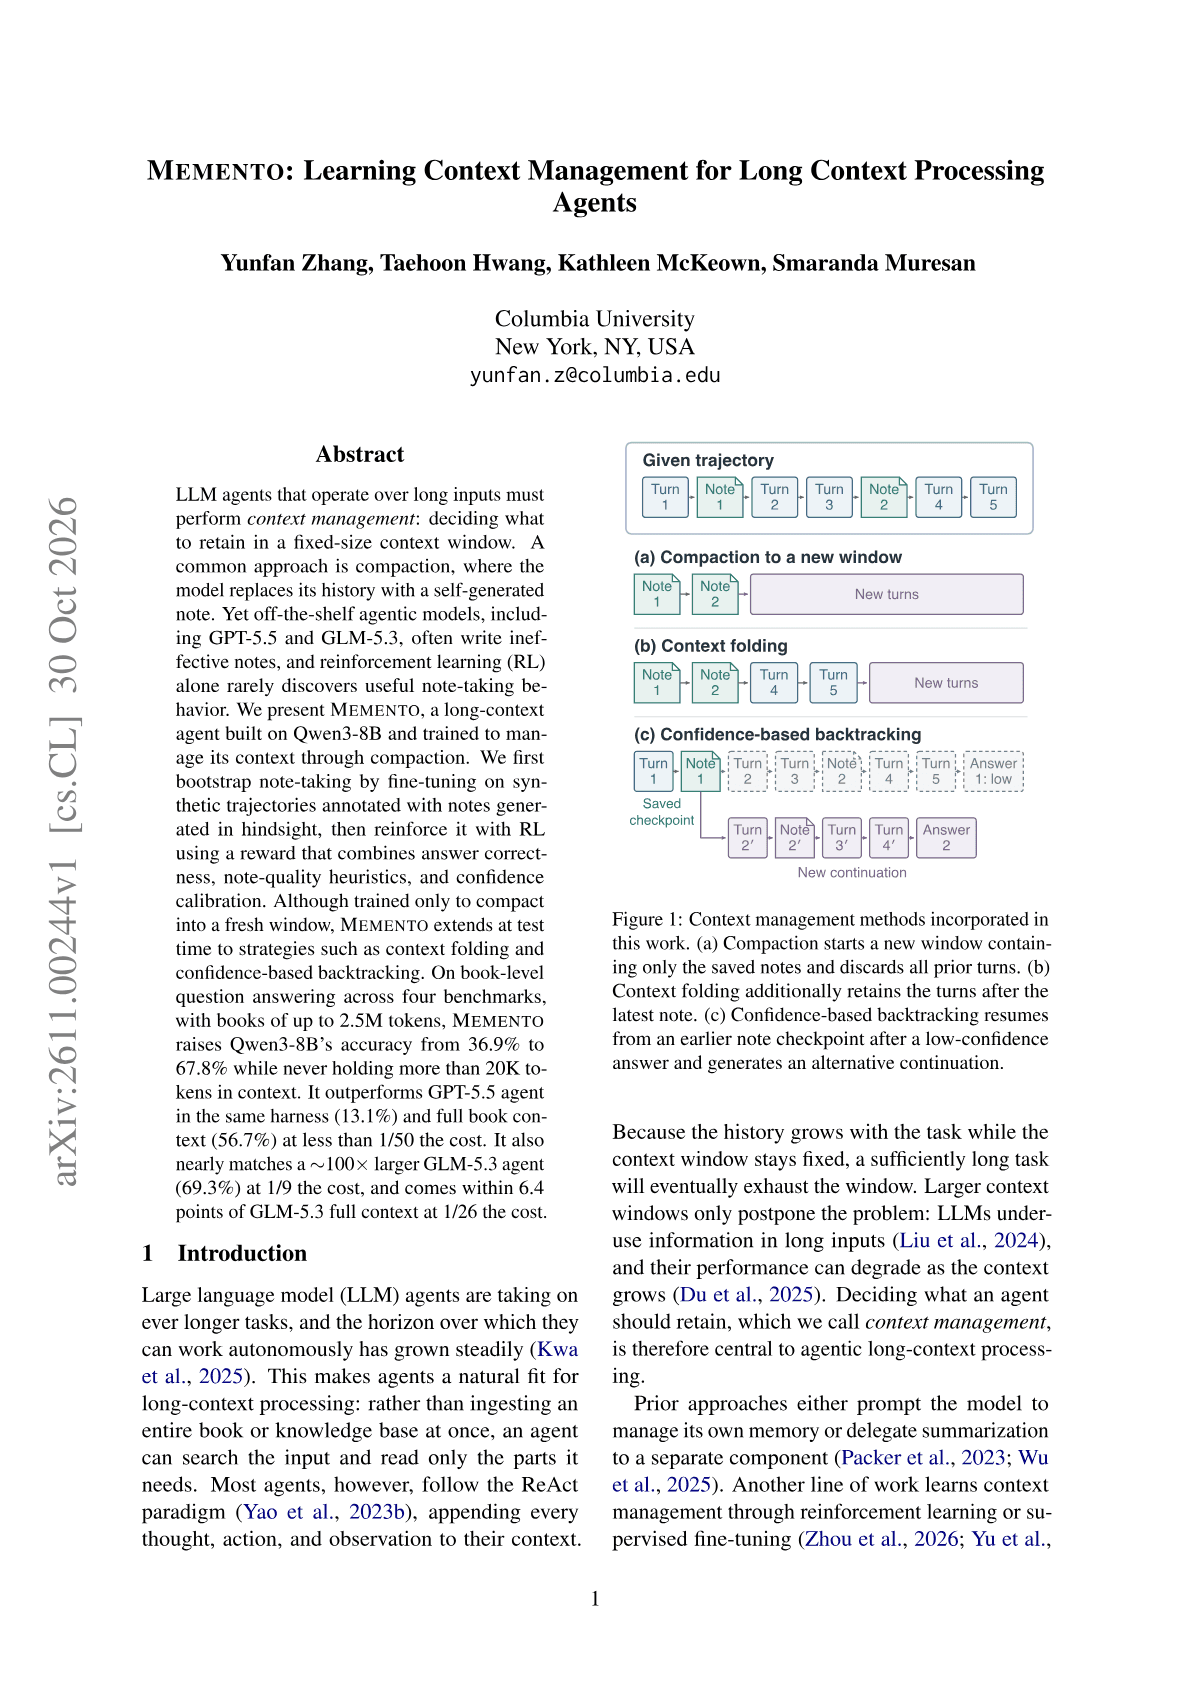
Transfer. Although trained only to compact into a fresh window, the policy also works with context folding and confidence-based backtracking at test time.
Limits. Evaluation covers English book QA only. Late in training the model flags only 30 to 40% of its wrong answers as low confidence, so backtracking adds only 1.0 point.
Abstract
LLM agents that operate over long inputs must perform context management: deciding what to retain in a fixed-size context window. A common approach is compaction, where the model replaces its history with a self-generated note. Yet off-the-shelf agentic models, including GPT-5.5 and GLM-5.3, often write ineffective notes, and reinforcement learning (RL) alone rarely discovers useful note-taking behavior. We present MEMENTO, a long-context agent built on Qwen3-8B and trained to manage its context through compaction. We first bootstrap note-taking by fine-tuning on synthetic trajectories annotated with notes generated in hindsight, then reinforce it with RL using a reward that combines answer correctness, note-quality heuristics, and confidence calibration. Although trained only to compact into a fresh window, MEMENTO extends at test time to strategies such as context folding and confidence-based backtracking. On book-level question answering across four benchmarks, with books of up to 2.5M tokens, MEMENTO raises Qwen3-8B's accuracy from 36.9% to 67.8% while never holding more than 20K tokens in context. It outperforms GPT-5.5 agent in the same harness (13.1%) and full book context (56.7%) at less than 1/50 the cost. It also nearly matches a ~100x larger GLM-5.3 agent (69.3%) at 1/9 the cost, and comes within 6.4 points of GLM-5.3 full context at 1/26 the cost.