Memorization in LLMs
First page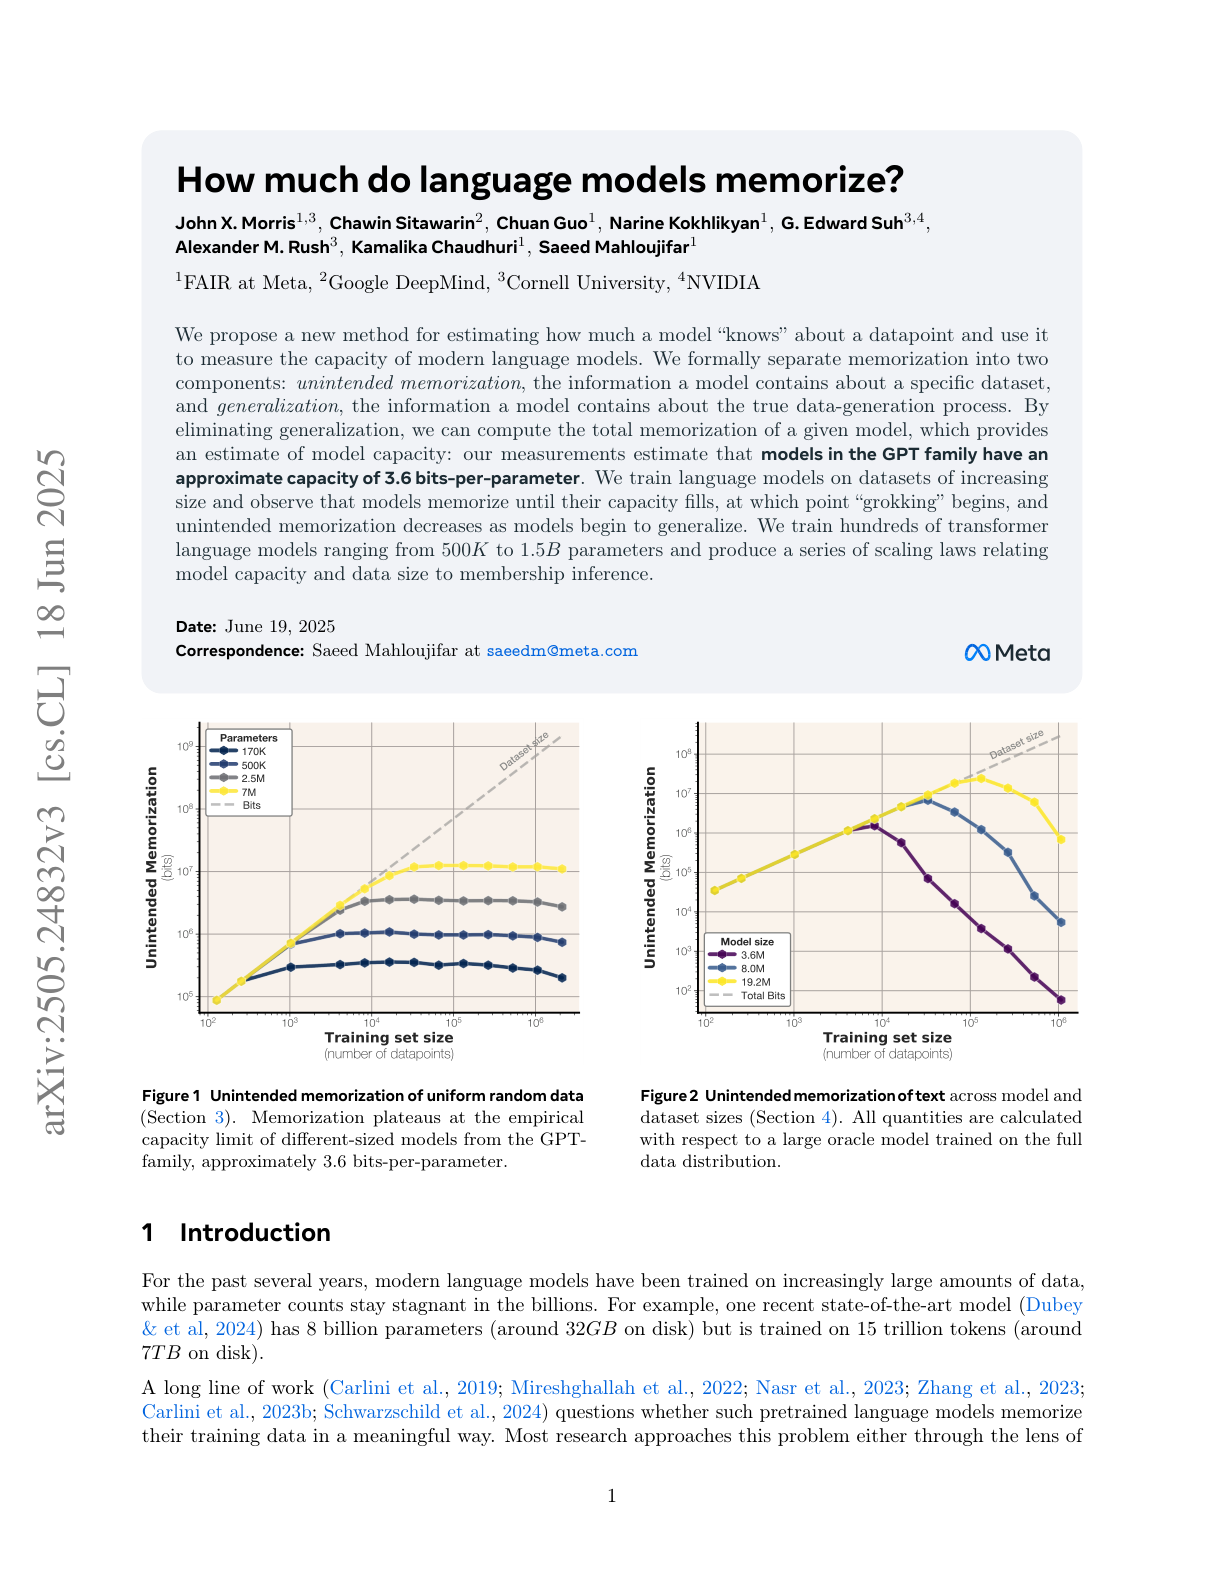
Paper summary
This study introduces a method to quantify how much a model memorizes versus generalizes, estimating GPT models have a capacity of ~3.6 bits per parameter. By training hundreds of models, the authors show that memorization saturates with data before generalization (“grokking”) kicks in, and derive new scaling laws linking capacity, data size, and membership inference.