Meta-Transformer
First page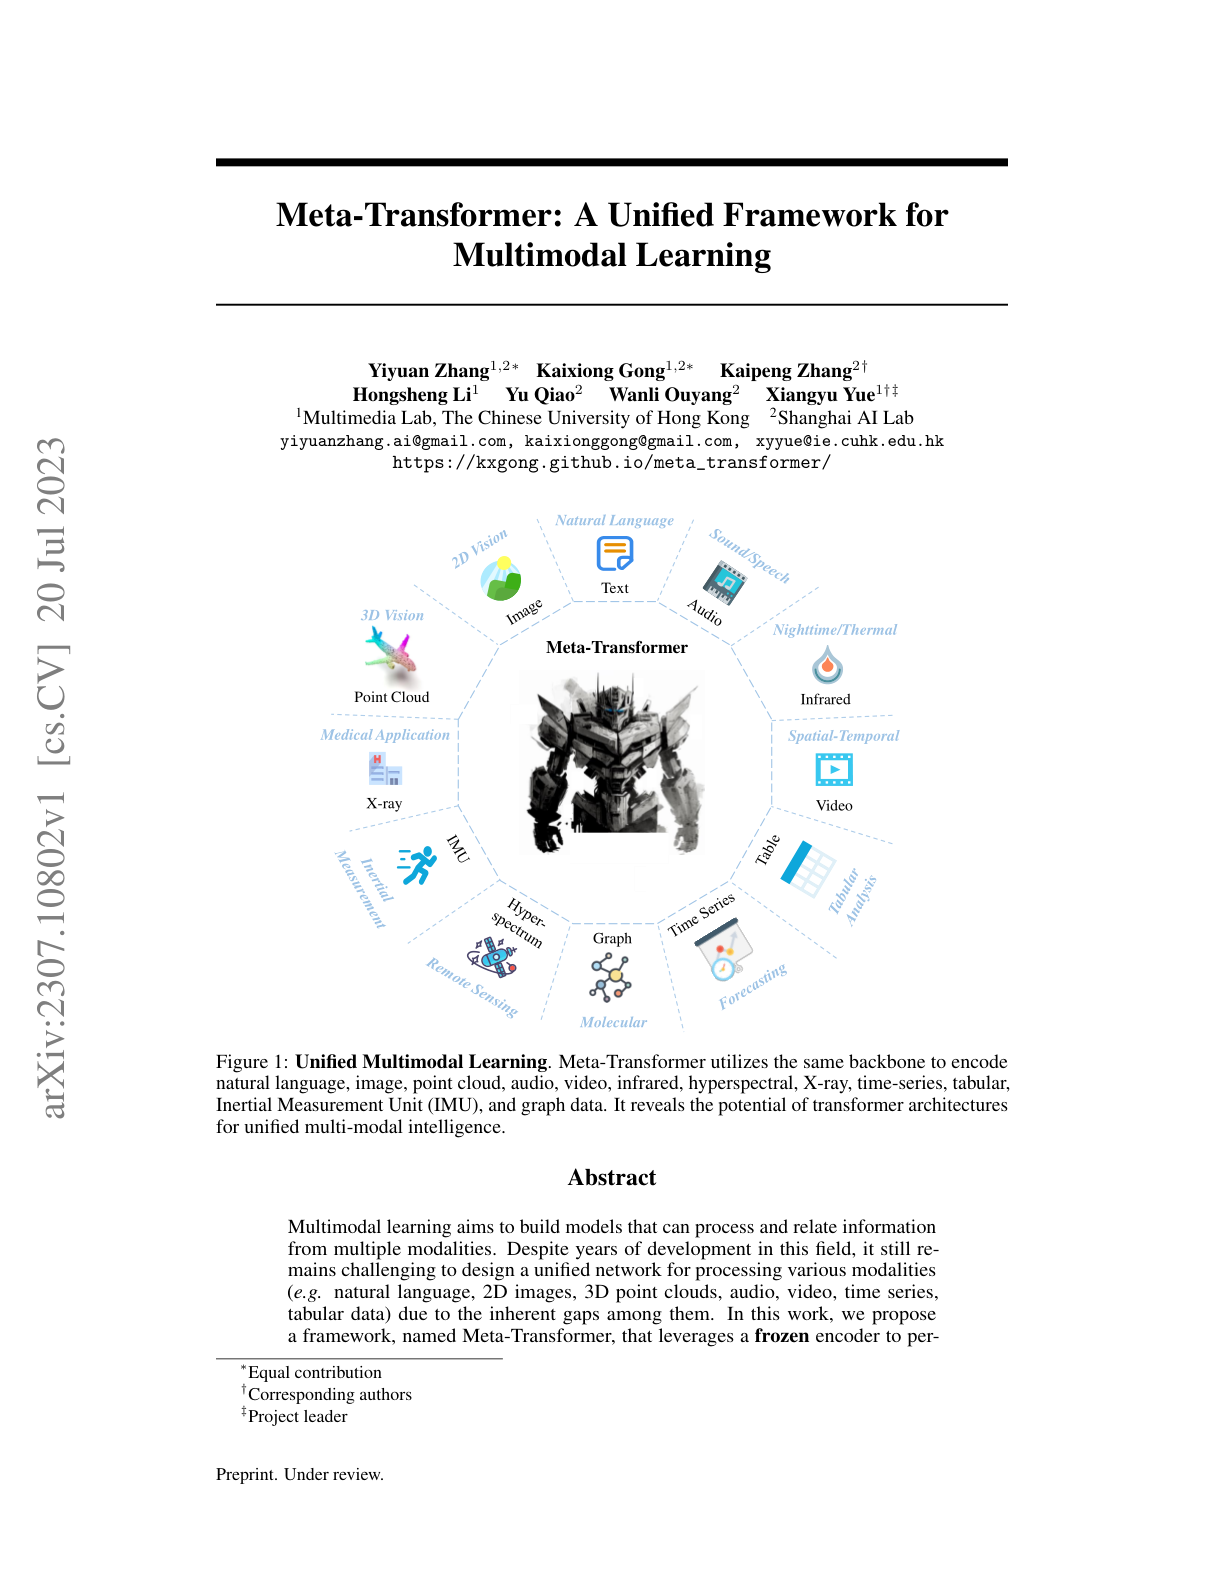
Paper summary
A unified framework performing learning across 12 different modalities with a shared backbone.
Ask this paper
01
12-modality coverage: Handles text, image, point cloud, audio, video, X-Ray, infrared, hyperspectral, IMU, graph, tabular, and time-series data.
02
Frozen encoder design: Uses a frozen modality-agnostic encoder paired with modality-specific tokenizers and lightweight task heads.
03
Extreme generality: Demonstrates that a single backbone can serve both fundamental perception and practical applications like medical imaging and industrial sensing.
04
Universal encoder direction: Points toward future architectures where a single foundation model serves as the universal encoder for any modality.