MiniMax-01
First page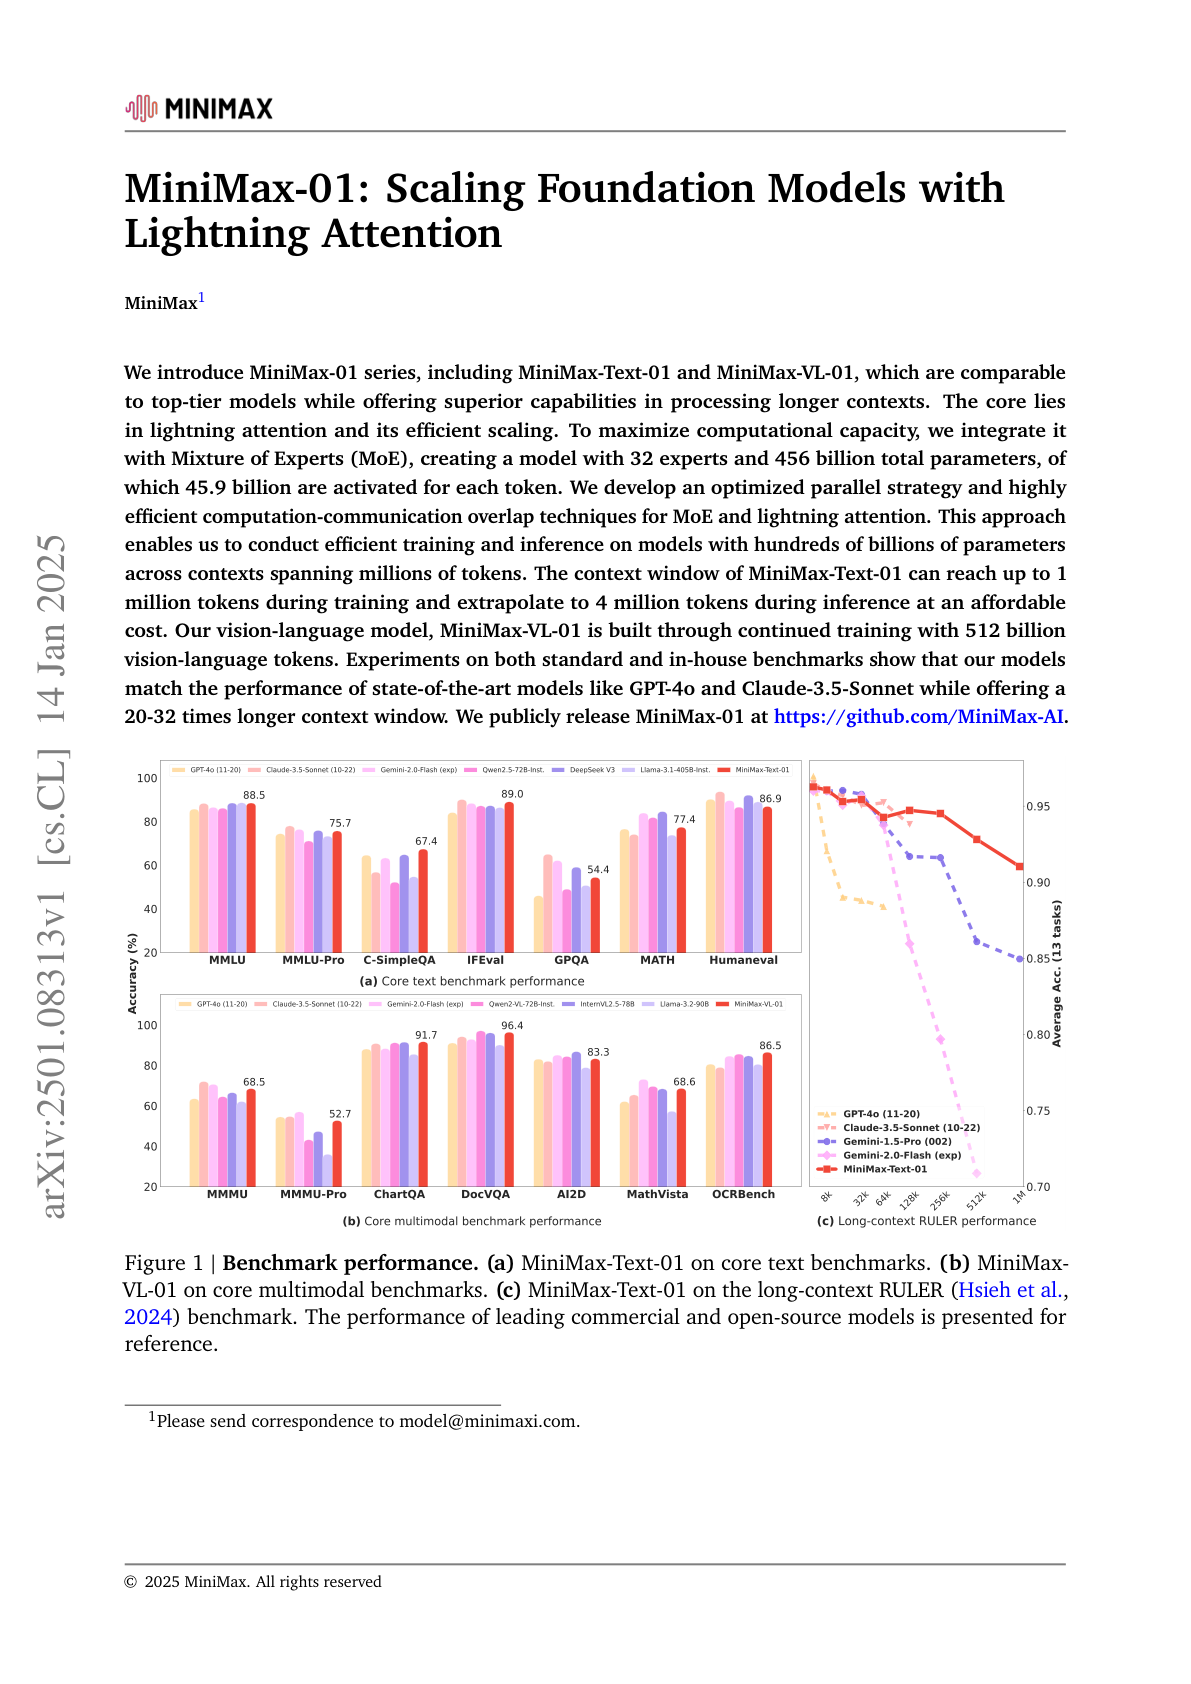
Paper summary
introduces a new series of models that integrate Mixture-of-Experts; introduces a model with 32 experts and 456B parameters, and 45.9B are activated for each token; claims match the performance of state-of-the-art models like GPT-4o and Claude-3.5-Sonnet while offering a 20-32x longer context window; it can handle context windows of up to 4 million tokens; it integrates linear attention with optimized hardware utilization which enhances the efficiency and scalability of the LLM; there is also a vision model called MiniMax-VL-01 built through continued training with 512 billion vision-language tokens.