VideoRAG
First page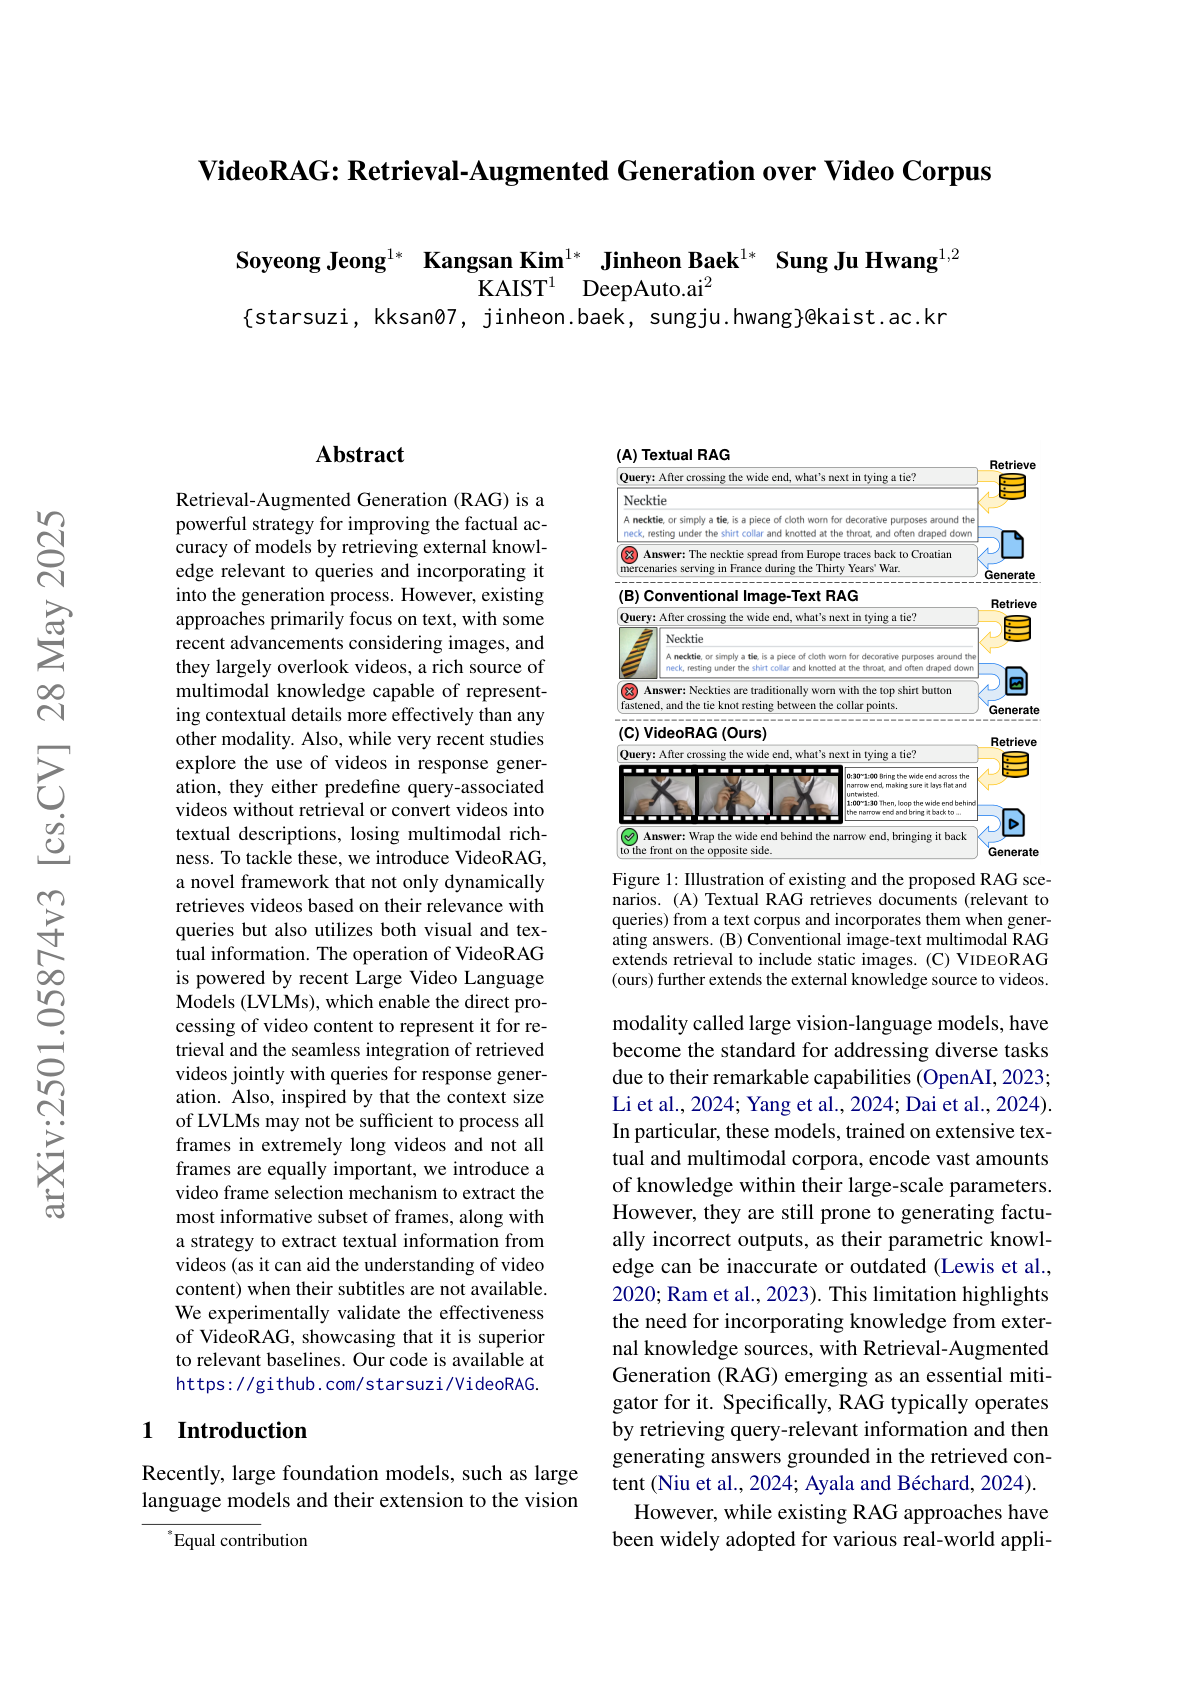
Paper summary
a framework that enhances RAG by leveraging video content as an external knowledge source; unlike existing RAG approaches that primarily focus on text or images, VideoRAG dynamically retrieves relevant videos based on queries and incorporates both their visual and textual elements into the generation process; the framework utilizes Large Video Language Models (LVLMs) to process video content directly, enabling more effective capture of temporal dynamics, spatial details, and multimodal cues that static modalities often fail to convey; for videos lacking textual descriptions, they propose using automatic speech recognition to generate transcripts, ensuring both visual and textual modalities can be leveraged.