Mixtral 8x22B
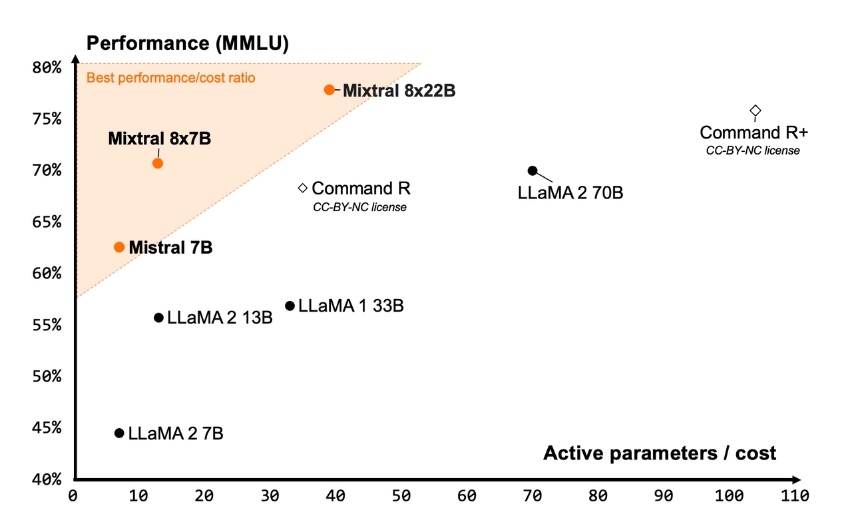
Mistral's Mixtral 8x22B is a sparse Mixture-of-Experts model with 141B total / 39B active parameters and a 64K context window, released under Apache 2.0. It leads open models on MMLU and posts strong math, code, and multilingual numbers.
Ask this paper
Sparse MoE setup: 8 experts with 2 active per token yields 39B active parameters out of 141B total, giving Llama-2-70B-class quality at roughly half the inference cost.
Multilingual and tooling: Fluent across English, French, Italian, German, and Spanish, with native function calling built in - a practical unlock for agent and tool-use pipelines.
Benchmark results: Best-in-class among open models on MMLU; 90.8% on GSM8K (maj@8), 44.6% on MATH (maj@4), and state-of-the-art HumanEval pass@1 among contemporary open-weight models.
License and openness: Apache 2.0 with weights freely available, explicitly framed by Mistral as promoting innovation and unrestricted deployment.