MLE-World: Predicting Machine Learning Experiment Outcomes with a Learned World Model
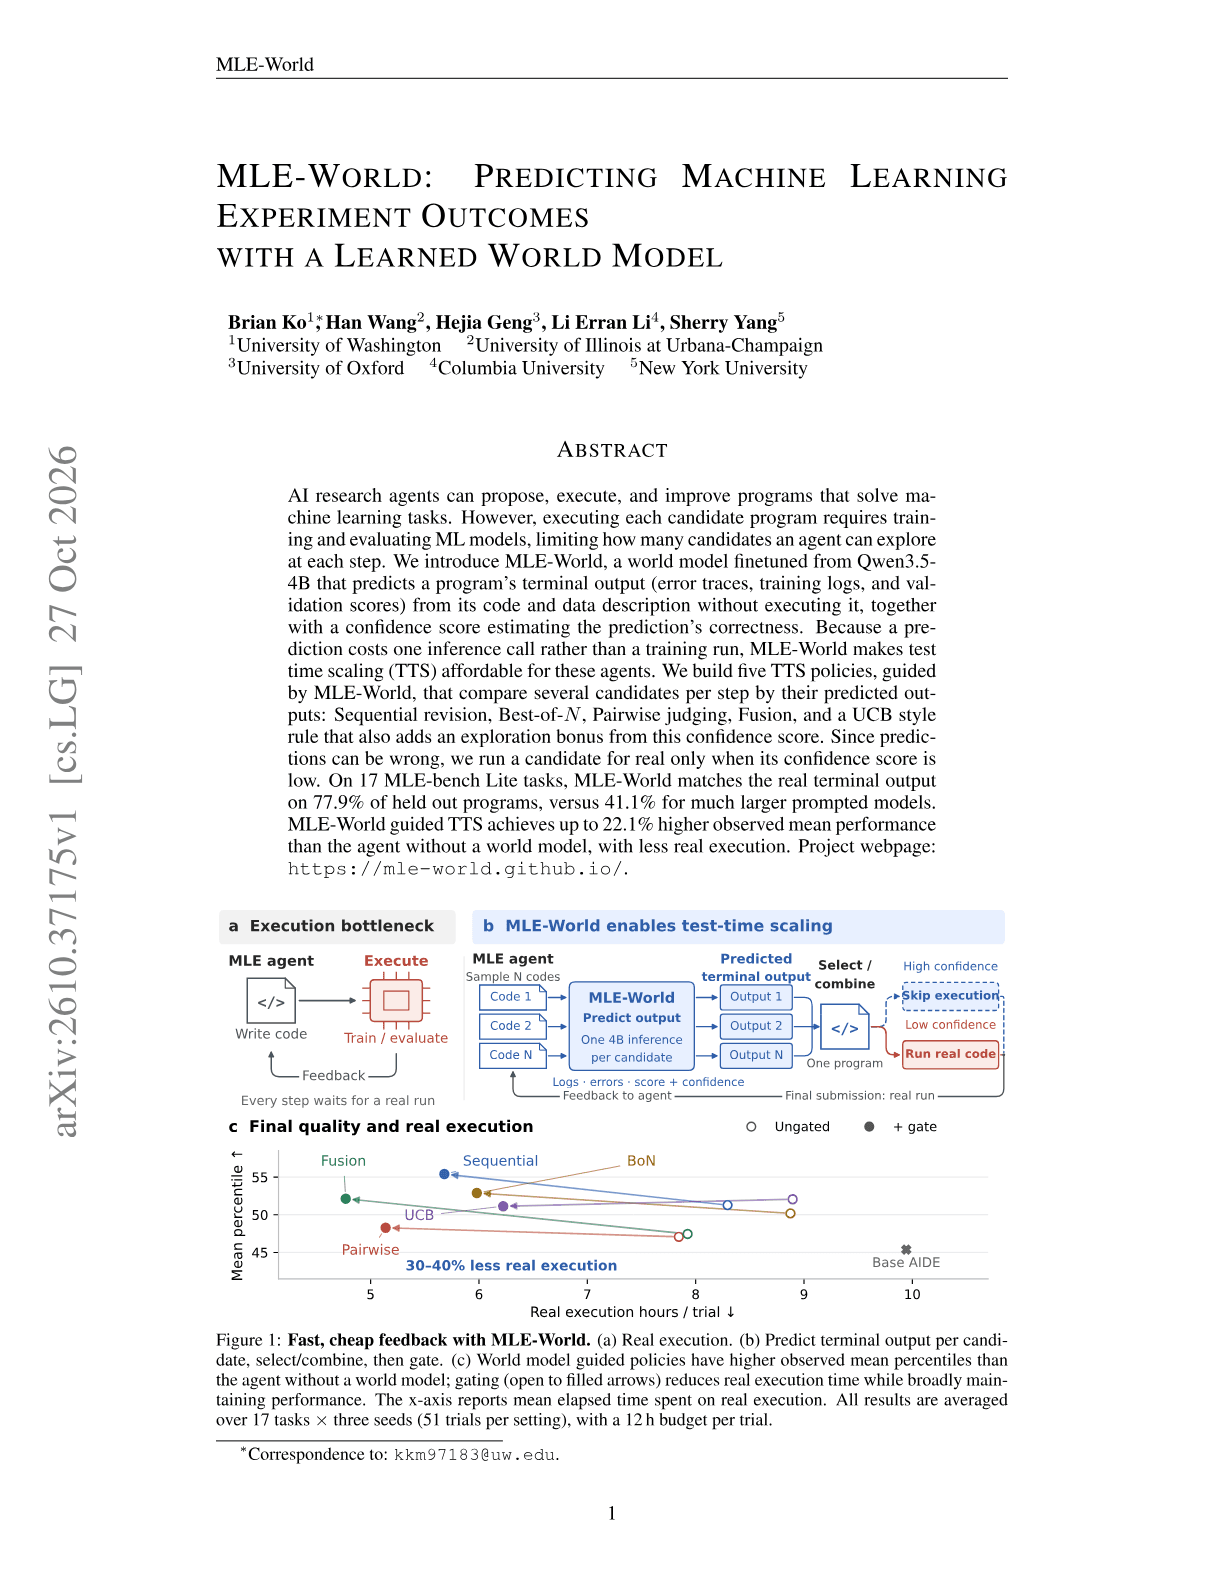
Brian Ko (University of Washington), Han Wang, Hejia Geng, Li Erran Li and Sherry Yang (UIUC, Oxford, Columbia, NYU) train MLE-World, a 4B model that predicts an ML program's terminal output without running it, so research agents can compare many candidates per step at the cost of one inference call each.
Ask this paper
Model. MLE-World is fine-tuned from Qwen3.5-4B to predict error traces, training logs and validation scores from code and a data description, plus a confidence score for each prediction.
Accuracy. On 17 MLE-bench Lite tasks it matches the real terminal output on 77.9% of held-out programs, against 41.1% for much larger prompted models.
Search policies. Five test-time scaling policies use the predictions: sequential revision, Best-of-N, pairwise judging, fusion and a UCB rule with an exploration bonus from the confidence score. Low-confidence candidates are run for real.
Results. World-model-guided search reaches up to 22.1% higher mean performance than the same agent without the world model, with less real execution.
Abstract
AI research agents can propose, execute, and improve programs that solve machine learning tasks. However, executing each candidate program requires training and evaluating ML models, limiting how many candidates an agent can explore at each step. We introduce MLE-World, a world model finetuned from Qwen3.5-4B that predicts a program's terminal output (error traces, training logs, and validation scores) from its code and data description without executing it, together with a confidence score estimating the prediction's correctness. Because a prediction costs one inference call rather than a training run, MLE-World makes test time scaling (TTS) affordable for these agents. We build five TTS policies, guided by MLE-World, that compare several candidates per step by their predicted outputs: Sequential revision, Best-of-N, Pairwise judging, Fusion, and a UCB style rule that also adds an exploration bonus from this confidence score. Since predictions can be wrong, we run a candidate for real only when its confidence score is low. On 17 MLE-bench Lite tasks, MLE-World matches the real terminal output on 77.9% of held out programs, versus 41.1% for much larger prompted models. MLE-World guided TTS achieves up to 22.1% higher observed mean performance than the agent without a world model, with less real execution. Project webpage: https://mle-world.github.io/.